The Problem With Watching Local Forecasts
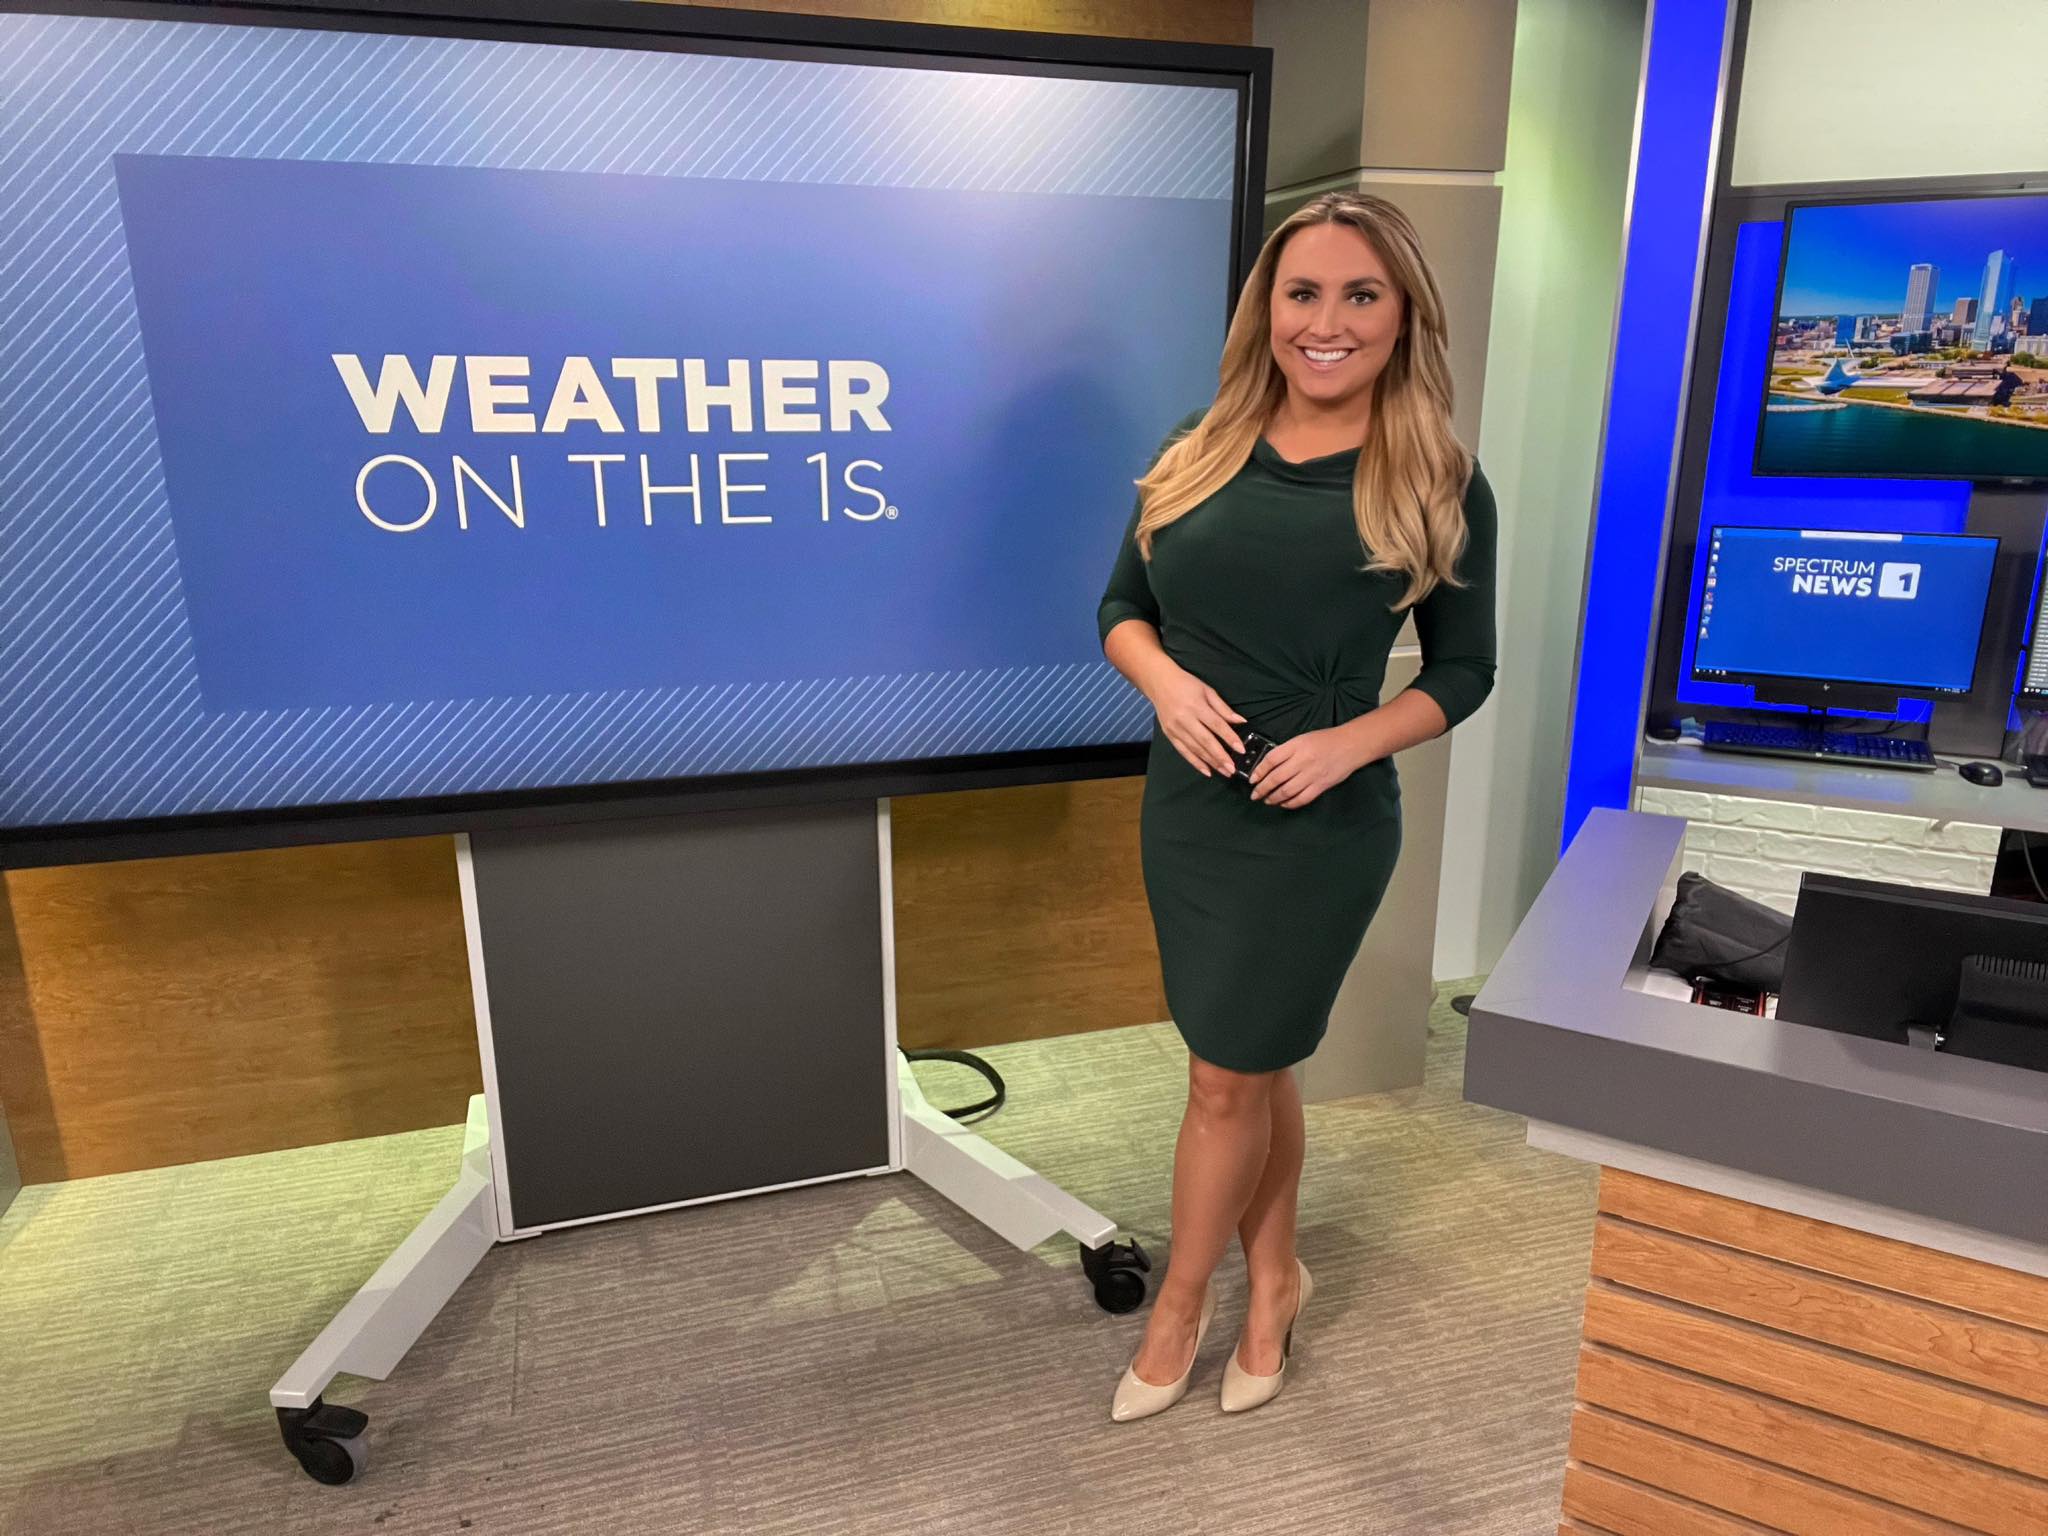
Most people treat weather apps like gospel. They glance at a percentage chance of rain and plan their entire week around it, then get soaked anyway. I have spent years watching meteorologists work, including people like Brooke Brighton, and what separates competent forecasters from the rest has nothing to do with fancy equipment. It comes down to how they read models, cross-reference data, and apply surface-level intuition that machines miss entirely. Brooke Brighton's forecasting approach is worth studying because she consistently lands closer to actual conditions than most people giving the same data. I have compared her local forecasts against official NWS bulletins and radar loops, and her tracks tend to be tighter, especially around convective initiation and boundary layer behavior. That is not luck. It is a methodology you can actually learn.
Unraveling The Mystery Of Brooke Brightons Exceptional Weather Forecasting Skills
The core of her method starts with model interpretation, but not the way most people do it. Beginners look at a single GFS run and treat it as truth. Brighton checks ensemble spreads, compares multiple model families, and looks at where the consensus breaks down. When the ECMWF and GFS disagree on a front's timing by six hours, that disagreement tells you more than either model alone. She also places heavy emphasis on sounding data and microscale features. Most forecasters I watch skip the skew-T log-P diagram entirely and just chase surface charts. A proper analysis of CAPE profiles, lifting condensation levels, and wind shear vectors will show you whether storms are going to fire at all, let alone whether they will produce severe weather. I remember spending an afternoon trying to catch a predicted squall line that never materialized because I ignored the low-level jet decoupling overnight. Brighton would have seen the drying mid-levels on the soundings and downgraded the confidence level before making any public call. Here is a practical breakdown of how her process actually works:
First, she reviews the latest model runs across the major suites: GFS, ECMWF, NAM, and the HRRR for short-range detail. She does not just look at precipitation totals. She checks dewpoint depressions, theta-e ridges, and vorticity advection patterns. Second, she overlays observed surface data and radarsatellite imagery to ground-truth the models. Models are wrong. Always. The question is by how much and in which direction. Third, she identifies the controlling features: cold pools, outflow boundaries, upslope flow, sea breezes, anything that local terrain or geography will amplify or suppress. Fourth, she writes down a probability range, not a single outcome, and updates it as new data arrives throughout the day. I ran into a specific problem last spring that really showed me how different this approach is from standard forecasting. We had a setup that looked textbook on paper: destabilizing atmosphere, decent lift, everything aligned for a convection event. I went with the forecast and set up coverage. What actually happened was a cap held firm until mid-afternoon, then the whole system collapsed within forty minutes because a dry intrusion from the west shredded the moisture profile. I learned two things from that. First, never trust a single model run. Second, watch the satellite loop for mid-level cloud features that indicate dry air mixing down. That dry intrusion was visible on water vapor imagery four hours before it hit the area, but I was too focused on the surface charts to notice it.
Get the Full Details

Why Most Forecasts Miss The Details
Weather models have improved dramatically over the last decade, but resolution limits still create significant gaps. A 3km model like the HRRR can simulate individual storm cells, but it still struggles with terrain-induced flows and urban heat island effects. That is where human judgment matters most. Brighton spends time understanding the local geography in a way that model outputs alone cannot provide. She knows which valleys channel cold air, which ridges force uplift, and how lake effects modify temperatures in specific corridors. This kind of knowledge takes years to build. I tracked temperature differences between two neighborhoods only three miles apart during a winter inversion, and the valley floor sat fourteen degrees colder than the ridge top. A model grid box covering that area would show one averaged number, which would be wrong for both locations. If you do not understand that dynamic, your forecast will always feel one step behind reality.
The Tools That Actually Matter
You do not need expensive software to start thinking like this. The free resources are sufficient if you know where to look. The NOAA Storm Prediction Center provides detailed convective outlooks with reasoning attached. The National Weather Service offers public soundings and radar products. The HRCR viewer gives you hour-by-hour model updates for your specific region. SkyWarn training through the NWS teaches you how to interpret observed data versus modeled data. What Brighton uses alongside these tools is a disciplined habit of noting her forecast errors afterward. Most forecasters never revisit their misses. She keeps records of where and why her calls went wrong, then adjusts her weighting of different signals accordingly. This feedback loop is probably the single most underappreciated skill in the entire field. It is how you move from guessing to calibrating. A few common pitfalls to avoid:
Do not anchor yourself to the first model run you see. Early runs are often noisy and get adjusted significantly by later updates. Do not overreact to dramatic model shifts without checking whether the change is physically realistic. Do not ignore the ensembles because they are confusing. Ensemble spreads are honestly the most useful tool for understanding uncertainty, and dismissing them means you are flying blind on risk assessment. Do not forecast in a vacuum. Check what other forecasters in adjacent regions are seeing. Weather systems do not respect jurisdictional boundaries, and neighboring analyses often catch features your own data misses.

What This Method Cannot Do
I want to be clear about the limitations here. No forecasting approach, including Brighton's, can reliably predict individual thunderstorm formation more than a couple hours in advance. We simply do not have the observational density or modeling resolution to do that yet. Anyone claiming otherwise is selling something. Chaotic systems resist precise long-range prediction, and the atmosphere will always find a way to surprise you. The best forecasters can do is assign reasonable probabilities, identify likely scenarios, and communicate uncertainty clearly. That is harder than it sounds, especially when you are working under deadline pressure for a broadcast slot. But it is the only honest way to do this work. If you need certainty, meteorology is not going to give it to you, no matter how skilled the forecaster.