What IS Actually An Information System
An information system is the combination of people, processes, data, and technology working together to collect, process, store, and distribute information. That's the textbook version. The real version is messier. Most organizations have five or six competing systems that all sort of do the same thing but none of them talk to each other. A hospital might have a patient registration database, a billing system, a lab results tracker, and several spreadsheets that nobody officially approved but everyone depends on. That is an information system. It's just not a clean one. Information systems exist at multiple levels. Transaction processing systems handle the daily operational data. Management information systems summarize that data for middle managers. Decision support systems help with structured choices. Enterprise resource planning ties departments together. Knowledge management systems try to capture institutional expertise. Each layer feeds the next, and each layer breaks in its own way.
Unraveling The Mysteries Of What Is Information Systems A Comprehensive Guide
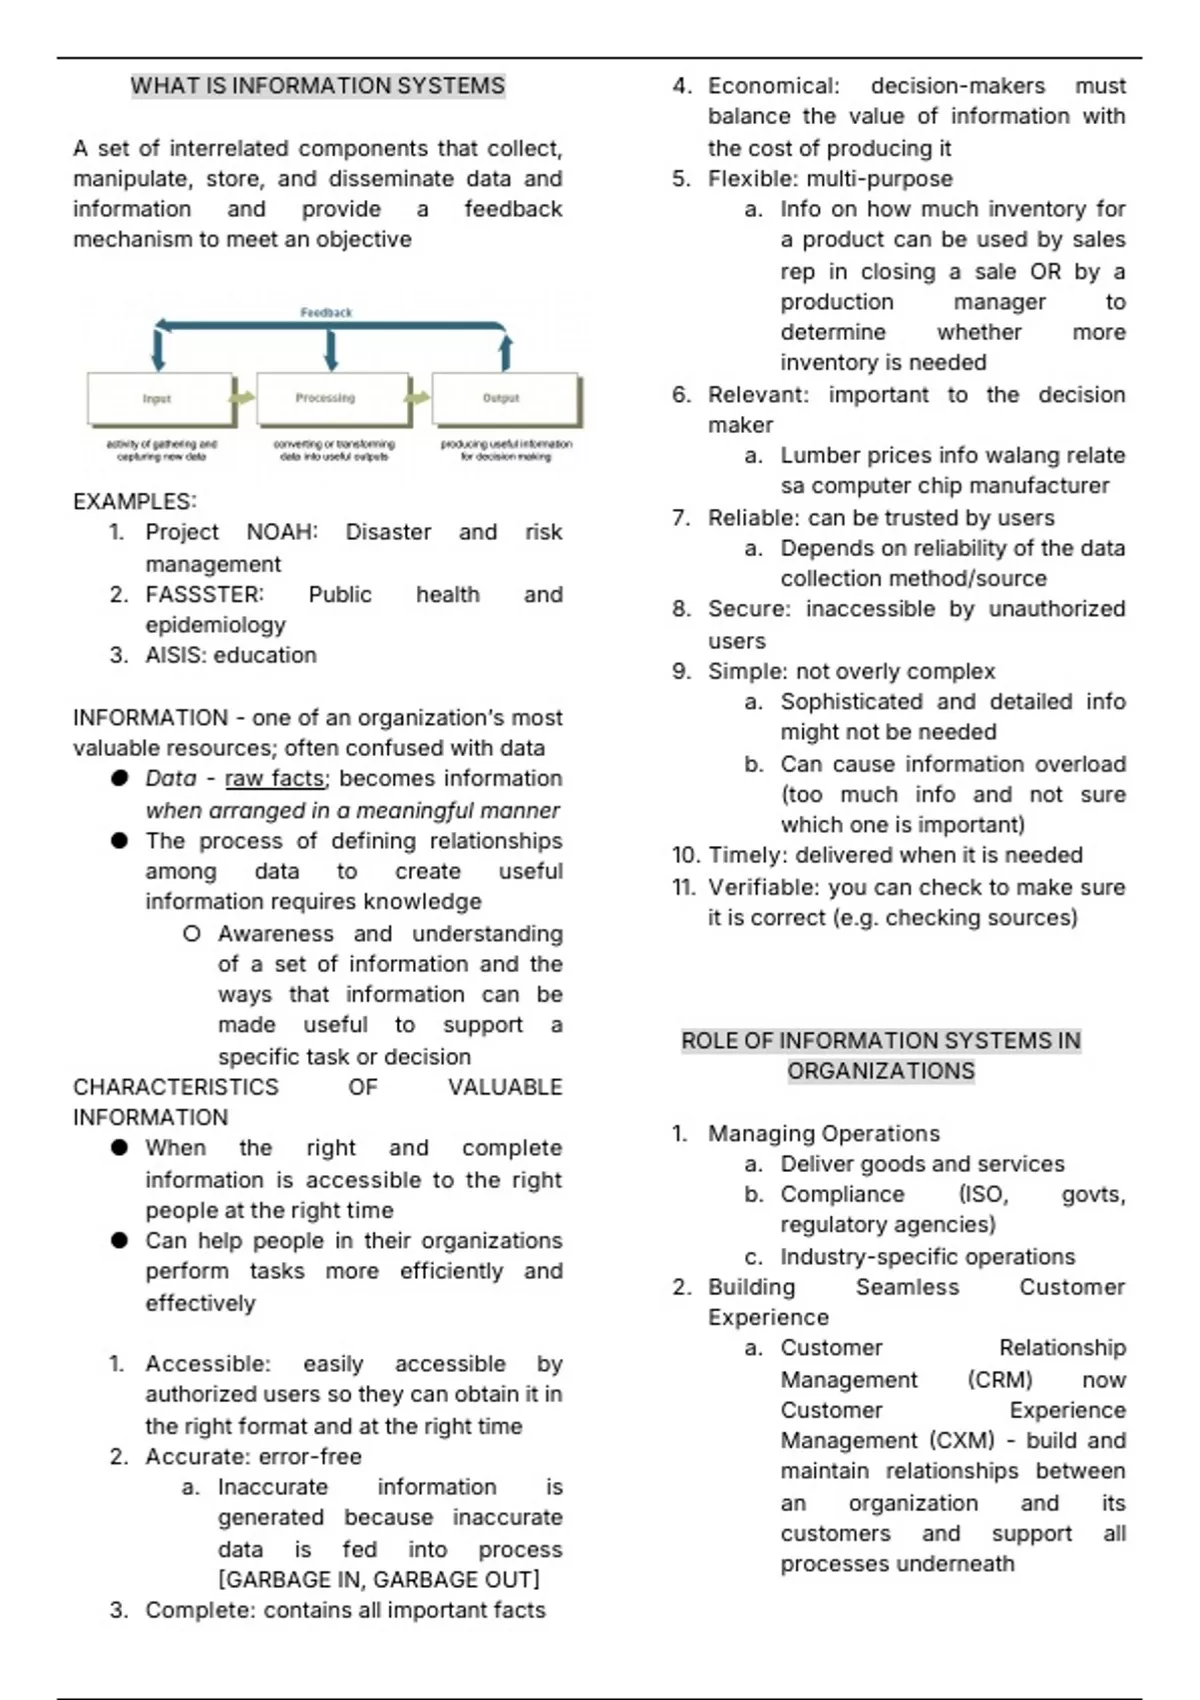
If you're looking for a structured path through this topic, this guide walks you through the components, the architecture, the common pitfalls, and how these systems actually function inside real organizations. Not the ideal version. The version that exists when a database has been running for eight years and nobody remembers who designed it or why certain fields were added in 2019. Every information system contains five elements. Hardware, software, data, procedures, and people. Remove any one of them and the system stops functioning. This sounds obvious until you see organizations build multi-million dollar software platforms and forget to train the people who will use them or write the procedures that define how the data should flow. The system runs. It just produces garbage outputs consistently. Data is the component most people misunderstand. It's not the product of an information system. Data is the raw material. The system transforms it. Input gets captured, processed against business rules, stored in a structured format, and output as usable information. Someone makes a decision based on that information. Sometimes the loop closes. Sometimes it doesn't. Most of the systems I've encountered break at the feedback stage because nobody set up the mechanism to verify whether the output actually changed the decision quality.
Architecture That Actually Works
System architecture determines how those five components interact. The two most common models are monolithic and distributed. Monolithic systems put everything in one place. A single application, one database, one server. Easier to manage initially. Harder to scale. Distributed systems spread functions across multiple servers and services. Microservices architecture is the current flavor of distributed. More complex to orchestrate. Far more resilient when individual components fail. Client-server architecture remains the dominant model for enterprise information systems. The client handles the user interface. The server handles the logic and data storage. Three-tier architecture adds a middle layer between the client and server, usually for business logic processing. This separation lets you update the interface without touching the database layer and vice versa. That separation is the difference between a system that can evolve and one that becomes impossible to modify after year three. Here's something most beginners miss. The architecture matters less than the data model. I spent six months the bottleneck was a poorly normalized relational schema that forced full table scans on every query. Swapped it for a properly indexed design and query times dropped from four seconds to under 200 milliseconds. Architecture decisions get promotions. Data model decisions get results.
Get the Full Details

How Information Systems Support Business Functions
Different systems serve different business purposes. Supply chain management systems track inventory, procurement, and logistics from raw material to delivered product. Customer relationship management systems centralize all interactions with clients, from first contact through post-sale support. Human resource information systems handle payroll, benefits, performance reviews, and compliance reporting. Financial systems manage transactions, accounting, budgeting, and regulatory reporting. Manufacturing execution systems control shop floor operations in real time. The systems that deliver the most value are the ones that connect across functional boundaries. A CRM that doesn't feed sales data into the ERP creates a revenue reporting gap. An HR system that doesn't integrate with payroll creates compliance exposure. Integration points are where most failures happen because each system was built by a different team with different assumptions about data formats, update frequencies, and error handling. The connector between two well-built systems is often the weakest part of the entire architecture.
A Real Implementation Problem
During a supply chain system rollout at a mid-size distribution company, we hit a specific edge case that wasn't documented anywhere in the vendor materials. The system supported batch updates for inventory reconciliation, but the existing warehouse workflow used continuous cycle counting throughout the day. Every time the batch job ran at midnight, it locked the inventory tables for approximately eleven minutes. Warehouse staff couldn't look up stock levels during that window. Shipping labels failed to generate. The system wasn't broken. It was doing exactly what it was designed to do. The design just didn't account for 24/7 operational requirements. The workaround was to split the reconciliation into two phases. Phase one ran every hour and processed only changes since the last cycle. Phase two ran overnight but used read-commit isolation instead of table locks, which let the warehouse management terminal queries proceed concurrently. It added about forty-five minutes of nightly processing overhead but eliminated the operational blackout. The vendor's support team admitted they hadn't encountered this scenario in their deployments, which told you everything you need to know about how these systems are tested before release.
Common Pitfalls That Sink Projects
Requirements volatility is the number one reason information system projects exceed budget and timeline. Stakeholders don't know what they need until they see a prototype. This isn't a character flaw. It's how complex systems work. The solution is iterative development with concrete demos every two to four weeks, not abstract requirement documents that get signed and forgotten. Waterfall planning for information systems almost always fails because the domain is too uncertain for a single up-front specification to remain valid. Another pitfall is treating legacy system integration as a technical problem rather than a business problem. The technical challenge is usually solvable. The business challenge is getting five departments to agree on what the data means, who owns it, and who gets access. I once watched a three-week data mapping exercise that was really just a series of arguments about whether "customer" meant the purchasing entity or the billing entity or the end user, and those three things were different people in forty percent of the cases. Performance problems also emerge from unrealistic concurrency assumptions. A system tested with fifty concurrent users will behave differently under five hundred. Queue-based architectures handle spikes better than request-response models for batch-heavy workloads. If your system processes reports and notifications during business hours alongside transactional traffic, schedule the heavy batch jobs for off-peak or move them to a separate processing tier entirely.
Getting Started With Information Systems
If you want to work with information systems, start by understanding the data flow. Draw it out on paper. Map where data enters the organization, what transformations it undergoes, where it's stored, and who consumes it. Most organizational dysfunction becomes visible once you trace the data across system boundaries. The gaps and contradictions appear immediately. Learn SQL. Not the tutorial version. The version where you're joining six tables, dealing with NULL handling in unexpected ways, and writing queries that need to run in under two seconds against millions of rows. That's the SQL that matters in professional settings. Then learn at least one programming language that connects to databases. Python and JavaScript are the practical choices. Python for data processing and backend work. JavaScript for full-stack applications that need to interface with modern frontends. Understand normalization. Not the academic definition. The practical consequence. A poorly normalized database creates update anomalies that compound over time. Insert one record wrong and suddenly three other records are inconsistent. The fix is restructuring tables to eliminate redundancy, which is painful to do on a live system. Prevention is cheaper than remediation.
What These Systems Get Wrong
Information systems struggle with unstructured data. Emails, documents, images, audio recordings. Enterprise content management systems attempt this but the results are usually adequate rather than excellent. Search functionality over unstructured data remains significantly harder than query functionality over structured data, and the gap hasn't closed as much as people claim. Vector databases and embedding models have improved things considerably, but they introduce new failure modes around semantic accuracy and computational cost. Security and usability remain in tension. Every security control that actually works reduces usability. Multi-factor authentication slows login. Password rotation policies get gamed. Role-based access controls create permission sprawl. The systems that last are the ones where security requirements were defined by the people who would actually operate the system, not by a compliance checklist written by people who don't use it. Automation bias is a real and underdiscussed problem. When a system consistently produces correct outputs, operators stop questioning its results. They trust the display over their own observation. This creates failure modes where a systematic data entry error goes undetected for months because every automated report looks internally consistent. The workaround is periodic manual verification against independent sources, ideally done by someone who didn't build the system.
Practical Tools and Resources
For learning the fundamentals, database textbooks like Elmasri and Navathe's fundamentals of database systems cover the theoretical foundations adequately. For practical implementation, the PostgreSQL documentation is one of the best freely available technical references for any relational system. ORM frameworks like SQLAlchemy for Python or Entity Framework for .NET reduce boilerplate but introduce their own abstraction leaks that you need to understand before they cost you. Architecture diagrams belong in every project. Not finished polished versions. Rough sketches that show data flow between components, decision points, and failure scenarios. When you can see the system on a single page, you can spot the parts that don't connect or the parts that create feedback loops. Those are the places where things break under load. The field moves faster than most textbooks capture. Cloud-native architectures, serverless computing, event-driven systems, and data mesh concepts are reshaping how organizations design information systems. The principles don't change. Data still flows from input to output through transformation and storage. People still make decisions based on that output. The mechanisms change frequently enough that staying current matters more than mastering any single technology stack.