What OCR Actually Does in Financial Operations
Optical Character Recognition in finance is the process of converting scanned documents, images, and PDFs into machine-readable text that can feed directly into accounting systems, compliance databases, and reconciliation engines. It sounds straightforward until you're dealing with bank statements from twelve different international banks, each with their own layout, font, and quality of scan. That's where the real work begins. I spent about three years implementing OCR pipelines for a mid-sized asset management firm. We processed roughly 40,000 documents a month across reconciliations, trade confirmations, and regulatory filings. Here's what actually happened when the theory met reality.
Unraveling The Mysteries Of Ocr In Finance What Does It Mean The Full Picture
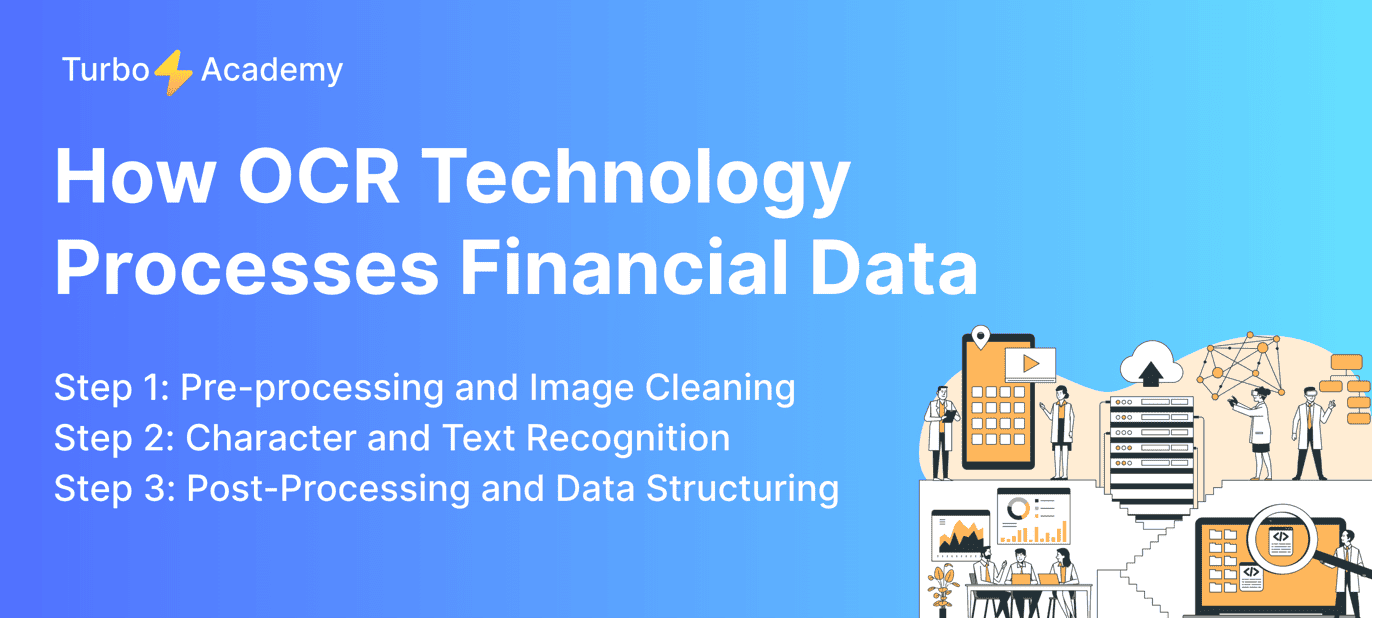
At the core level, OCR takes pixel data and translates it into characters. Tesseract, ABBYY, and Google Cloud Vision are the most common engines people reference. But the actual value in finance doesn't come from the character recognition itself. It comes from what happens after recognition, which is where most implementations fail or produce garbage output that looks clean enough on the surface to pass initial QA but quietly corrupts downstream reporting. The pipeline has three stages. First is preprocessing, which involves deskewing, contrast adjustment, noise removal, and sometimes image segmentation. Second is the actual recognition pass. Third is post-processing, which applies business logic, field mapping, validation rules, and confidence scoring. Finance teams that skip the preprocessing or post-processing steps because "the OCR engine handles it" are the ones who end up spending more time on manual corrections than they would have on a paper-based process. Preprocessing matters more than the recognition engine. A poorly preprocessed image will sink even the best model. I've seen teams burn budget on premium ABBYY licenses only to realize their input images had inconsistent DPI, compression artifacts from fax re-scans, and misaligned columns that no model could reliably parse without intervention first.
Field-Level Extraction vs. General Document Recognition
There's a fundamental difference between reading a document and extracting specific fields from it. General recognition gives you raw text. Field-level extraction tells you that "1,247,890.33" in the upper right corner of a bank statement is the closing balance, not a transaction amount or a reference number. In practice, financial OCR typically targets these fields: Account numbers and routing information
Get the Full Details
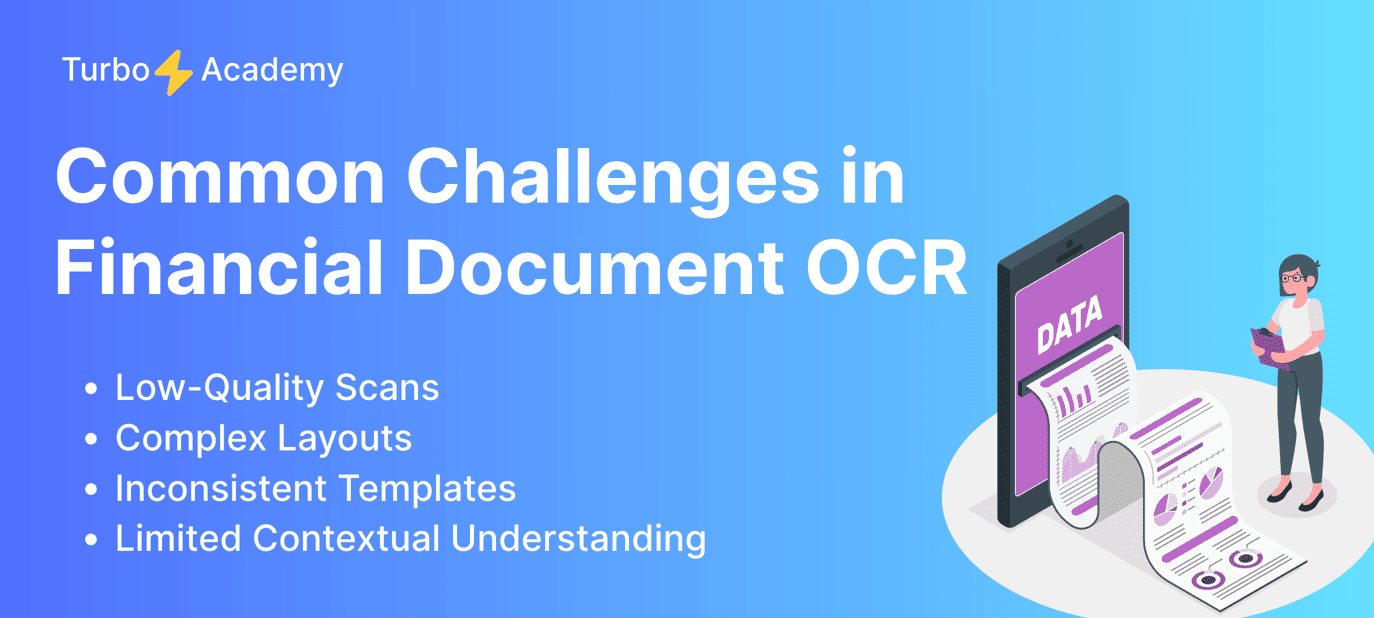
Date fields, often in inconsistent formats like DD/MM/YYYY, MM-DD-YY, or written-out dates Transaction amounts and currency codes Counterparty names and identifiers
Invoice numbers and purchase order references Regulatory field codes and classification markers The problem with date formats alone accounts for roughly 40 percent of field extraction errors in my experience. An American model reads 03/04/2024 as March 4. A European system reads it as April 3. When your reconciliation breaks because of this, you don't immediately know which interpretation is correct without additional context clues.
What I Actually Did When Things Broke
Here's a specific case. We were processing bank confirmations from a German subsidiary. The documents used a dual-column layout where the left column contained transaction descriptions and the right column contained amounts. The OCR engine read left-to-right across both columns, producing lines like "Payment received from client XYZ 15,000.00 EUR" instead of separating the description from the amount. This looked perfectly reasonable as text but was completely wrong for our reconciliation mapping. The workaround was to add a pre-processing step that detected the vertical column divider line, split the image into two regions, ran OCR on each region separately, then merged the results with positional awareness. This added about eight seconds per document to the pipeline but reduced our manual correction rate from roughly 18 percent down to under 2 percent. Eight seconds per document across 40,000 documents a month is about 278 extra hours of processing time, but it eliminated maybe 6,000 manual correction items. The math works in favor of the added complexity. Another edge case involved stamped documents. Many financial institutions in Asia and Latin America use physical rubber stamps over transaction details. These stamps obscure text, introduce colored noise, and create shadows. Standard OCR treats stamp ink as document content and often misreads stamped text as part of the underlying print. Our solution involved a color segmentation step to isolate red and blue stamp colors, then a masking operation to blank those regions before recognition. After recognition, we used a separate stamp-detection model to identify and extract stamp text independently.
Common Pitfalls That Beginners Miss
Confidence scoring is not a reliability guarantee. Most OCR engines output a confidence value between zero and one for each recognized character or word. Teams treat high average confidence as proof of accuracy. It isn't. A bank statement with mostly clear text and one critical digit misread at 99 percent confidence will still produce a wrong reconciliation. The confident error is the dangerous one because nobody questions it. Layout-aware models exist but they're expensive and fragile. Modern solutions like AWS Textract, Azure Form Recognizer, and Google Document AI use layout analysis to understand tables, key-value pairs, and structured fields. They work well on standard document types. They fall apart on custom or vintage formats that weren't represented in training data. A 2019 bank statement format from a regional credit union may have zero overlap with the model's training distribution. Expect a sharp drop in accuracy rather than a graceful degradation. The biggest pitfall is assuming OCR replaces document classification. You need to know what type of document you're processing before you can apply the right extraction logic. A trade confirmation needs different field mapping than a tax form, which needs different mapping than a wire transfer instruction. Run classification first, then routing, then extraction. Skipping classification and sending everything to a single general-purpose model produces mediocre results across the board and poor results on anything non-standard.
Realistic Performance Numbers
Field-level accuracy for standard bank statements using modern cloud OCR sits around 94 to 97 percent on clean, high-resolution scans. For messy inputs, including faxes, photos taken with smartphones, or documents with heavy annotations, accuracy drops to the 70 to 85 percent range. Invoice extraction from standardized forms like the AIA G702 or common AP formats can reach 96 to 98 percent accuracy with proper preprocessing. Handwritten signatures, notes, and marginalia are largely irrelevant to financial processing and should be excluded from the recognition target to avoid noise. Processing speed varies significantly. Cloud-based APIs typically handle a page in two to eight seconds depending on resolution and model complexity. On-premise engines like ABBYY Vantage can process faster but require GPU infrastructure. For our volume, cloud APIs gave us better accuracy at the cost of slightly higher latency. The total pipeline from scan ingestion to structured output averaged about forty-five seconds per document, including preprocessing, classification, extraction, validation, and quality logging.
When OCR Is Not the Right Answer
Some document types resist OCR regardless of investment. Heavily watermarked security documents, photos of screens with moiré patterns, and documents where the text is embedded in complex graphics or vector art will not produce reliable results. In those cases, manual entry, alternative data sources, or requesting digital replacements is usually faster than building a custom solution. If you have fewer than 500 documents per month, the ROI on a full OCR pipeline is questionable. Manual review or a hybrid approach where humans handle the first pass and OCR handles batch verification is often more practical. The fixed costs of setup, testing, maintenance, and quality assurance don't scale down well at low volumes. Regulatory documents that require legal-grade accuracy, such as signed contracts or audited financials, should never rely solely on OCR output. Use it for indexing and searchability, but treat the extracted text as a working approximation, not a verified record. The original scanned document remains the authoritative source.

Practical Implementation Steps
If you're building this out, start by cataloging your document types and volumes. Know what you're dealing with before you select a tool. Collect at least five hundred representative samples per document type, including the worst-case quality inputs you realistically receive. Test multiple engines on the same samples. Compare field-level accuracy, not just overall text accuracy, because you only care about the fields your downstream systems consume. Build a validation layer that checks extracted values against business rules before they enter any system. A date field that falls outside the expected range. An amount that doesn't match a known invoice. A counterparty name that doesn't exist in your vendor master file. These checks catch the confident errors that slip through. Maintain a correction log. Every time a human edits an OCR output, record the input image, the extracted result, the correction made, and the reason. This log becomes training data for future model refinement and helps you identify systematic failures. In our pipeline, the correction log revealed that our German bank confirmation issue wasn't isolated. Three other European banks had similar dual-column layouts that the engine consistently misread. Fixing one fixed four.
Document retention and audit trails matter. Store the original image alongside the extracted data. Link them permanently. If a reconciliation discrepancy surfaces eighteen months later, you need the original scan to investigate, not just the extracted text that may have silently degraded your records.
Tools and Options Available
Cloud platforms offer the lowest barrier to entry. AWS Textract provides table and form extraction with reasonable accuracy on standard financial documents. Azure Form Recognizer has strong performance on invoices and receipts. Google Document AI handles complex layouts and multilingual documents well. All three charge per page, which scales linearly with volume and can become expensive at high throughput. ABBYY Vantage and Kofax offer enterprise on-premise and hybrid options with deeper customization but require significant implementation effort and licensing cost. Tesseract is free and highly configurable but demands substantial engineering investment to reach production-quality results, especially for structured financial documents. For smaller teams or limited budgets, starting with a cloud API on a pilot set of document types, measuring actual accuracy against your ground truth samples, and iterating from there is the most practical path. Don't commit to an enterprise license before you've proven the approach works on your specific document population.

The Bottom Line
OCR in finance is not a plug-and-play solution. It's a processing pipeline that requires careful design, continuous monitoring, and ongoing maintenance. The technology has improved significantly over the past few years, but the gap between demo accuracy and production accuracy remains wide for anyone handling real-world financial documents. The teams that succeed treat OCR as a first pass in a larger workflow, not as a final authority on document content. They invest in validation, logging, and fallback processes. They accept that some documents will always need human review and plan for that reality instead of pretending it won't happen. If you're considering implementing this, the first question isn't which OCR engine to use. It's how many documents you process monthly, what types they are, what accuracy level your downstream systems require, and what your acceptable manual correction rate is. The answers to those questions determine everything else.

