When Hive Metastore Client Creation Starts Throwing NPEs
Unraveling The Mysteries Of Hive Metastore Client Instantiation Issues Your Ultimate Troubleshooting Guide
I spent three days tracking down a NullPointerException that only appeared when we tried to create a HiveMetastoreClient from our Spark jobs. The error wasn't in our code. It was in the way the metastore configuration was being loaded from the cluster's classpath versus our application's classpath. This is one of those problems that looks like a coding bug but is actually a classloading issue. The HiveMetastoreClient is instantiated through a factory pattern, typically via either the Configuration object or directly through Thrift connection parameters. When things go wrong, you get exceptions ranging from MetaException to Connection refused, and the stack traces can be misleading.
Common Instantiation Patterns and Where They Fail
There are really three ways people instantiate the client, and each has different failure modes. The first and most common approach uses the Configuration object. You load hive-site.xml from your classpath, pass it to the HiveConf constructor, and then call getClient(). This works fine in a simple local setup. The problem shows up when you're running inside a containerized environment or a distributed framework like Spark or Flink. The hive-site.xml file might not be visible to every executor or worker node. I ran into this exact scenario last year on a production cluster. Our metastore client worked fine in local testing, but when we pushed to a YARN-managed cluster, the executors failed with a MetaException complaining about being unable to open a new state store. The root cause was that our build process excluded the metastore configuration from the fat jar we were shipping. The Driver had the config. The Executors didn't. Each attempt to create a client from an Executor threw because it couldn't read the hive.metastore.uris property.
The fix was straightforward once I realized what was happening. We added the hive-site.xml to the Spark submit configuration using --files and verified every node could read it. But finding that took about six hours of checking configs across fifteen different service instances. The second approach passes Thrift URI strings directly. This is common when you're building custom pipelines or lightweight integrations. You skip HiveConf entirely and go straight to constructing a metastore client with the raw URI. The failure mode here is different. If the URI format is wrong even slightly, you get a Connection refused rather than a configuration parsing error. People often forget that the URI needs the full scheme, like thrift://metastore-host:9083, and not just the hostname.
Get the Full Details
Thrift Connection Timeout and Pool Exhaustion
Another category of issues involves the underlying Thrift connection pool. The HiveMetastoreClient wraps a ThriftClientPool by default, and this pool has finite size. When you create too many clients in rapid succession without closing them, you exhaust the pool and get a TTransportException. This happens frequently in Spark applications where each partition or task tries to open its own client instance. The symptom is usually a timeout after 60 seconds of waiting for a pool slot. The timeout is controlled by hive.metastore.client.socket.timeout, which defaults to 60 seconds. I've seen people raise this to 120 or 180 and wonder why the problem persists. It doesn't fix the pool exhaustion, it just makes the timeout happen later. The real solution involves either sharing a single client instance across tasks or explicitly managing the pool size through hive.metastore.client.pool.size. Setting this higher means the metastore server itself needs to handle more concurrent connections. Make sure your HMS configuration allows it. The default max connections on the HMS side is often lower than what a busy Spark job will demand.
SSL and Authentication Misconfiguration
If your metastore runs with TLS enabled, client instantiation can fail due to certificate trust issues. The client needs to trust the CA that signed the HMS certificate. If you're using a self-signed certificate in development, the client will reject the connection with a certificate validation error that gets buried inside a MetaException. The actual SSL handshake failure is three levels deep in the stack trace. I've found that the fastest way to diagnose this is to run a simple telnet or nc command against the metastore host and port from the failing machine. If the TCP connection succeeds but the client still fails, you know it's a certificate or authentication issue. If the TCP connection fails, you have a network problem that nothing in the Hive configuration will fix. For Kerberos-authenticated clusters, the principal mismatch is a common trap. The client attempts to authenticate using the current user's keytab or ticket cache. If the HMS principal is configured differently from what the client is presenting, you get an authorization exception that again hides inside a generic MetaException. Check your hive.metastore.kerberos.internal.spnego.principal and make sure it matches what's running in the metastore process.
Version Compatibility Between Client and Metastore Server
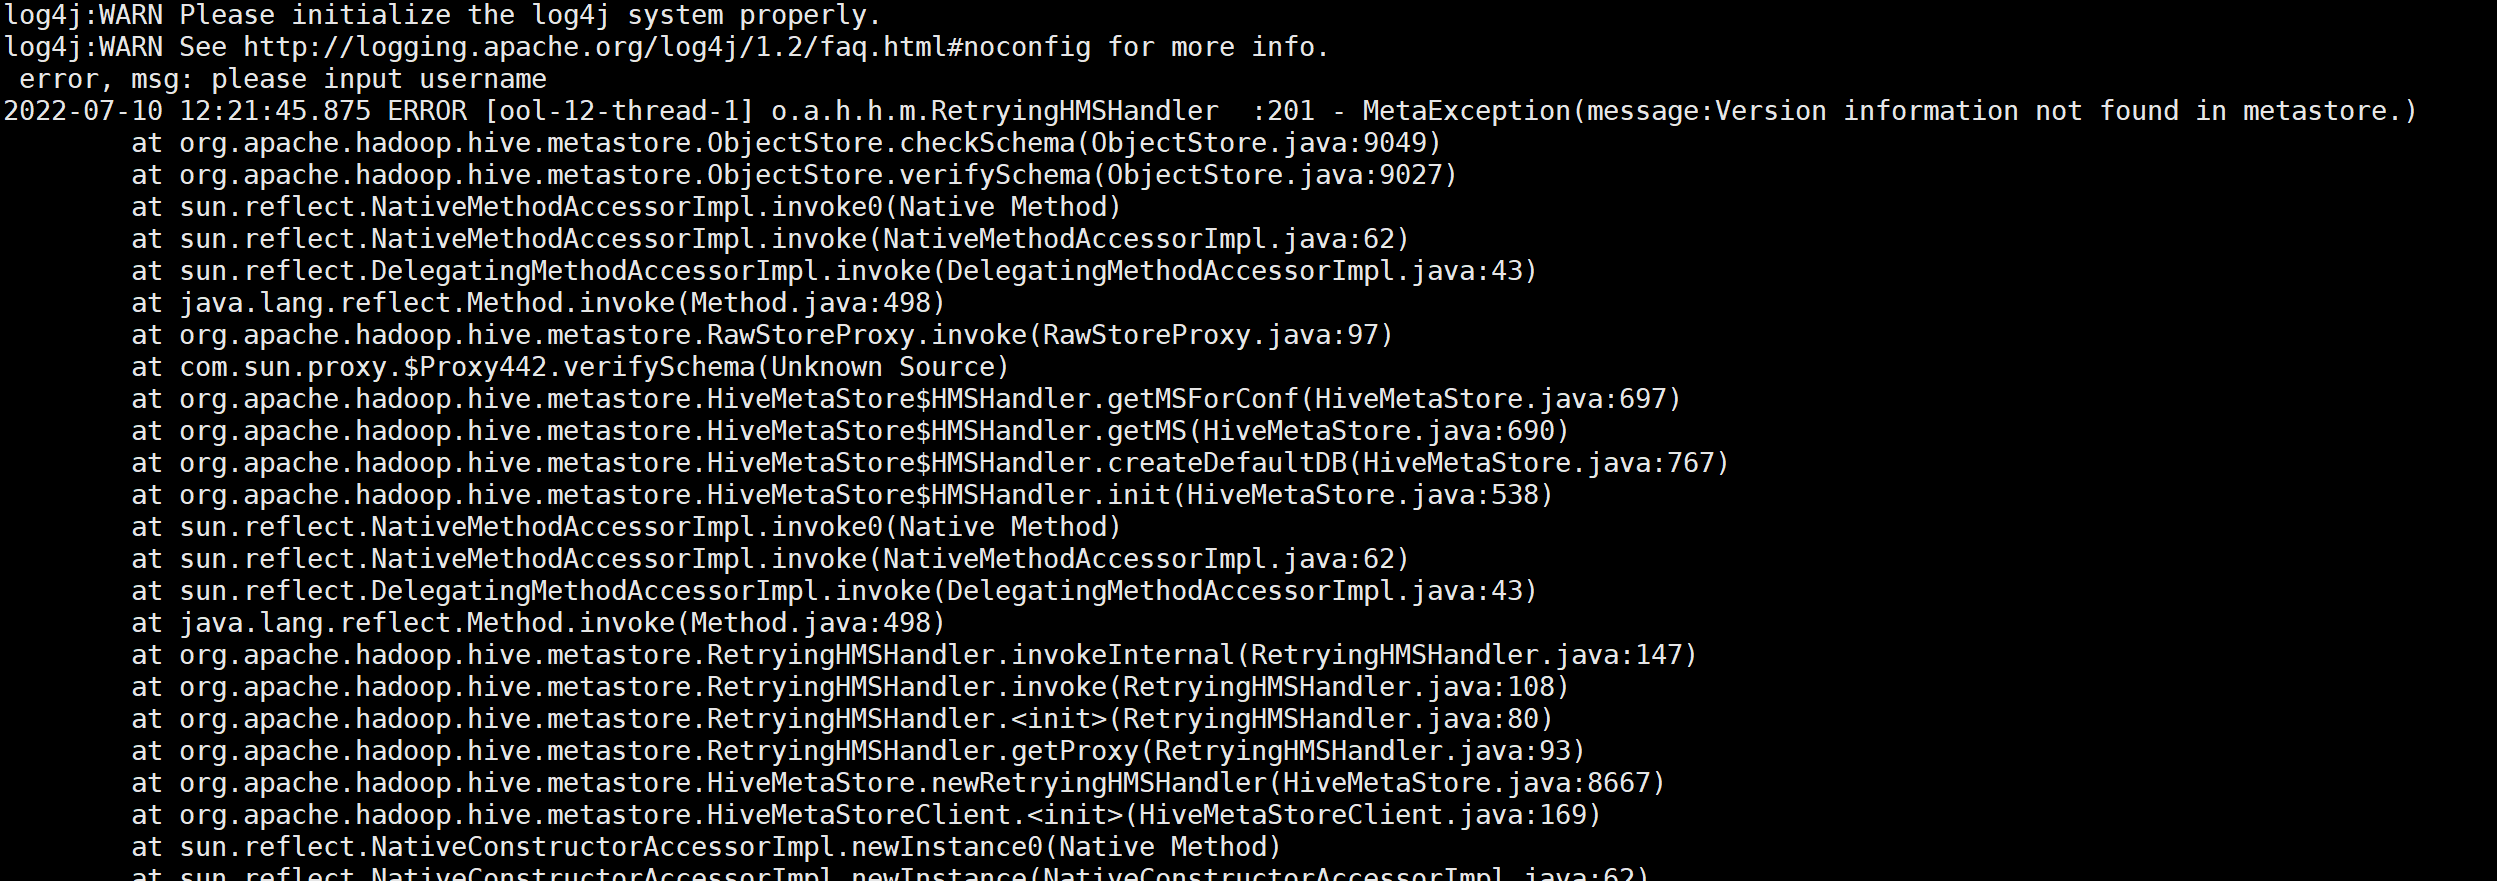
This is one of those things that isn't documented well. The Hive Metastore client version needs to be compatible with the metastore server version. A client built against Hive 3.1 won't always work with a Hive 2.3 metastore, even though they share the same package name. The Thrift protocol evolved between versions, and certain schema fields that the client expects may not exist on the older server. When this mismatch occurs, you typically see errors about unknown fields or unsupported protocol versions during the handshake phase. The client initialization appears to succeed but then fails when it tries to query metadata. I encountered this when upgrading our metastore server but forgetting to update the client library in our application dependencies. Maven showed a clean build, but runtime behavior was broken. The workaround is to align your client dependency version with the metastore server version. Not close. Not compatible range. Same major.minor version. You can verify your running HMS version by connecting to the database directly and checking the VERSION table, or by running the HMS JMX metrics endpoint if it's exposed.

Configuration Loading Order and Property Precedence
The Configuration object loads properties from multiple sources in a specific order. System properties override everything. Then hive-site.xml on the classpath. Then any default values defined in hive-default.xml. If you have conflicting definitions across these layers, the wrong value wins and causes subtle failures that are hard to trace. For example, I once spent two days debugging why a client would connect to the wrong metastore. The hive-site.xml in the classpath pointed to the production URI, but a system property set during container startup was overriding it with a staging URI that didn't exist. The error came back as a connection refused, which looked like a network issue at first glance. Running the Java application with -Djavax.net.debug=all revealed the actual URI being used and made the problem obvious in five minutes.
Practical Debugging Steps
When you're facing a metastore client instantiation problem, start by printing the effective Configuration object before creating the client. Log the value of hive.metastore.uris, hive.metastore.client.socket.timeout, hive.metastore.client.pool.size, and any security-related properties. This gives you a baseline of what the client thinks it should be using. Next, verify network connectivity from the exact machine and user context where the failure occurs. Use the same JVM and the same classpath. Tools like hive --conf hive.metastore.uris=thrift://host:9083 will help confirm whether the client can reach the server independently of your application logic. Check the HMS server logs for incoming connection attempts. If the client logs show it's trying to connect but the HMS logs show nothing, you have a network or firewall issue. If the HMS logs show connections arriving and then being rejected, the problem is on the authentication or authorization side.
Finally, enable Thrift debug logging. Set hive.metastore.logger.level to DEBUG and watch the connection lifecycle in the logs. You'll see exactly where the initialization fails, whether it's during pool creation, authentication handshake, or the first metadata query.

What This Approach Doesn't Fix
These troubleshooting steps won't help if the metastore server itself is unhealthy. If the underlying database is down or extremely slow, the client will time out regardless of how correctly it's configured. Also, if you're dealing with a multi-tenant environment where the metastore is shared across multiple clusters, the issue might be resource contention rather than a configuration problem. In those cases, the fix is upstream infrastructure work, not client-side debugging. For large-scale deployments where pool exhaustion is chronic, consider moving away from per-task client creation entirely. Maintain a singleton client instance at the application level and reuse it across all operations. This requires careful attention to thread safety, but it eliminates the pool management problem altogether. Apache Hive's own SessionState does something similar, and you can follow that pattern if you're building custom integrations.