What Credit Risk Actually Looks Like In Practice
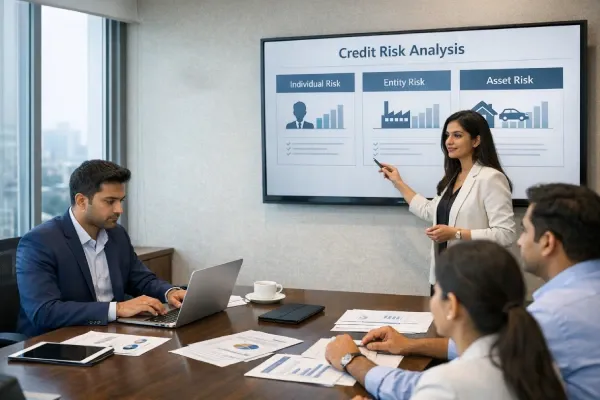
Credit risk models are rarely as clean as textbooks make them look. Most beginners pick this up assuming there is a single correct formula for calculating default probability, then spend months figuring out why their output looks nothing like reality. The core concept is straightforward: you are estimating the chance a borrower fails to meet obligations. Everything else is implementation detail. The practical starting point is understanding three components that every credit risk framework relies on. First is Probability of Default, or PD, which is your baseline estimate that a borrower defaults within a given horizon. Second is Loss Given Default, LGD, which captures how much you lose once default happens. Third is Exposure at Default, EAD, which reflects the outstanding balance at the time of default. Multiply these three together and you get Expected Loss. That number should not tell the whole story though. In my experience, the hardest part for beginners is not learning the formula. It is recognizing that these variables are correlated in ways that standard models often miss. When a borrower defaults during an economic downturn, LGD tends to spike because collateral values are compressed. EAD can also shift if the borrower has drawn down lines of credit before the default materializes. Treating these as independent inputs produces estimates that look reasonable on paper but understate risk during stress periods.
Another thing most people gloss over is data quality. You can have a beautifully specified model and still get garbage results if your historical default records are incomplete or your borrower segments are too broad. I ran into this when working on a portfolio of small business loans where the default definition varied across lenders. Some recorded defaults at 90 days past due, others waited 120 days. Comparing PD estimates across those datasets without adjusting for the definition gap produced misleading calibration. I solved it by restricting the analysis to loans with consistent collection practices and building separate submodels for each dataset rather than forcing a single model across heterogeneous records. The workhorse method for estimating PD is logistic regression, and it remains the most widely used approach for good reason. It is transparent, interpretable, and easy to validate. But logistic regression assumes a linear relationship between log-odds and the predictors. When your features include variables like debt-to-income ratios or payment history length, that linearity assumption breaks down in the tails. Spline transformations or segmented models handle that better. I learned this the hard way when a client complained that their model assigned uniformly high risk scores to borrowers with thin credit files, even when their actual repayment behavior was solid. The model was essentially guessing because there was insufficient signal in the data, and logistic regression amplifies that uncertainty rather than accounting for it. For LGD estimation, recovery data is typically skewed and censored. You do not always observe the full recovery amount because collections can span years. A common approach is to use a beta regression or a Tobit model that accounts for the left-censored nature of the data. More recently, machine learning approaches like gradient boosting have gained traction, but they introduce a new problem: interpretability. Regulators and internal audit teams often reject models they cannot explain line by line. The industry standard remains a hybrid approach where ML assists with feature selection and weighting, but the final model is translated into a logistic or piecewise linear form.
EAD modeling is the most overlooked component. Credit lines are dynamic. A borrower may not be in distress when you issue the facility, but if conditions deteriorate, they will draw down aggressively. Converting this drawdown behavior into a single number requires conversion factors that vary by product type, borrower rating, and macroeconomic conditions. I worked on a project where the team used a flat 75 percent conversion factor across all revolving credit facilities. It simplified the work, but it understated EAD for high-risk segments by roughly 30 percent when tested against actual drawdown patterns. The fix was introducing a rating-dependent conversion factor table that updated quarterly based on observed utilization trends. Validation is where most beginner efforts fall apart. Backtesting a credit risk model is not about checking whether the predicted PD matches the actual default rate in a single quarter. It is about assessing calibration across multiple time periods, stress scenarios, and borrower segments. A model can appear well-calibrated on average while systematically underestimating risk for a specific subgroup. I recommend running at least a Population Stability Index analysis quarterly alongside a Hosmer-Lemeshow test, and tracking these metrics by vintage rather than by calendar quarter alone. Vintages reveal how loan cohorts age and whether early payment behavior predicts later default. There are real limitations to keep in mind. Credit risk models perform poorly during structural breaks, such as a pandemic or a sudden regulatory change that alters borrower behavior overnight. Historical data simply does not contain signals from events that have never occurred before. No amount of feature engineering fixes that. In those situations, manual overrides and scenario analysis fill the gap, but those are less precise and harder to defend to auditors. Another limitation is model drift. A model calibrated on five years of stable macroeconomic conditions will gradually degrade as conditions shift. I would expect a well-maintained model to require recalibration at least annually, and more frequently if your portfolio composition changes significantly.
Get the Full Details

If you are just getting started, the most useful resource I know is a practical implementation guide that walks through building a full credit risk pipeline from raw data to validated output. Look for materials that cover data preparation, model specification, validation procedures, and documentation standards. Theory is necessary but insufficient. The gap between knowing the formulas and deploying a model that passes internal review is large and mostly filled by trial and error.