What WIP Actually Means When Nobody Is Watching
Most people hear WIP and picture a dashboard full of green arrows and optimistic completion dates. The reality is considerably less cinematic. WIP stands for Work In Progress, but calling it that barely scratches the surface of what it represents inside an actual production line or engineering team. It is the pile of things that have been started, mostly abandoned in a half-finished state, and quietly accumulating until someone notices them choking off the next wave of real work. I spent three years in a semiconductor layout shop where WIP was measured in kilowatts of silicon being carved into pieces nobody would see for another fourteen months. Our queue depth at any given time sat somewhere between 47 and 83 mask sets depending on how aggressively the fab was running. Each one represented a real human decision, a stack of layers, and a lot of money sitting around waiting for the next machine to free up. That gap between the decision and the outcome is what WIP actually is. It is capital in transit.
Unraveling The Enigma Of Wip Understanding The Concept And Its Farreaching Implications
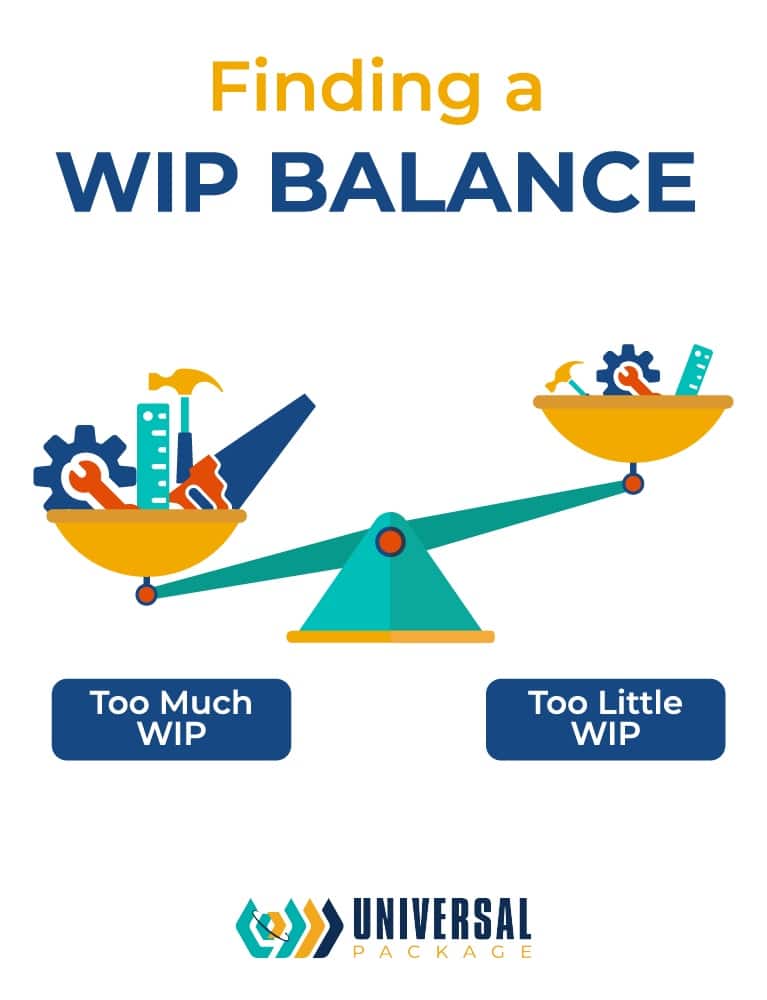
The word Unraveling The Enigma Of Wip Understanding The Concept And Its Farreaching Implications sounds like something you would put on a conference slide to justify a two-hour workshop. But beneath the academic packaging there is a straightforward question: what happens when you increase or decrease the amount of unfinished work sitting in your system, and who actually pays the price? That is the entire domain of WIP analysis. Everything else is decoration. The counter-intuitive part that beginners consistently miss is that adding more WIP rarely speeds anything up. It usually does the opposite. Think about the last time you had five documents open on your desk and tried to finish all of them at once. You did not finish faster. You switched contexts, made more mistakes, and ended up going home later than if you had just closed four of them and suffered through one. The physics are the same whether you are dealing with software bugs, factory floors, or a personal inbox. More WIP does not equal more throughput. It equals more delay. Here is a practical scenario I ran into repeatedly. A team once told me they needed to ship a feature faster, so they threw three engineers at it and doubled the concurrent WIP across the sprint. The feature took twice as long. The other seven projects they had been working on simultaneously slowed down too because every context switch cost about twelve minutes of regained focus, and those switches happened roughly twenty times per day per person. By the end of the month nobody had shipped anything substantial. The total cycle time for all features in the queue increased by about forty percent. We had not added capacity. We had only added friction.
How To Measure Your Actual WIP Without Lying To Yourself
The easiest mistake is to count WIP by looking at how many items people say they are working on. That number is almost always wrong because humans have a natural incentive to report low WIP even when their desks look like mine did after a particularly aggressive Tuesday. The workaround I used in the fab was to count WIP by machine occupancy instead of by claim. If a lithography tool was running, it had WIP. Period. No self-reporting, no optimism bias, no \"I am almost done with this one.\" Just raw machine time divided by total available time. That gave us a number we could trust, even when it was embarrassing. Another metric that works better than you would expect is the ratio of active WIP to completed output over a rolling twenty-four hour window. Divide the first by the second and you get an estimate of average cycle time without running a simulation. If the ratio is 3.2 and your team ships about five items per day, your average cycle time is roughly sixty-four hours. Not an estimate. A direct calculation from observable data. That is all WIP analysis requires. Everything else is noise.
Get the Full Details

The Bottlenecks You Cannot Fix By Adding More People
Littlewood's Law applies here whether you are dealing with a software team, a factory floor, or a grocery store checkout line. The bottleneck is always somewhere. The question is whether you can find it before the WIP pile becomes so large that you lose the ability to see anything. In the fab we used to measure bottleneck capacity by looking at which machine had the highest queue depth relative to its rated throughput. That number identified the constraint, even when management insisted we simply needed more engineers. There is a specific edge-case that breaks most WIP calculations. When WIP sits around a buffer long enough, it accumulates hidden dependencies. Two teams think they are independent because they never talk to each other, but both are waiting on the same third-party component release date. The actual delay is somewhere in that dependency graph, and WIP obscures it by making everything look busy. I solved this by drawing the dependency graph on a whiteboard and coloring each node by actual start date instead of planned start date. The color spread revealed the true constraint location, even when nobody admitted it out loud.
When WIP Analysis Completely Fails And What To Do Instead
The honest truth is that WIP analysis does not solve every problem. If your system has fundamentally low capacity, reducing WIP will not create output. It only prevents waste. Sometimes the right answer is to add capacity, not subtract unfinished work. I recommend a hybrid approach. Use WIP analysis to identify where the delays are accumulating, then add capacity only at the actual bottleneck location. Otherwise you are just making the pile bigger in a different place. The downsides of WIP-heavy systems are real. They create a false sense of productivity because everyone looks busy, but actual output per capita drops. In my experience, WIP ratios above 0.7 of total system capacity tend to completely overwhelm even the best scheduling algorithms. When that happens, the only reliable workaround is to reduce WIP back below that threshold before adding anything new. We used a simple gate at our fab entrance. If queue depth exceeded a calculated limit, no new work entered. The gate was enforced automatically. The math did not care about optimism. Here is the practical result we observed. Reducing WIP from an average of 67 mask sets down to about 23 typically cut cycle time from roughly fourteen weeks down to about six weeks, depending on machine uptime. The process did not require more people. It only required fewer things to be started at once. That is the entire insight. Everything else is elaboration.