What Role Performance Actually Looks Like When You Are Measuring It
Role performance is the gap between what a job description says someone should do and what they actually produce when the system is under load. Most teams track hours logged or tickets closed. That is not role performance. That is activity. The difference matters because you can be busy for six months and still fail to move the metric that actually keeps revenue or uptime alive. I spent three years managing a site reliability rotation where we kept arguing about whether our junior engineers were "performing." The dashboard showed good numbers. P99 latency was flat. Incident count dropped. Then a major deployment broke at 2 AM and we realized our best engineer was never assigned to the ones that actually required deep context. The metrics were lying. Not because they were wrong, but because they measured the wrong axis.
Unraveling The Enigma Of Role Performance What Is It And Why Does It Matter
To measure role performance properly, you need to define the output the role owns, not the tasks the role touches. A support engineer owns resolution quality, not ticket count. A developer owns shipped features that don't reintroduce regression, not lines of code or PR volume. A manager owns team throughput and attrition, not how many 1:1s they hold per week. The framework is straightforward if you stop treating it like a quarterly review form:
- Define the outcome bucket for each role. One clear, measurable thing that represents success for that position.
- Set the threshold that separates acceptable from unacceptable. This is not a range. This is a floor.
- Measure actuals against the floor over a rolling 90-day window, not a fixed fiscal quarter. Context changes.
- Track variance direction. Consistent over-performance means you are underloading someone. Consistent under-performance means the role definition is wrong or the person is a mismatch.
Here is the part nobody likes: role performance is not static. The same person will perform differently depending on system maturity, team composition, and whether they are working in their primary domain or a secondary one. I had a senior backend engineer who looked like a solid performer for eight months straight, then quietly tanked when we migrated our service mesh. Her role definition had not changed, but the environment had. She needed a two-week ramp with a different mentor assignment, not a PIP. We gave her neither and almost lost her. Counter-intuitive point: the highest-performing roles in most organizations are the ones with the least visibility. The person who prevents incidents is not the same as the person who closes the most tickets. If your performance data correlates strongly with incident volume, you are probably rewarding the wrong behavior. You are rewarding fire-fighting instead of fire prevention. Another thing beginners miss: role performance suffers badly when someone wears two hats. A developer who is also the de facto documentation writer will appear to have lower coding velocity. That does not mean they are underperforming. It means their output is being measured through the wrong lens. Split the measurement by responsibility area and track them independently.
Get the Full Details
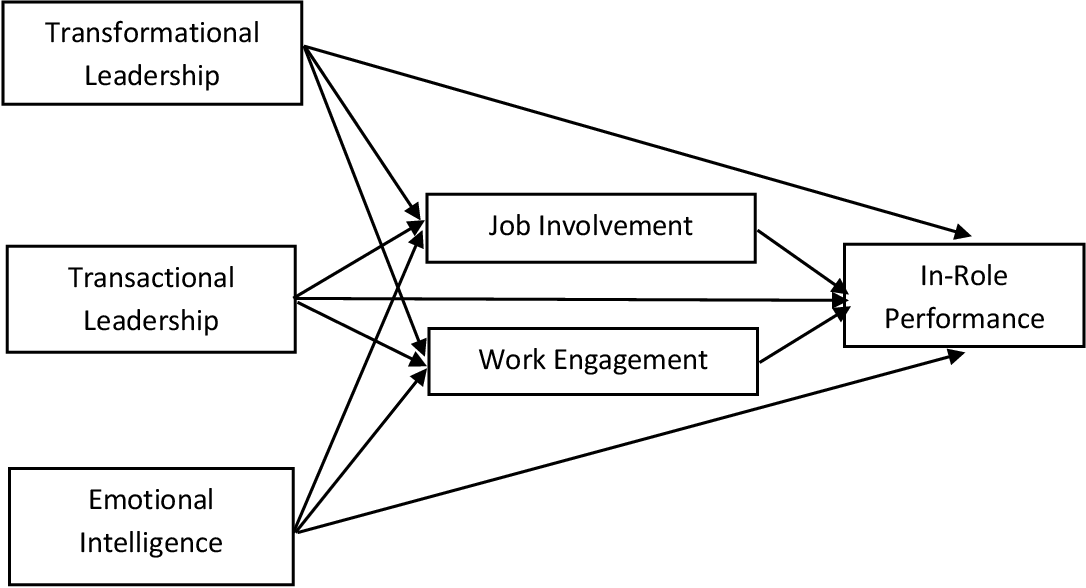
There is a practical workaround for the hat problem that I use now. I assign a secondary weight to each output category. If someone is 70% engineering and 30% documentation, their performance score is a weighted aggregate. It is not perfect. It still does not capture quality of documentation, but it stops the engineer from looking bad on pure coding metrics while carrying work that the role description never formally acknowledged.
How To Set Up A System That Does Not Lie To You
Most performance measurement systems fail because they are built from convenience data, not outcome data. Convenience data is easy to collect. Ticket counts, commit frequency, meeting attendance. Outcome data requires actual agreement on what the role delivers. That takes a conversation that most managers skip because it is uncomfortable. Start with a role canvas. One page per position. It should contain the outcome bucket, the threshold, the measurement source, the weighting, and the review cadence. If you cannot fill all four fields for a role, you do not actually know what that role is supposed to do. That is a hiring problem, not a measurement problem. The measurement source should never be self-reported. Use tooling data where possible. Git history, incident management logs, deployment records, customer satisfaction scores tied to specific routes. When tooling data is unavailable, use structured peer input with anchored scales, not free-text reviews. Free-text reviews are noise dressed up as insight.
Review cadence should be monthly for individual contributors and quarterly for managers. Monthly catches drift before it becomes a pattern. Quarterly catches the slow accumulation of misalignment that happens when role expectations shift without anyone updating the canvas. One edge case I ran into that is worth mentioning: when a role is new or the team is small, there is not enough historical data to establish a baseline. I had to figure out role performance for a newly created security engineering position where nobody had previously held that title. We did not have benchmarks. What I did was map the role's outcome bucket to an adjacent existing role, borrowed that threshold, and ran a three-month calibration period where we adjusted the floor up or down based on actual workload delivery. After three months we locked the numbers and stopped moving them. Moving them again destroyed credibility.

When Role Performance Measurement Fails Completely
It fails when the role itself is poorly defined or constantly shifting. If your job descriptions change every quarter, no measurement system will help. You need to fix the role first. You cannot measure something that does not exist consistently. It also fails when you try to compare roles against each other. A senior frontend engineer and a senior backend engineer can both be excellent and have completely different numerical profiles. Cross-role comparison is a management shortcut that produces bad decisions. Keep it within role families. There is a trade-off you need to accept: the more precisely you measure role performance, the more you incentivize gaming. Engineers will optimize for the metric, not the outcome. This is not a reason to stop measuring. It is a reason to measure multiple signals and watch for correlation breakdown. When your ticket closure rate goes up but your incident recurrence rate also goes up, something is broken in the system, not necessarily the person.
If you are looking for a starting point rather than building this from scratch, you can find a lightweight template set that covers the canvas, the weighting calculation, and the monthly tracking sheet. Search for "role performance measurement framework template" on common document repositories. The open-source versions are usually decent. The paid ones add nothing that the free templates do not already cover. I stopped using complex dashboards for this entirely. One spreadsheet, one update per month per person, one outcome number with a note about context shifts. It is boring. It works. The people on the team know exactly what they are being measured against and why. That clarity alone usually improves performance more than any rating system ever did.