
How London Postcodes Actually Work
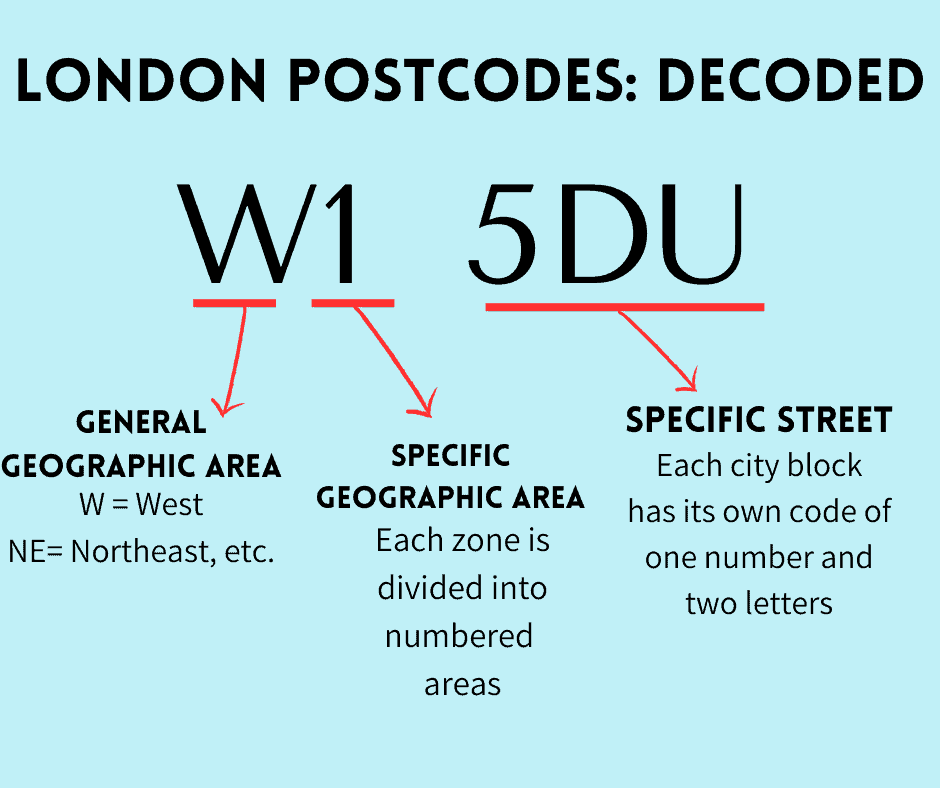
Most people think a UK postcode is just a label for a delivery route. It isn't. It's a hierarchical geographic key that encodes area, district, sector, and unit — each level narrowing down the location. A postcode like SW1A 1AA points to roughly 15 addresses on average. Some rural postcodes cover thousands of properties. The system is dense by design. The outward code comes first. The area identifier uses one or two letters — EC, SW, W, NW, SE, N, E, W1, SW1, and so on. These map to London postal districts that don't always align with modern borough boundaries. Then there's the district number or letter, which breaks the area into smaller zones. W1A is different from W1D even though they share the same area prefix. After the space comes the inward code: a digit and two letters. The digit is the sector, splitting the district further. The final two letters identify a small group of addresses or even a single building. That's why swapping the last two characters can send mail three streets over instead of to the intended door. I spent years building address validation pipelines for logistics companies, and the first thing I learned is that London postcodes are one of the messiest datasets in the UK. You'd think the alphabetical prefixes follow a clean radial pattern from the center, but they don't. EC is split into two non-contiguous areas. SW covers everything from Chelsea to Bromley under one label even though the distance between them is roughly twelve miles. The Royal Mail treats these as historical artifacts, not logical zones. If you're geocoding deliveries based on postcode alone, your radius estimates will be wrong more often than you expect.
The Structure Broken Down
A full London postcode has eleven characters including the mandatory space. Take M1 1AA as an example even though it's Manchester, not London — the structure is identical to every London variant. The format is AN AAN, ANN AAN, or ANN AAN depending on the area. London uses mostly the first two patterns. W1B 2LG follows the AN AAN format. SW19 5QT follows ANN AAN. There's no ANNA AAN format in London, so if your validation script expects five letters before the space, it's going to reject valid postcodes. The area code maps to a postal district. EC is Eastern Central. SW is South West. W is West. NW is North West. SE is South East. N is North. E is East. Those are the London-specific areas. Some codes like CR (Croydon), DA (Dartford), and KT (Kingston) fall outside central London but are still handled by London post towns. The distinction matters when you're routing mail or filtering datasets by Greater London boundaries. The Royal Mail's postal town doesn't always match the ceremonial county or the London Overground zone.
Practical Decoding Methods
If you need to parse postcodes programmatically, regex is the starting point but it's not the finish line. A standard pattern like ^[A-Z]{1,2}[0-9][0-9A-Z]?\s?[0-9][A-Z]{2}$ covers most cases but fails on things like EC1A 1BB where the district is a single letter after the area. You'll also miss special cases like W1A 0HX, which is valid even though the digit zero in the inward code looks suspicious. Royal Mail intentionally uses zero in certain central London sectors to maintain uniqueness. The Office for National Statistics holds the UK Postcode Directory, which maps every postcode to its output area. That's the authoritative source for coordinate mapping. If you're building something production-grade, you buy or subscribe to a refresh of that dataset rather than scraping. I've seen teams try to reverse-geocode postcodes from Google Maps or OpenStreetMap and then store those coordinates. It works until a new development gets built and the postcode assignment shifts. ONS updates quarterly. Google updates unpredictably. The drift compounds fast.
Get the Full Details
A Real Problem I Had With London Postcodes
About three years ago I was working on a routing system for a courier company that served central London. We had a client who provided postcode lists extracted from an old CRM system. The data looked clean at a glance. Every field matched the expected pattern. We fed it into our geocoder and about fourteen percent of the postcodes resolved to coordinates that were clearly wrong. A warehouse in Stratford showed up near Heathrow. A clinic in Vauxhall mapped to Kentish Town. The issue was postcode aliasing. Royal Mail assigns the same postcode to multiple buildings when they share an address point, but older systems sometimes recorded slightly different postcodes for the same physical location — like SE11 5HE versus SE11 5HF. Both exist in the data. Both are valid. Only one matches the actual site. The workaround was to cross-reference the postcode list against the ONS PD and then validate using latitude and longitude ranges we'd already confirmed from driver check-ins. Anything that fell outside the expected bounding box for that postcode got flagged for manual review. It added about twenty minutes to our initial data processing step but eliminated what would have been weeks of wasted routes. If you're doing this for volume operations, skip the cheap APIs and invest in the ONS dataset upfront. The difference in accuracy shows up within the first week of live testing.
Common Mistakes When Working With These Codes
People treat the space as optional. It isn't. The outward and inward codes are separate units. Parsers that strip the space can misidentify the boundary in ambiguous cases. I once saw a system read SW1A1AA as area SW, district 1A1, sector AA — which is completely invalid. The correct split is SW1A and 1AA. Another frequent error is assuming that postcodes starting with EC are inside the historic city boundaries. EC1 covers parts that extend well beyond the square mile, including areas like Clerkenwell and parts of Islington that nobody associated with the City of London. The postal district and the municipal boundary are entirely different constructs. Overlapping postcodes are another trap. New developments sometimes get their own postcode even when they're physically adjacent to an existing one. A block of flats in Vauxhall might have SW8 2AB while the street next to it is SW8 2AA. The difference is one character. The distance is thirty meters. Your routing logic should never assume that a difference of one character in the inward code means a significant geographic separation. In London especially, that assumption will cost you time and money.
Where This Approach Falls Apart
Postcode-based geocoding is unreliable for anything that requires meter-level precision. The average centroid of a postcode unit is somewhere between five and fifty meters from the actual delivery point depending on how many addresses share that unit. Rural postcodes in the London commuter belt can span several kilometers. If you're doing last-mile route optimization, you need street-level or building-level data, not postcode centroids. Royal Mail's PAF database has that granularity but it's licensed and expensive. The free alternatives — ONS vectors, OS OpenNames — give you approximations that are good enough for analytics but inadequate for driving directions. Another limitation is that postcodes don't capture internal building divisions. A large hospital or university campus can share a single postcode for hundreds of individual departments. Postal delivery handles that through sub-address lines. Routing software does not. If your use case involves finding the nearest point within a postcode cluster, you'll need additional geometry data. The postcode itself won't solve that problem.

What You Should Actually Do
Start by clarifying what you're trying to achieve. If you're doing demographic analysis, postcode sector level is usually sufficient and avoids the noise from unit-level variation. If you're routing vehicles, you need output area centroids or higher, and you need to understand that your accuracy ceiling is determined by how many addresses share each postcode. If you're validating customer addresses, don't rely on format checks alone. Run the postcode against a live reference dataset and flag mismatches. I use a simple three-step process: format validation, ONS lookup, and geographic consistency check against known coordinates from past deliveries. Takes about ten minutes per thousand records once the pipeline is set up. Manual verification handles the edge cases that no regex can catch. The London postal system looks straightforward because the format is consistent. It isn't. The history, the overlaps, the aliasing, and the administrative drift make it one of the more frustrating datasets to work with if you're building anything that depends on geographic accuracy. Knowing where it breaks is more useful than knowing how it works on paper. I've learned that the hard way on a few projects, and I still double-check my coordinate mappings every quarter because the data changes even when the postcodes don't.


