
How London Postcodes Actually Work
Most people think a postcode is just a label for mail delivery. It is more precise than that. A London postcode breaks down into an outward code and an inward code, separated by a space. The outward code covers a district, usually a whole area or part of one. The inward code narrows it down to a street or a group of addresses. A single postcode can cover as few as ten houses, or as many as a hundred depending on density. I have spent years working with address data for logistics and mapping projects, and I will tell you flatly that London postcodes are not simple to parse. The Royal Mail Addressbase dataset is the source of truth, but even that has quirks. Let me walk you through what is actually happening when you try to decode them.
Unravel The Secrets Of London A Deep Dive Into Decoding Postcodes
London postcodes are organised by area letters and district numbers. SW stands for South West, EC for Eastern Central, WC for Western Central. These are the tricky ones. Then there is M, B, L, and others that extend beyond the Greater London boundary but are still treated as London postcodes in many systems. You will lose hours if you assume every postcode starting with two letters and a number falls inside Greater London. It does not. Here is how the format breaks down structurally: The first part, the outward code, contains the area and the district. SW1 is a real outward code. SW1A is another. The second part, the inward code, is always three characters. A digit followed by two letters. 1AA, 1BB, and so on. The digit represents a sector. The two letters represent a unit, often a single large address or a small street.
When I built parsers for this, I learned quickly that you cannot rely on regex alone. A naive pattern like ^[A-Z]{2}\d[A-Z0-9]?\s?\d[A-Z]{2}$ will match things that do not exist. There are invalid combinations that technically fit the format but are not assigned to any real address. I had a pipeline that accepted SW1X 9ZZ as valid, and it turned out that postcode covers one single building, a hotel in Belgravia. The data was technically correct but completely useless for routing deliveries at scale. The workaround was straightforward. I cross-referenced every parsed postcode against the Royal Mail PAF database, which is not free. After that, I added a secondary check using OpenStreetMap geocoding to flag any postcodes that returned no coordinates. That caught the edge cases I was missing.
Get the Full Details

The Practical Problems You Will Hit
Parsing a postcode string is easy. Making it work in production is where people struggle. Here are the real issues I encountered. Spaces and formatting inconsistencies. Some datasets omit the space between outward and inward codes. Others use non-standard spacing. You need a sanitisation step that removes all whitespace and then reinserts a single space before the last three characters. This takes maybe ten lines of code, but skipping it causes silent failures downstream. Duplicate postcodes for different entities. Large organisations have their own postcodes. The BBC has W1A. Some government buildings have postcodes that are accurate but not useful for geographic routing. If you are building a delivery system, you will need to decide whether to treat these as valid or filter them out. I filtered them using a blocklist derived from known large-user postcodes.
Postcodes that change over time. Royal Mail assigns new postcodes regularly, especially in new housing developments. A postcode that existed in 2022 might have been retired by 2024. If your system stores historical addresses, you need to track date ranges. Without that, you will have data that looks correct but points to addresses that no longer accept mail. Overlapping areas. Some postcodes sit on the border of two districts. SW19 touches CR0, which is Croydon but sometimes grouped with London. Your parsing logic should not enforce a strict boundary unless your use case requires it. Most people do not need that level of rigidity.
What You Can Actually Build With This
Once you have a reliable parser, the applications are straightforward. Geographic segmentation for marketing. Delivery route optimisation. Property valuation models that use postcode-level data. Crime mapping. All of these depend on the same foundation: accurate postcode decoding. For a practical implementation, start with the Addressbase Premium dataset from Royal Mail. It costs money, but it is the most complete. If budget is tight, OS Places or OpenDataStreet are acceptable alternatives. OpenStreetMap alone is not enough because it does not contain the full postcode geometry you need for precise matching. Here is the basic parsing logic I use:
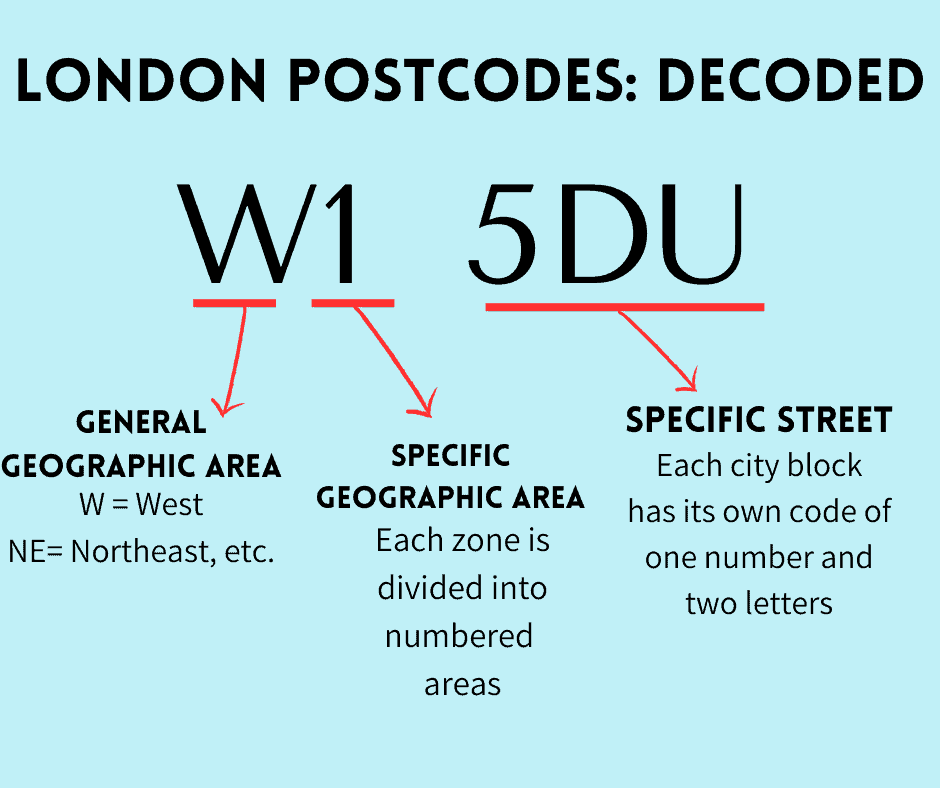
Strip all whitespace from the input string. Validate that the remaining string matches the expected character count and pattern. Split at the third-from-last position to separate outward and inward codes. Query a postcode lookup table. If the query returns no result, flag it for manual review rather than discarding it outright. Flagged postcodes should be batch-checked quarterly because the dataset updates regularly. I should mention the limitations clearly. Even with Addressbase Premium, coverage is not perfect. Some rural fringe areas within the London postcode region have incomplete data. New builds may not appear for months after construction. Postcodes that were decommissioned can linger in legacy datasets and cause mismatches. If you are working with historical records, always add a timestamp to your postcode lookups and store the version of the dataset you used. I have seen teams lose weeks of work because they assumed their postcode data was current when it was actually two years outdated. The bottom line is that decoding London postcodes is not a hard problem. It is a tedious one. The format is consistent enough that automation works well. The edge cases are what will trip you up. Build your system with validation layers, keep your data sources current, and do not trust regex to do all the work on its own.


