So You Want To Talk About Yottabytes
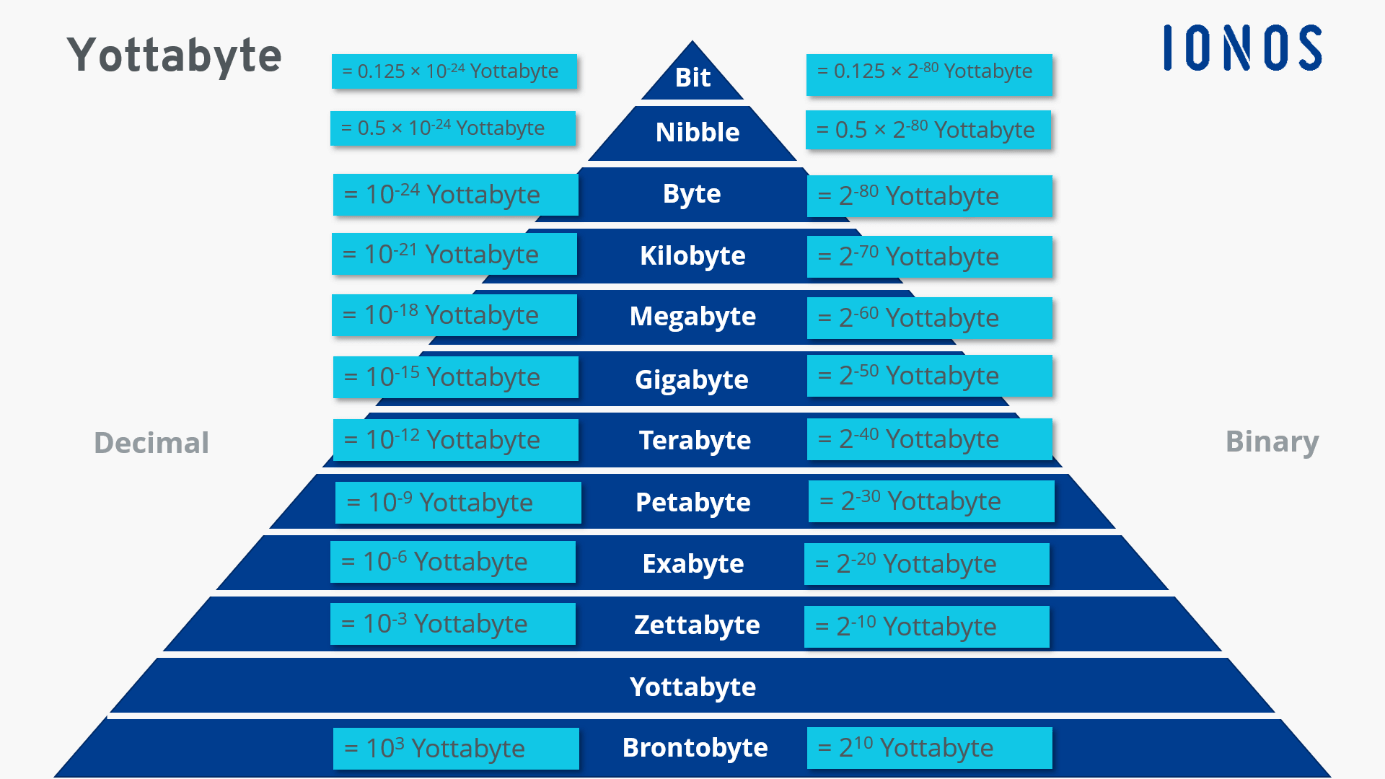
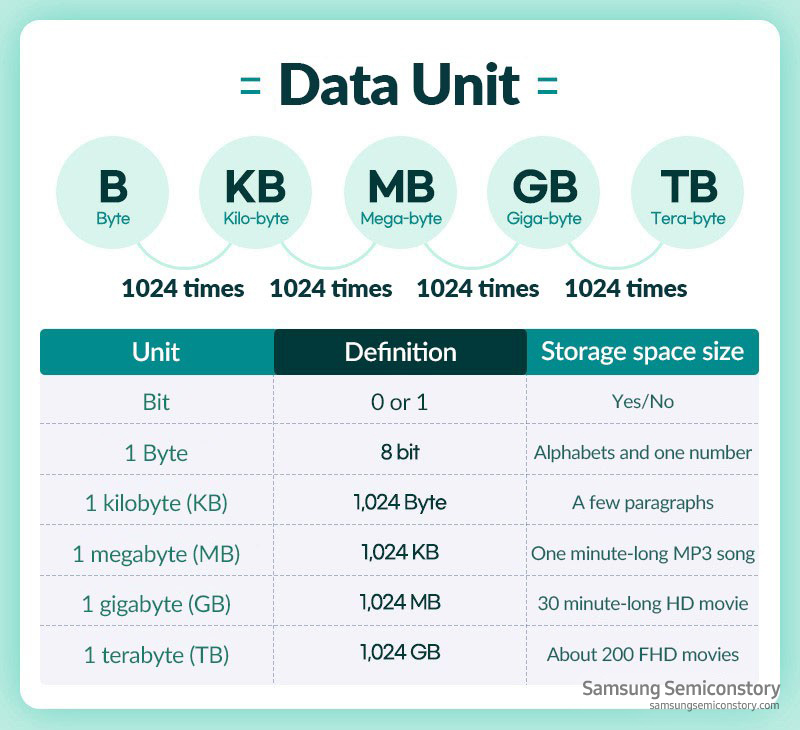
Most people stop at terabytes or petabytes because that's where their storage hierarchy ends. The yottabyte is 10 to the 24th power, or more precisely in binary terms 2 to the 80th power depending on whether you are using SI or IEC units. That distinction matters more than people admit because the difference between a YiB and a YB is about 4% and it compounds when you are actually doing calculations on a scale this large. I ran into this problem last year when a client needed to size a cold storage tier for seismic imaging data. They wanted to fit twelve years of raw survey lines and the quote came in around 1.4 yottabytes. Not the total capacity, just the uncompressed raw files. The moment you hit that scale the math breaks from what any spreadsheet can handle cleanly. You need a different mental model. Here is the practical breakdown. One yottabyte equals one trillion terabytes, one billion petabytes, or one million exabytes. In binary it is 1,024 yobibytes in a zettabyte and each step down multiplies by 1,024. Most vendors selling storage at this level use decimal rather than binary. If you order "one yottabyte" from a hardware supplier they will likely deliver roughly 0.909 YiB of actual addressable space. Factor that in before you do any capacity planning or you will be short somewhere around ninety-one exabytes.
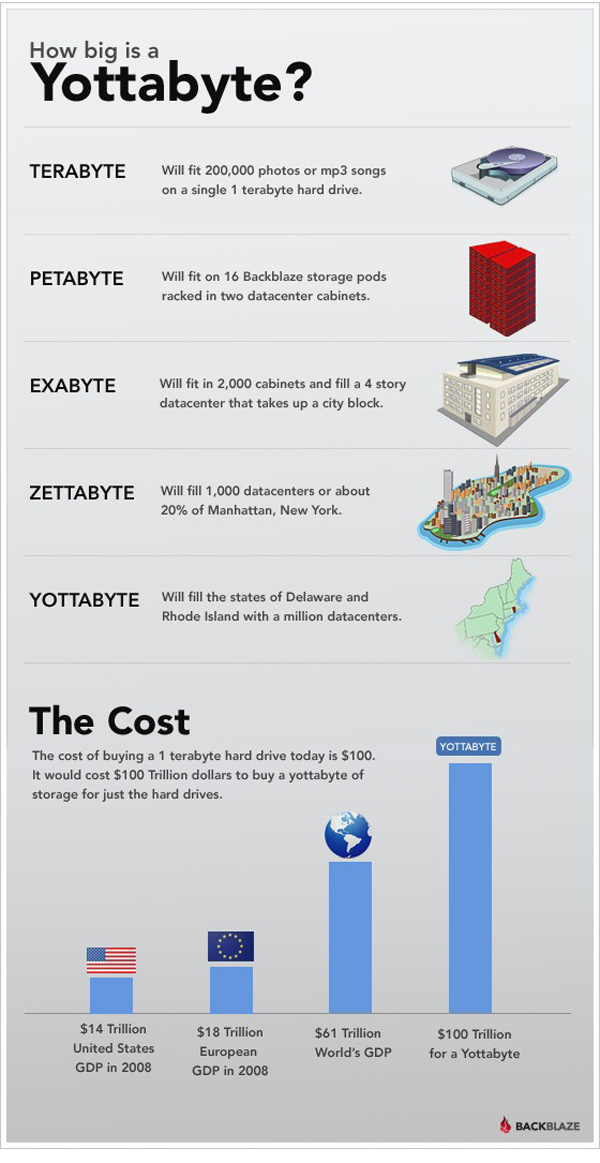
The IEEE naming convention adds Yobi for the binary version and Yotta for decimal. That is not just semantics. When you are writing scripts to track allocation across arrays that span continents, mixing the two up will quietly corrupt your reporting by a factor large enough to trigger unnecessary procurement calls. I learned this the hard way after a vendor audit flagged a discrepancy in one of our long-term archive contracts. The finance team had been forecasting against decimal but the engineers were provisioning against binary. It took three weeks and a Python script that normalized everything to base 2 to get the ledger to match. At this scale you stop thinking in terms of drives and start thinking in terms of sites. A modern HDD sits at about 26 terabytes per unit for consumer drives and maybe 36 terabytes for enterprise SMR drives. That means you would need roughly thirty-eight million of those 36 TB drives to approach one yottabyte. Multiply by shelf density, rack space, power, cooling, and network fabric and you are looking at a facility that could fill several city blocks. The actual global digital universe is estimated somewhere between fifty and a hundred zettabytes right now so we are still talking about capacity that does not exist in a single deployment. There is one counter-intuitive thing nobody mentions when they talk about yottabyte-scale systems. Bandwidth becomes a harder constraint than raw storage. If you are moving data between geographically distributed nodes at ten gigabits per second you are looking at roughly 8,760 terabytes per year per link. That means you need about one thousand parallel 10 GbE links just to ingest data at the rate one yottabyte would accumulate in a year. Most people size the storage and forget to size the transport layer.
I also had to deal with a metadata problem at this scale that absolutely wrecked our initial architecture. We were storing every file as an object in an S3-compatible system and the bucket namespace started degrading past a certain threshold. AWS itself recommends keeping sub-100 GB per key prefix and at yottabyte scale you are forced into deeply nested partitioning schemes that look like dates, geographies, or asset classes sliced dozens of levels deep. The workaround was to switch from a single flat namespace to a layered hash partitioning strategy. Instead of s3://bucket/year/month/day you go s3://bucket/hex-prefix-4/hex-prefix-2/object-key. That keeps read patterns predictable and avoids the hot key issue that shows up when millions of sensors report simultaneously. Compression ratios also behave differently than you expect. At the petabyte level you can usually get two-to-one on scientific data with tools like Zstandard or zstd-fast. At yottabyte scale the compression ratio drops because redundancy gets distributed across so many heterogeneous sources that the common patterns break down. My best result on a mixed dataset of seismic, LiDAR, and satellite imagery was closer to 1.4 to 1. Do not bet your capacity model on a two-to-one squeeze. Plan for 1.3 to 1.5 and add a contingency buffer or your tiering strategy will fail on the first winter migration. If you are actually designing for this kind of scale the first thing you should do is pick a unit system and stick with it. Decimal for billing and procurement, binary for provisioning and software. Document it in a single sentence at the top of your design spec and never deviate. The second thing is to model your I/O profile before you model your storage. You will spend less money on networking upgrades if you know whether your workload is sequential bulk ingest or random query. They require completely different hardware profiles.
Get the Full Details

The yottabyte is not a marketing term. It is a legitimate planning unit for things like national climate model archives, global sensor networks, or any project that expects to accumulate data faster than current archival strategies can handle. The numbers are unwieldy and the edge cases pile up quickly. But if you keep the unit system straight, respect the bandwidth bottleneck, and partition your metadata early, it is just arithmetic at a larger scale.