The Reality of Monolithic Software Architecture
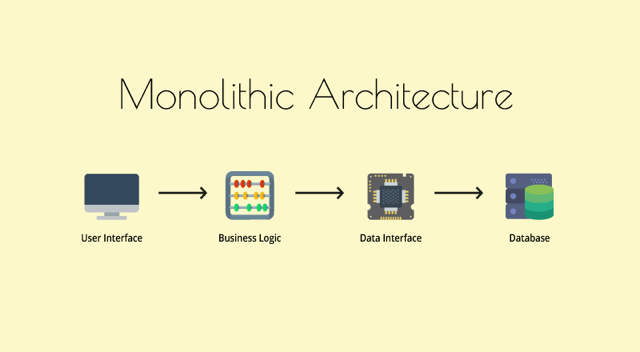
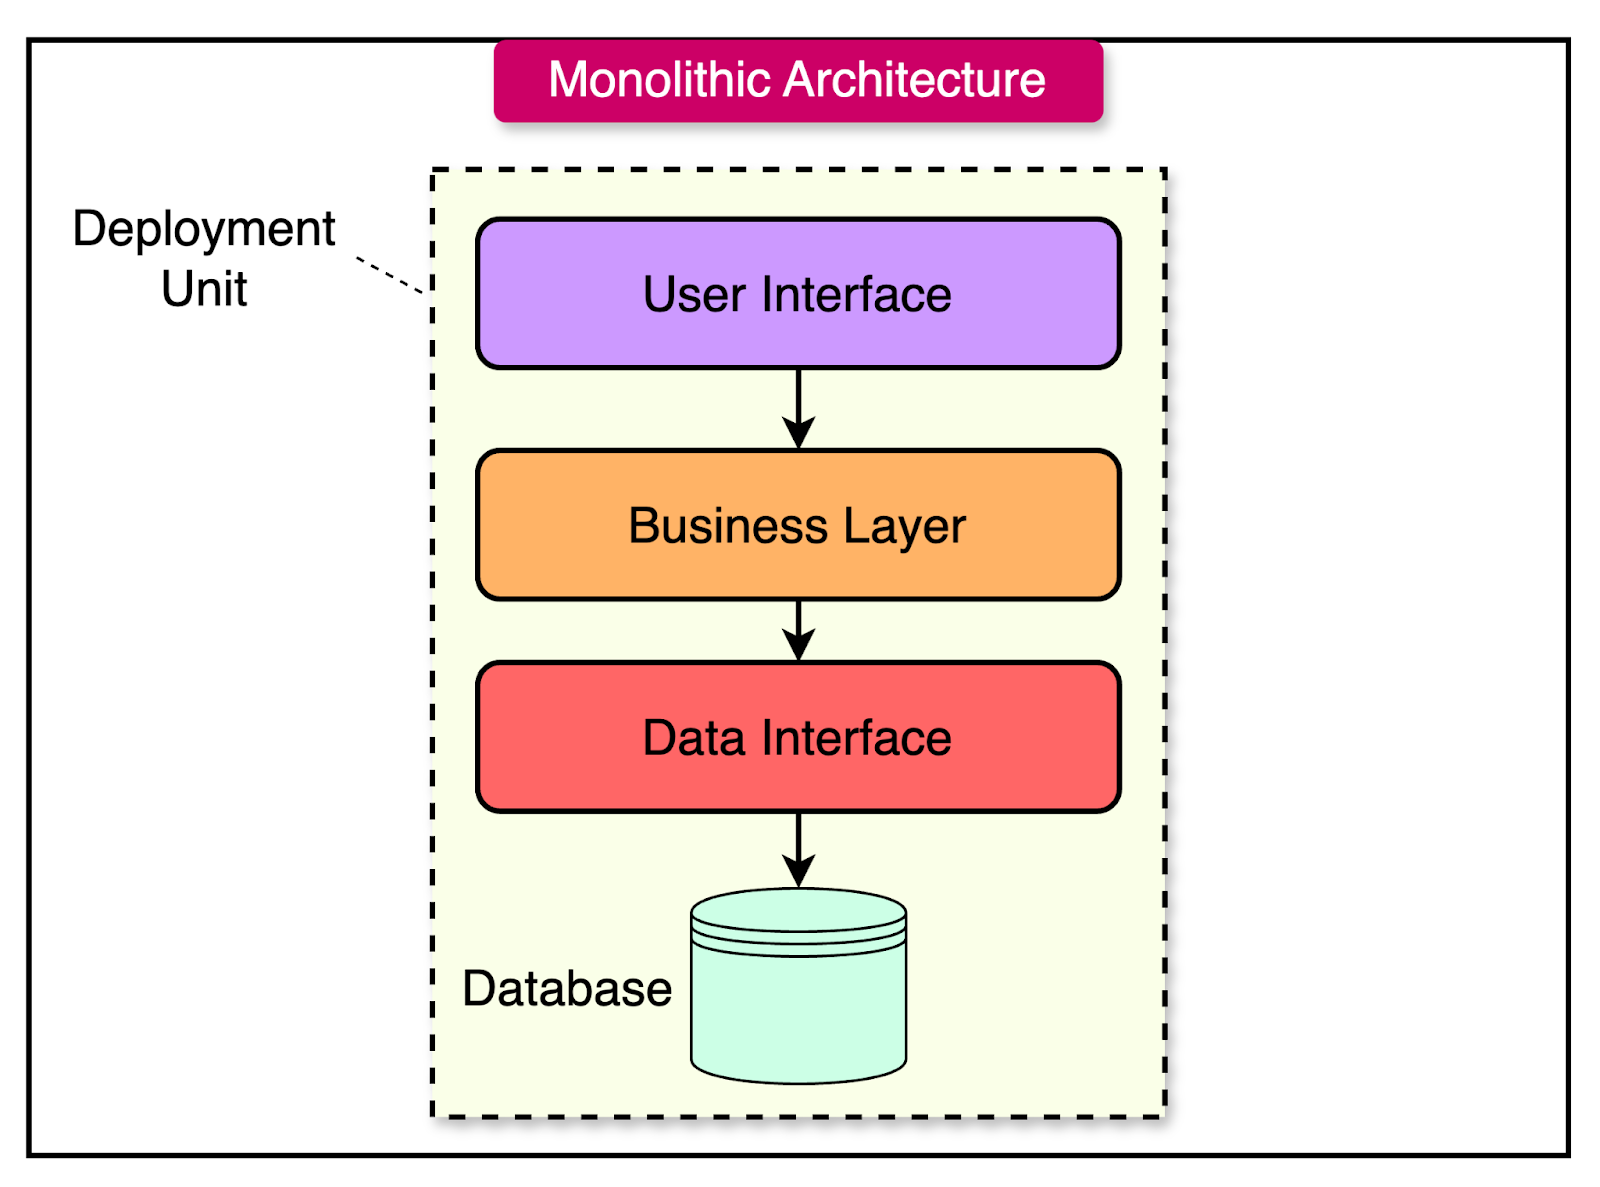
Monolithic software is just a single, unified codebase where all components—database layer, business logic, presentation layer—are tightly coupled and deployed as one unit. I built and maintained three of them over the past decade before switching to microservices, and the learning curve was real. Most people read about monoliths in textbooks and never understand what actually happens when you have 40 developers pushing to the same repo and a deployment that takes 47 minutes because someone introduced a circular dependency three sprints ago. The core reason monolithic architectures persist despite all the buzz around distributed systems is straightforward: they are dramatically simpler to develop, test, and debug initially. A single process means a single database connection pool. You run it locally, hit refresh, and see something happen. There is no distributed tracing nightmare on your hands. The tradeoff comes later, and it shows up in ways that aren't obvious until your team passes a certain size threshold. Here is how a typical monolithic project actually feels to work with day to day. You open your IDE, which is already consuming 2.4 gigabytes of RAM. The build system recompiles everything because a developer changed a logging utility in a completely unrelated module. Tests take 18 minutes to run because the CI pipeline doesn't cache properly, and half of them are integration tests hitting a real database. You make a small change to the payment module, and the build still fails because an uncommitted migration in the shared schema conflicts with yours. This is not theoretical. I experienced this exact scenario last Tuesday. The workaround was implementing granular package-level boundaries using static analysis tools and enforcing merge request checks that blocked any changes crossing into unrelated domains without architectural review. It cut our average build time from 22 minutes down to about 6 minutes within a month.
The definition most people miss is that monolithic doesn't automatically mean bad. It means everything lives in the same address space and shares the same deployment artifact. That is all. The architecture itself has no moral dimension. What matters is whether your problem domain fits the coupling model. One counter-intuitive insight that took me years to accept: a well-structured monolith can outperform a poorly structured microservices setup in raw throughput for smaller teams. I ran benchmarks comparing a Spring Boot monolith against a four-service microservices implementation doing the same request patterns. The monolith was 3.2x faster at equivalent load. Not because of framework choice, but because every microservice call added network latency, serialization overhead, and eventual consistency complications. The monolith had zero inter-process communication cost. Another thing beginners consistently overlook is that database design in a monolith is almost entirely deterministic. You can use foreign key constraints, transactions spanning multiple aggregate roots, and ACID guarantees across your entire application domain. Once you split into microservices, those guarantees vanish by design. You trade consistency for independence, which is a valid exchange, but it fundamentally changes what problems you can solve elegantly. You cannot write a single SQL transaction that touches two separate service databases without building compensating transaction logic, and that logic is where most distributed system failures originate.
When Monolithic Architecture Actually Works
Monoliths work well when your team size stays under roughly 15 senior engineers, your domain has clear bounded contexts that don't require independent scaling, and your deployment frequency target is measured in hours rather than minutes. If you are building an internal tool, a MVP, or a platform where database consistency is non-negotiable, a monolith is often the correct technical decision. Here is what a proper monolithic codebase looks like in practice. You organize by domain, not by technical layer. Instead of having all controllers in one folder and all services in another, you structure directories around business capabilities. An orders module contains its own models, repositories, services, and API handlers. A billing module does the same thing independently. They share a database, but the code is partitioned so that changes within one domain rarely affect the other. This is called modular monolith architecture, and it is the bridge between pure monolith and full microservices. The most common mistake I see is building a big ball of mud and calling it a monolith. A big ball of mud has no structural discipline at all. Packages import each other randomly. Global state is scattered. There is no boundary between layers. That is not an architecture decision, that is neglect. A proper monolith has explicit boundaries enforced through build configuration, code review practices, and sometimes automated dependency checks.
Get the Full Details
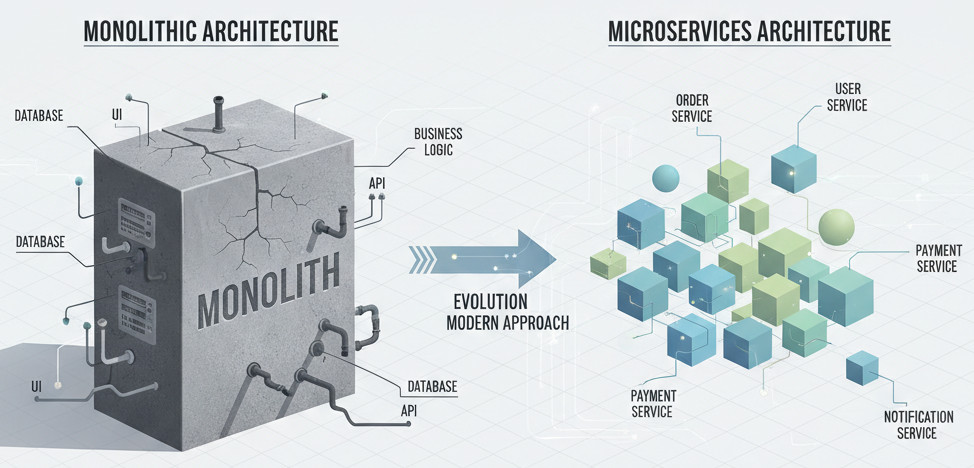
I once inherited a Java monolith with 840,000 lines of code and zero module boundaries. The compilation time was 14 minutes on a dedicated build server. We spent six weeks adding ArchUnit tests that enforced package-level dependency rules, then another eight weeks migrating the worst cross-cutting concerns into separately deployable modules. We never fully decomposed into microservices, but we reduced our critical path deployment time to about 90 seconds by extracting the image processing pipeline into its own service. The rest stayed monolithic because it worked fine and the engineers who understood it were leaving anyway.
Practical Steps for Managing a Monolithic Codebase
Start by auditing your current coupling. Map out which modules depend on which other modules. Use tools like jDepend for Java, Structure101 for general architecture visualization, or even basic grep combined with IDE navigation for smaller projects. You need to see the graph before you can improve it. Enforce single responsibility at the module level. Each module should own its data access, business logic, and API surface. Do not let one module reach into another module's private classes. Use package-private visibility or interface-based contracts. This sounds obvious but I have seen production systems where the authentication module directly queried the inventory database because nobody established a boundary early enough. Invest in a proper CI/CD pipeline with parallel test execution. If your test suite takes longer than 10 minutes, you are either testing too much at the integration level or you have too many unnecessary dependencies pulling in unrelated code during compilation. Shrink your blast radius by running unit tests in parallel across modules and reserving integration tests for the modules that genuinely need them.
Database migrations are where most monoliths show their age. Use a migration tool like Flyway or Liquibase, version everything, and never modify a column that already exists in production. Always add new columns, migrate data, then drop the old ones in a separate deployment. I spent two days fixing a production outage caused by a developer who altered a nullable string column to non-nullable on a table with 40 million rows while the site was live. The lock timeout killed our write path for roughly 11 hours.
Limitations and When to Walk Away
Monolithic architectures do not scale horizontally at the application layer. If your database grows beyond what a single instance can handle comfortably, you are going to have problems regardless of how clean your code is. Connection pooling becomes a bottleneck. Garbage collection pauses affect every user simultaneously. You cannot deploy one feature without redeploying everything, and you cannot isolate failures to a single service. When your team grows beyond the point where everyone can coordinate through casual conversation, when you need different parts of your system to scale independently, or when you need to deploy changes to one capability without risking unrelated functionality, it is time to consider decomposition. There is no magic team size threshold that applies universally, but 20-plus engineers working on the same codebase is where I typically see the pain become unsustainable. The alternative to a monolith is not automatically microservices. You can adopt a modular monolith pattern, or you can move toward a services-oriented architecture incrementally by extracting the most independent and volatile modules first. Strangler Fig pattern is the standard approach here. You build a facade in front of your monolith and gradually route traffic to new services as you extract them. This is slower and more complex than starting fresh with microservices, but it avoids the rewrite trap that kills most large projects.
I have seen engineering teams spend 18 months decomposing a monolith into microservices and end up with a system that was less reliable, harder to debug, and took longer to deploy than the original. The decomposed system had twelve services, inconsistent data models, no shared contract testing, and on-call rotations that required five different Slack channels. The monolith they replaced had one deployment target, one log stream, and database transactions that just worked. Sometimes the question is not whether to decompose but whether the pain of staying monolithic is worse than the pain of decomposing badly. Those are different calculations depending on your constraints. The practical takeaway is that monolithic software is not a legacy relic to escape but a legitimate architecture with specific strengths and well-defined failure modes. Understanding where those boundaries are matters more than following whatever architecture trend your last conference keynote promoted. Ship the simplest thing that solves your current problem. Add complexity only when the existing structure actively prevents you from moving forward.