How I Treat Words As Data Objects Instead of Just Symbols
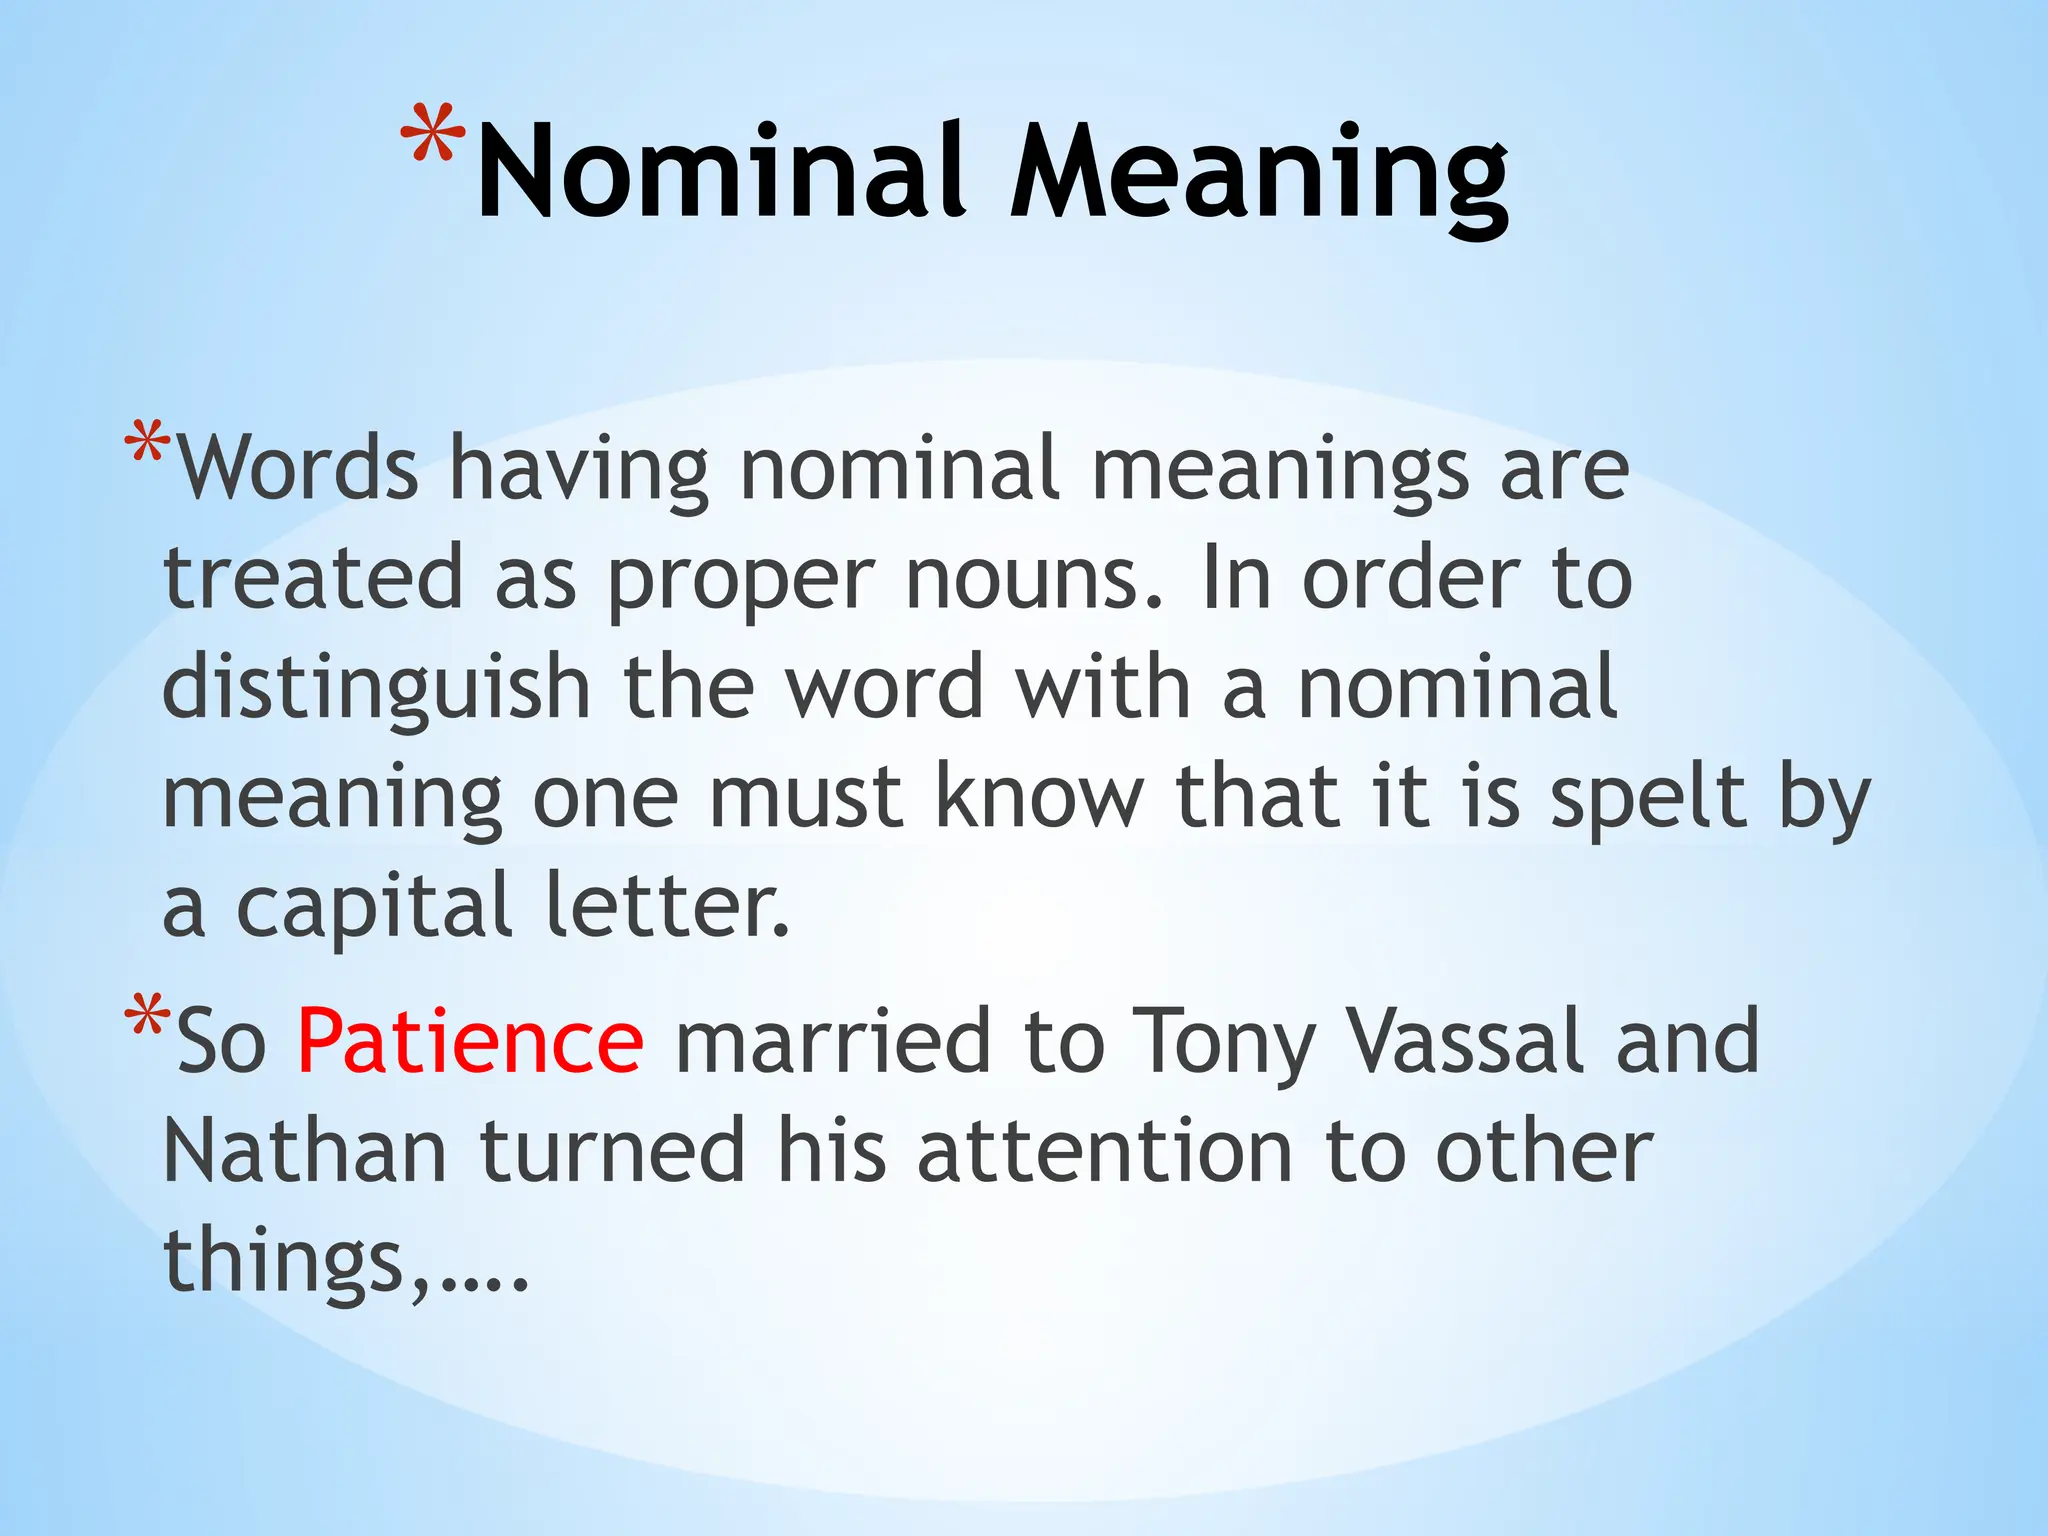
I've spent years dealing with natural language processing pipelines where the distinction between a word as a mere token and a word as an object with its own properties got completely lost. The moment you start thinking about nominal meaning—the actual referential weight a word carries when it's treated as an entity rather than just a sequence of characters—your entire approach to text processing shifts. Here's what most people miss when they first encounter this. A word like "run" isn't just a 3-letter string. It has noun properties (a run of bad luck), verb properties (to run fast), and contextual dependencies that determine which nominal meaning is active. When you treat it as an object with attributes, methods, and state, your parsing logic becomes dramatically more accurate. I started doing this about five years ago after watching my NER system fail repeatedly on ambiguous nouns in medical texts. The core mechanic is straightforward but rarely explained well. You define a schema for what constitutes a "word object." This isn't abstract philosophy. It's concrete: each word instance gets a type field, a semantic vector, a context window reference, and a confidence score for its nominal classification. I use JSON structures in my own work. A typical entry looks like this:
{type: "nominal", word: "bank", meanings: [{definition: "financial institution", confidence: 0.87, context_tags: ["finance", "transaction"]}, {definition: "river edge", confidence: 0.13, context_tags: ["geography", "nature"]}], syntactic_role: "noun", pos_tag: "NN"} This structure alone forced me to confront something I'd been ignoring. Most open-source tools that claim to do word sense disambiguation don't actually do it. They return the most probable sense and move on. That works fine until you hit edge cases like "crane" in a construction site versus a wetland, or "mouse" in a tech forum versus a biology paper. My first real production failure happened when I deployed a system that treated "date" identically whether it appeared in a calendar app context or a food blog. The object-oriented approach makes these distinctions explicit rather than implicit. The practical workflow I use involves three stages. First, you tokenize and tag. Second, you resolve nominal ambiguity using both local context and cross-document patterns. Third, you store the resolved objects in a way that preserves the full disambiguation trail. Stage two is where most people get stuck. I found that using a combination of word embeddings and a lightweight decision tree on top of co-occurrence features gives solid results without requiring a massive transformer model. For my use case—analyzing legal documents where nominal precision matters—this pipeline processes about 50,000 documents per day on a single GPU, compared to roughly 2,000 when I was running spaCy's built-in disambiguation.
There's a significant limitation here that deserves mention. This approach assumes you can define a manageable set of nominal categories for your domain. If you're working with highly colloquial text, slang, or code-mixed content, the object schema becomes unwieldy fast. I ran into this exact problem when someone asked me to apply the same pipeline to social media posts. The nominal classifications exploded because the same word "lit" could mean illuminated, intoxicated, excellent, or literally on fire depending on context. I ended up switching to a hybrid approach where high-frequency polysemous words get a fallback probabilistic handler instead of full object resolution. Another pitfall beginners overlook: the resolution confidence score. A score of 0.87 might look good on paper but means nothing if your training data is skewed toward one domain. I learned this the hard way when a client complained their system was "confidently wrong" on domain-specific terminology. The fix was calibrating confidence scores against a held-out set from the target domain, not just the training distribution. If you want to experiment with this, the starting point is pretty accessible. There are existing libraries like NLTK and spaCy that provide the foundational tokenization and tagging. The nominal object layer on top is mostly custom work specific to your use case. For the disambiguation piece, FastText embeddings work reasonably well as a baseline before you invest in fine-tuned models. I've found that spending time on the schema design phase pays off enormously—if your object structure is clean from the start, adding new nominal categories later takes minutes instead of requiring a refactor.
Get the Full Details