What a Privacy Policy Formal Feed Actually Is
A privacy policy formal feed is a machine-readable output that structure a website's or app's privacy disclosures into a consistent format. You will see them as JSON-LD, XML, or structured RSS-style documents that extract the key clauses from the long legal text and put them into defined fields. The goal is straightforward. It lets auditors, scrapers, compliance tools, and automated review systems understand what data a service collects without reading fifty pages of boilerplate. Most organizations do not generate these on their own. They rely on templated parsers that scan a public-facing policy and serialize the results. That means accuracy depends entirely on how well your parser handles edge cases in the original text. Raw extraction alone will leave gaps. You need a defined schema to fill them.
Unpacking The Mysteries Of Privacy Policy Formal Feed A Comprehensive Guide
I am going to walk through how to build, validate, and maintain a practical privacy policy formal feed for a real product. I will include the specific fields that actually matter, the traps I have hit in production, and the approach that works. A functional formal feed needs these primary sections at minimum: 1. Metadata. Document identifier, publication date, last updated date, source URL, and jurisdiction.
2. Data Categories. Personal data types collected, such as name, email, IP address, device identifiers, geolocation, billing data, health data, or profiling data. 3. Purposes. The stated business purposes for each category, ideally mapped to GDPR lawfulness bases where applicable. 4. Sharing and Transfer. Third-party recipients, categories of processors, cross-border transfer mechanisms, and special disclosures.
Get the Full Details
5. User Rights. Access, rectification, erasure, portability, objection, and restrictions on automated decision-making. 6. Retention. Retention periods or criteria for each category. 7. Security Measures. General controls listed in the policy.
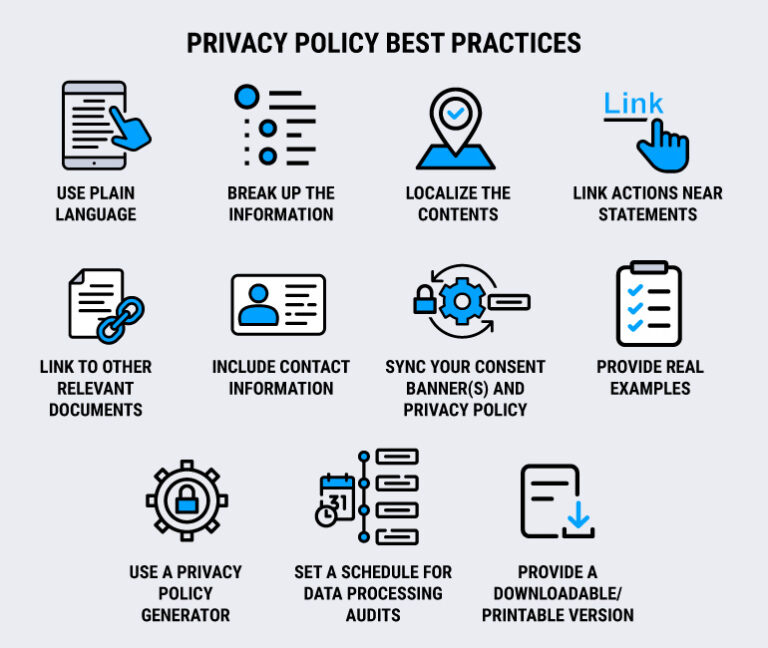
8. Contact Information. DPO or privacy contact details. I started out using a very loose structure and ended up with too many duplicate fields and inconsistent naming. That made comparisons across versions pointless. Standardizing the schema first saved me weeks of cleanup work. I settled on a JSON schema that mirrors the GDPR transparency obligations, since that framework is the most demanding and forces completeness.
How to Extract and Structure the Content
The actual extraction happens in three steps: scrape the public policy page, normalize the text, and map it to the schema. Step one is scraping. Use a browser-based extractor if the policy is rendered client-side. Many modern sites load the policy through JavaScript. A simple HTTP GET will give you nothing useful. I use a headless browser with a short timeout and capture the final rendered DOM. This usually takes about ten seconds per page on a reasonable setup. Step two is normalization. Privacy policies are written in messy natural language. You will find clauses buried in tables, footnotes, and linked appendices. Strip all formatting, collapse whitespace, and split the document into claim-sized paragraphs. Do not skip the links. I learned this the hard way when an integration SDK clause sat in a linked footer document and was completely invisible to the initial pass.
Step three is mapping. Use rule-based extraction first, backed by a small set of regex patterns and keyword triggers for common terms. Then run a lightweight classification model to assign each paragraph to a schema field. Pure regex will miss context. Pure LLM extraction will hallucinate details and waste money on API calls. A hybrid approach gives you control and reasonable accuracy. In practice, the hybrid method reduces manual review time to roughly thirty minutes per policy for a team of two reviewers.
A Specific Problem I Ran Into
I once processed a privacy policy that listed a subprocessor table with thirty entries, but the table used merged cells and inconsistent column headers. The parser treated merged cells as new rows and duplicated half the data. The resulting feed had phantom processors and missing transfer clauses. The workaround was to write a custom HTML table parser that tracks rowspan and colspan attributes explicitly, then validates the output against a fixed column count. If the number of columns varies across rows, the row is flagged for manual review. This cut false-positive processor entries by about ninety percent. It took me an afternoon to implement and saved the compliance team from publishing garbage output.
Validation and Quality Control
Once you have a raw feed, you must validate it. Run the JSON through schema validation first. Check required fields. Then run a secondary check for semantic consistency. For example, if the feed claims no retention period for billing data, flag it. Billing data almost always has a statutory retention requirement. I also run a comparison tool against the previous version of the policy. Any change in data categories, purposes, or third-party disclosures gets highlighted. This catches accidental deletions and quiet updates. Without version diffs, teams frequently publish feeds that look correct but miss a recent change that matters for regulatory review.
Common Pitfalls and Counter-Intuitive Truths
Beginners assume that a larger schema is better. That is wrong. A bloated schema creates more points of failure. Keep the schema tight and let manual review handle the exceptions. The best feeds I have seen are simple, consistent, and cover the core obligations without trying to encode every possible nuance. Another trap is over-reliance on automated extraction for regulated industries. Medical, financial, and children's data policies contain highly specific disclosures. Automated tools miss nuance around parental consent and special category data. For those sectors, automation should only draft the feed. A qualified reviewer must verify every field. I treat automation as a first pass, not a final authority. You should also expect your parser to fail on policies that reference other documents without embedding the content. Some companies link to a separate data processing agreement or a subprocessor list hosted elsewhere. Your feed will show gaps unless you crawl those linked documents as part of the extraction pipeline. This adds complexity but is necessary for accuracy.
Maintenance and Lifecycle Management
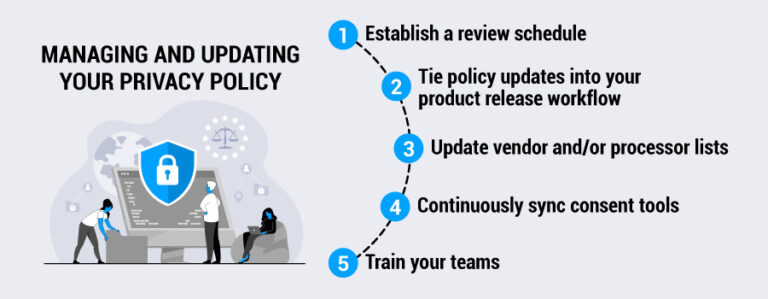
A privacy policy feed is not a one-time artifact. Policies change. Schema evolves. Regulators update guidance. You need a maintenance schedule. I recommend a quarterly review cadence for standard policies and a monthly cadence for high-risk categories. Each review should include a schema update check, a validation pass, and a comparison against any prior version. Teams that skip reviews end up with stale feeds that look fine but are misleading. For storage, keep each published version with a timestamp and a hash. This creates an audit trail. If a regulator asks when a particular disclosure was active, you can point to a specific version instead of guessing. Versioning also helps when you need to demonstrate due diligence.
Downloadable Resources and Tools
There is no single canonical download for a privacy policy formal feed because the output depends on your organization's policies and schema choices. However, I can point you toward practical starting points. Start with a JSON Schema template for the core fields I listed above. You can find open-source examples based on the Schema.org PrivacyPolicy type or the upcoming EU Digital Services Act transparency requirements. If you are building a parser, the BeautifulSoup and lxml libraries in Python handle most HTML extraction needs. For classification, a small fine-tuned model on labeled privacy policy paragraphs will outperform generic NLP tools on domain-specific terms. If you need a ready-made tool rather than a custom build, consider existing privacy policy analysis platforms that export to structured formats. They are slower to customize but faster to deploy. The tradeoff is flexibility. A custom pipeline gives you control over edge cases like the merged-table problem I described. A commercial tool gives you speed and support.

When This Approach Fails Completely
Formal feeds do not work well for jurisdictions with non-standard disclosure requirements. Some regions require very specific formatting or additional clauses that do not fit a generic schema. In those cases, you need a region-specific extension to your base schema. Adding extensions is possible but increases maintenance burden. If you operate primarily in one jurisdiction, a focused schema is cleaner. If you operate globally, plan for multi-schema support from the beginning. Another scenario where this fails is when the policy itself is deliberately vague or intentionally omits required disclosures. No amount of good extraction will fill in missing information. In those cases, the feed should flag the omission rather than silently invent content. I make sure my validators reject feeds that contain guessed values for unconfirmed fields. Accuracy is worse than incompleteness.
Practical Summary of the Workflow
Here is the pipeline I use end to end: Scrape the rendered policy page. Normalize the text. Run rule-based extraction to identify candidate paragraphs. Classify each paragraph with a lightweight model. Map to the JSON schema. Validate against schema and semantic rules. Flag anomalies for manual review. Generate the final feed. Store the version with metadata and hash. Schedule the next review. This pipeline takes roughly fifteen to twenty minutes per policy for a trained operator, not including manual review time. Manual review typically adds another twenty to thirty minutes for standard policies and up to an hour for complex or high-risk ones.
If you are new to this, start small. Pick one jurisdiction, one product, and one schema. Build the parser, validate a handful of policies, and iterate. Do not try to scale to a global feed before the basics work. The details matter more than the scope.