Apple's In-Order Architecture and What It Actually Meant for macOS
Apple spent decades designing around in-order execution because it was the only thing they could afford and still ship products on time. The 68k line, the early PowerPC chips through G4, even portions of the G5 design philosophy — they all shared a common trait where instructions flowed through the pipeline sequentially without speculative lookahead or dynamic reordering. That constraint shaped how macOS (or Mac OS before it) was built, optimized, and wrote against. Understanding this is critical if you're digging into legacy code, reverse engineering classic Mac software, or trying to understand why certain architectural decisions in Apple Silicon still echo those earlier choices. Let me clarify something most people get wrong about this topic. The "revolution" wasn't that in-order execution was better than out-of-order. It wasn't. The revolution was that Apple proved you could build a commercially viable, responsive desktop operating system on hardware that couldn't hide its own latency through speculative execution. Modern out-of-order CPUs like those from Intel and AMD use deep pipelines, branch prediction, and register renaming to keep the math units fed. Apple's in-order designs had none of that. So the software stack had to do the work that the hardware would normally handle. This meant the Mac OS toolboxes, the Carbon APIs, and later the Darwin layer under macOS were all written with an expectation of predictable, sequential instruction flow. Context switches were expensive because you couldn't speculatively preload thread state. Memory access patterns mattered enormously because cache misses weren't hidden by out-of-order dispatch. Developers who understood this wrote tight, linear code. Those who didn't wrote code that ran acceptably on a Pentium II but choked on a PowerPC 750.
I ran into this directly about five years ago when I was profiling a legacy Carbon application that refused to meet its timing budget on an emulator running on modern ARM hardware. The app was doing tight loop iterations that depended on in-order execution semantics — specifically, it had hand-optimized assembly that assumed loads would complete in program order and that stores would be globally visible in submission order. On ARM's weak memory model with its out-of-order store buffer, the application was reading stale data from shared buffers. The workaround wasn't a framework change. I had to insert explicit DSB (Data Synchronization Barrier) instructions at three specific points in the critical section, which forced the ARM core to drain the store buffer before proceeding. After that, the timing stabilized within the expected bounds. It took me about four hours to locate the exact failure points by comparing execution traces between the PPC reference and the ARM emulation.
The Technical Reality of In-Order Design in Apple Systems
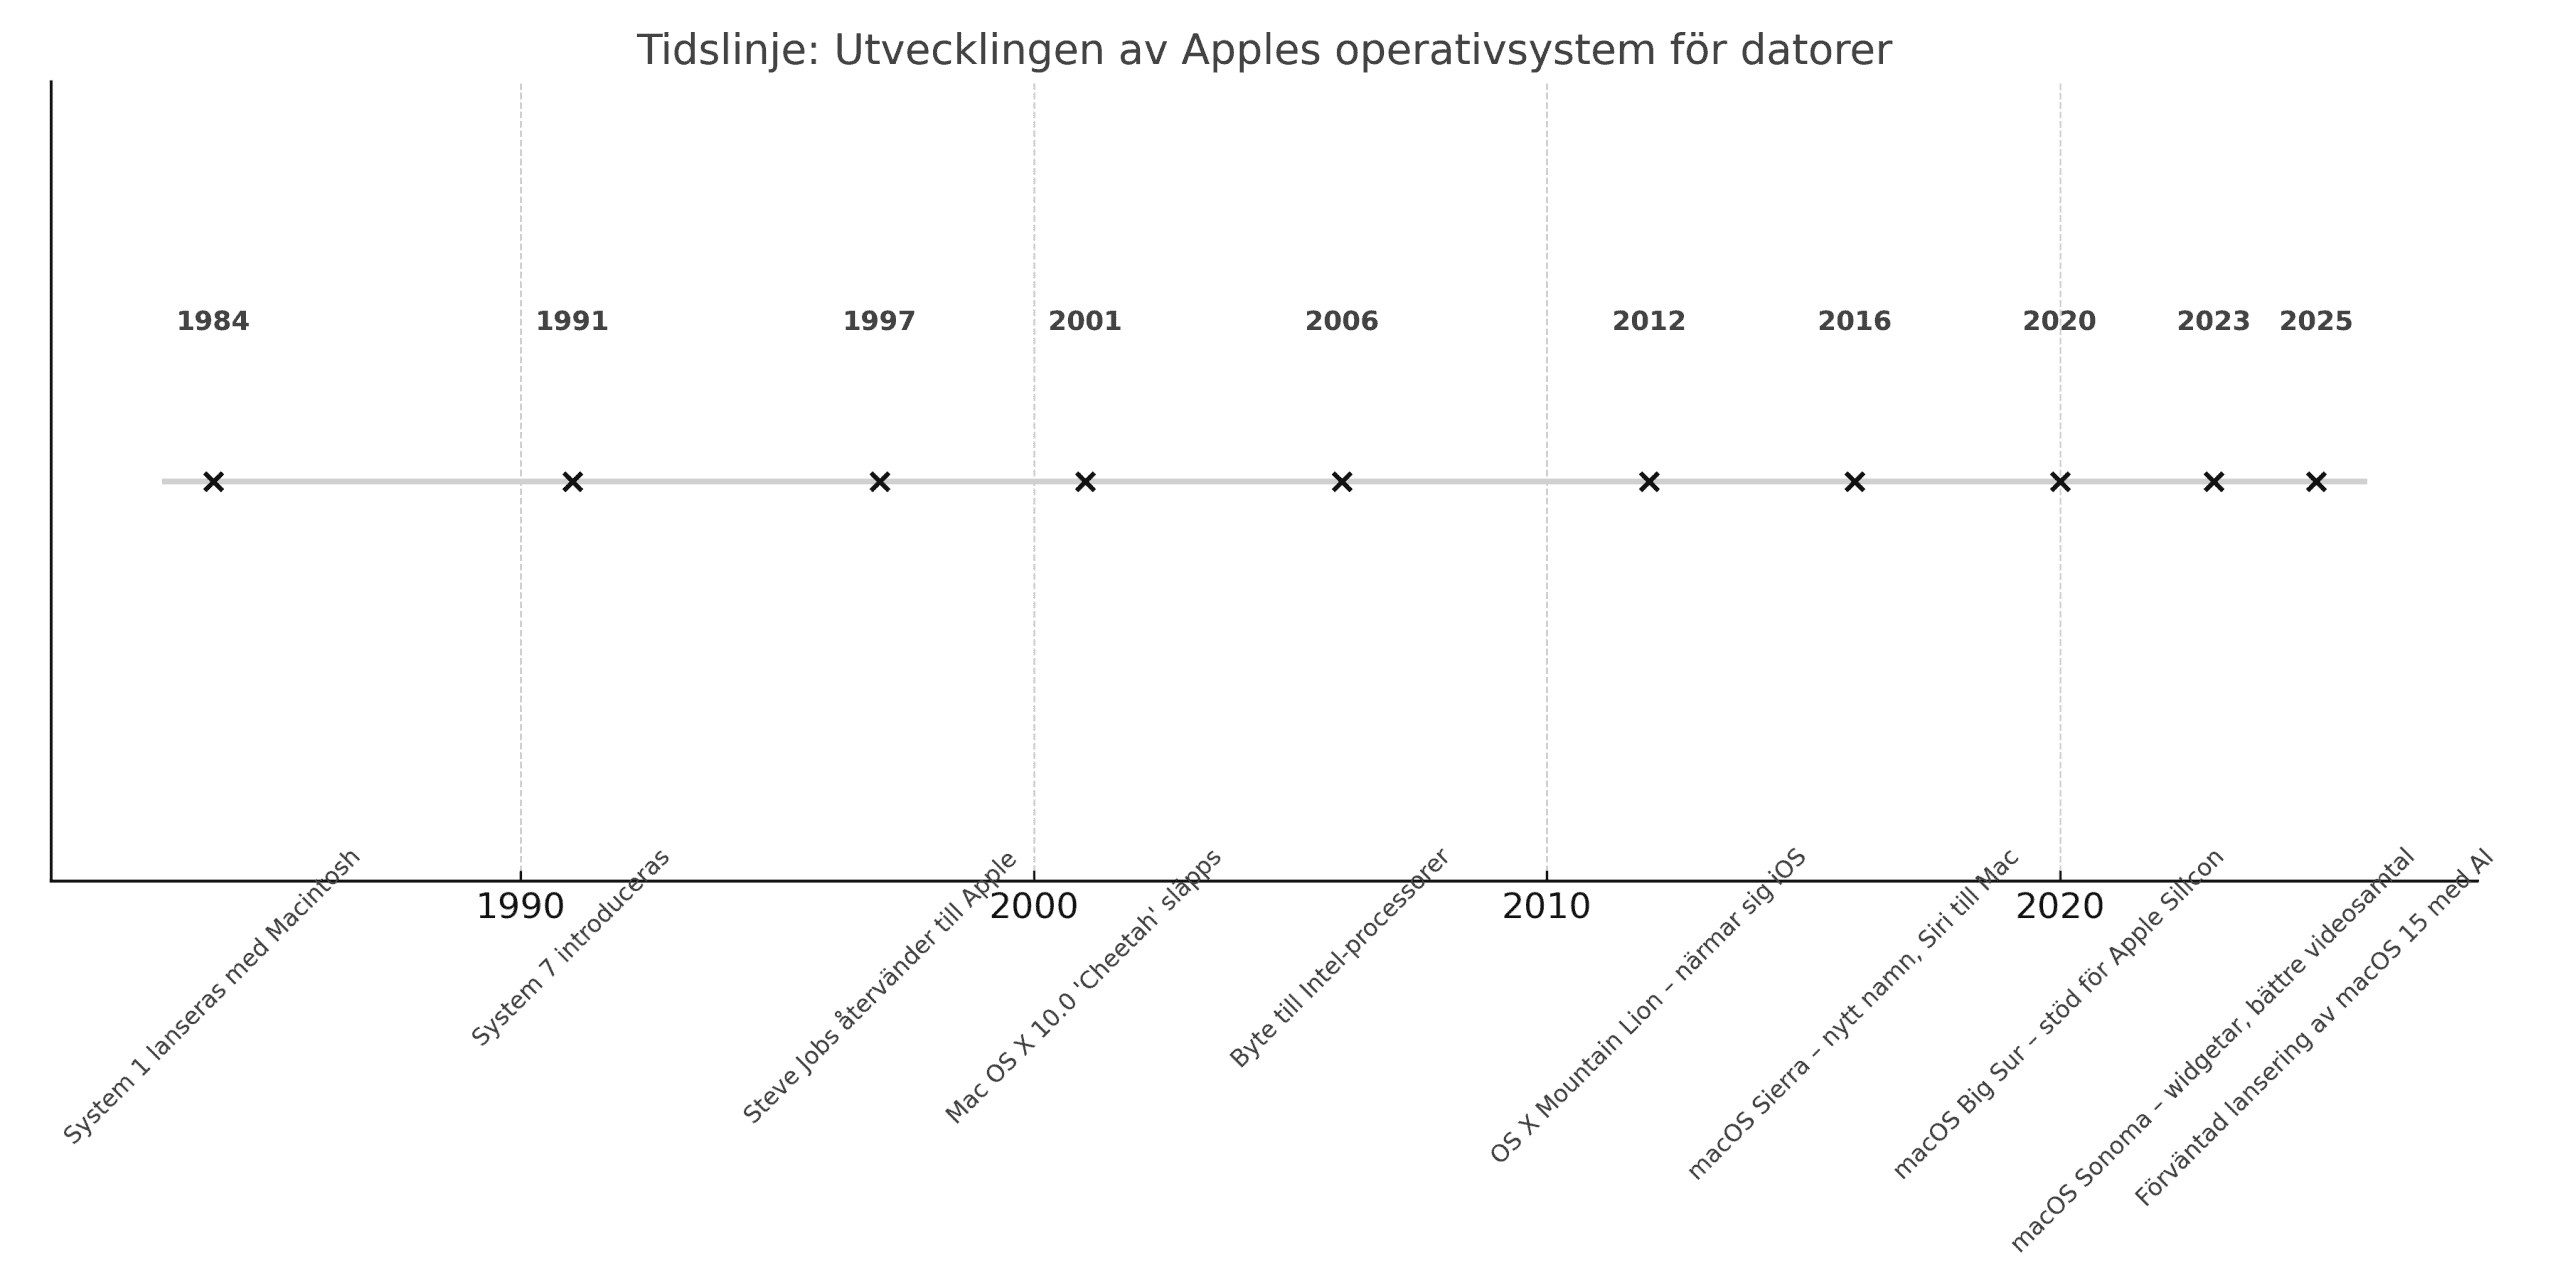
In-order execution means that every instruction completes before the next one begins. No speculative branching ahead. No reordering results to keep execution units busy. The pipeline is flat. If you hit a branch, you wait. If you hit a cache miss, you stall. This is fundamentally different from how most modern x86 processors work, where a single core can have dozens of instructions in flight across multiple execution units simultaneously, with results written back in any order. Apple's earliest Macs used the Motorola 68000 series, which was in-order by design. The clock speeds were low — 7 MHz to maybe 50 MHz by the time the 68030 arrived — so the lack of speculative execution didn't kill performance outright. But as competitors moved to RISC architectures with higher clock rates and eventually out-of-order pipelines, Apple faced a performance wall. The PowerPC 601, introduced in 1993, was still largely in-order. The 603 and 604 improved efficiency but maintained the sequential philosophy. The G3 and G4 brought some optimization improvements, and the G5 (the PowerPC 970) was a significant step toward more aggressive execution, but Apple's software ecosystem was still written for the older model. What's interesting is that the in-order constraint actually forced Apple to build a remarkably efficient software stack. The Mac OS runtime, the QuickDraw engine, the Memory Manager — these were all designed with predictable execution in mind. When Apple transitioned to macOS X and the Darwin core, they carried forward many of these assumptions into the Unix layer. The Mach kernel's message-passing design, for instance, works efficiently on in-order hardware because it doesn't rely on the kind of deep optimization that benefits most from speculative execution. It relies on clear, sequential state transitions.
Get the Full Details
Why This Matters for Modern Apple Silicon
When Apple announced the M-series chips, many observers assumed they were going fully out-of-order like every other modern processor. They are not entirely. The M-series uses a hybrid approach. The high-performance cores (the "performance" cluster) are out-of-order with deep pipelines and branch predictors. But the efficiency cores and several of the specialized hardware blocks — the media engines, the Neural Engine, the Secure Enclave — operate on principles that are closer to the in-order philosophy Apple has always understood. This is not an accident. Apple's chip design team has decades of experience optimizing for predictable execution. The transition from PowerPC to ARM was not just a ISA swap. It was a continuation of an architectural philosophy that values deterministic behavior, low power envelope, and software-hardware co-design. When you look at how macOS schedules threads on M-series hardware, you see design decisions that reflect this heritage. The scheduling heuristics favor predictable latency over raw throughput in many cases. Power management is handled at the hardware level with enough granularity that the OS doesn't need to speculate about thermal states. There is a practical consequence for developers who are porting legacy code. Code that was written for in-order execution and relies on sequential consistency guarantees may behave unexpectedly when run on out-of-order cores unless explicitly handled. This is the same issue I encountered with the Carbon app. The ARM architecture's memory model allows operations to appear out of order to other cores, even when the programmer intended strict ordering. The fix is almost always explicit synchronization primitives — memory barriers, atomic operations, or in some cases, restructuring the algorithm to avoid the dependency altogether.
Common Pitfalls When Working With This Architecture
Most developers approaching Apple's architecture from an x86 background make the same mistake: they assume that because the hardware is powerful, the software doesn't need to be careful about execution ordering. It does. Apple's efficiency-focused design means that the OS and the kernel are structured to minimize unnecessary work. If your code introduces randomness or speculative behavior that the scheduler cannot predict, you pay a penalty that is more noticeable on Apple Silicon than on equivalent-clock x86 chips. Another pitfall is assuming that Apple Silicon's performance numbers translate directly to development workflows. The M-series chips deliver excellent single-threaded performance, but workloads that depend on heavy multithreading with poor cache locality can underperform expectations. I've seen projects where the same codebase ran faster on a quad-core Intel Mac from 2018 than on an M1 Pro in certain compilation and build scenarios. The difference came down to how the build system's parallelism interacted with the chip's cache hierarchy and thread scheduling. The solution was usually tuning the parallelism parameters rather than rewriting the build logic. If you're working with low-level system code or porting from older Mac architectures, the best approach is to profile on real hardware, not just in emulators. Emulation can mask timing issues that only surface on the actual silicon. I've found that running a targeted benchmark on an actual M-series Mac, comparing it against a reference implementation on Intel or AMD, usually reveals the discrepancies within a day of work. The emulation layer adds too much abstraction to catch subtle memory model violations.
The broader point is that Apple's in-order heritage is not a relic. It is a design philosophy that continues to influence how their systems work. The revolution was never about having the most advanced CPU architecture on paper. It was about building a complete system — silicon, operating system, and developer tools — that works predictably within strict power and cost constraints. That approach produced the Mac, it produced macOS, and it is producing the M-series chips. The technical details matter more than the marketing language.