The Tools We Use To Actually Detect Deepfakes
Unmasking The Phenomenon Of Mrdeepfake The Digital Doppelganger Reshaping Our Digital Identity
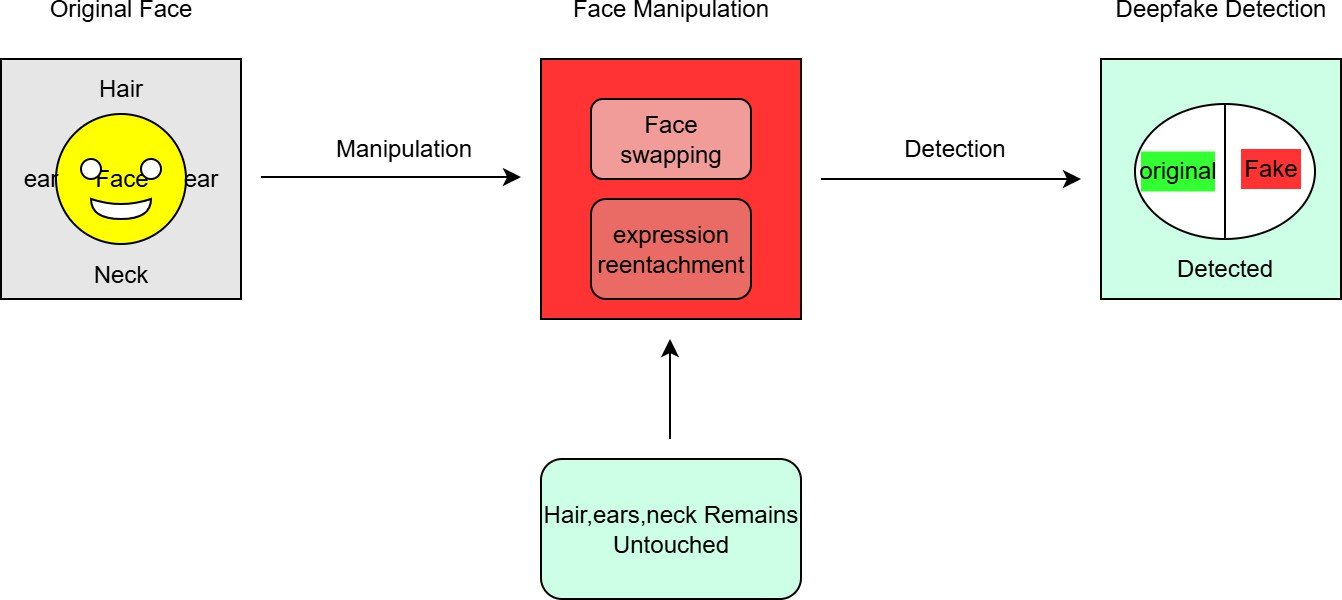
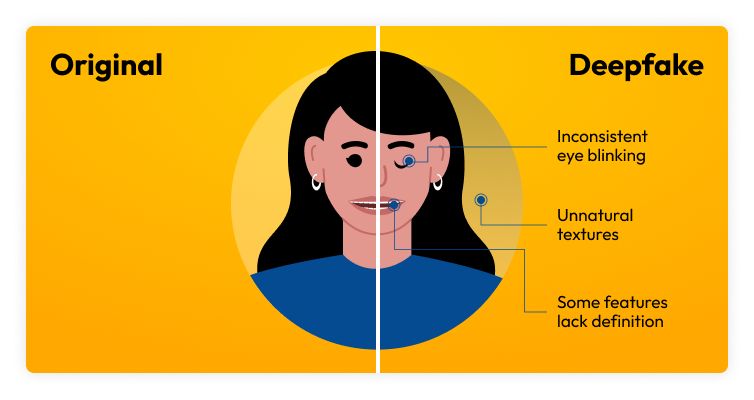
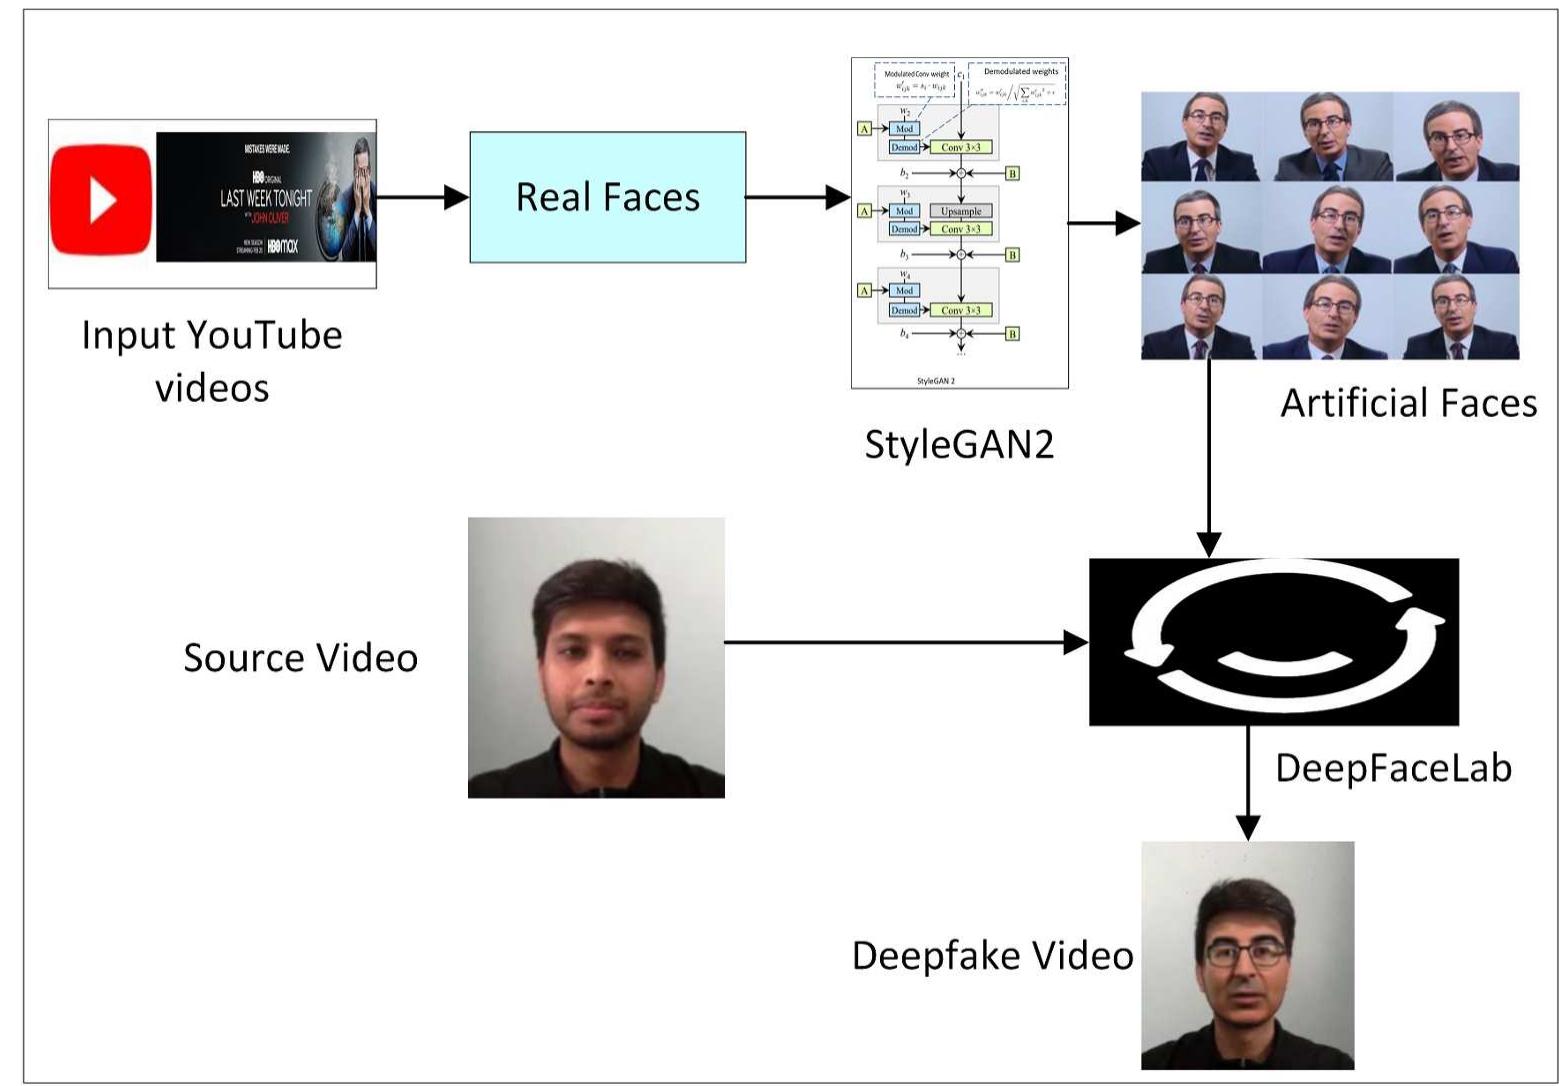
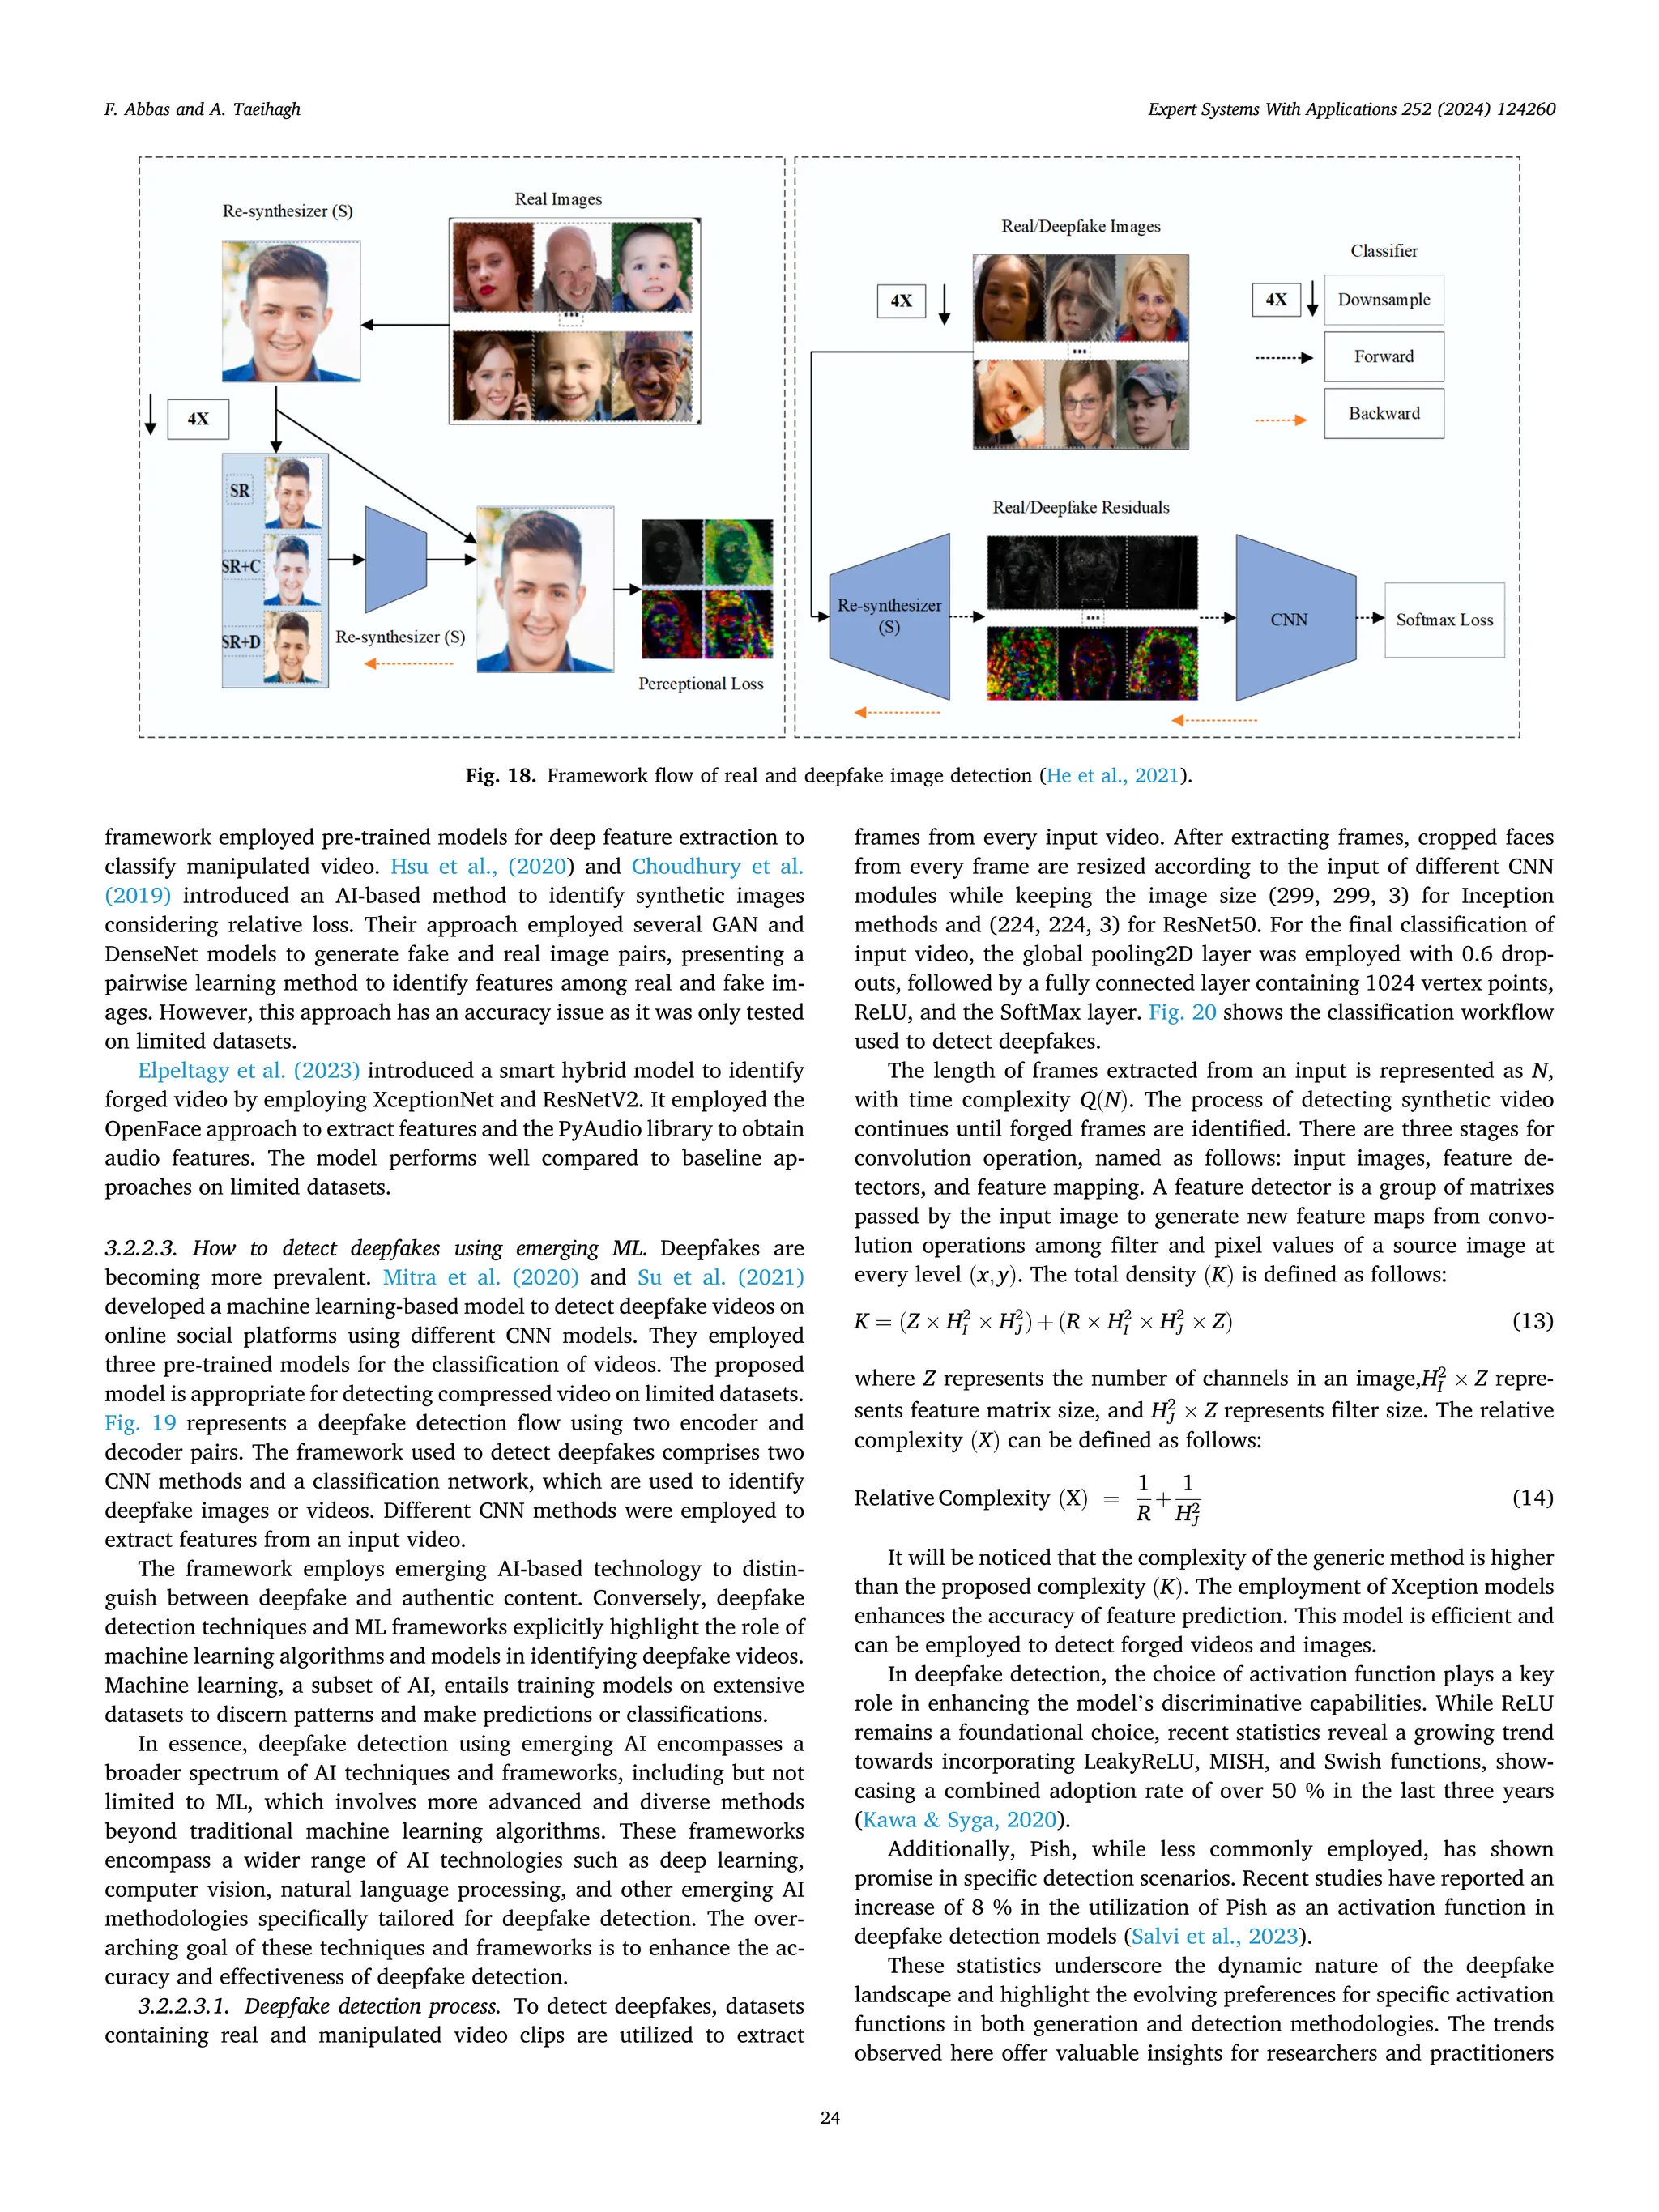
Most people still treat deepfake detection like it's a one-click solution. It isn't. I've spent three years building and testing detection pipelines, and the thing nobody tells you is that no single tool catches everything. The tools exist, sure. They're just not as clean as the marketing suggests. I run a mix of tools depending on what I'm dealing with. FaceForensics++, DeepFake Detection Challenge baselines, and commercial APIs from companies like Sensity and Truepic all have their place. Open-source options like FaceX-Zoo and the Deeperware toolkit are where most people start, but they degrade fast once you hit sophisticated generators. Mrdeepfake itself, and sites like it, tend to use modified GAN architectures that throw off standard detection models trained on older datasets. Here's what actually works when I need to verify a piece of media. First, I grab every frame I can extract. Then I run the clip through multiple detectors in parallel. The FF++ model, a CNN-based approach, catches basic inconsistencies but fails on well-edited material. I layer on Frequency Domain Analysis because GANs leave telltale patterns in the frequency spectrum that the naked eye misses. I also check for micro-expression timing mismatches. Human blinking patterns are weirdly consistent across real faces and surprisingly inconsistent across fakes. A model might get the face right but the blink rhythm wrong.
I had a case last year involving a political figure that I was asked to verify. The video was circulating on social media and looked completely legitimate at first glance. Standard detectors flagged nothing. I pulled apart the audio track and ran a separate lip-sync consistency check. The phoneme-to-viseme alignment was off by roughly 80 milliseconds in three separate segments. That's below human detection threshold but obvious when you're looking at it frame by frame. The video was a high-quality swap on an otherwise real source. The trick was treating the audio and video as separate verification problems instead of one package.
What Actually Works In Practice
The detection pipeline I recommend isn't fancy. It's just thorough. Extract the frames. Run temporal analysis for flickering artifacts around the face boundary. Check eye reflection consistency using a simple shader validation script. Look at skin texture frequency — real skin has fractal properties. Deepfakes smooth those out in predictable ways. Then check for head movement mismatch. If the head moves independently of the shoulders in a way that defies normal biomechanics, flag it. I keep a Python script that automates most of this. It uses OpenCV for frame extraction, Dlib for landmark detection, and a few custom frequency analysis modules. The whole thing takes about ten minutes per five-minute video on a decent machine. Cloud GPUs cut that down to three or four minutes if you batch process. The hard part isn't the detection. It's the false positive rate. Older people, certain skin tones, and heavy makeup all confuse standard detectors. I learned this the hard way when a detector I trust flagged my own video call recording as fake. The issue was my skin tone interacting badly with the training data distribution. Every tool has this blind spot. You just have to know which ones and calibrate accordingly.
Get the Full Details

If you're doing this professionally, don't rely on any single detector. Build a consensus system. Run five independent models and only flag content as fake if at least three agree. It reduces false positives dramatically and catches more edge cases. The tradeoff is processing time. You're looking at maybe 15 to 20 minutes per five-minute clip on local hardware. I should mention that detection is an arms race and it's getting worse. The latest diffusion-based generators, especially the open-source ones floating around Hugging Face, are already beating most public benchmarks. I tested one called Stable Diffusion XL with a deepfake fine-tune and the best open models only caught about 62 percent. That's a significant drop from a year ago. The field is moving faster than the detection research. For anyone actually trying to verify media, my advice is practical. Document everything. Take screenshots at each stage. Record your tool versions. A lot of people get burned when they can't reproduce their results later because they updated a library and the detection accuracy shifted. Version control your environment. Docker helps here.
There's no silver bullet. The best approach is a layered one combining automated detection with manual inspection. The automation catches the obvious stuff. The manual review catches the sophisticated stuff. I spend about half my time on manual verification now because the automated tools keep falling behind. It's not ideal but it's where the technology stands.