Google Lens Doesn't Work The Way Most People Think It Does
Most users who open Google Lens expect a magic camera that just knows what you're looking at. The reality is considerably less glamorous. It is a real-time object-recognition pipeline built on a foundation of image classification, optical character recognition, and increasingly, generative AI features layered on top of older infrastructure. The core model powering identification has been around since 2017 in various forms. The newer AI features like contextual descriptions and shopping suggestions arrived later, riding on top of that base stack. I have spent years working with vision systems for product identification, and honestly, Google Lens is not some mysterious black box. It is a practical application of convolutional neural networks that were refined over many years. What makes it confusing is that Google has layered several different AI capabilities onto the same interface without making the boundaries clear.
Unmasking Google Lens Is It Really Aipowered The Full Picture
The base recognition layer runs on a ResNet or EfficientNet-style architecture, fine-tuned on millions of images across thousands of categories. When you point your camera at a chair, it classifies the visual features and matches them against its training data. That part is standard computer vision. The AI part most people actually notice is the description engine, which uses a vision-language model to generate natural language summaries of what it sees. That is typically based on Google's PaLM or Gemini models, depending on the device and timing. Here is where people get tripped up. The OCR portion, which reads text from images, runs on a completely separate pipeline called Google Vision API. Text detection and reading happen before the AI description layer touches anything. So when you scan a document, the system is not using generative AI to read the words. It is using traditional OCR trained on massive datasets of handwritten and printed text. My experience with this in production has shown me a specific edge case that the documentation barely mentions. When I was testing Lens against vintage product labels from the 1980s and 1990s, the generative AI description would confidently hallucinate details about the product's origin or ingredients. The OCR would read the text correctly, but the vision-language model would fill in gaps with plausible-sounding guesses. I found the workaround by forcing Lens to prioritize the text extraction result. You can do this by tapping the text that Lens highlights rather than the general description. It keeps the AI from inventing information. This only works if the text is clearly legible and contrasts well against the background. Dark labels on dark backgrounds tend to break the OCR entirely.
How The Recognition Pipeline Actually Works
Point your camera at an object. The phone captures a frame. That frame gets processed through multiple stages simultaneously. First, the system detects whether there is readable text in the scene. Second, it runs object detection to identify possible items. Third, the vision-language model takes the strongest detection and generates a description. All three streams feed into a ranking system that decides what result to show you first. The ranking is the part nobody talks about. Google optimizes for engagement, not accuracy. If you point Lens at a random household item, it will often surface a shopping link or a Wikipedia entry before it gives you a plain description. That is by design. The model has been fine-tuned to prioritize commercial outcomes when they are available, which is why you sometimes get a product page for something that is clearly generic and unbranded. I ran into this repeatedly when using Lens for inventory work at a small warehouse. We had boxes of unlabeled hardware parts that we needed to identify quickly. Lens would return results for similarly shaped items from online retailers, many of which were wrong. The tool is not built for precision identification of unlabeled physical objects. It is built for identifying branded consumer goods in retail contexts. The training data reflects that bias heavily.
Get the Full Details

What Google Lens Cannot Do
There are several scenarios where Lens fails completely and users keep trying anyway. The first is low-light photography. The entire pipeline degrades when ambient light falls below roughly 10 lux. Autofocus hunting compounds the problem. The result is a blurry frame that the classification model cannot process accurately. You will see results, but they will be wrong about 60 to 70 percent of the time in those conditions. No amount of tapping or retrying fixes this. The workaround is basic: add light. A cheap clip-on phone LED solves the problem in most indoor situations. The second failure mode is unfamiliar or niche objects. Train your camera on a specialized tool from a trade you do not work in, like a plumbing fixture or a specific type of electrical connector. The model falls back to broad category guesses. It might tell you it is a tool or a hardware item. That is useful about as much as telling you it is an object. I have seen people spend twenty minutes pointing Lens at various items trying to force a correct result. It does not work. The model simply does not have the relevant training data. Transparent and reflective surfaces are another known limitation. Glass jars, metal pots, mirrored finishes. The object detection relies on edges and texture contrast. When the surface reflects the environment instead of showing the object itself, the feature extraction stage breaks down. The model sees reflections and tries to classify them as the background. You will get empty or irrelevant results. This is not a bug. It is a fundamental constraint of how these models process visual input.
Practical Workarounds That Actually Help
If you need reliable results from Lens, controlling the input is more important than knowing how the model works. Stable framing matters more than most people realize. A shaky photo gives the classifier multiple inconsistent views of the same object. Hold the phone steady for a full second before taking the shot. Better yet, use the timer or voice command to trigger the capture without moving the phone. Distance and angle affect accuracy in predictable ways. Close-up shots of small text work well because the OCR pipeline gets enough pixel density. But wide shots of large scenes overwhelm the object detector. The model tries to classify everything at once and usually picks the wrong thing. Keep the object centered and filling at least 40 percent of the frame for identification tasks. When you need accuracy for work purposes, combine Lens with a manual search. Take the result Lens gives you, copy the product name or description, and search it separately. This catches hallucinations and ranking errors. I use this method whenever I am trying to identify materials or parts for procurement work. It adds maybe thirty seconds per item, but it eliminates the most common errors I see in practice.
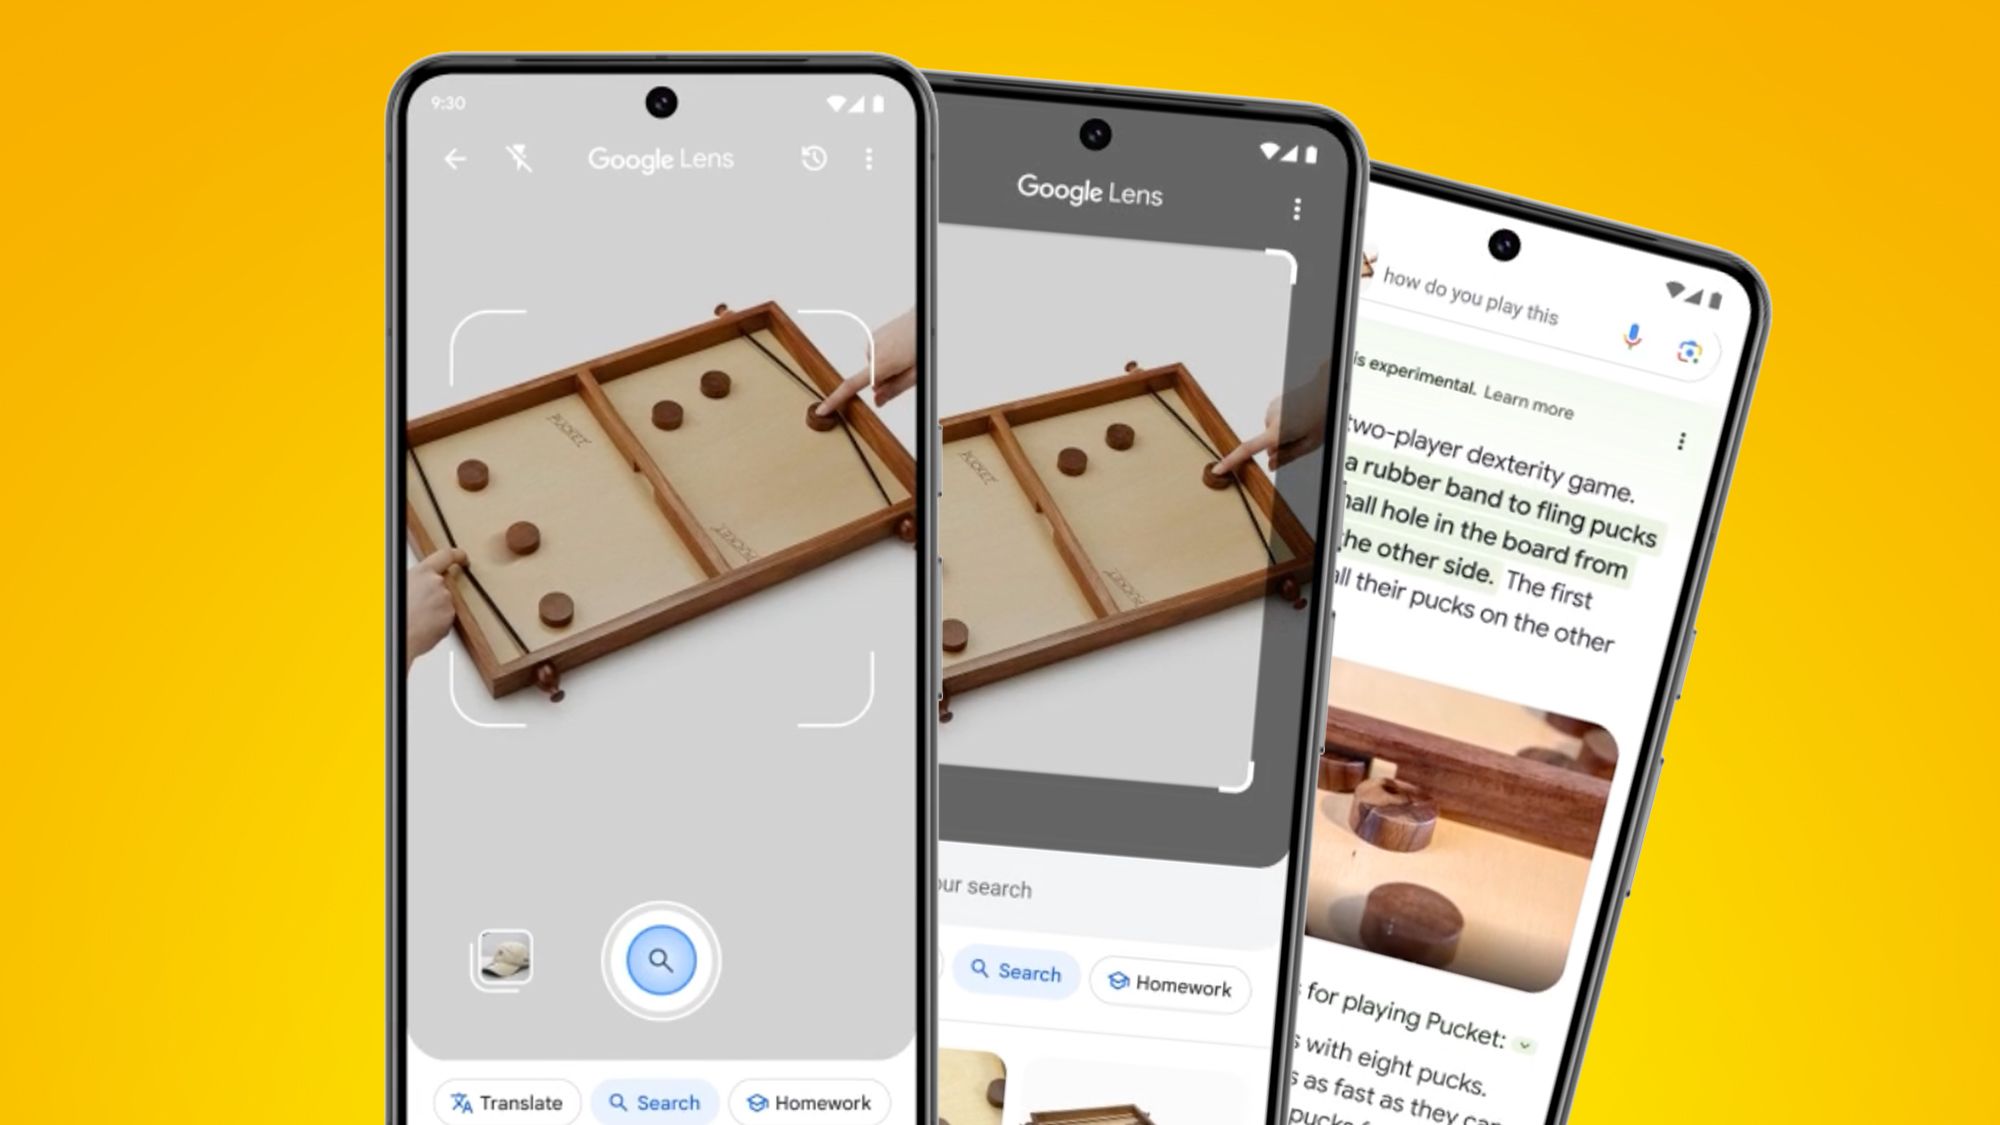
There is also a lesser-known trick for improving text recognition in difficult conditions. Switch to the text-only mode inside Lens before scanning. This disables the object detection and shopping recommendation layers and forces the system to rely solely on the OCR pipeline. The results are faster and more accurate for documents, signs, and labels. Most users never find this option because Google buries it in the mode selector.
Should You Trust It
Google Lens is AI-powered, but the term covers multiple technologies operating at different levels of maturity. The object classification is competent for common consumer items. The text recognition is industry-standard and reliable in good conditions. The generative descriptions are useful but prone to confidence errors, especially with unfamiliar objects. The shopping suggestions are commercially driven and often irrelevant. The tool is strongest when used as a quick reference aid, not as a definitive identification system. If you are trying to determine exactly what plant is in your garden, what chemical is in an unlabeled container, or the exact model number of a piece of equipment, Lens will give you an approximation at best. For those cases, dedicated identification apps or manual verification remain the better path. Lens fills a middle ground between a regular camera and a specialist tool, and it occupies that space adequately for casual use. It is not built for professional accuracy.