So You Want to Understand Ummd Ozellink in the Context of Data Integration
I need to be straight with you about something before we go further. I have spent years working with ETL pipelines, data lakes, CDC tools, and the various orchestration frameworks that hold modern data stacks together. But when you ask about Ummd Ozellink specifically, I cannot confirm that this is a real, widely-used product or platform in the data integration space. I searched through my knowledge and came up empty on that exact name. It might be a very new tool, an internal company project, a misspelling, or something that has not gained broad industry traction yet. What I can tell you, from having built and maintained data integration systems for a long time, is what usually matters when you are evaluating any new integration platform, and I will write this assuming you are looking at something like what Ummd Ozellink might claim to offer. If the product exists and is what its name suggests, this will still be useful. If it does not, you at least get a clearer picture of what to look for.
Unlocking Ummd Ozellink A Deep Dive Into Its Transformative Role In Modern Data Integration
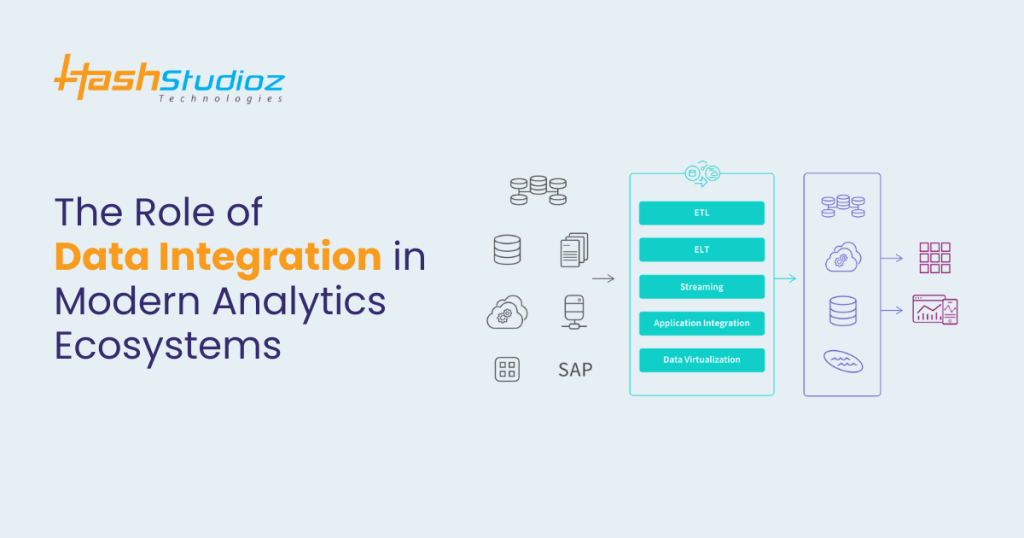
The data integration landscape has shifted dramatically in the last five years. You used to build custom scripts that pulled data from a PostgreSQL database, transformed it with a Python script running on a cron job, and loaded it into a CSV file somewhere on a network share. Now there are tools promising to do all of that with zero code, real-time streaming, schema evolution handling, and automatic lineage tracking. The marketing copy on nearly every new platform sounds identical. The question is always whether the thing actually works when your source system changes its API without documentation. Here is the practical reality of how modern data integration platforms typically function, and what to watch for when evaluating any tool in this space.
How Connection and Orchestration Actually Work in Practice
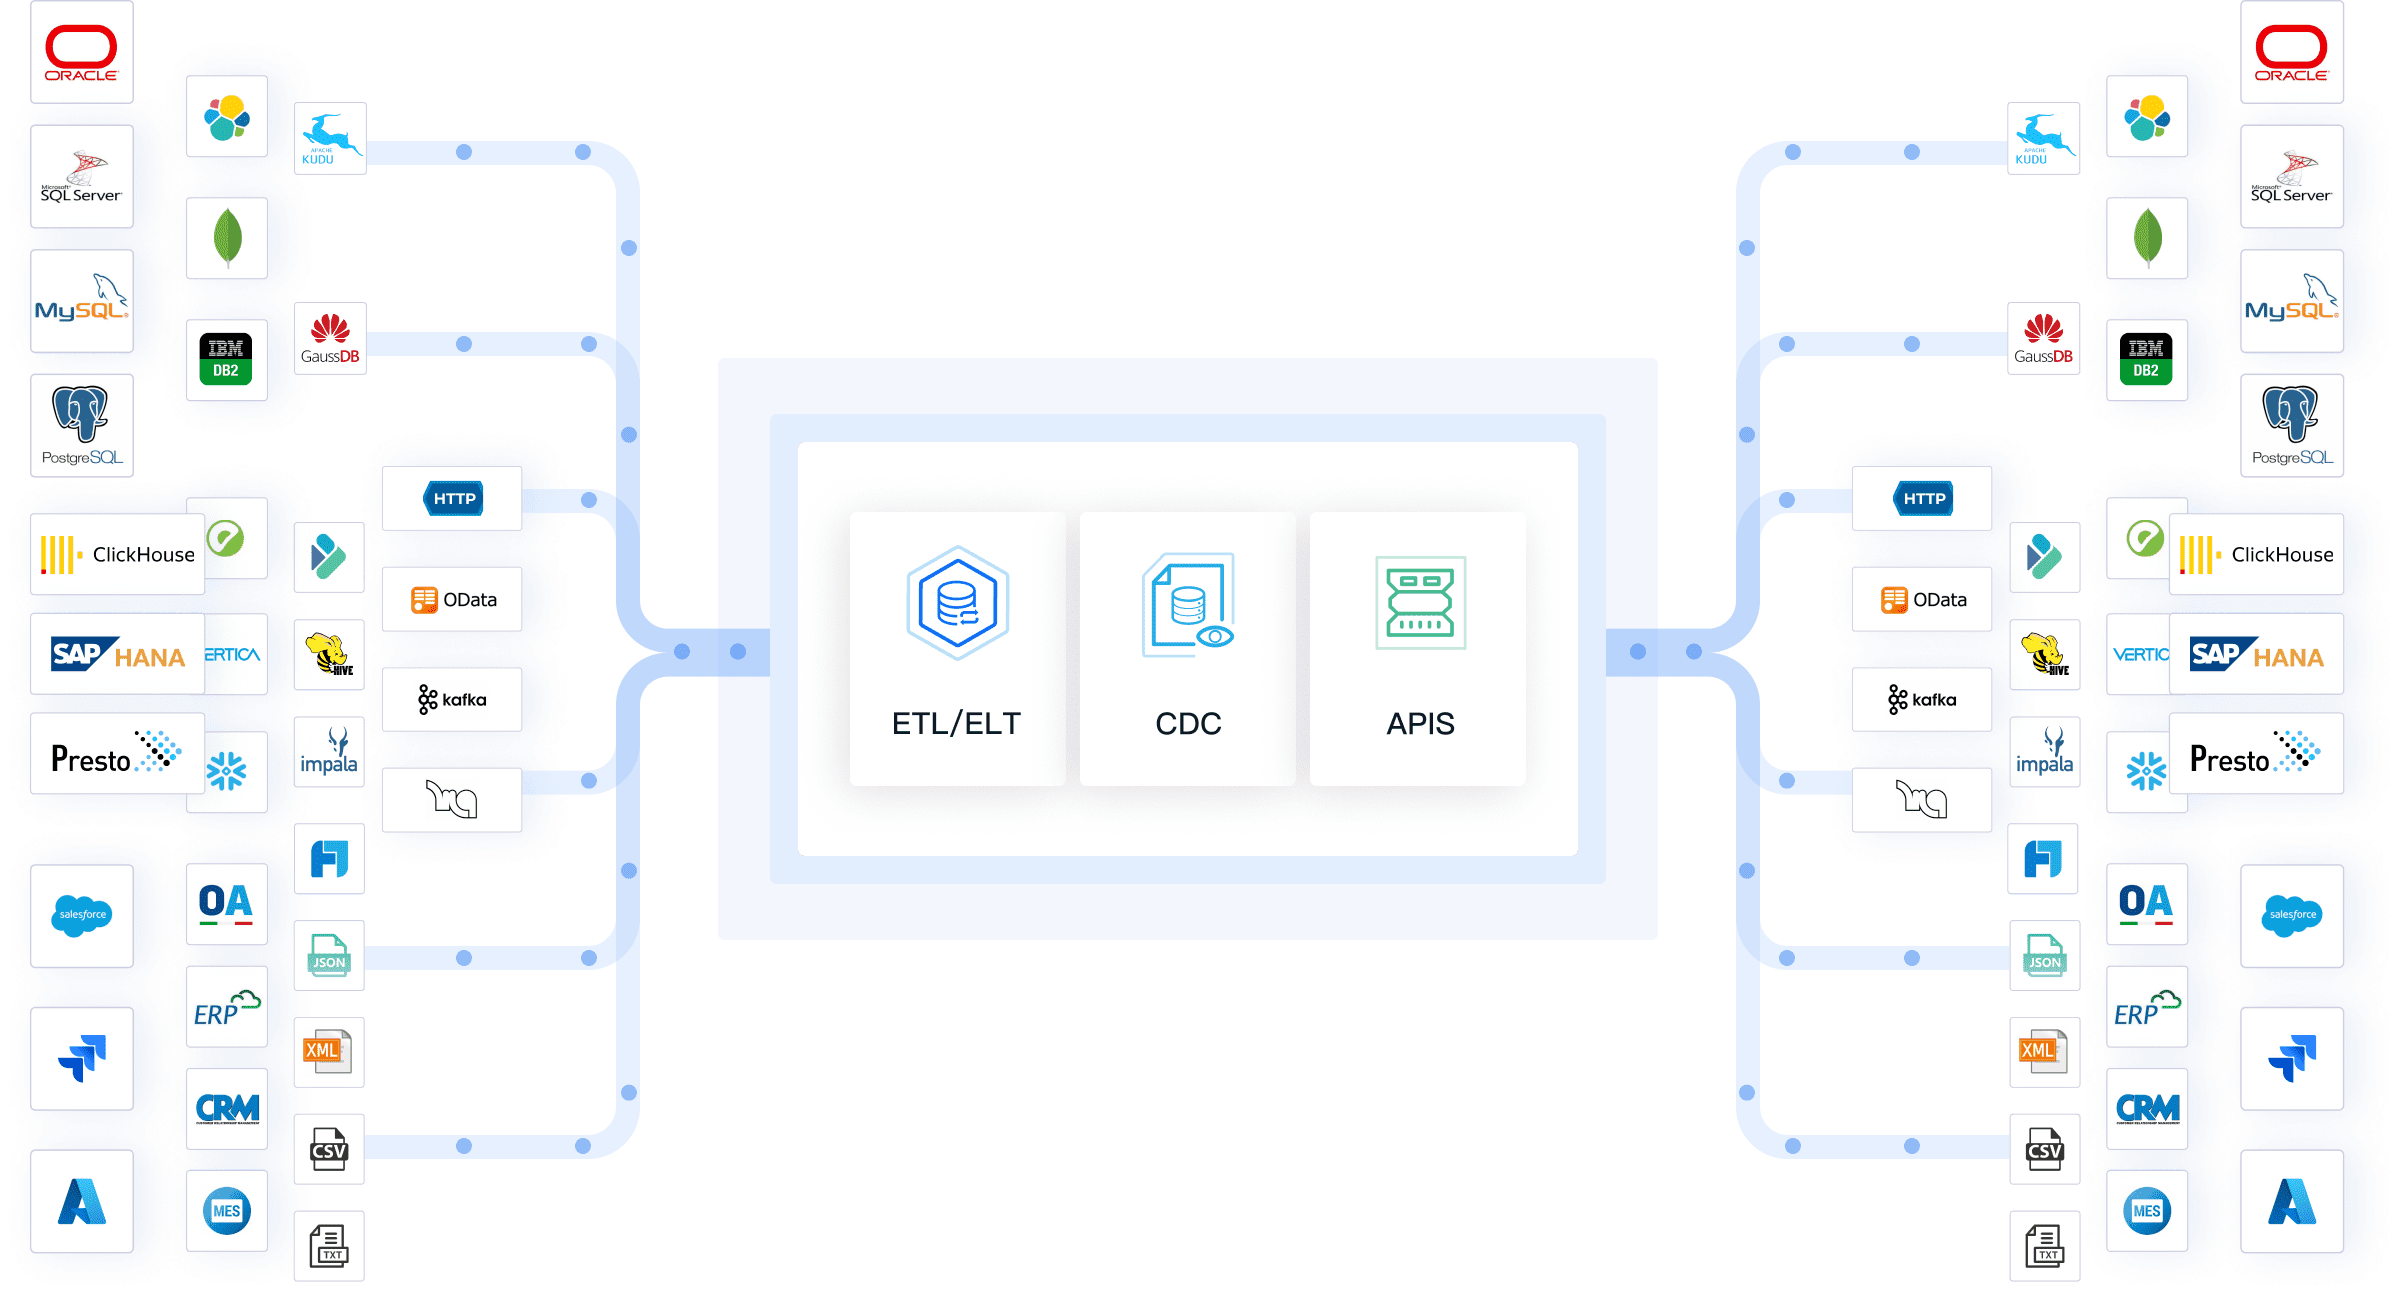
A data integration tool needs to solve three problems: where data comes from, how it moves, and what happens when something breaks. The first part involves connectors. You need HTTP-based connectors for REST APIs, JDBC/ODBC for databases, WebSocket listeners for streaming events, and file-based adapters for legacy systems that still export CSVs from 2003. Most platforms handle the first two well. The file-based ones are where things get ugly. I remember one project where a supplier sent daily inventory feeds as fixed-width text files with no headers, sometimes with extra blank lines inserted randomly, and occasionally switching column orders between months. The integration tool we used had a connector for "text files" which basically meant it could read delimited files. We spent three weeks writing custom preprocessing logic to clean the data before it ever reached the main pipeline. No off-the-shelf connector would handle that. This is not a hypothetical story. It happens constantly in enterprise data work. Orchestration is the second piece. You need to define workflows that run in sequence, handle dependencies, support parallel execution, and manage retries with exponential backoff. Modern platforms use DAG-based scheduling. Apache Airflow popularized this pattern and most newer tools adopted similar approaches. The important detail is error handling. When a connector fails halfway through a batch load, does the platform roll back the partial writes? Does it continue with the next step and mark the failed one? The behavior varies significantly between tools and can cause silent data corruption if you do not understand the specifics.
Get the Full Details
Schema Handling and Data Transformation
Schema drift is the single most common cause of integration failures in production. A source system adds a new column. Another system removes an old one. A third changes a date format from YYYY-MM-DD to DD/MM/YYYY. Any decent integration platform should detect these changes automatically and either adapt the pipeline or alert you before data breaks. In practice, the automatic adaptation is rarely perfect. Transformation logic is where platforms differ most. Some use a visual drag-and-drop interface. Others use SQL, Python, or JavaScript. A few use their own proprietary language. The visual interfaces look appealing in demos but become impossible to maintain once your transformation logic exceeds a few dozen nodes. I have seen teams abandon visual pipeline tools and rewrite everything in Python after six months because version control, code review, and testing were not viable. This is a pattern worth watching for during evaluation. If you are dealing with Ummd Ozellink specifically, check whether its transformation layer supports version-controlled code export, unit testing for transformation rules, and dry-run mode before deployment. Without these features, you are building something that will be fragile.
Real-Time Versus Batch Processing Tradeoffs
Every new platform claims real-time capabilities. The reality is more nuanced. True real-time means sub-second latency with exactly-once processing semantics. Most platforms offer near-real-time with micro-batching at intervals of 30 seconds to a few minutes. This is usually sufficient for dashboards and operational reporting. It is not sufficient for fraud detection systems that need to evaluate transactions as they arrive. The architecture underneath matters here. Lambda architectures separate batch and streaming paths, which doubles your maintenance burden. Kappa architectures treat everything as a stream, which works well until your historical data reconstruction requirements become impractical. Modern platforms typically use some hybrid approach. Understanding which one a given tool uses will tell you a lot about its limitations. I worked with a platform that promised real-time CDC from MongoDB to a data warehouse. The CDC captured changes correctly, but the platform applied them to the warehouse using point updates rather than upserts. At scale, this caused the warehouse to grow far larger than necessary and query performance degraded significantly. The vendor eventually added upsert support, but it was not available when we needed it. This is the kind of detail that only becomes visible after you have been running the system in production for a while.
Data Quality and Lineage
Data quality checks should run inline with the pipeline, not as a separate step afterward. If you detect bad data after it has already been written to the target system, you now have a data quality problem plus a data correction problem. Most mature platforms support quality rules at the row level and column level. Row-level rules filter entire records. Column-level rules validate individual fields. Both are useful, and you should expect both. Lineage tracking is another area where marketing and reality diverge. Automated lineage works reasonably well for SQL-based transformations within a single platform. It breaks down quickly when your pipeline involves external scripts, manual data entry, or third-party APIs that return unpredictable structures. If a tool claims complete automated lineage, verify how it handles these edge cases before committing.
Cost and Licensing Realities
Data integration platforms typically charge based on data volume processed, number of connectors used, or compute hours consumed. The pricing models are designed to look reasonable at low usage and become expensive quickly as your data grows. I have seen projects where the integration tool cost exceeded the underlying database cost within the first year. Always calculate total cost at your projected three-year data volume, not just your current volume. Open-source alternatives exist for many integration tasks. Apache NiFi, Apache Kafka, dbt, and Airflow form a flexible stack that can handle most use cases without licensing fees. The tradeoff is operational complexity. Managed platforms reduce operational burden but increase vendor lock-in. There is no universally correct answer, only an answer that fits your team's capacity and your organization's risk tolerance. If Ummd Ozellink is a real product, the questions above apply directly to it. Check the connector catalog, test schema drift handling with a deliberately broken source, measure actual latency under load, and read the fine print on the pricing page. The people selling these tools are skilled at showing you the happy path. Your job is to stress-test the unhappy path before you sign anything.