Working With Z-Scores and Probability Tables
I learned about the standard normal distribution table back when I was running quality checks on a manufacturing line. We needed to know what percentage of our parts would fall outside acceptable tolerances. The table was printed on a single sheet of paper, laminated and taped next to my desk. I still have it somewhere. Here is how you actually use it without going insane.
Unlocking The Secrets Of The Standard Normal Distribution Table Your Guide To Mastering Probability
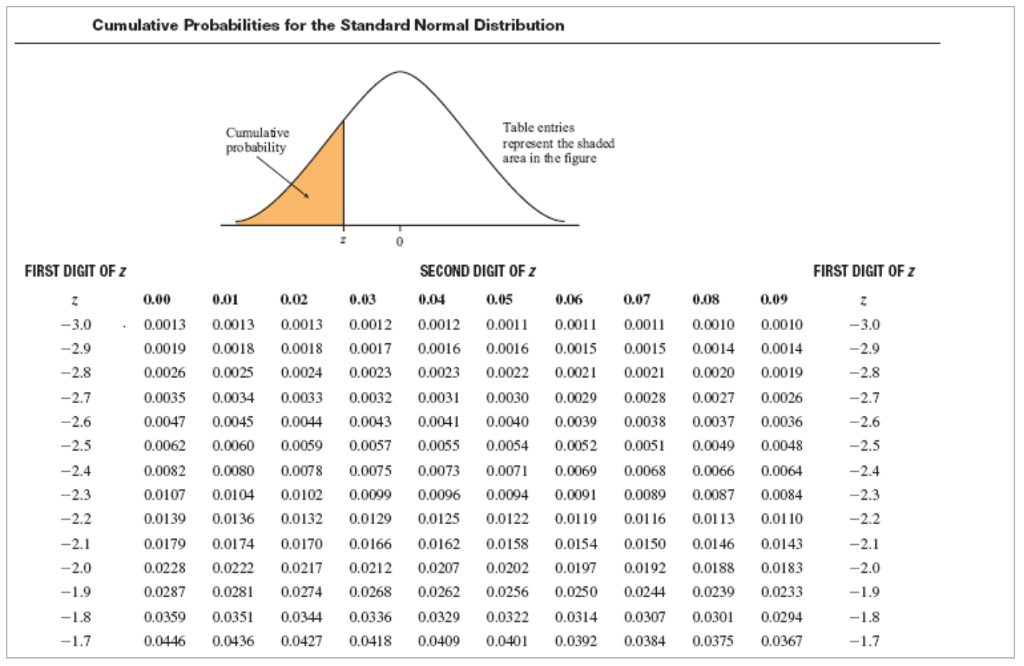
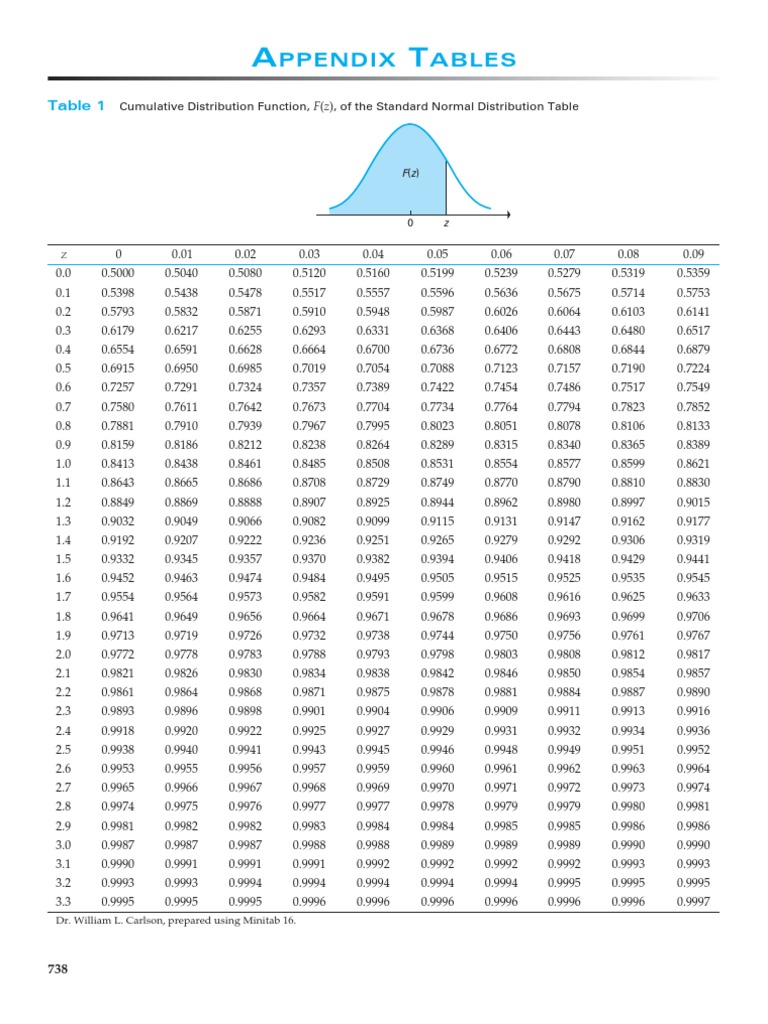
First, forget the idea that you need to remember anything. The table does the work for you. You just need to understand what you are looking up. The standard normal distribution has a mean of zero and a standard deviation of one. Every other normal distribution can be converted into this one using the Z-score formula: Z = (X - ) / . That is all the math you need upfront. Everything else is just reading a grid. Open the table. The left column gives you the Z value to one decimal place, like 1.2, 1.3, 1.4. The top row gives you the second decimal place, like 0.00, 0.01, 0.02. Find where your Z value lands, then read across and down to the intersection. The number you see is the cumulative probability from negative infinity up to that Z score.
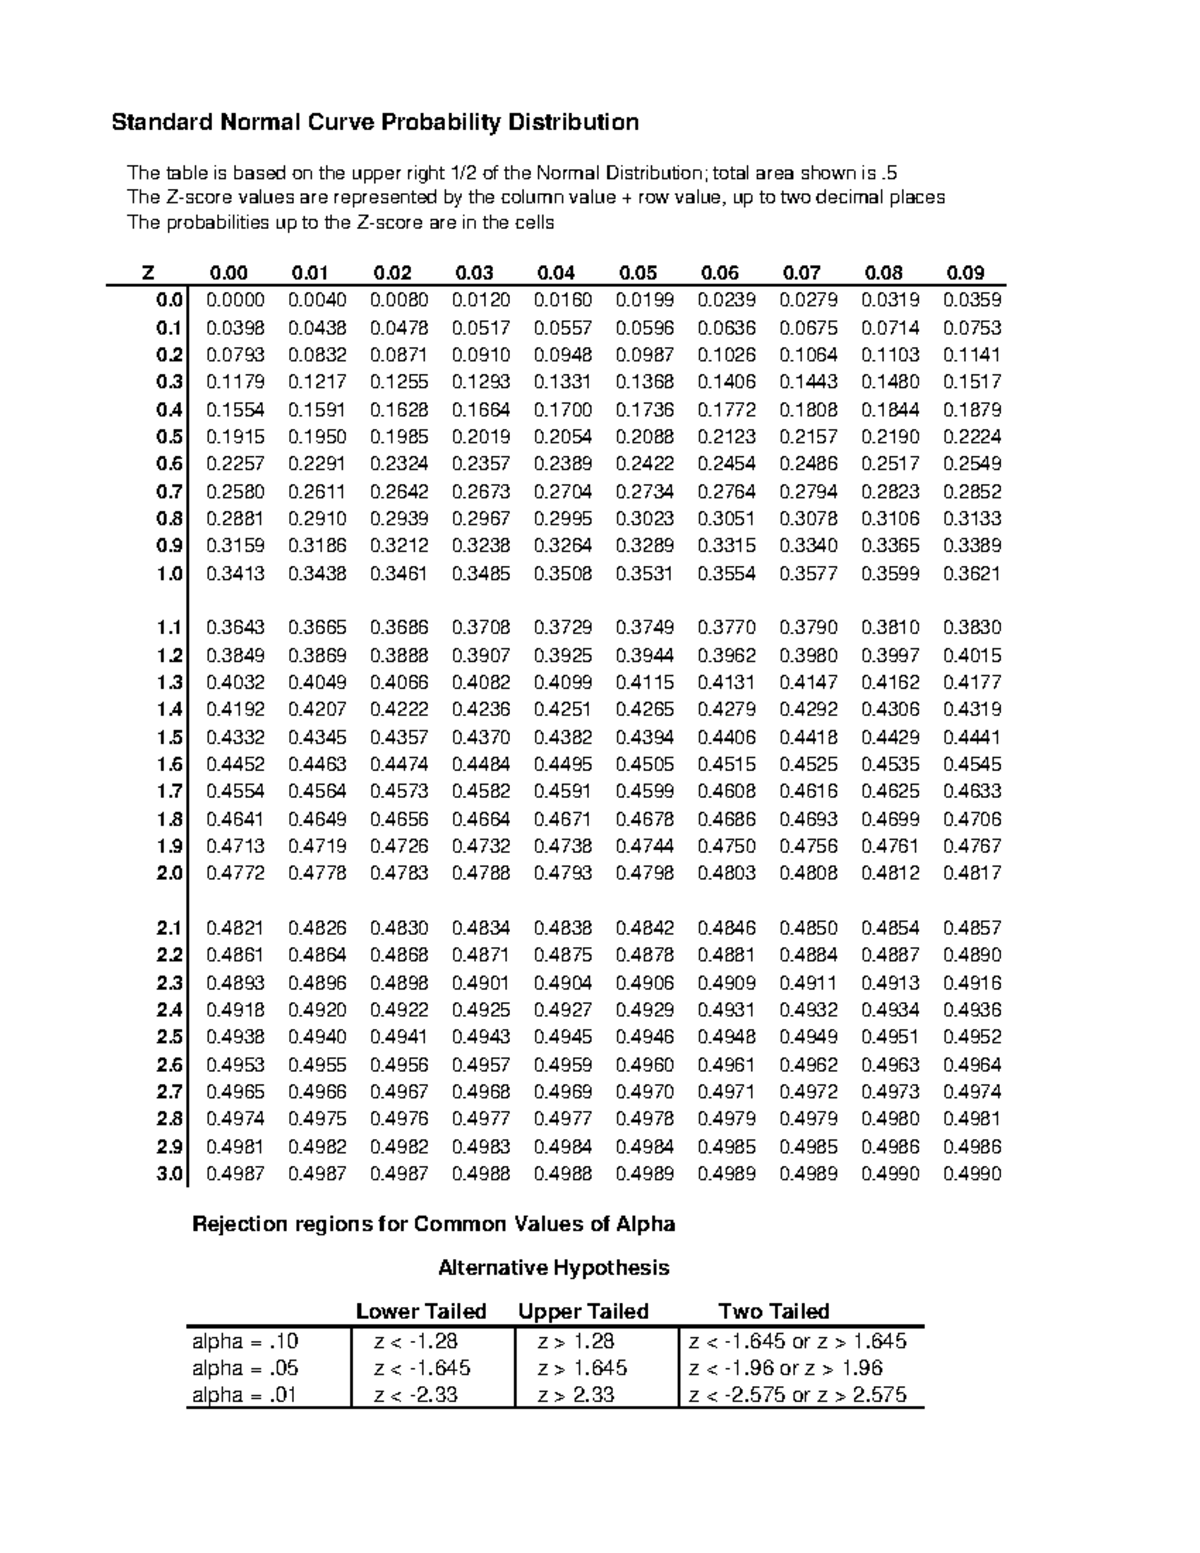
I used to get confused about whether the table gave me the area to the left or the area between the mean and the Z score. Different textbooks use different conventions. My workaround was simple: check the very first entry. If the table gives 0.5000 for Z = 0.00, it is showing cumulative area from the left. If it gives something else, you are dealing with a different format and need to adjust. This saved me countless hours of second-guessing myself during exams. Let me walk through a real example. Say you need to find the probability that a value is less than 1.47 in a standard normal distribution. Go down to row 1.4, then move across to column 0.07. You will find 0.9292. That means 92.92 percent of values fall below a Z score of 1.47. The remaining 7.08 percent fall above it. If you need the area between the mean and Z = 1.47, subtract 0.5000 from 0.9292 to get 0.4292. Now here is where beginners consistently mess up. They forget to handle negative Z scores. Most tables only show positive values because the distribution is symmetric. If your Z score is -1.23, find 1.23 in the table and get 0.8907, then subtract that from 1 to get 0.1093. The area to the left of -1.23 equals the area to the right of +1.23. That is symmetry, not magic.
Get the Full Details
Another common mistake: people treat the table as exact when it is not. The standard normal distribution table is computed numerically and rounded to four decimal places. That gives you roughly 0.0001 precision, which is fine for most practical work but inadequate if you are doing financial risk modeling or aerodynamics calculations. In those cases, use a calculator or software. RStudio, Python's scipy, even Excel with NORM.S.DIST will give you more precision without the lookup hassle. There is also a practical limitation nobody warns you about. The table assumes a perfectly normal distribution. Real data rarely behaves that cleanly. I once worked on a project where the underlying data was slightly skewed, and applying the normal table blindly gave us results that were off by nearly three percent in the tails. That seemed small until you are designing safety margins for bridge supports. Always check your data first, usually with a quick histogram or a Shapiro-Wilk test if you have sample size to spare. If you need area between two Z scores, like P(-0.5 < Z
1.2), look up both values and subtract. Table gives 0.8849 for 1.2 and 0.6915 for 0.5, but since we want negative 0.5, that is 1 minus 0.6915, which equals 0.3085. Then 0.8849 minus 0.3085 gives 0.5764. You are just finding two areas and taking the difference. That is the entire technique.
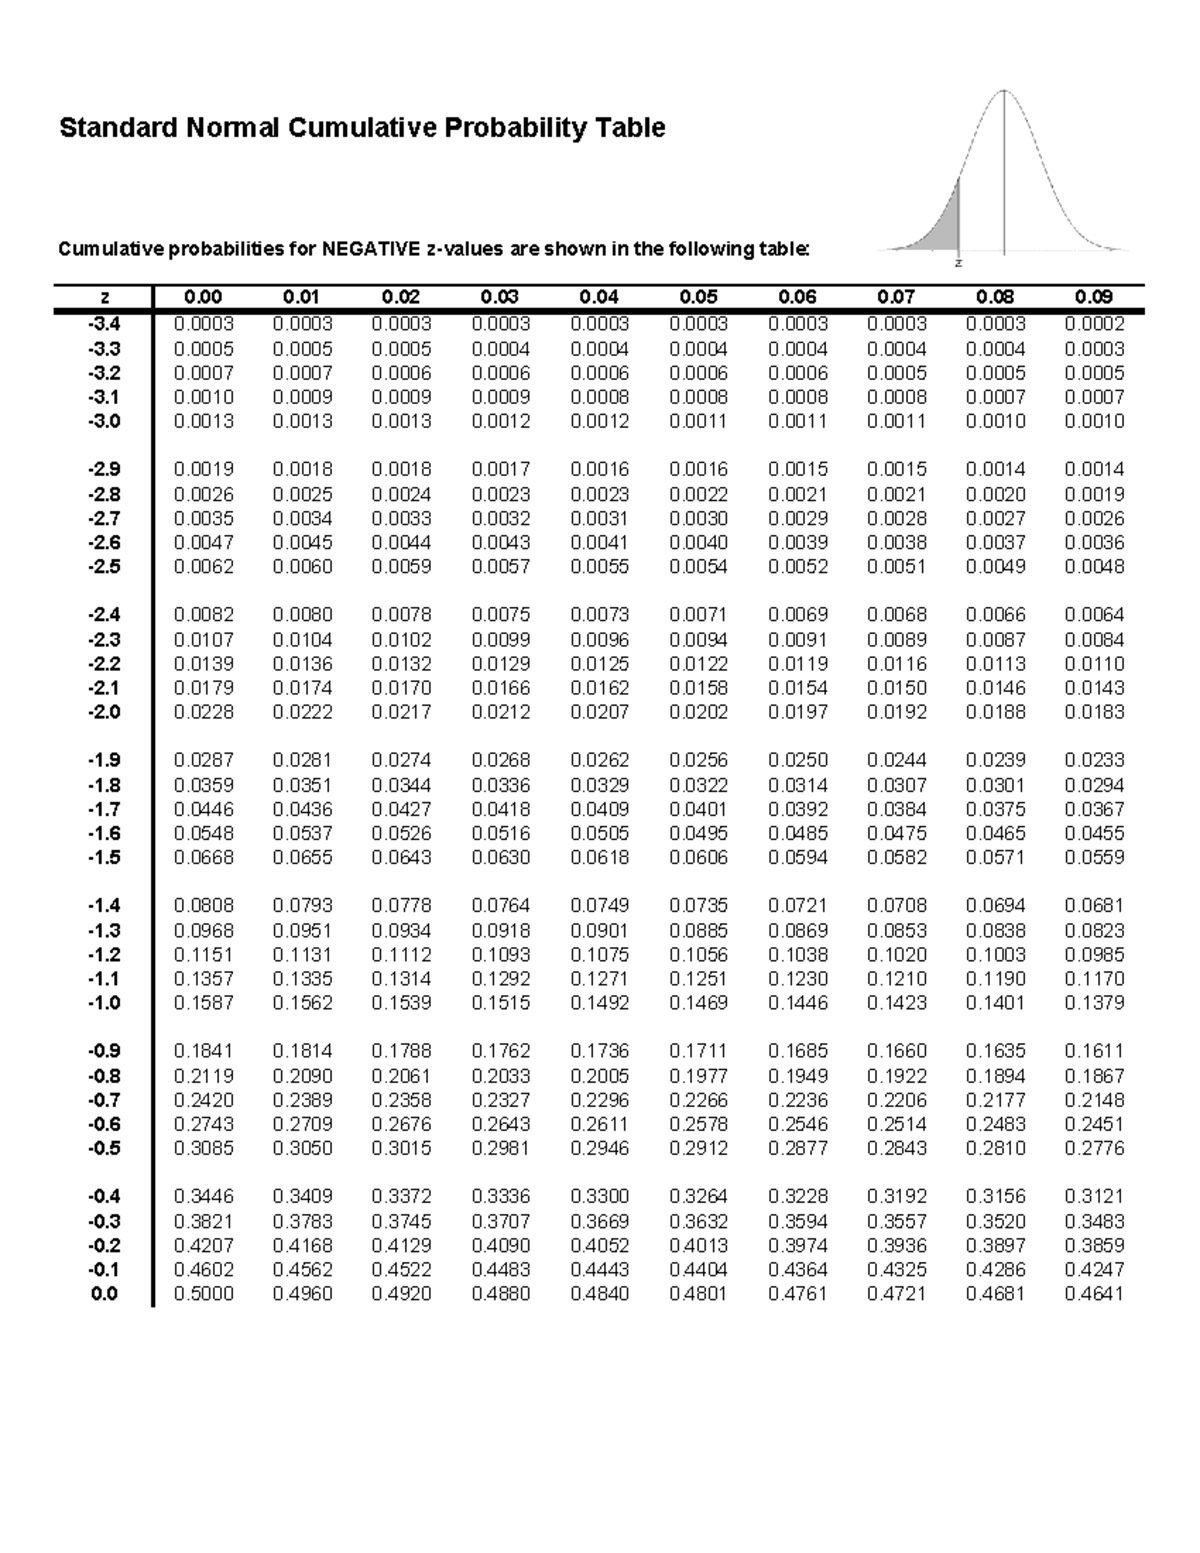
For the right tail, P(Z > a), always subtract the table value from 1. For the left tail, P(Z
-a), either look up a and subtract from 1, or use symmetry and look up -a directly if your table supports negative rows. Some modern tables include negative values, older ones do not. Know which you are holding before you start. I have seen people try to memorize common Z values instead of using the table. Z = 1.645 for 95 percent confidence, Z = 1.96 for 97.5 percent, Z = 2.576 for 99 percent. Those are worth knowing because you will use them constantly in hypothesis testing, but they do not replace the table. They only cover three values out of thousands. The table covers everything else. One edge case that catches people off guard involves interpolation. If your Z score falls between two table entries, like 1.473, some people round up, some round down, some average them. Rounding to the nearest hundredth is the standard approach and introduces negligible error for most applications. I have never seen anyone in practice complain about rounding 1.473 to 1.47 rather than interpolating between 1.47 and 1.48.
Also worth noting: the table only works for the standard normal. If your data has a different mean or standard deviation, you must convert to Z first. There is no shortcut. I watched a student in grad school skip this step and use the table directly on raw scores, getting results that made no physical sense. It took us twenty minutes to find the error. The conversion step is non-negotiable. For those who want to practice, most university statistics departments publish free downloadable PDFs of the standard normal table. Search for "standard normal distribution table PDF" and you will find versions with and without cumulative distribution, with positive and negative values. Print one out if you are studying for an exam. Electronic tables on calculators are convenient but hide the mechanics, which makes you vulnerable when technology fails during a test or a presentation. The deeper you go into statistics, the more this table becomes background noise in your mind. You stop reading it consciously and start recognizing patterns. Z = 2 means roughly 95 percent within, Z = 3 means 99.7 percent. These rough heuristics are useful in casual conversation, but they are not precise enough for actual work. When precision matters, go back to the table or the calculator.
That is really all there is to it. The standard normal distribution table is not a mystery. It is a reference tool, like a dictionary. You do not need to understand why the words are arranged the way they are, you just need to know how to find what you are looking for quickly and accurately.