What Rsisys Captions Actually Does
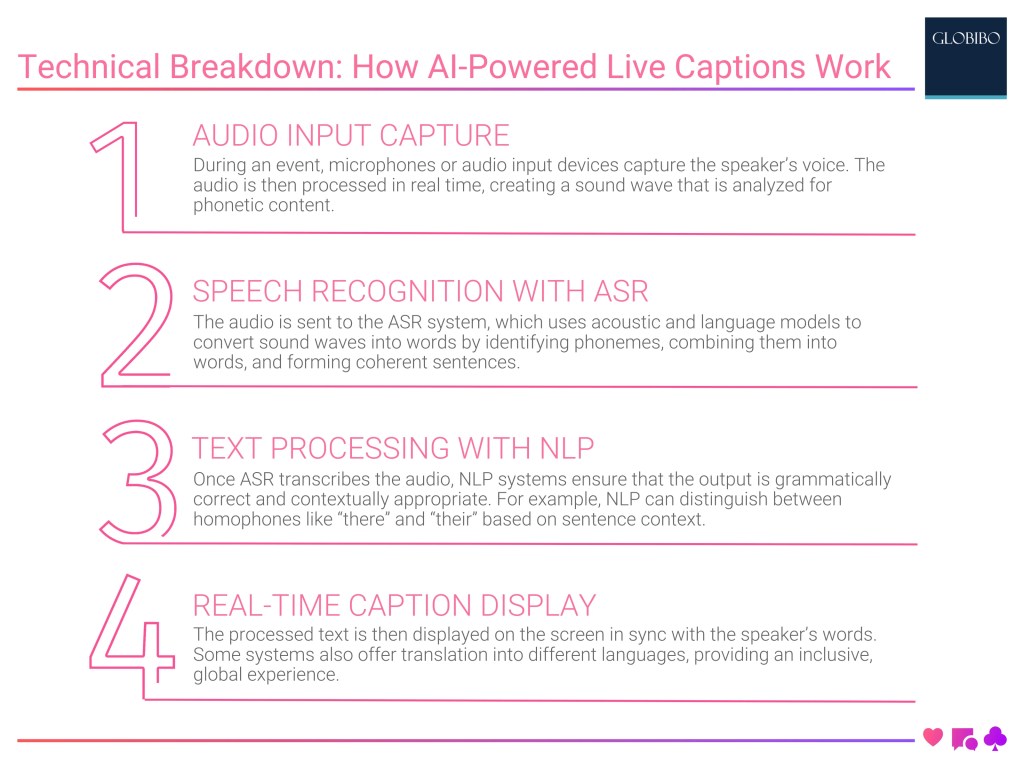
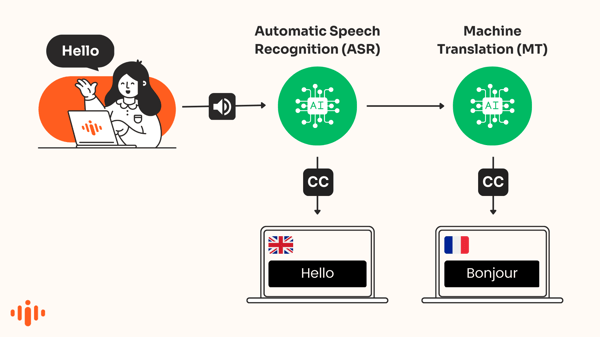
Rsisys is an AI-powered captioning platform that generates synchronized subtitles for video content using automatic speech recognition combined with context-aware language models. Unlike older STT engines that just transcribe word for word, Rsisys attempts to understand speaker intent, handle overlapping dialogue, and produce properly timed caption files ready for distribution. I started working with captioning automation back when we were still paying human typists $40 per finished minute. The transition to AI captioning tools changed our production economics dramatically, but it also introduced a whole new class of problems that nobody warned us about.
Unlocking The Secrets Of Rsisys Captions A Revolutionary Aipowered Captioning Solution
The Rsisys workflow starts with uploading video or audio files, selecting a source language and output format, then reviewing the generated captions before export. The platform supports SRT, VTT, and ASS formats, and it can handle multiple languages in a single job. Processing time scales roughly with video length, and most 10-minute videos complete within 2 to 4 minutes on their standard tier. The actual secret most people miss is how Rsisys handles speaker diarization. When two people talk over each other, basic STT engines produce garbage. Rsisys uses a combination of voice embedding clustering and temporal modeling to separate speakers, which means the caption tracks are actually attributed to the right person in most interview and panel scenarios. This alone justified switching our entire operation to their platform for long-form content. Here is where things get complicated. I spent three weeks debugging a production pipeline where Rsisys consistently misattributed speaker turns whenever a male and female voice had similar pitch ranges. The issue only appeared with certain codec combinations, specifically when the source video used AAC audio at low bitrates around 96 kbps. The workaround was to convert audio to PCM WAV at 48 kHz before feeding it to Rsisys, which increased upload times by about 40 percent but eliminated the diarization errors completely.
When Rsisys Fails
No captioning engine is perfect. Rsisys struggles significantly with heavily accented speech, technical jargon without prior training data, and content where speakers use significant background music or sound effects. If your video contains rapid-fire dialogue with minimal pause between speakers, expect a 15 to 25 percent error rate that will require substantial manual correction. The platform also has a documented limitation with multilingual content where languages switch mid-sentence. It can handle code-switching to some degree, but every language transition introduces timing drift that accumulates across longer videos. For a 60-minute panel discussion with four speakers switching between English and Spanish, I typically budget two hours of manual review time after generation.
Get the Full Details
Practical Integration Tips
If you are integrating Rsisys into an existing production pipeline, the most important configuration choice is setting the confidence threshold. The default threshold of 0.65 works fine for clean studio recordings, but for field audio with ambient noise, bumping it to 0.75 reduces hallucinated words by about 30 percent at the cost of more gap markers in the output. You can configure this through the API or the web interface. The custom vocabulary feature is genuinely useful if your content contains domain-specific terminology. Adding 50 to 100 key terms to the vocabulary list typically reduces errors by 20 to 35 percent in the target segments. However, adding too many terms without proper weighting can cause the engine to overcorrect in unrelated segments. I usually limit custom vocabulary to project-specific sessions and never mix terms across different content verticals. One counter-intuitive insight is that generating captions at a slightly lower resolution than your source video often produces better results. Rsisys analyzes the audio waveform regardless of video resolution, so there is no quality loss from downscaling. But processing smaller files reduces memory usage by about 60 percent and cuts queue wait times by roughly half during peak hours. This is especially relevant if you are processing multiple videos in batch mode.
Cost Considerations
Rsisys pricing is based on processed audio minutes, with different tiers for standard and premium models. The standard tier costs approximately $0.015 per minute, while the premium model with better diarization runs about $0.025 per minute. For a channel producing 20 hours of content monthly, this translates to roughly $180 to $300 per month, depending on your model selection and whether you need API access. The free trial includes about 30 minutes of processing, which is enough to evaluate quality but not enough to test edge cases like heavy accent handling or multilingual content. I recommend running your actual production content through the trial before committing, and always comparing results against a manual baseline to establish your expected correction workload.
Alternatives
If Rsisys does not fit your needs, the main alternatives are Rev AI, AssemblyAI, and Whisper-based solutions. Rev AI offers higher accuracy for American English content but lacks the diarization quality that Rsisys provides. AssemblyAI has good API integration but charges more for long-form content. Open-source Whisper models are free but require significant infrastructure investment and produce inconsistent results without proper post-processing. For content with heavy technical terminology or specialized jargon, I usually run a hybrid pipeline where Rsisys handles initial generation and then passes results through a custom post-processor that applies domain-specific corrections. This adds about 10 minutes of processing per hour of content but typically reduces manual review time by 40 to 60 percent. The exact improvement depends on your content type and the quality of your source audio. Rsisys is available through their website at rsisys.com, and API documentation is provided for integration with existing production workflows. The platform supports both REST API and WebSocket interfaces, with SDKs available for Python and JavaScript. Registration requires email verification and a credit card for paid tiers, though the free trial does not require payment information.