Getting Started With the SDK
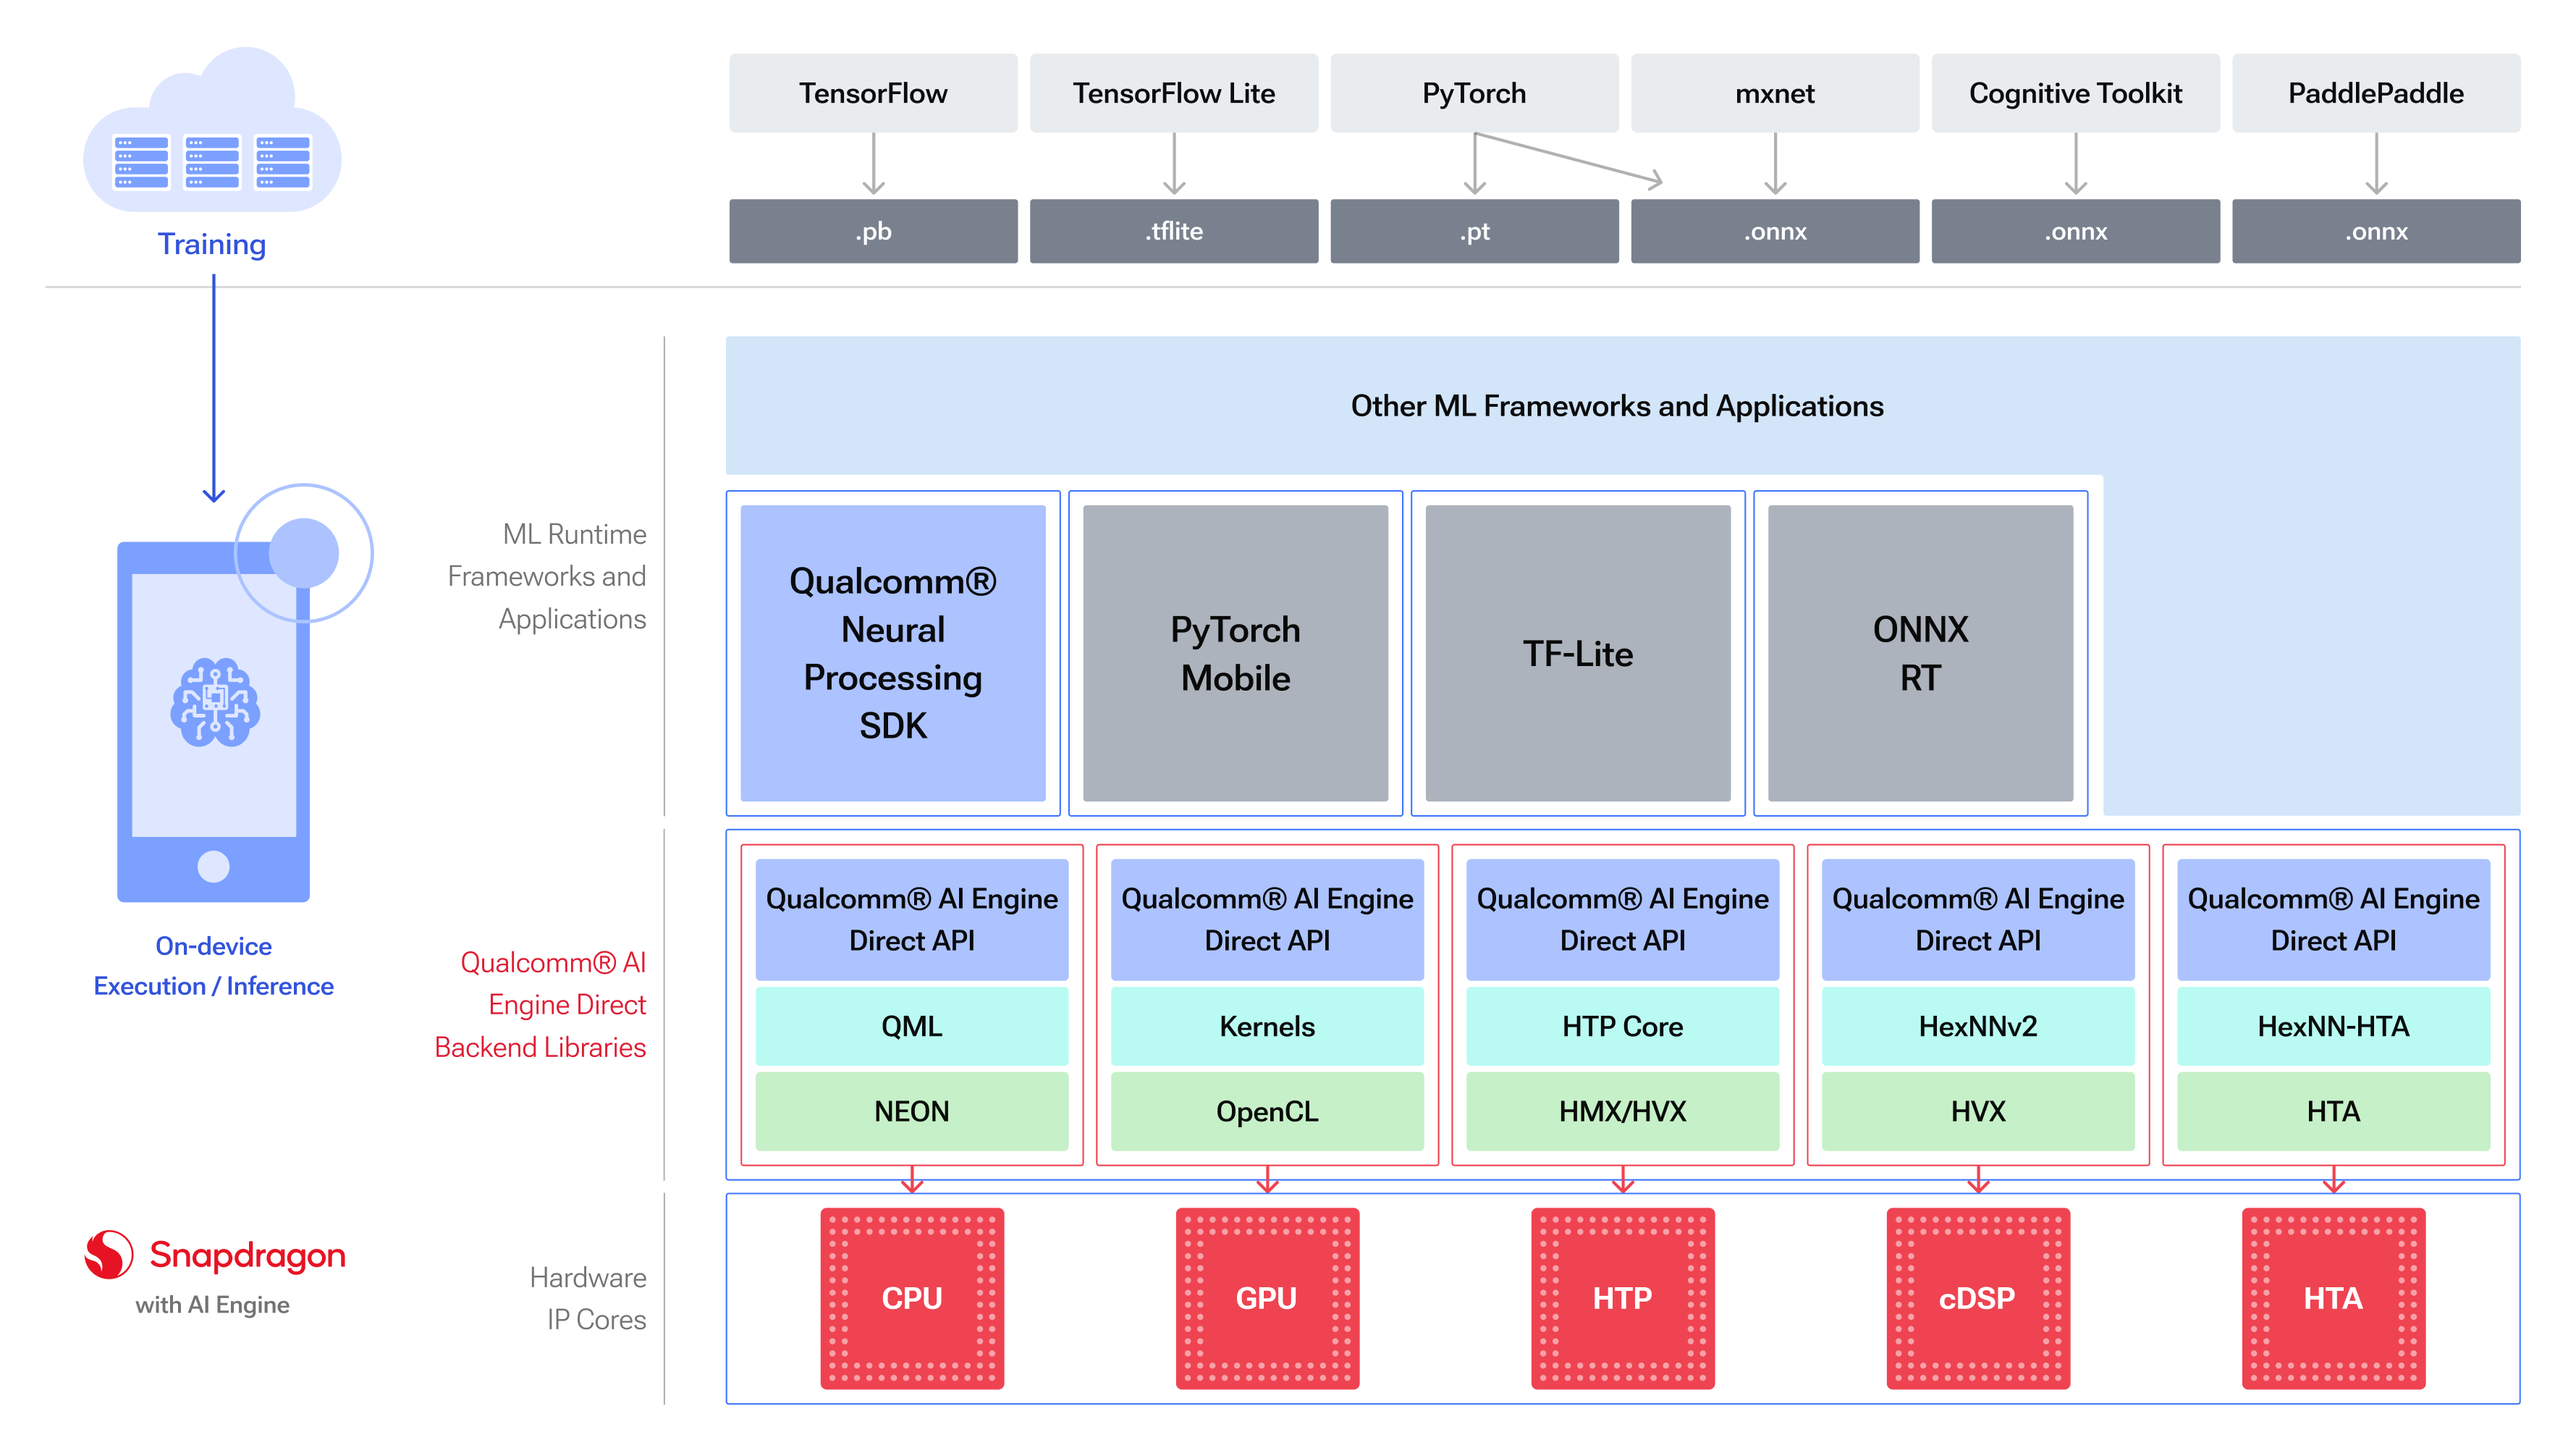
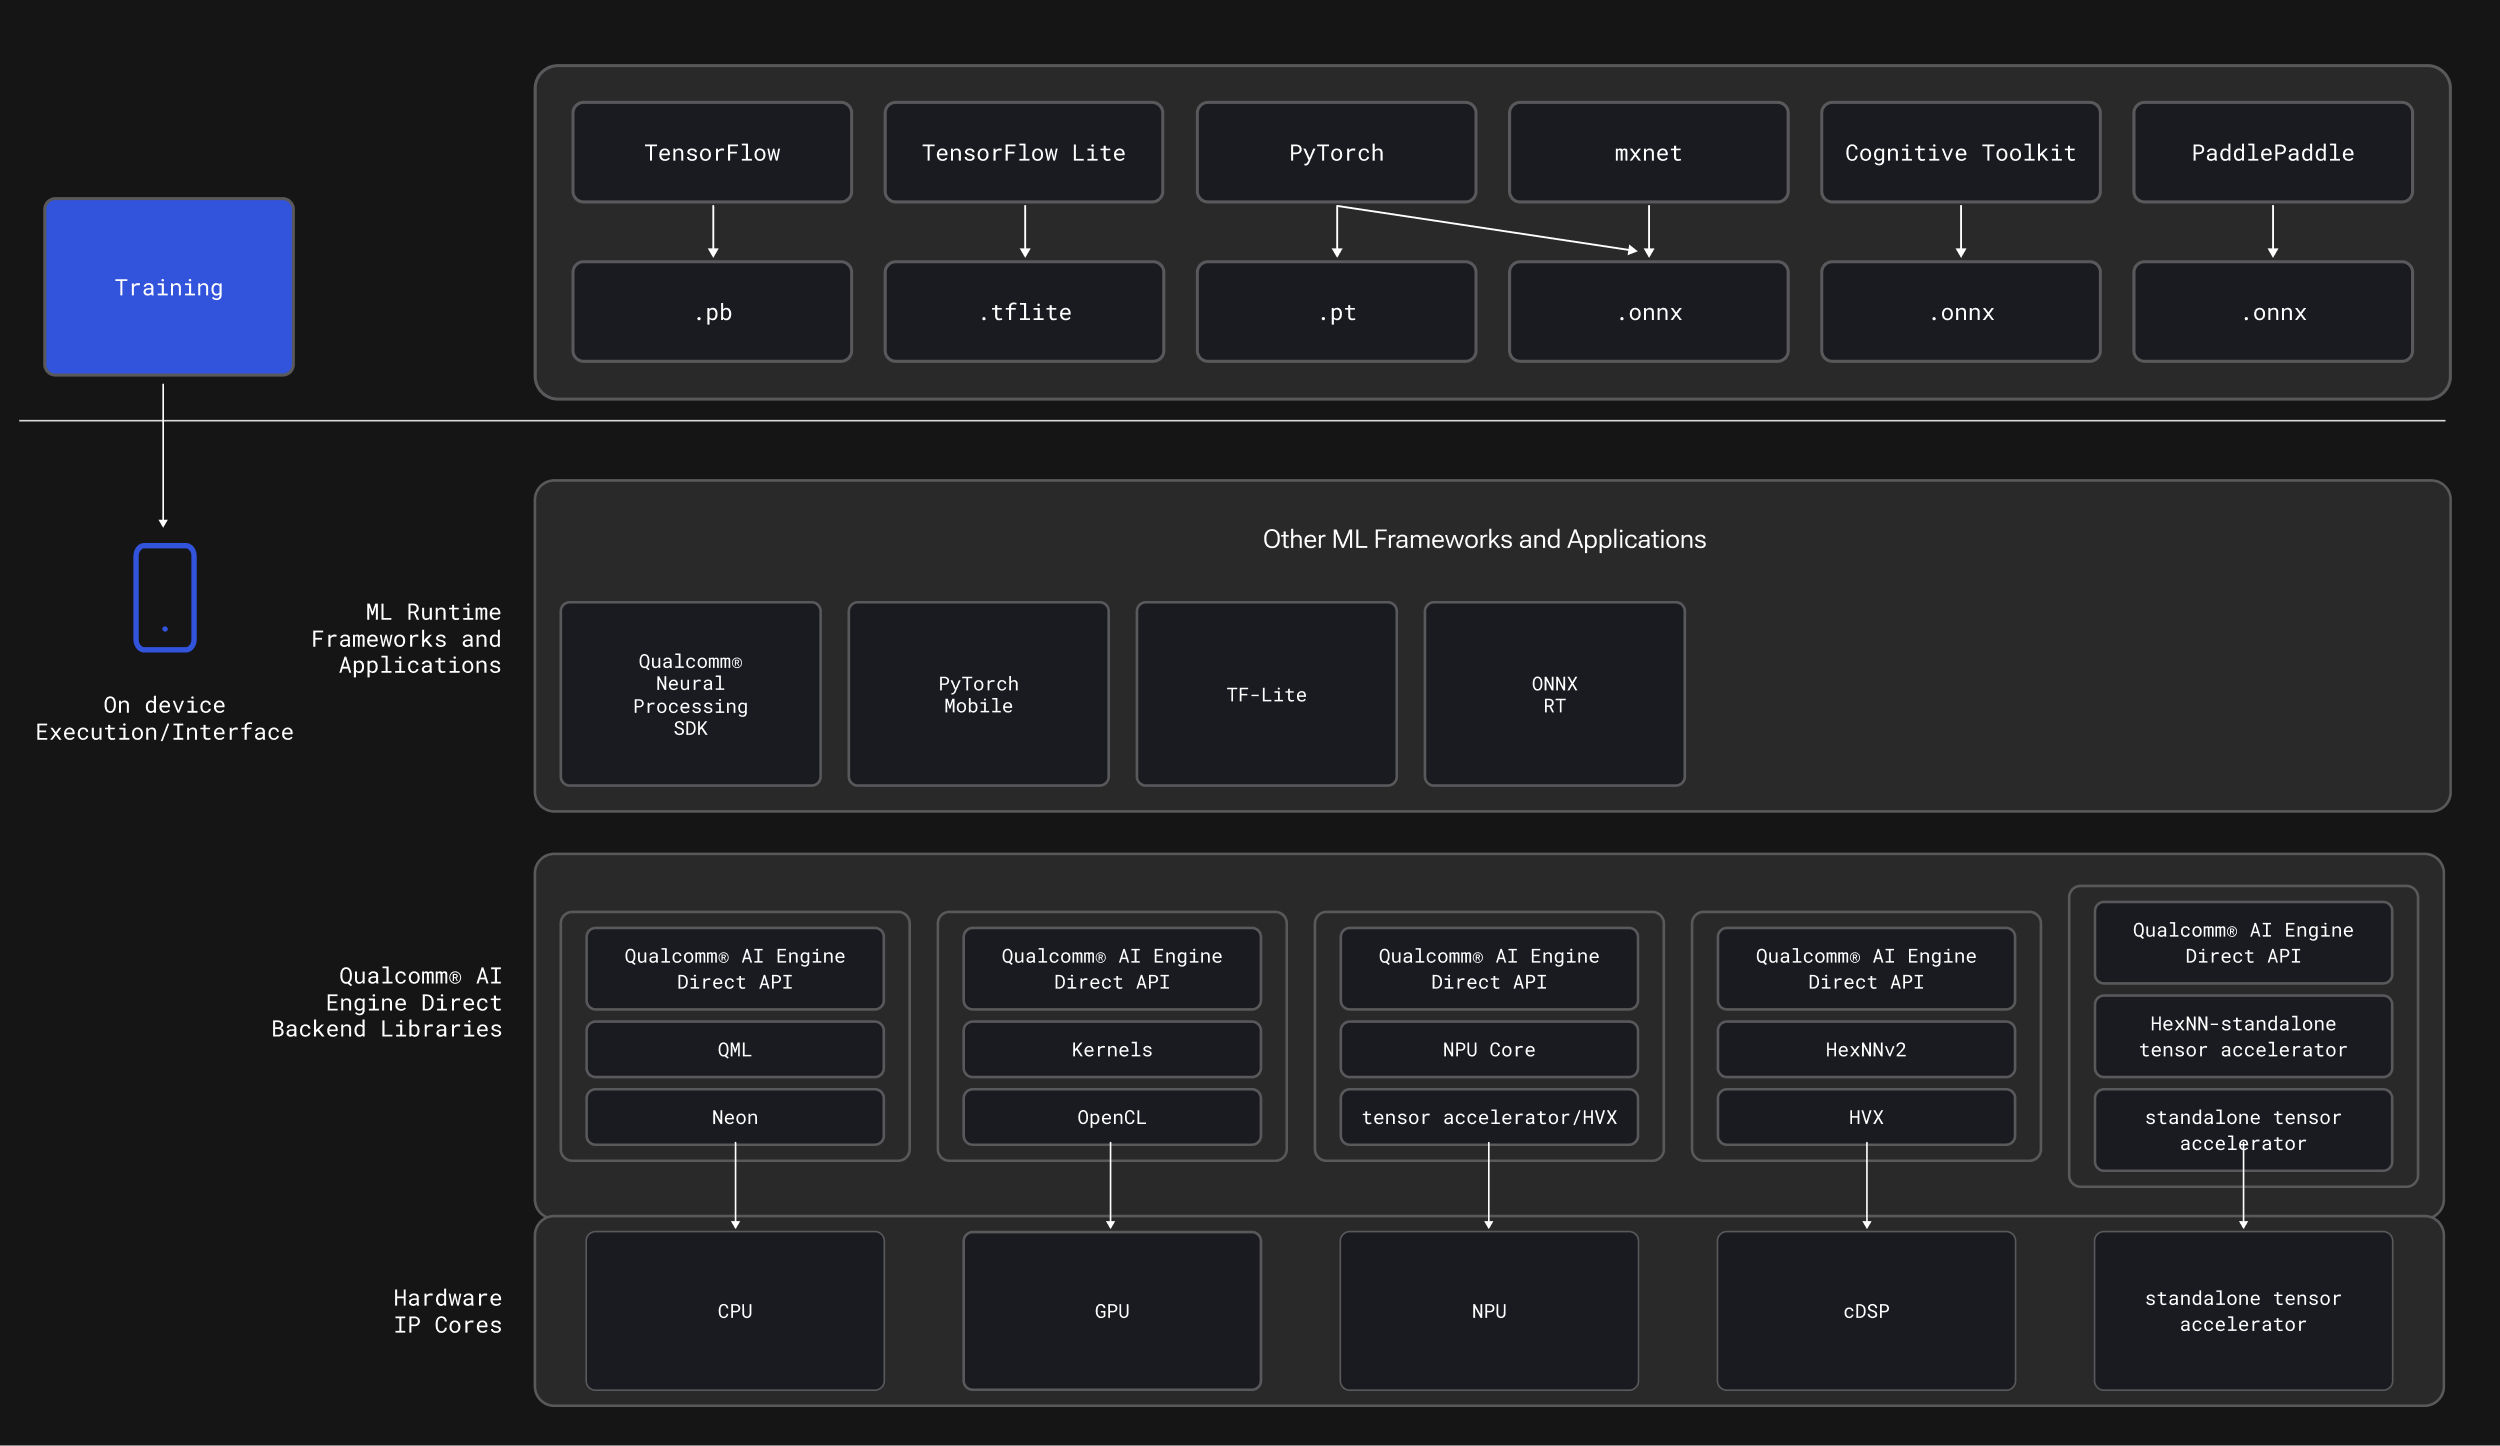
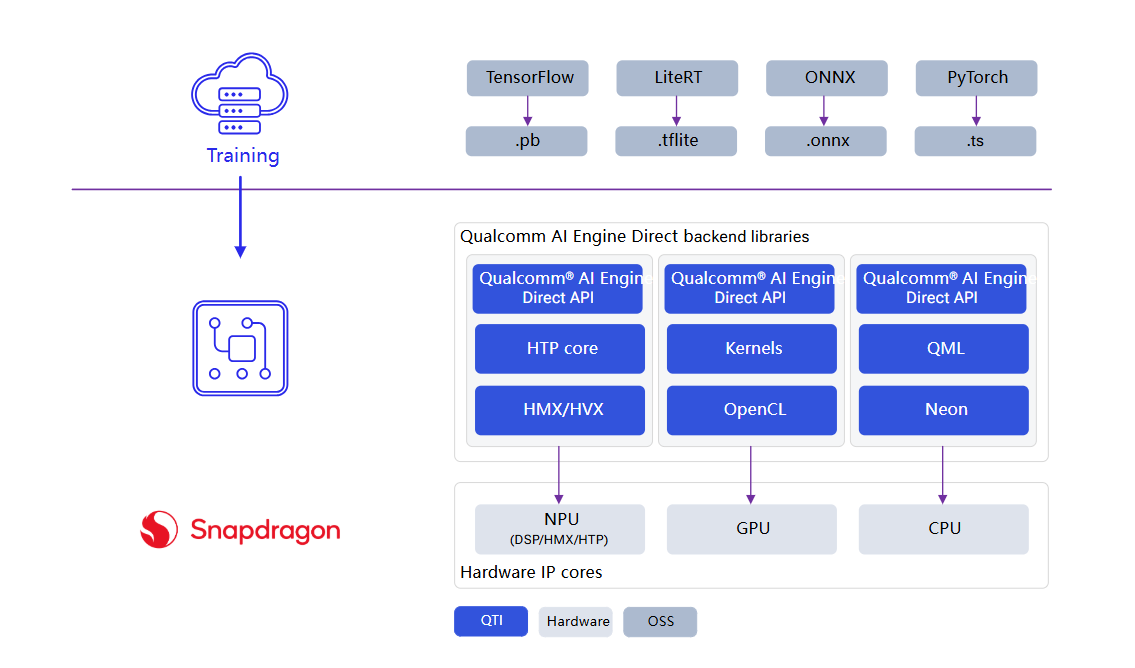
The Qualcomm AI Engine Direct SDK lives on GitHub and gives you the tools to run neural networks directly on the Hexagon DSP inside Qualcomm Snapdragon chips. Most people come here trying to get a model off the CPU and onto the DSP. The documentation covers the basics, but the hard part is actually making things work end to end. The GitHub repo contains samples, documentation, and release notes. Clone it, read the README, then immediately look at the samples directory. That's where the actual working code is. The README is useful for setup, but the samples show you what deployment actually looks like.
Unlocking The Secrets Of Qualcomm AI Engine Direct SDK A Comprehensive GitHub Guide
The SDK is structured around a few key pieces: the core runtime library, the converter toolchain for transforming models from frameworks like TensorFlow or PyTorch into QNN format, and a set of sample applications that demonstrate different architectures. The converter is arguably the most important part because this is where most models break. To get started, you need a compatible Snapdragon device running the right firmware version. The SDK does not run on emulators. You need an actual phone or development board. The hardware matters because different chip generations support different operator sets, and the Hexagon version changes between SoCs. Download the SDK from the Qualcomm developer portal and extract it. You will get a directory with libs, include files, samples, and documentation. Set your environment variables for the SDK path and the target device platform. This is one of those steps that seems simple but causes problems later if you get it wrong, so pay attention to which device platform string you use for your target chip.
Model Conversion
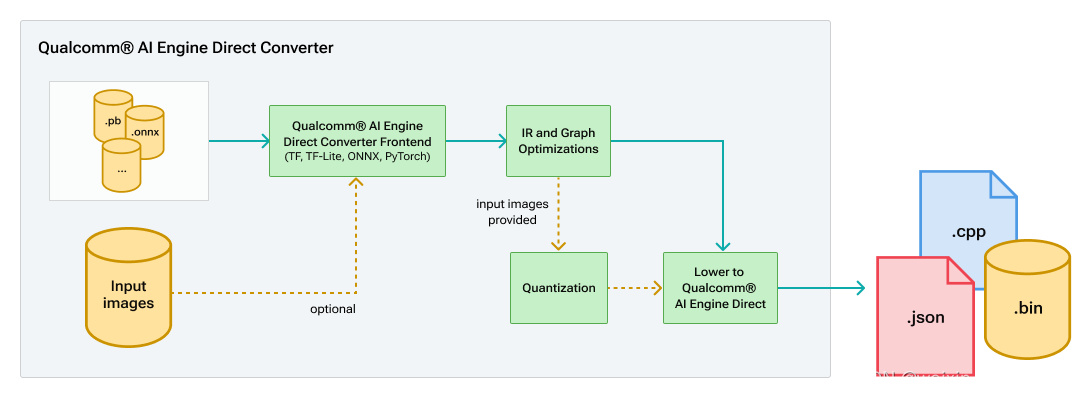
The converter takes a standard model and turns it into a QNN shared library that runs on the Hexagon DSP. You feed it a TensorFlow SavedModel, ONNX file, or TensorFlow Lite model. It outputs a .so file that the runtime loads at execution time. The command line looks something like this: python convert.py --model_dir ./my_model --backend hexagon --output_dir ./qnn_output
Get the Full Details
The options are extensive. You specify the backend, the precision mode, and which operators to target. The default settings usually produce a working model, but they are not always optimal. Running with --op_precision mixed gives you a good balance between accuracy and performance without requiring manual configuration of every layer. I ran into an issue converting a YOLOv8 model last year. The converter choked on the Concat operation inside the network section. The error message was not particularly helpful. The problem was that the concat axis was set in a way the Hexagon backend could not resolve cleanly. I worked around it by modifying the model definition to use a different concatenation strategy before conversion, which made the export succeed without any meaningful change to output quality. Another common issue is dynamic shapes. The SDK handles dynamic dimensions better than previous versions, but you still hit limits. If your model uses variable input sizes and the converter fails, try freezing the shape first. It adds overhead to deployment but guarantees the conversion succeeds.
Runtime Integration
Once you have your QNN model compiled, you load it into your application using the QNN runtime API. The flow is straightforward: initialize the context, create the graph, set inputs and outputs, run inference, and clean up. The samples on GitHub demonstrate this pattern clearly. Here's what initialization typically looks like in code: Qnn_Context_t context = NULL;
QNN_LIB_PATH points to the QNN shared library on the device. Make sure this path is correct for your target architecture, otherwise the app crashes immediately on launch with a library not found error. The performance you get depends heavily on how you manage the device resources. Running inference on the CPU fallback path is always available but defeats the purpose. You need to make sure the Hexagon backend is actually being used. You can verify this by checking the device context initialization logs. If the logs show the Hexagon backend was not selected, your model probably contains an unsupported operator and fell back to CPU. Profiling is built into the SDK. Use the QNN profTool to capture timing data across the entire inference pipeline. It tells you exactly where time is being spent and which operations are the bottleneck. Without this, you are guessing about performance issues.
Common Problems and Workarounds
The biggest source of frustration is operator support. Not every PyTorch or TensorFlow operator maps cleanly to Hexagon. When a model fails to compile, check the operator list against the Qualcomm supported operator documentation. If an operator is missing, you have two choices: rewrite that part of the model in supported operations, or fall back to the CPU for that segment only. Memory management is another area where things go wrong. The DSP has its own memory space separate from the ARM CPU memory. If you pass pointers incorrectly, you get segmentation faults or silent data corruption. Always use the QNN memory allocation functions provided by the runtime rather than allocating buffers manually and hoping they end up in the right place. One specific issue I dealt with involved model accuracy degradation after conversion. The numerical differences between the original model and the Hexagon execution were small in most cases, but for a particular detection model, the false positive rate spiked noticeably. The fix was switching from float16 to float32 precision on the critical layers using the converter's layer override flags. This added some latency but restored accuracy to acceptable levels.
The SDK release notes are worth reading before every update. Qualcomm frequently fixes converter bugs and adds operator support. I wasted half a day troubleshooting a model conversion issue that was resolved in a patch release I had not installed yet.
Practical Tips
Keep your models small and simple. The Hexagon DSP handles straightforward architectures well, but complex custom layers increase the chance of conversion failures and runtime instability. If a model works on CPU but fails on DSP, the issue is almost always in the model definition rather than the SDK. Test early and test on the actual device. Cross compilation for Snapdragon chips is not the same as running on the phone. An app that builds cleanly on your machine may crash on the target. Set up a fast iteration loop by pushing builds to the device frequently. Use the sample apps as a baseline before writing your own integration. They cover the common use cases and edge handling that you would otherwise discover the hard way. Modifying an existing sample is faster than starting from scratch.
The GitHub repository includes issue trackers and community discussions. Checking those before opening a new issue often reveals that you are hitting a known problem with an existing workaround. Qualcomm engineers do respond to issues in the repo, but the community answers tend to be faster.
When This Approach Does Not Work
If your model relies heavily on operators that the Hexagon DSP does not support, the AI Engine Direct SDK may not be the right choice. In those cases, running on the GPU through OpenCL or Vulkan compute shaders is a viable alternative. The Adreno GPU supports a much larger operator set than Hexagon, though the performance characteristics are different. Some models actually run faster on GPU despite the reputation of DSPs being more power efficient. Cloud-based inference is also worth considering for models that simply cannot be optimized for edge deployment. The latency is higher, but you avoid the entire conversion and compatibility problem. The SDK itself has limitations on maximum model size, though these limits have increased with each release. Very large vision models may exceed what the DSP can handle in a single inference call, requiring you to split the computation across multiple runs or use a hybrid CPU-DSP approach, which adds complexity.