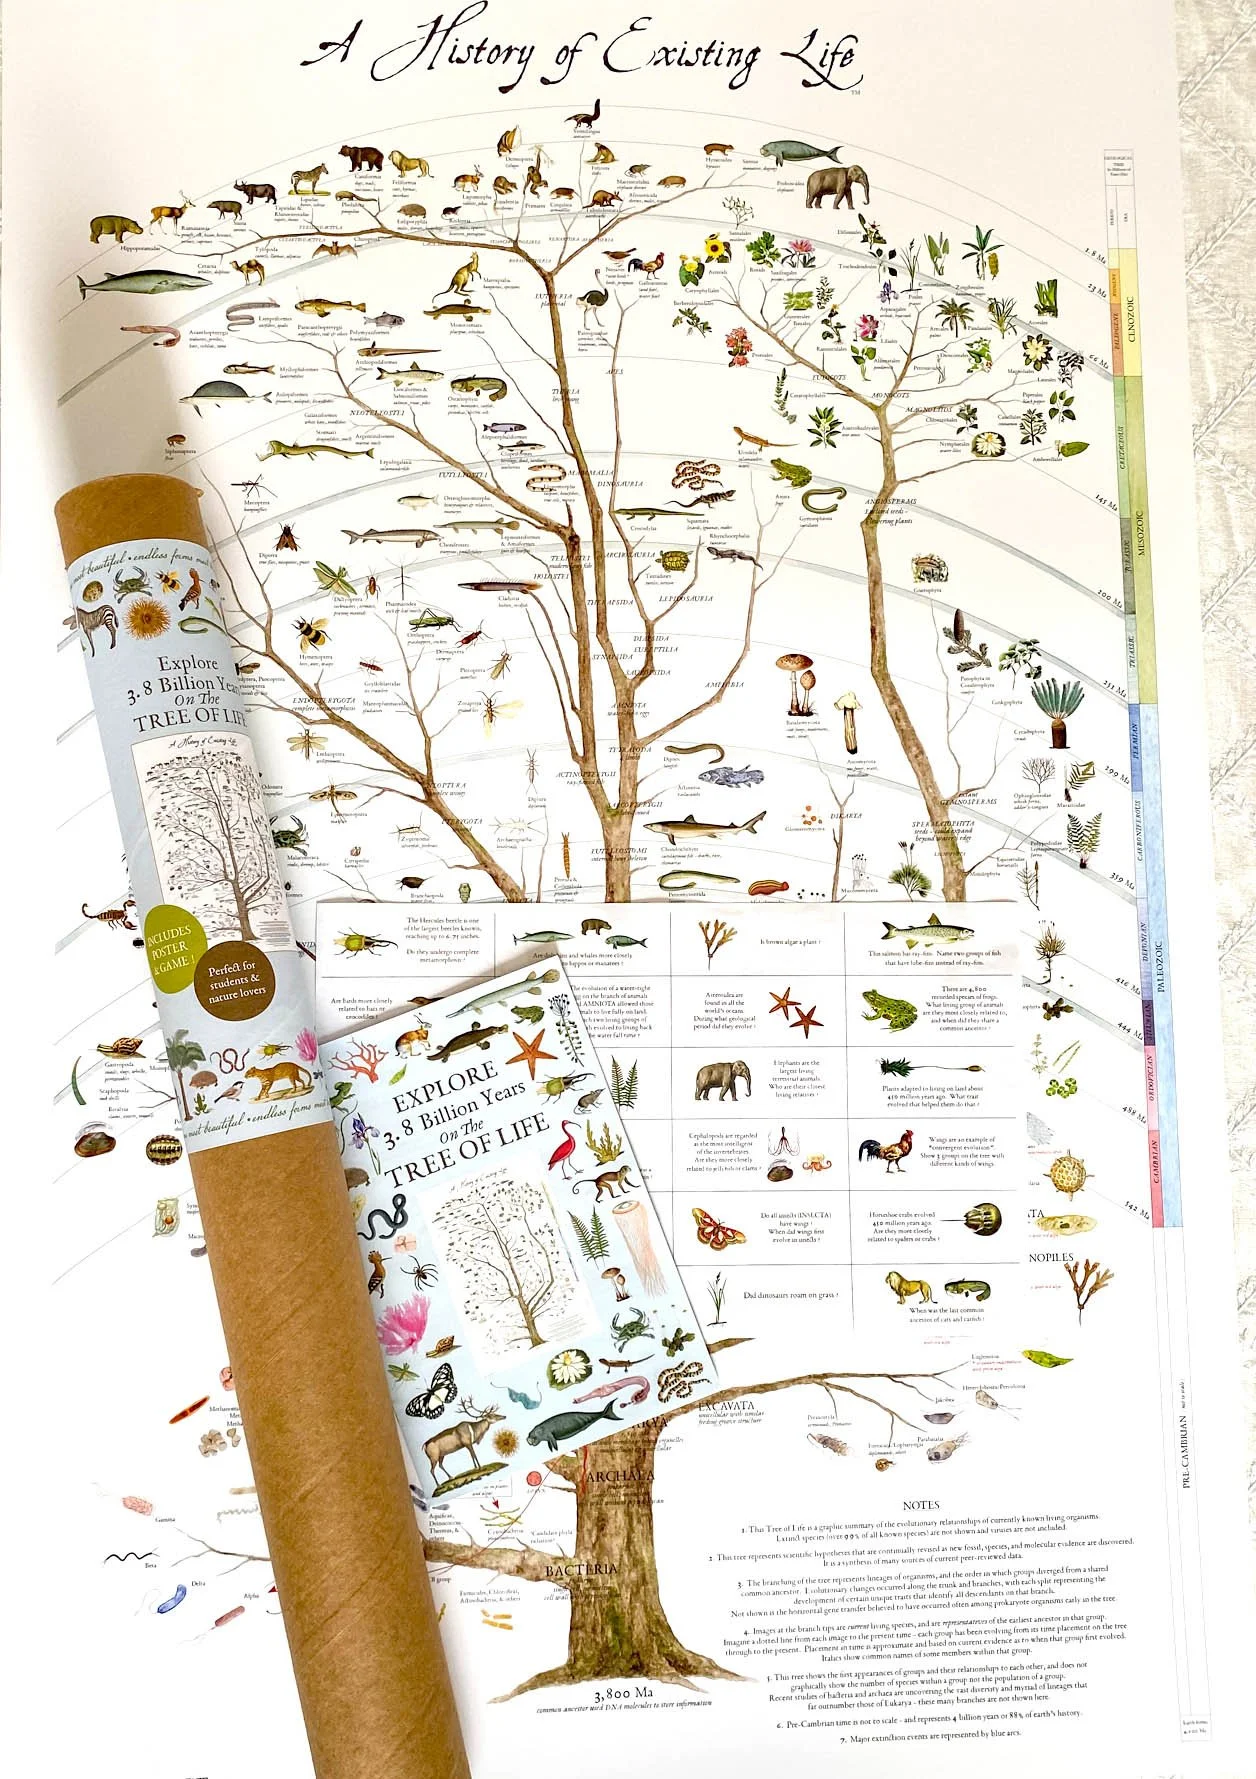
Phylogenetic trees are just one of those things everyone uses without really understanding what they're doing
I spent years getting burned by poorly constructed trees and bad alignment parameters. You build a tree, someone says "that's beautiful," and then you realize the bootstrap values were garbage because you ran the wrong model or forgot to trim ambiguously aligned sites. It happens more than you think. Here's how I actually do it now. Not the textbook version. The version that doesn't make you look like an idiot when someone asks about your confidence values.
Getting Started With Unlocking The Secrets Of Life The Power Of Phylogenetic Trees
You need sequence data first.FASTA files, preferably aligned. If you're aligning from scratch, MAFFT is fine for most things up to a few hundred sequences, but if you're working with large datasets or divergent sequences, Clustal Omega or even PRANK for codon-aware alignment will save you later. I use MAFFT with the --auto flag and usually add --retree 2 for better accuracy on tricky sets. Takes maybe ten minutes longer but the results are noticeably cleaner. Once you have your alignment, check it. Not just visually. Use a tool like AliView or Geneious to spot obvious misalignments, but more importantly, trim it. TrimAl with the gappyout or automated1 setting removes the worst offenders without shredding your data. Skipping this step is the single most common mistake I see. People feed a raw, messy alignment into a tree builder and then act surprised when their topology looks like spaghetti.
Picking The Right Substitution Model
This is where most people mess up and then wonder why their trees don't match published work. Model selection matters more than you'd expect. jModelTest 2 or ModelFinder (built into IQ-TREE) will run through candidate models and give you the best fit based on BIC or AICc. Don't skip it. Don't default to GTR+G just because it's the default in some software. Pick the model the data actually supports. I remember one project where switching from the naive model (GTR+G) to the selected model (TVME+F+R4) changed the entire deep topology. The relationship between three clades flipped completely. That one mistake would have cost me a revision if anyone had caught it.
Get the Full Details
Tree Building And Confidence Assessment
For maximum likelihood, IQ-TREE is what I use now. It's fast, handles large datasets well, and the built-in model selection is solid. The command I run looks something like this: iqtree -s alignment.phy -m MFP -B 1000 -A 1000 -nt auto The -B and -A flags run ultrafast bootstrap replicates. 1000 is reasonable. Don't bother with 10000 unless you're publishing and need every possible reviewer happy. The speed difference is enormous. A tree that takes thirty minutes with standard bootstrap might take four hours with 10000 replicates, and the extra precision rarely changes the interpretation.
Bayesian methods like MrBayes or BEAST2 are an option, but honestly, for most standard phylogenetic analyses they're overkill. They take forever and the convergence diagnostics are a pain to manage. I only use them when I specifically need divergence time estimates or when the dataset is small enough that computational cost isn't a factor. Here's something counter-intuitive that beginners miss: high bootstrap values don't mean your tree is correct. They mean the data strongly supports that grouping given your model and alignment. If your alignment is wrong, or your model is wrong, or there's long-branch attraction messing things up, those bootstrap values will be confidently wrong. I've seen bootstrap values of 99 percent on branches that were clearly artifacts of poor taxon sampling. Always cross-check with alternate methods or at least different model specifications before trusting a topology.
A Specific Problem I Ran Into
Last year I was building a tree for a group of fungal endophytes and got completely contradictory topologies between my ML tree and the Bayesian analysis. The bootstrap support was high across the board, which made it worse. After two days of troubleshooting, I realized the issue was compositional heterogeneity. Some sequences had wildly different GC content, and the substitution model wasn't accounting for it. The fix was running Phylo-MCOA to detect compositional bias, identifying the problematic sequences, and then using a codon model in IQ-TREE instead of a nucleotide model. The resulting tree matched what the literature predicted. Took me another six hours but at least it wasn't garbage anymore. If you're working with deep evolutionary questions or highly divergent sequences, always check for compositional bias. Posterior predictive checks in PhyloBayes can help too, though they're slower. Just running the chi-squared test for compositional homogeneity in PAUP or R with the phangorn package takes seconds and might save you hours of headache.
Visualization and Final Steps
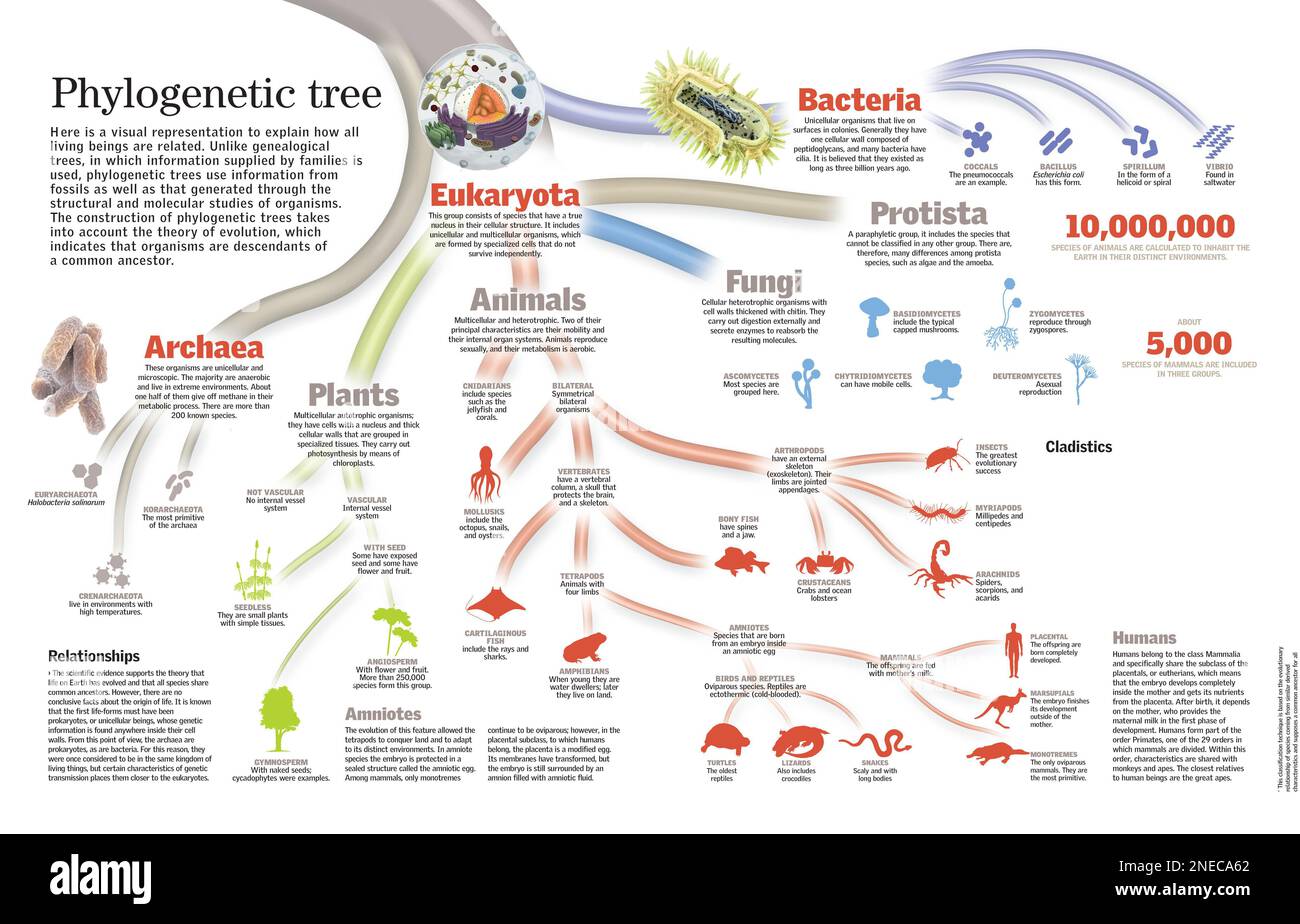
FigTree is the standard for basic tree visualization. DendroScope is better if you need publication-quality figures with annotations. I also use ggtree in R when I need to merge tree data with other metadata like geographic origin or host species. It has a learning curve but it's worth it if you do this regularly. Export your tree in Newick format. Make sure you label your nodes with bootstrap values or posterior probabilities if your software supports it. An unlabeled tree is basically useless to anyone who isn't you, and even you won't remember what it means six months from now.
The Limits of What You Can Trust
Phylogenetic trees have real limitations. They are hypotheses, not facts. The resolution drops sharply as you go deeper in time. For recent divergences, you'll get clean supported nodes. For ancient radiations or groups with incomplete lineage sorting, your tree is going to be messy no matter what you do. There's no workaround for that except adding more loci and accepting that some relationships will remain unresolved. Horizontal gene transfer also wrecks single-gene trees in prokaryotes. If you're working with bacteria or archaea, a single marker like 16S rRNA might give you a tree that looks fine but tells you nothing about the organism's actual evolutionary history. Use concatenated marker sets or whole-genome approaches instead. Tools like Roary for pangenomes or OrthoFinder for orthogroup inference are useful starting points. And saturation is a real problem. If your sequences are too divergent, multiple substitutions at the same site erase the phylogenetic signal. You won't know this just by looking at the tree. Check for saturation plots - plot transitions and transversions against genetic distance. When both curves plateau, you've hit the limit of what your data can tell you. Switching to amino acid sequences or using codon models sometimes helps, but often the answer is just to narrow your taxon sampling to include closer relatives.
I keep a record of every parameter I use, every model selected, and every alignment version. Not because reviewers require it, but because I always come back to an old project months later and have no idea what I actually did. That habit alone has saved me more than once.