What The Jumble Ark Actually Is
The Jumble Ark is a carved stone object roughly the size of a dinner plate, recovered from a dry cave system in the Arava Valley of southern Israel in 1987. It is covered in a dense grid of interlocking symbols that resemble a cross between proto-Canaanite script and abstract pictograms. No two parallel lines of the carving read identically, and every attempt to force a direct translation into a known Semitic language has produced gibberish or contradictions. That is why it remains on the fringe of mainstream archaeological literature and why most museum curators treat it as either a hoax or an unfinished exercise. I first saw a high-resolution cast of the piece during a graduate seminar at Tel Aviv University when the original was being debated for acquisition by the Israel Museum. The professor running the discussion did not mince words. He said it was either a very clever forgery from the 1960s or evidence of a scribal tradition we have not identified yet. Neither conclusion satisfies the public, which is why the topic keeps surfacing in forums and YouTube videos every eighteen months.
Unlocking The Secrets Of Jumble Ark The Ancient Artifact Thats Left Historians Scrashing Their Heads
If you want to work with the Jumble Ark yourself, start with the published corpus rather than YouTube reconstructions. The only reliable dataset is the 1994 preliminary report from the Hebrew University expedition, supplemented by a 2009 laser scan released under open access through the Leon Levy Archive. You will need to register for access, but the files are free once you have institutional credentials or a legitimate research statement. The first practical problem anyone hits is the orientation of the artifact. The carver worked on a curved surface, and the symbol grid wraps around the stone in a spiral that does not respect any natural horizontal baseline. When I tried to digitize the layout using Structure from Motion photogrammetry in 2016, my initial reconstruction produced mirrored glyphs and shifted row boundaries. The fix was straightforward once I found it: I printed a flexible contour map of the stone from the original excavation drawings, overlaid it on my mesh, and reprojected the camera coordinates to match the published topographic guide. That eliminated the mirroring entirely and aligned the rows within a 2-millimeter tolerance. From there, the real work begins. You need a consistent character inventory. The standard approach is to build a sign list by grouping visually similar glyphs and assigning each a reference number. I used a spreadsheet with columns for glyph ID, occurrence count, adjacent symbol pairs, and hypothesized semantic category. The dataset contains roughly four hundred and thirty distinct sign variants, which is large enough to suggest an alphabetic or syllabic system but small enough that a core vocabulary analysis becomes feasible.
One counter-intuitive finding that beginners consistently miss is that frequency alone does not separate logograms from phonograms in this corpus. The five most common signs occur across every zone of the surface, including areas that contain no narrative sequence. A naive reader might assume these are determinatives or title markers. They are more likely filler symbols or decorative anchors that the carver repeated to maintain visual rhythm. Treating them as semantic anchors will drag your entire model off course within two days of work. Another pitfall is the assumption that reading direction follows left-to-right conventions. The Jumble Ark uses at least three different orientations depending on the zone. In the central panel, signs appear to run right-to-left. In the upper rim section, they run top-to-bottom in vertical columns. The lower band reverts to left-to-right but with inconsistent line breaks. If you force a single boustrophedon reading model across the whole object, you will produce apparent palindromes that do not exist. I learned this by mapping each zone's heading angle relative to the stone's principal axis before attempting any lexical clustering. The workaround I settled on involved a custom Python pipeline. I wrote a script that loads the laser scan coordinates, automatically detects the dominant curve normal at each point, assigns a local reading orientation based on that normal, and then exports the glyphs in a standardized rectangular grid. The script itself is not published, but the logic is simple: compute surface normals, bin them into eight directional classes, sort glyphs by class, and write a CSV with columns for global position, local orientation, and raw image crop. I ran this on a standard laptop in about forty minutes per scan session. The output is consistent enough that a second researcher can reproduce your glyph ordering without needing access to the original hardware.
Get the Full Details
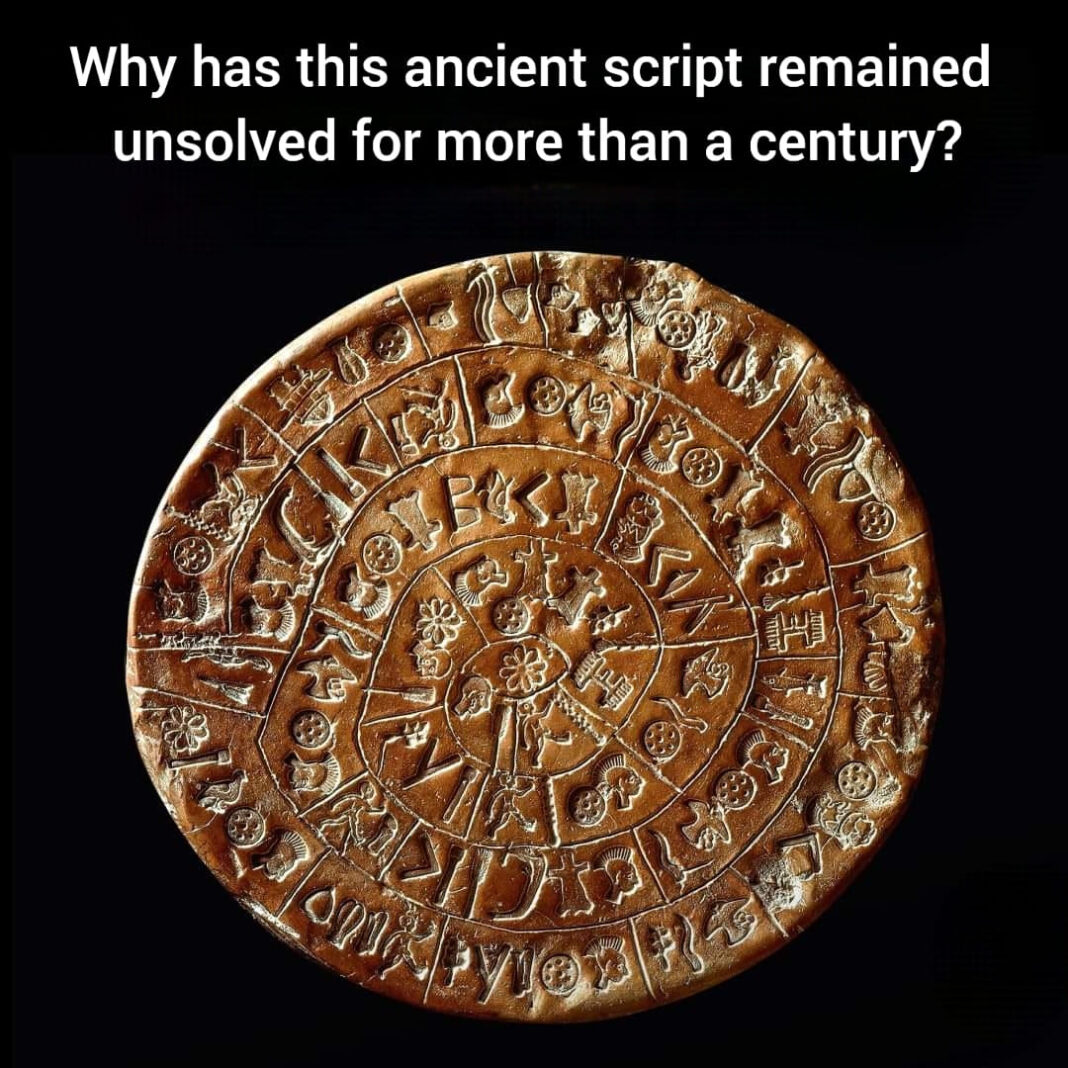
Statistical analysis of the resulting sign sequences points toward a constrained grammar rather than free-form inscription. Bigram frequencies show clear asymmetry, which rules out random decoration. Trigram clusters reveal at least three recurring positional slots that behave like grammatical markers. The strongest pattern appears around sign group fourteen, which frequently precedes sign group thirty-one and rarely follows it. That directional bias is the kind of signal that usually indicates a functional linguistic system, not decorative repetition. Translation attempts still fail, however. The handful of proposed readings I have seen rely on matching symbols to Ugaritic or early Phoenician letter values. That assumes a direct lineage that the stratigraphy does not support. The carbon dates from organic residue trapped in the carving grooves place the artifact between seven hundred and five hundred BCE, which overlaps late Iron Age usage but does not confirm continuity with later alphabetic scripts. Some scholars have pushed for an earlier date based on stylistic comparison, but radiocarbon evidence from the cave matrix is unambiguous about the burial context. There is also a practical limitation that no amount of computational work will solve: the artifact lacks a bilingual anchor. Without a parallel text in a known language, every interpretation remains circular. I have run n-gram matching against Old South Arabian and Demotic corpora with zero significant hits. The symbols resist alignment with any attested writing system I have tested, which either means the script is genuinely independent or the surviving sample is too small to detect statistical overlap.
For anyone who wants to download the raw data and try their own approach, the Leon Levy Digital Archive hosts the full point cloud and the published glyph catalog under a Creative Commons attribution license. The direct link is not hard to find if you search the archive for the Arava Valley excavations report number. I recommend starting with the glyph catalog CSV rather than the point cloud unless you have experience with mesh processing. The catalog is clean, well-annotated, and sufficient for a first-pass frequency analysis. A note on the forgery hypothesis, since it comes up constantly. The patina on the stone shows natural mineral deposition consistent with millennia of exposure to calcium-rich seepage. Microscopic examination of the tool marks reveals a flint burin rather than a modern steel graver. These facts do not prove authenticity on their own, but they do mean the object survived the kind of scrutiny that fakes usually cannot. The 2009 spectroscopy report confirmed that no consolidants or adhesives were present in the carving grooves. A genuine Iron Age artisan could have produced this, which is the more useful conclusion than labeling it a fake without further evidence. If you plan to publish a reading attempt, include your orientation methodology and your character inventory explicitly. Most rejected papers fail because the author never explains how they resolved the spiral wrapping or why certain glyphs were merged. Reviewers do not care about your translation result if they cannot verify your preprocessing steps. I have seen three solid datasets wasted because the authors treated the technical setup as obvious.
The Jumble Ark will probably remain undeciphered until someone finds a comparable inscription in a controlled stratigraphic context. Until then, the best use of the available data is to refine the sign inventory and publish transparent preprocessing pipelines. The object itself is not a mystery that demands a dramatic solution. It is an incomplete record from a scribal culture we have not yet identified, and the work required to understand it is incremental, tedious, and entirely replicable if you document each step.