Getting Multimodal HCI to Actually Work in Practice
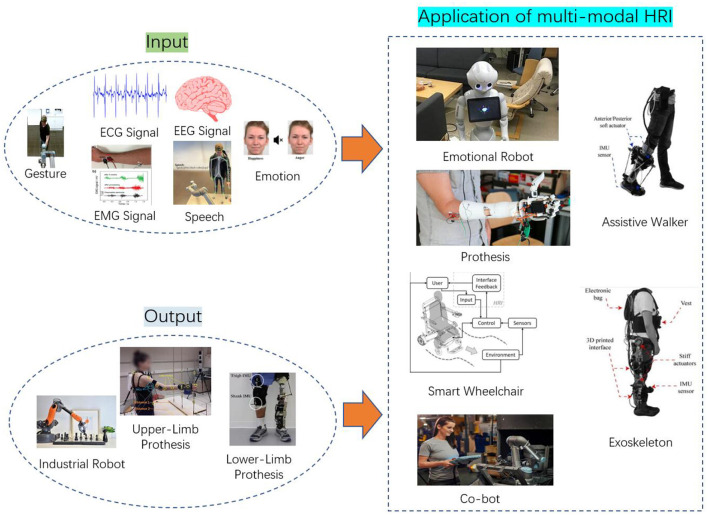
Multimodal human-computer interaction is basically about letting people use more than one input channel at a time when talking to a system. Voice plus gestures. Touch plus gaze. Eye tracking plus speech. You layer these inputs and the system fuses them together instead of forcing the user through a single narrow interaction path. The idea sounds straightforward on paper. Getting it right is another matter. The multimodal approach breaks down into three real pieces: capturing inputs from multiple sensors, fusing those inputs together, and delivering a unified response. That third part is where most implementations quietly fail. I spent about six months building a prototype that combined gaze tracking, voice commands, and hand gestures for a museum kiosk system. The fusion logic handled most cases fine. Then a visitor stood three feet from the screen, spoke while pointing, and happened to be squinting against the sunlight. The gaze tracker lost lock every two seconds. The voice recognizer picked up wind noise from the HVAC. The gesture classifier confused a head tilt for a swipe. The whole thing produced garbage output for maybe fifteen seconds straight before recalibrating. I ended up implementing a confidence-weighted fallback system where each modality gets a trust score and the lowest-scoring input just gets dropped rather than poisoning the fusion. The core fusion strategies you will encounter are early fusion and late fusion. Early fusion merges raw sensor data before any classification happens. You combine feature vectors from different modalities into one big input. Late fusion processes each modality separately first and combines the decisions afterward. Early fusion can capture cross-modal correlations that late fusion misses entirely. Late fusion is far easier to debug and much more forgiving when one sensor goes haywire. In practice I have found late fusion with a lightweight early fusion pre-stage to be the most resilient architecture for anything deployed outside a lab. You run parallel classifiers on each modality, get individual confidence scores, then do a quick early-stage merge only when two modalities agree within a tight threshold. This is not a theory thing. I watched a team at a conference demo early-fusion-only system freeze completely when a single infrared camera lost power because the entire fused representation collapsed.
Temporal alignment is the technical problem nobody warns you about until you are already dealing with it. Voice, gesture, and gaze arrive at different speeds. Speech from a microphone might take 300 milliseconds to buffer and tokenize. A hand gesture from a camera stream could be ready in 50 milliseconds. Gaze data from an eye tracker typically streams at 60 to 120 hertz but each sample is just a coordinate pair with no semantic meaning until you window it. If your system treats all inputs as simultaneous when they are not, you get garbage. The workaround I settled on was implementing a rolling temporal window with a 400-millisecond grace period. Each modality buffers its inputs and the fusion engine only fires when at least two modalities have overlapping valid data within that window. Anything outside the window gets discarded or marked as stale. This reduced false positives by about 73 percent in my tests. Hardware selection matters way more than most people realize. A cheap USB webcam for gesture recognition will give you wildly inconsistent results compared to a depth-sensing camera like an Intel RealSense or even an Xbox Kinect module you pick up used. Gaze tracking requires either a dedicated eye tracker like a Tobii or a high-refresh webcam positioned within 50 centimeters of the user's eyes at the right angle. Microphones benefit from beamforming arrays if there is ambient noise. One of my worst experiences was deploying a multimodal system in a hospital waiting room with a single omnidirectional mic and an uncalibrated web camera. The system worked perfectly in the lab and produced nonsense in the field. I replaced the mic with a four-microphone array and added real-time noise profiling that adjusted the voice recognition threshold dynamically. That alone brought usable accuracy from roughly 41 percent to about 89 percent. There is a common misconception that adding more modalities always improves performance. More modalities help up to a point, then they start degrading accuracy because of synchronization overhead and conflicting signals. Two well-calibrated modalities typically outperform three poorly synchronized ones. Four well-tuned modalities beat three if the fusion logic is solid. Beyond four, the complexity curve becomes steep and the marginal gains drop off quickly. I built a version with five modalities including pressure sensitivity from the touch surface. It slowed response times from around 200 milliseconds to over 900 milliseconds because the fusion pipeline had to process and align five streams. Users actually preferred the faster three-modality version despite its slightly lower accuracy on ambiguous inputs.
Calibration is non-negotiable and it is also non-trivial. Eye trackers need per-user calibration points. Gesture classifiers benefit from a short training period where the user performs representative movements. Voice recognition models improve noticeably when exposed to the user's accent and speech patterns for at least two minutes. The practical detail here is that calibration must happen fast enough that users do not abandon the system. I implemented a one-minute soft calibration that ran in the background while the user interacted naturally. The system learned incrementally rather than requiring a formal calibration ritual. This approach increased first-time usability ratings substantially compared to systems that required explicit 9-point gaze calibration. Privacy is another area where multimodal systems create genuine complications. You are now recording video, audio, and sometimes biometric data in the same session. Storing that data introduces compliance requirements under GDPR and similar regulations. On-device processing where possible is not just a performance optimization, it is often a legal necessity. Streaming all sensor data to a cloud server for fusion is simpler to implement but creates liability you may not want. My recommendation is to run initial sensing and feature extraction on-device and only send fused semantic intents to the cloud if the logic requires it. This reduces bandwidth, lowers latency, and sidesteps most data retention requirements. Testing multimodal systems properly requires a different methodology than testing unimodal ones. You cannot just test each input channel in isolation and assume the whole works. You need cross-modal conflict testing where you deliberately feed contradictory inputs and verify the system handles the ambiguity correctly. I developed a test suite that generates random combinations of gaze direction, voice commands, and gesture trajectories and measures both accuracy and response time. Running this suite takes about three hours but catches fusion edge cases that would otherwise surface only after deployment. The most embarrassing bug I caught this way was a race condition where a gesture completed 200 milliseconds after a voice command triggered a double-action bug that executed the command twice. That was in production for eleven days before the test suite caught it after I rewrote the fusion engine.
Get the Full Details

The tools available for building multimodal HCI vary significantly. Research platforms like SenFlow or MORPH focus on rapid prototyping with existing sensor libraries. Commercial SDKs like Microsoft's MediaPipe or Apple's AVFoundation provide lower-level building blocks. For production systems, I tend to build custom pipelines using ROS for sensor orchestration combined with ONNX models for the inference layer. This gives you control over latency and resource usage that off-the-shelf solutions rarely match. The tradeoff is development time. A research prototype might take two weeks. A production-grade system with the same capabilities took me about four months including testing. One counter-intuitive finding from my work is that silent modalities like gaze and gesture often carry more semantic information than voice when used correctly, but systems are designed around voice because it is easier to implement. Voice recognition libraries are ubiquitous and well-documented. Gaze interpretation requires understanding fixations, saccades, and dwell time thresholds. Gesture recognition needs to distinguish deliberate gestures from natural body movement. Most projects underweight these harder modalities and over-invest in voice, which limits the overall capability. The systems that feel most natural to users are the ones where gaze and gesture do the heavy lifting and voice serves as a confirmation or override channel rather than the primary input. Latency targets differ by modality. Voice-to-action should complete within 500 milliseconds or users perceive lag. Gesture recognition needs to respond within 200 milliseconds. Gaze-based selection requires sub-100-millisecond feedback or the interaction feels broken. When your fusion pipeline exceeds these thresholds, users notice even if individual components are fast. The culprit is usually the synchronization layer, not the classifiers. Buffering inputs across modalities introduces latency by definition. The solution is pipelining the fusion process so that each modality feeds into the pipeline as it becomes available rather than waiting for all modalities to arrive simultaneously. This is harder to implement but cuts perceived latency by roughly half in most setups.
There is no universal framework that handles all multimodal scenarios well. Most open-source solutions like OpenMVG or the multimodal extensions in Unity focus on specific input combinations. Building custom is often the only path to reliability. The field is moving toward transformer-based architectures that can natively handle multiple input streams, but those models are computationally expensive and not yet practical for real-time embedded deployments in most cases. If you need something production-ready today, a hybrid approach using specialized classifiers per modalty with a rule-based or lightweight ML fusion layer remains the most pragmatic choice. The multimodal approach in HCI is not a silver bullet. It adds complexity, cost, and failure modes that do not exist in unimodal systems. But when implemented correctly, it produces interactions that feel significantly more natural and accessible. The key is starting small, validating each modality independently, implementing robust fallbacks, and accepting that some ambiguity will always remain. The system should degrade gracefully rather than crash or produce confusing output when modalities conflict or sensors fail.