Understanding Human Settlements: Density vs Distribution
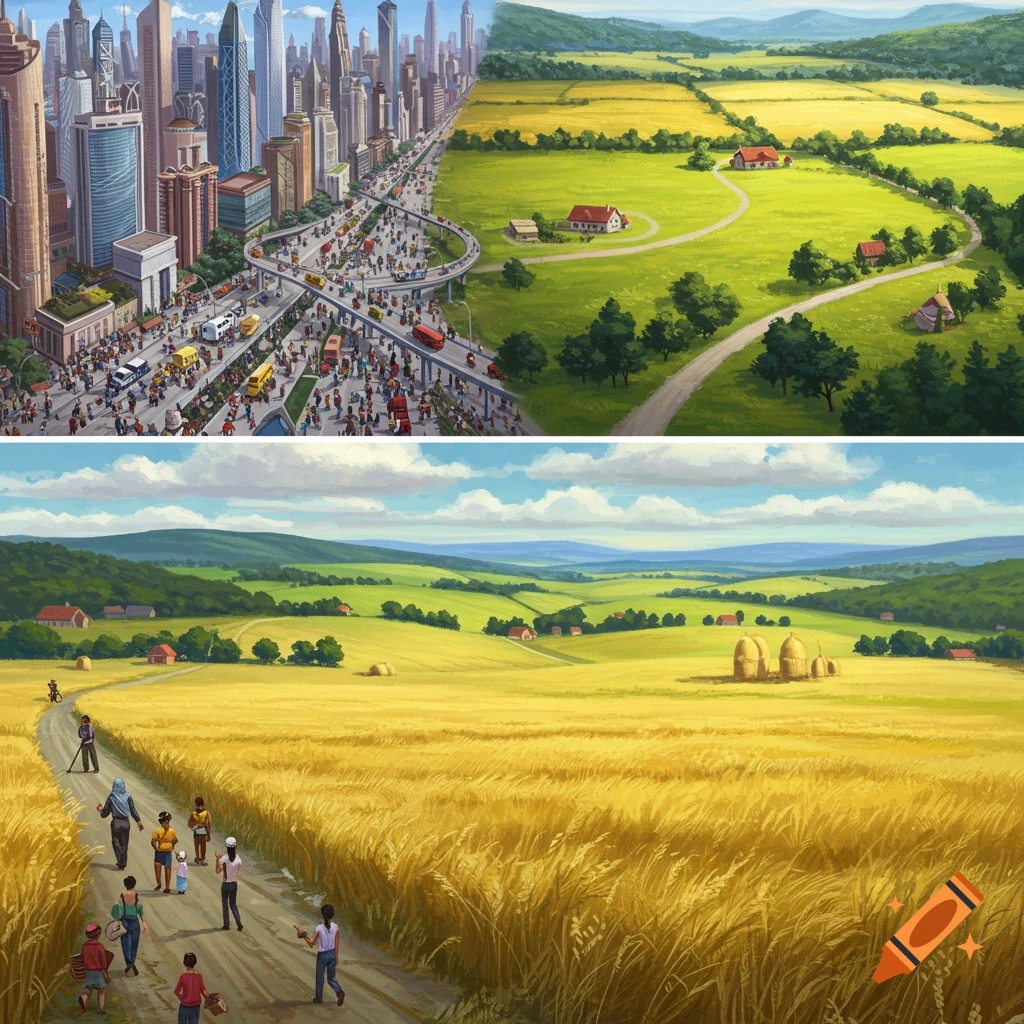
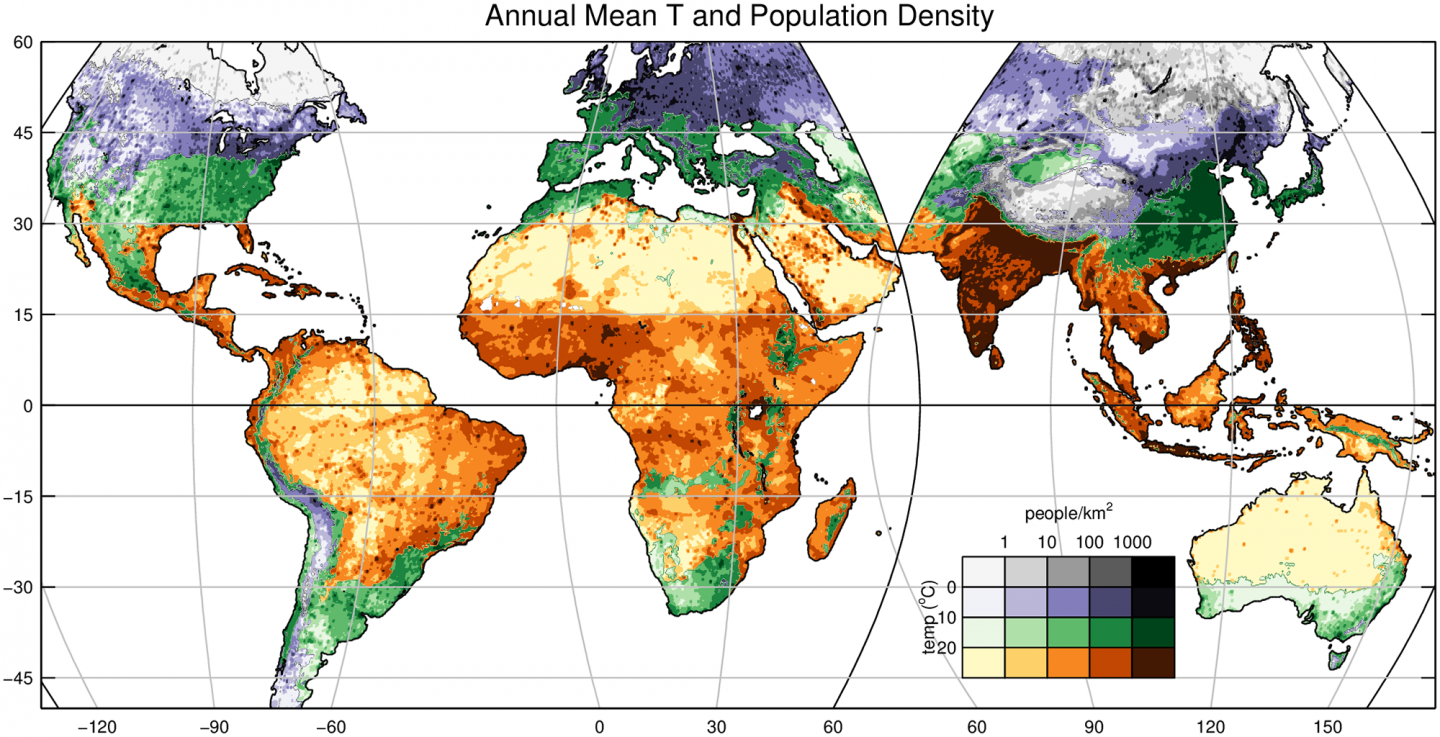
Population density and population distribution get confused constantly. They sound similar but describe completely different things, and mixing them up leads to bad analysis. I have seen entire planning reports derailed by people who used one when they meant the other. The difference matters more than most beginners realize. Population density is a ratio. It tells you how many people occupy a unit of area. You calculate it by dividing total population by land area. The result is usually expressed as people per square kilometer or per square mile. Simple enough. But here is where people stumble. Arithmetic mean density uses total area including water, forests, and unusable land. That number can be misleading for places like Dubai, where the actual built-up density is staggering compared to the overall figure. Population distribution describes how people are spread across a landscape. It is not a single number. It is a pattern. Are people clustered in cities and empty elsewhere? Are they spread evenly? Is there a linear pattern along a river or coastline? Distribution requires maps and spatial analysis, not just a calculator.
The Practical Difference
I once worked on a housing feasibility study for a mid-sized city. The preliminary data showed a low population density, which suggested plenty of room for expansion. We pushed forward with the analysis, confident we had room to grow. Then we pulled the distribution maps and found that ninety percent of residents were concentrated in a narrow corridor along the main transportation route. The rest of the municipality was largely empty agricultural land. Expanding outward from the existing corridor made sense. Sprawling in any direction was a non-starter. The density number alone would have pointed us toward the wrong answer. Distribution corrected the course. That is the practical gap between these two concepts. Density answers the question of how crowded a place is on average. Distribution answers the question of where those people actually are. One compresses everything into a statistic. The other reveals the geometry of human settlement.
How to Analyze Both Without Making Common Mistakes
Start by deciding which metric matters for your objective. If you are evaluating infrastructure demand like water or sewage capacity, density is your starting point. If you are planning service locations or transportation networks, distribution is more relevant. Using the wrong one wastes time and produces irrelevant results. When calculating density, choose the right denominator. Use built-up area instead of total administrative area if you want to understand actual crowding. I use the Global Human Settlement Layer data from the European Commission for this because it filters out non-settlement land automatically. It saves hours compared to manually masking out forests and water bodies from raw census boundaries. For distribution analysis, census tract or block-level data is ideal. Zip codes and postal codes are garbage for this purpose. They follow mail delivery routes, not human settlement patterns. Block groups or enumeration districts are significantly better if they are available in your region. If you only have coarse regional data, be honest about the limitation. Don't pretend your distribution analysis is more precise than it actually is.
Get the Full Details

Visualize distribution using heat maps or kernel density surfaces. Raw point data on a map is harder to read. Heat maps make patterns obvious quickly. I usually export my data to QGIS and run the Kernel Density Estimation tool. It takes about three minutes on a standard dataset and produces a clear visualization in under five minutes total.
Edge Cases That Trip People Up
Seasonal populations are a real headache. Tourist destinations like coastal towns or ski resorts can have density figures that fluctuate by a factor of ten between peak and off-peak seasons. An annual average smooths this out and hides the reality. When I encountered this with a Mediterranean municipality, I pulled monthly visitor statistics from the local tourism board and adjusted the density calculations seasonally. The infrastructure planning completely changed once we accounted for summer peaks. Another issue is administrative boundary changes. Cities absorb surrounding rural areas all the time. The population stays roughly the same but the area increases, so density drops artificially. Always check the boundary history before comparing density figures across years. A sudden drop in density is often just a boundary revision, not an actual depopulation trend.
When These Methods Fail
Neither density nor distribution analysis works well in informal settlements. Places like favelas or densely packed refugee camps often lack official census data, and the buildings are so tightly packed that standard area measurements break down. In those situations, satellite imagery and nighttime lights data provide better input. I have used Sentinel-2 imagery combined with building footprint detection to estimate settlement patterns where traditional data simply did not exist. It is not perfect but it is better than pretending the data gap does not matter. Also, density numbers can mask extreme inequality within a small area. Two neighborhoods might share the same average density while one is comfortable and the other is critically overcrowded. Distribution at a fine grain level exposes that. Always drill down to the smallest reliable geographic unit available.
What Actually Moves the Needle
The most useful insight I have picked up is that density and distribution interact. High density in a dispersed pattern creates different problems than high density in a concentrated pattern. Sprawl with moderate density often produces worse transportation outcomes than compact high density. Yet planners sometimes treat density as an absolute good without considering whether it is clustered or scattered. The combination matters more than either metric alone. If you are starting from scratch, pull census microdata, calculate arithmetic and loaded density, map the distribution pattern, and check for seasonal or boundary effects. That process typically takes me about forty-five minutes for a standard metropolitan area. The output gives you a far clearer picture than either metric would on its own.