Monitoring Your OSCP Lab With Grafana And InfluxDB
I spent three weeks trying to keep track of my home lab during OSCP study. I had six Kali instances, a dozen target VMs, Metasploit sessions bouncing around, and no idea what was actually happening at any given moment. I kept missing things. I ran a scan so quietly that my own tools logged nothing useful, and by the time I realized what happened I had to rebuild the entire test. The solution was simpler than you might expect. Grafana for the visual layer, InfluxDB as the time-series backend, and a few custom queries to track what matters during pentest study. This isn't about enterprise-grade observability. It's about knowing when your lab explodes so you can fix it and move on.
Unlocking The Secrets Of Grafana Alerting With Influxdb For Oscp Prep
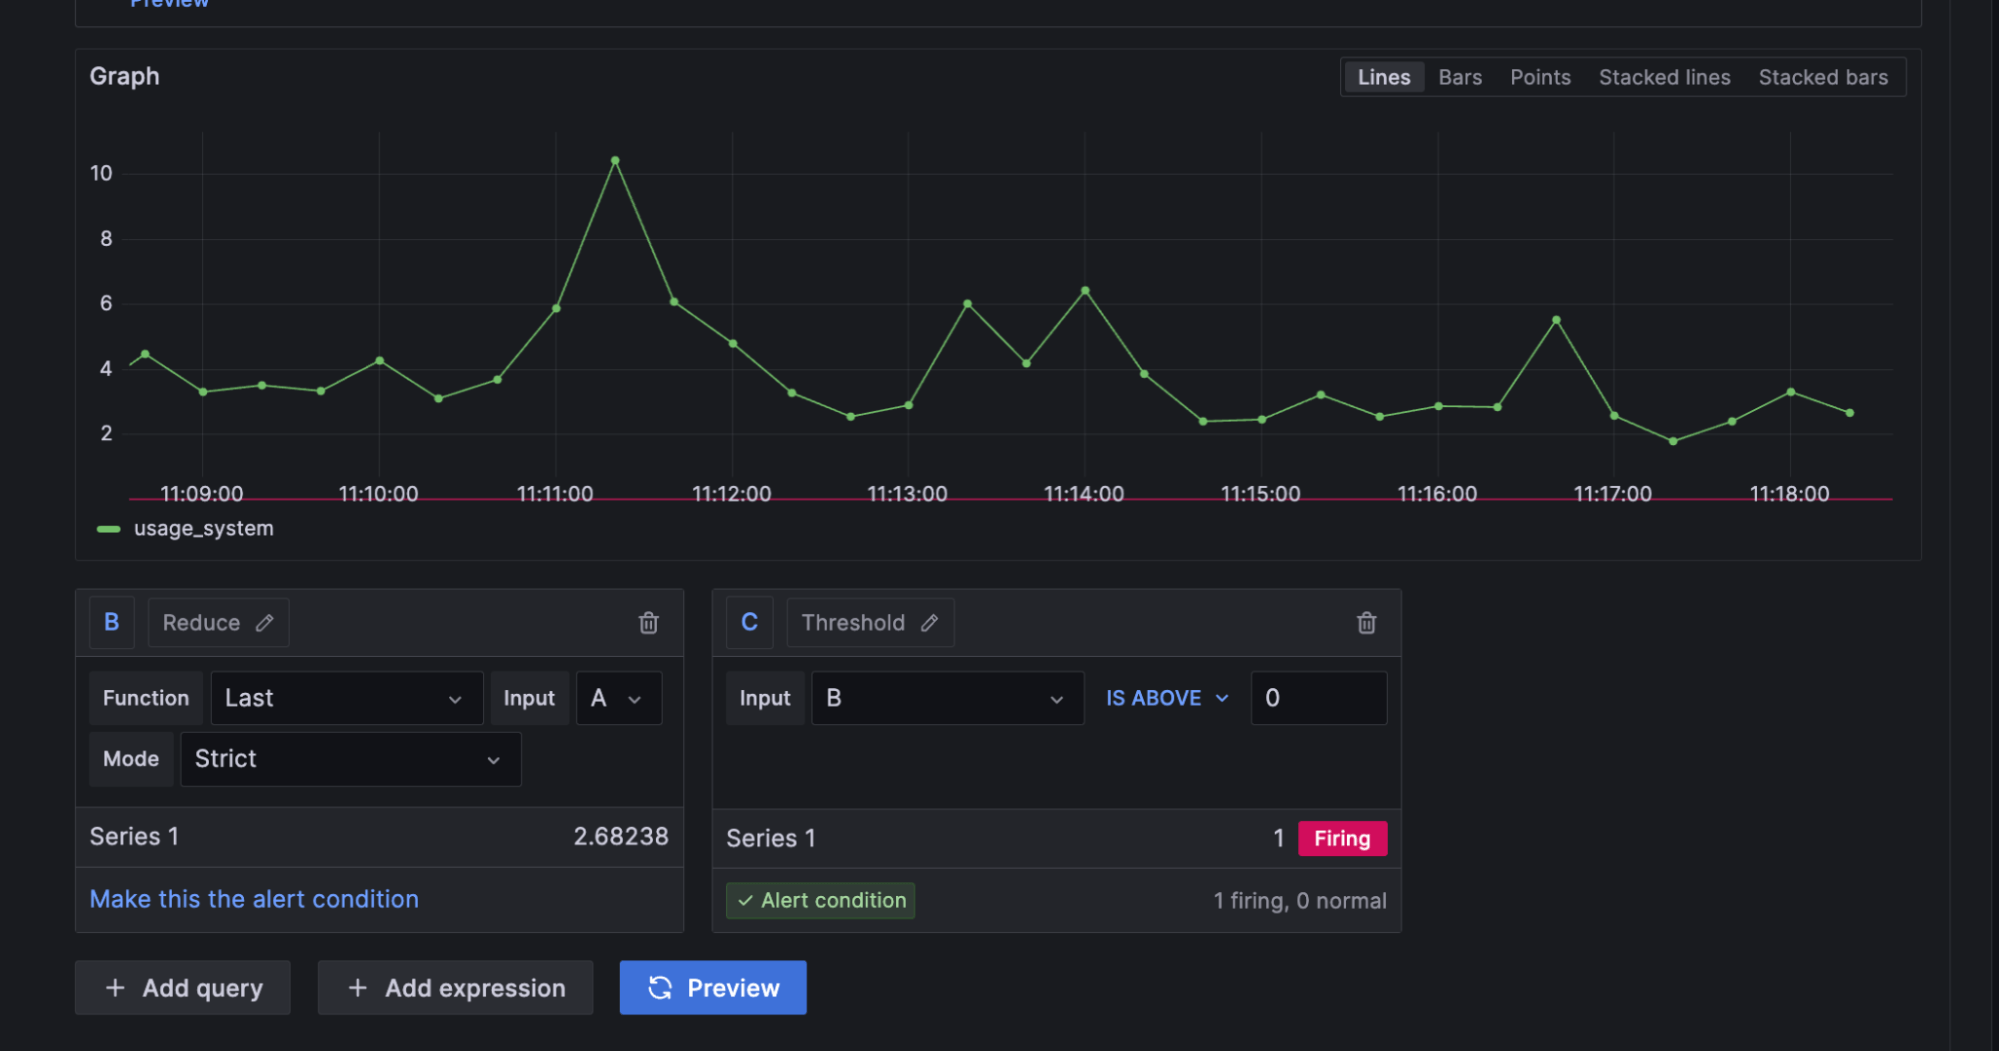
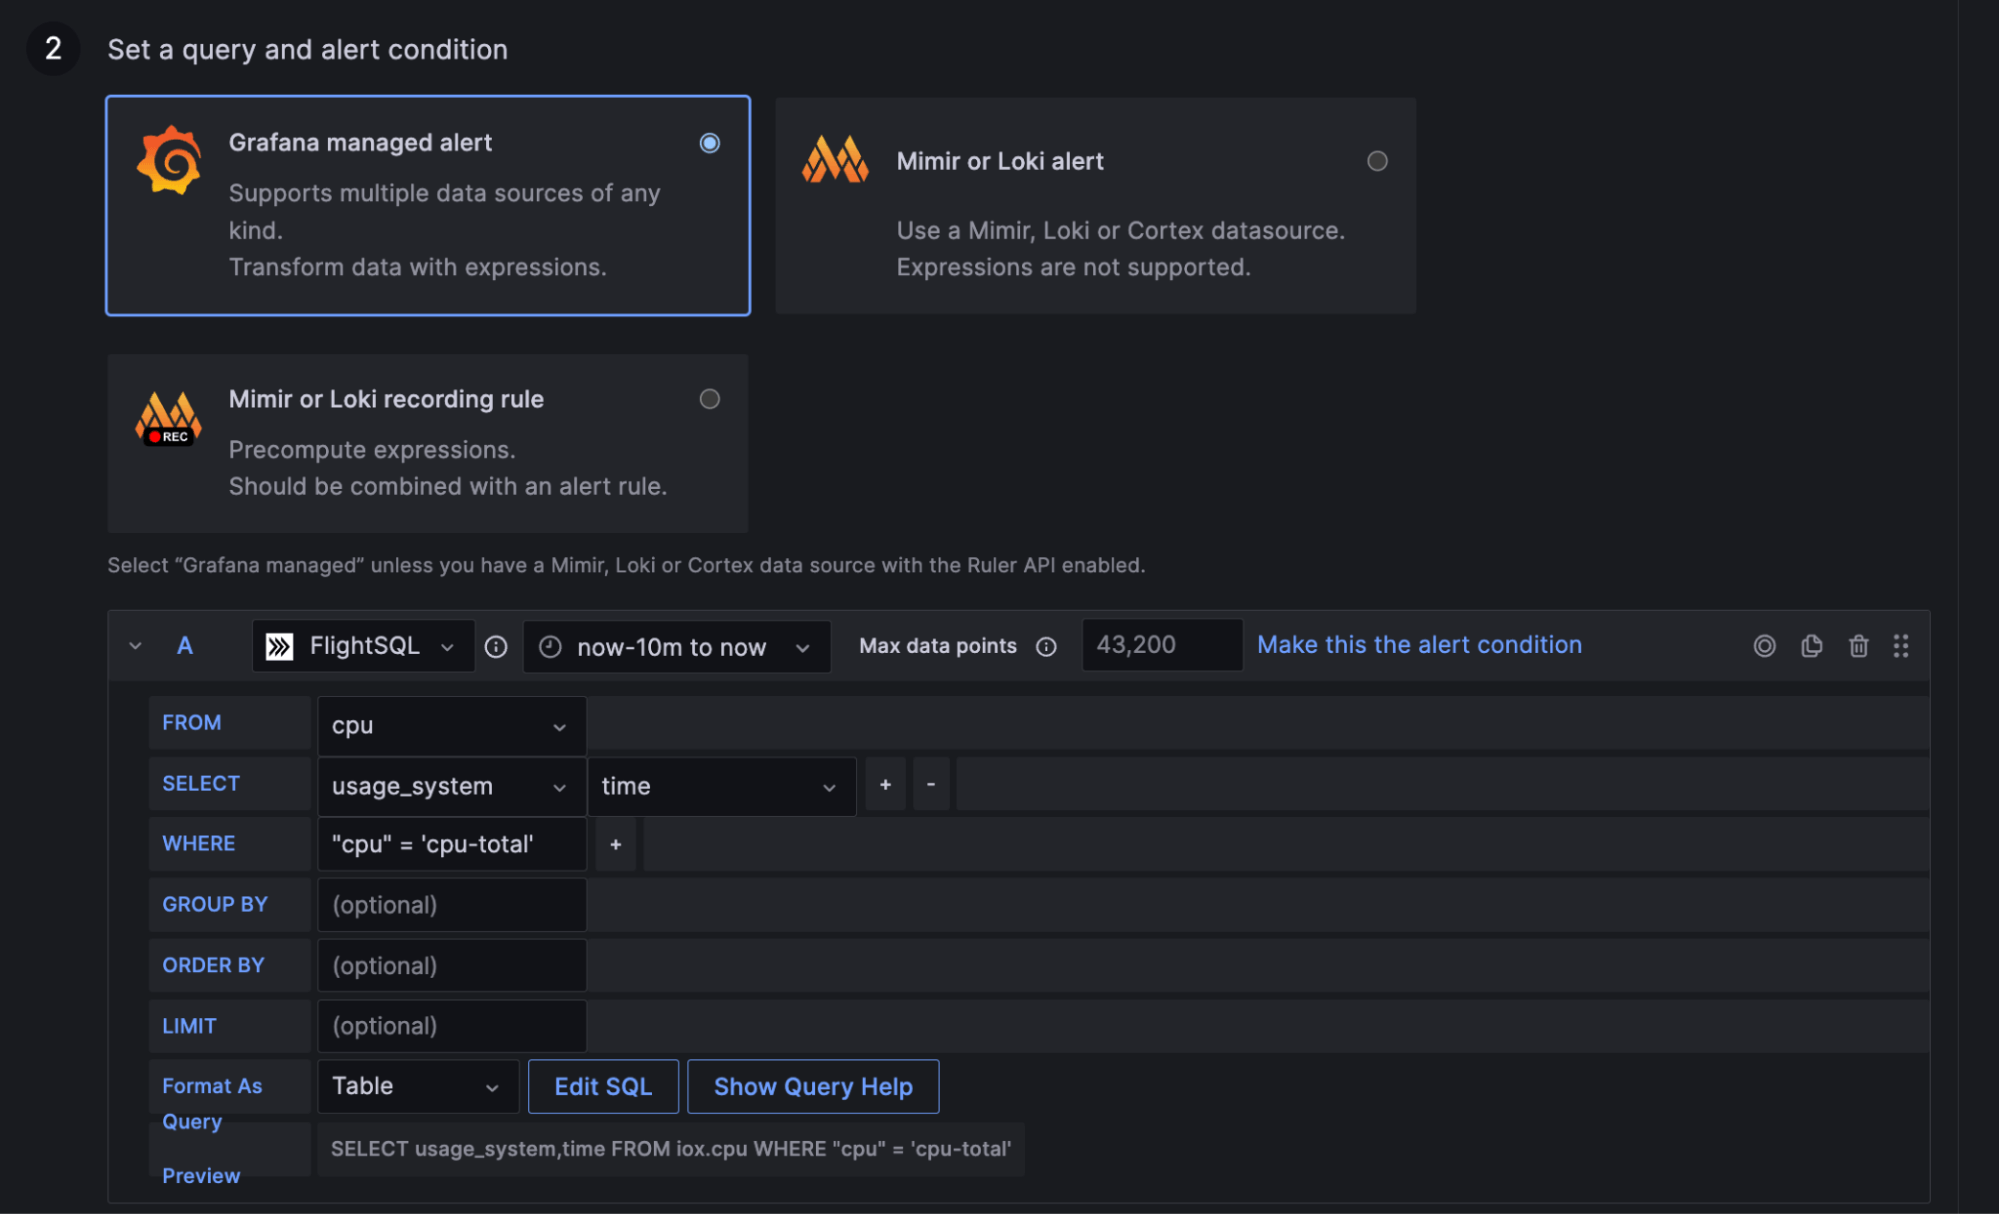
First, the stack. InfluxDB 2.x handles the data ingestion. Grafana talks to it over HTTP. You write your metrics into Influx, then build queries that answer questions like "how many processes did this VM spawn in the last five minutes" or "did the target machine's listening ports change." The OSSEC agent, Telegraf, or even a simple Python script can push data to Influx. I prefer a lightweight Python helper that dumps process tables and open sockets every thirty seconds. For alerting, Grafana's notification pipeline is what matters. You create a datasource pointing at Influx, write a Flux query, set a threshold condition, and wire it to an alert rule. That rule can push to Discord, Telegram, email, or a webhook that triggers a script on your Kali box. The script part is where most people skip the details and end up with useless alerts. I learned this the hard way. My first alert fired because Influx couldn't connect to Grafana for forty-five seconds due to a network blip, and the alert rule was configured to fire on "data not found." I got three hundred notification spam messages before I realized what was happening. The fix was adding a "no data" action to the alert configuration and wrapping the query in a condition that ignores gaps shorter than ten minutes. That alone cut noise from hundreds of false positives down to maybe two per study session.
Here is the actual setup that works. Install InfluxDB 2.x and create a bucket called lab-metrics. Install Telegraf or run a small Python script that pushes metrics every fifteen seconds. The metric I found most useful is a simple counter for listening ports on each target VM. Query it like this: from(bucket: "lab-metrics") |> range(start: -5m) |> filter(fn: (r) => r._measurement == "listening_ports") |> group(columns: ["host"]) |> last() This shows you the current port count per host. If a target's port count jumps from three to twelve in under a minute, that's likely a service vulnerability exploit in progress. Set the alert threshold to trigger when the difference between the last two samples exceeds five new ports within the window.
Get the Full Details
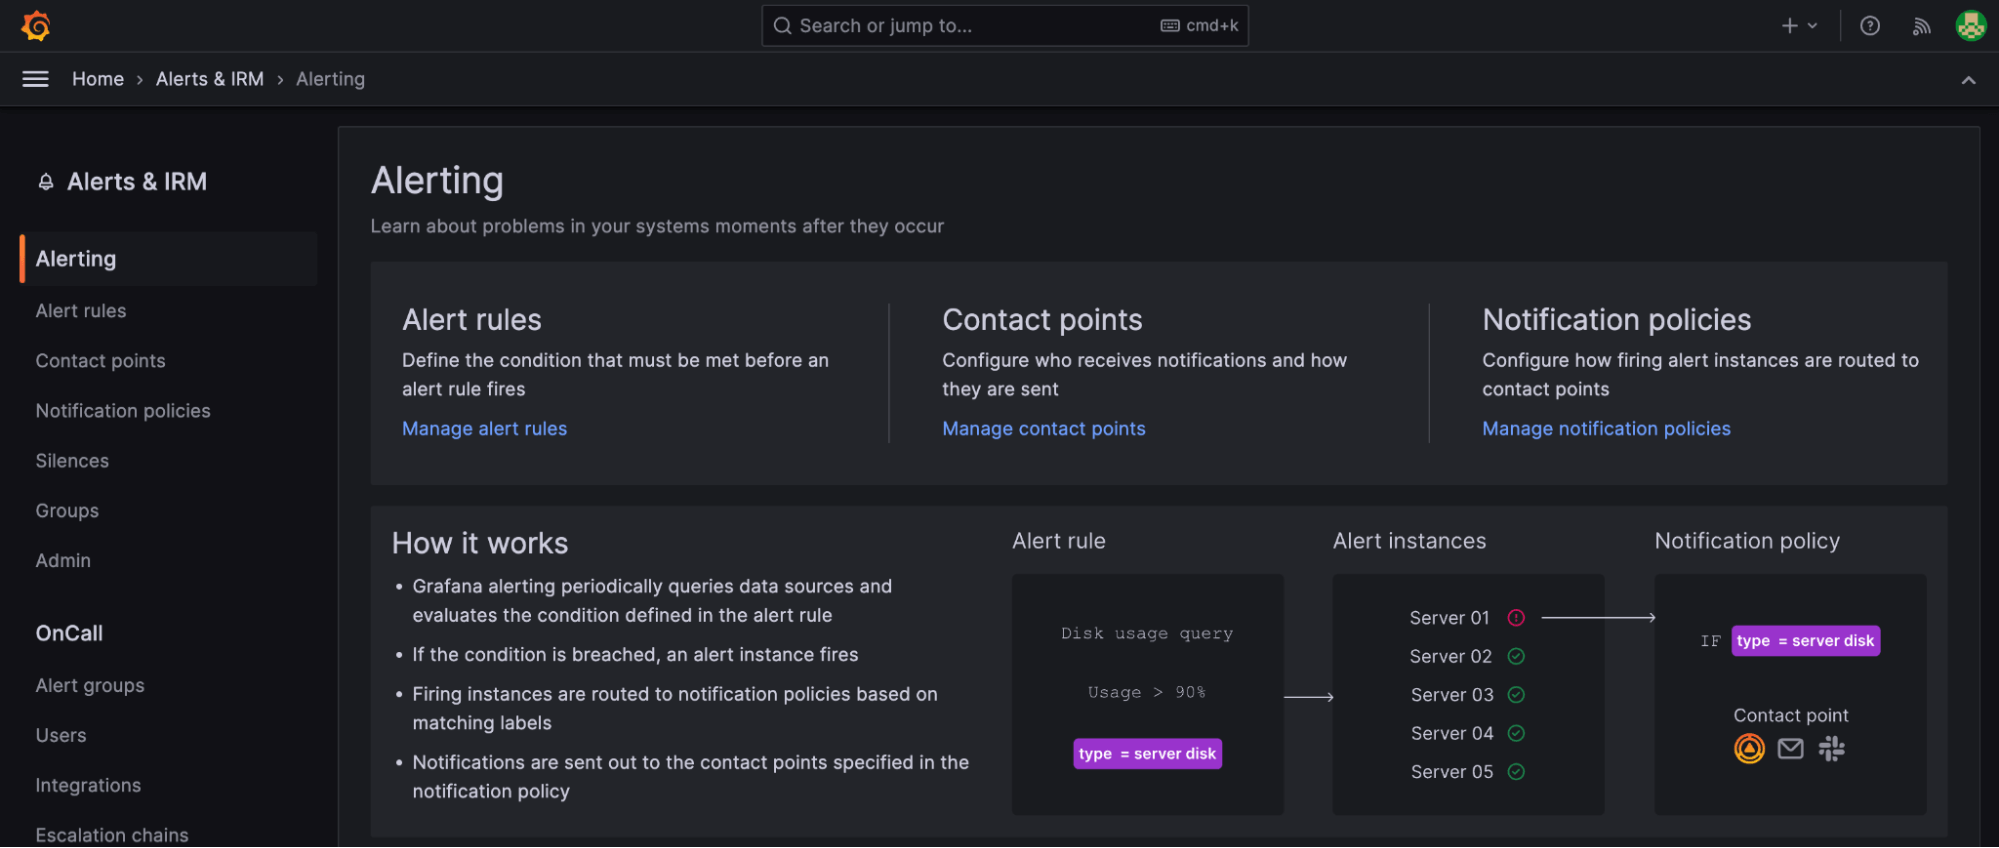
Another thing beginners miss: InfluxDB's retention policies matter more than you think during OSCP prep. If you're storing process-level metrics for a month, your disk fills up fast. I set my retention to seven days with hourly aggregation. The raw data disappears after a week, but the aggregated view stays longer. This keeps the database under two gigabytes even after heavy lab usage and cuts query times significantly. Grafana queries that once took eight seconds dropped to under one second after aggregation. For the actual alert rules, I recommend starting with just four: new listening ports on targets, high CPU usage on Kali instances, failed SSH login attempts exceeding a threshold, and outbound network traffic spikes. The outbound traffic one caught me once. I was running Nmap against a network range and didn't realize how much background traffic I was generating. The alert showed me I was broadcasting more packets than my hypervisor's virtual switch could handle cleanly. Connection drops everywhere. The notification channel setup is straightforward but easy to mess up. Grafana supports webhooks natively, which is useful because you can pipe alerts into a local script that does something beyond just sending you a message. My webhook handler runs a bash script that records the alert timestamp, takes a screenshot of the active VM console if one is running, and logs everything to a file. When I wake up to an alert, I can look back at exactly what state my lab was in when the event triggered.
One edge case that trips people up: InfluxDB 2.x uses Flux instead of InfluxQL. Flux is more powerful but has a steeper learning curve, and the documentation assumes you already understand it. If you come from a SQL background, start with simple queries and work up. Don't try to write complex joins on day one. A basic filter and group by gets you 80% of what you need for lab monitoring. The Grafana dashboard itself doesn't need to be fancy. Three panels: a timeseries of port counts across all hosts, a gauge showing CPU usage per VM, and a table of the last twenty alerts with timestamps. That is all you need to see what is going on. Fancy dashboards take hours to build and rarely get used once you are deep in study mode. For the download side of things, InfluxDB 2.x installs via the official package repository. Grafana follows the same pattern. Telegraf is also available from the official repos. There is no special software required beyond what is already in their standard distribution. The Python helper I mentioned can be a single file you write yourself, or you can find community scripts online that do similar things. The exact code doesn't matter as much as understanding what data points are worth capturing for your use case.
The main limitation of this approach is that it only monitors what you explicitly instrument. If you don't push a metric, Grafana cannot alert on it. A lot of people set this up, run it for a week, then forget about it because they expected it to magically track everything. It won't. You have to decide what matters and instrument that specifically. For OSCP prep, that means focusing on port changes, process creation, and network anomalies rather than trying to monitor every possible system event. There is also the question of whether this is the best approach or just a convenient one. For someone running a small home lab on a single machine with VMware or VirtualBox, this works fine. If you are managing fifty VMs across multiple physical hosts, you might want something more robust like Prometheus with Alertmanager. But for OSCP study purposes, Grafana plus InfluxDB covers the requirement without unnecessary complexity. The real value here isn't the monitoring itself. It's the visibility. When you are trying to learn penetration testing methodology, having a system that tells you when your target reacts to your actions in real time changes how you approach each exercise. You stop guessing whether your exploit worked and start seeing the results directly. That feedback loop is what separates people who pass OSCP from those who spend months going in circles.