What You Actually Need To Know About Cladograms
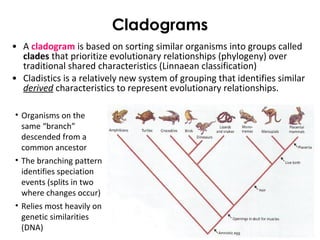
A cladogram is a branching diagram that shows hypothesized evolutionary relationships among organisms. That is the textbook definition. In practice, it is a visual tool biologists use to organize shared characteristics into a hierarchy of relatedness. The branches represent lineages, the nodes represent common ancestors, and the length of the branches does not necessarily mean anything unless specifically scaled. Most students learn this and move on without actually understanding what the thing does or how it gets built. I spent years untangling messy phylogenetic data before it clicked. Building one starts with selecting the organisms you want to compare. Then you pick traits. These can be morphological, like the presence of feathers or the number of chambers in a heart, or molecular, like DNA sequence alignments. You code these traits as characters, assigning states like 0 or 1, or sometimes multiple states for more complex features. The goal is to find which traits are shared derived characters, called synapomorphies, because those are the ones that actually matter for grouping organisms together. Once you have your character matrix set up, you run it through a parsimony analysis or a likelihood model. Parsimony means you are looking for the tree that requires the fewest evolutionary changes. It is simple and fast, which is why it remains the default in many teaching labs. But it has a well known problem called long branch attraction, where unrelated lineages that both evolved quickly get incorrectly grouped together. I wasted an entire weekend in 2014 working on a salamander phylogeny where three fast evolving species were clumping artificially because of this. The fix was switching to a maximum likelihood framework with a gamma distributed rate model and removing the most variable sites from the alignment. The resulting tree was completely different from the parsimony result.
Most people who encounter cladograms in an introductory biology course never see the actual messiness behind them. They see a clean diagram with neat branches and assume the relationships are settled facts. They are hypotheses, heavily dependent on the characters you chose and the method you used. If you add or remove a single trait, the topology can shift. I had a student once try to argue that her cladogram proved birds were closer to crocodiles than turtles based on a subset of skeletal features. She was technically right about the bird crocodile grouping, which modern systematics supports, but her tree was built with only twelve characters and no outgroup comparison. The conclusion was correct by accident. There are a few practical things you should know if you are actually working with these. First, always include an outgroup. This is a species or lineage that is closely related to your study group but falls outside it. It roots the tree and lets you determine which traits are ancestral versus derived. Without an outgroup, you are just building an unrooted network and cannot tell directionality. Second, be careful about circular reasoning when selecting characters. If you pick traits based on an assumption about relationships and then use those same traits to prove the relationships, you have proven nothing. Third, understand that cladistics and phenetics are different approaches. Phenetics groups by overall similarity, which sounds intuitive but conflates ancestral similarities with derived ones. Cladistics deliberately avoids this by focusing only on shared derived traits. Software for constructing cladograms ranges from accessible to punishing. Mesquite is free and powerful but has a steep learning curve. PAUP is the classic option for parsimony analysis. For maximum likelihood and Bayesian inference, MrBayes and BEAST are standard tools, though BEAST is primarily built for dated phylogenies rather than simple cladograms. If you are doing this by hand, which some instructors still require, you will build a character matrix, calculate the number of steps for each possible tree, and pick the shortest one. The number of possible trees grows factorially with the number of taxa, so even ten species gives you more trees than you could reasonably evaluate without computational help. Ten species produces over two hundred million possible rooted trees under parsimony.
The biggest limitation of cladograms is that they do not convey everything you might want to know. They show topology, not time, unless specifically calibrated with fossils or molecular clocks. They do not show horizontal gene transfer, which is rampant in bacteria and archaea and essentially breaks the tree metaphor entirely. They also do not account for incomplete lineage sorting, which frequently causes gene trees to disagree with species trees in rapidly radiating groups. I spent months trying to reconcile conflicting signals in a cichlid fish radiation from East Africa, and the final analysis required combining multiple independent loci and explicitly modeling gene tree discordance. A single cladogram cannot capture that complexity. If you want to build your own cladogram for a class project or personal interest, start small. Pick five to ten species with well documented traits, probably vertebrates since the morphology is intuitive. Download a curated character matrix from a published paper rather than making up your own traits. Use a free online tool or Mesquite to run a parsimony analysis. Compare the resulting tree to what is already published. You will quickly see where your character choices and method matter, and that is the actual point of the exercise. The diagram is just a representation of a hypothesis, and the value is in understanding how that hypothesis was constructed and where it might be wrong.
Get the Full Details