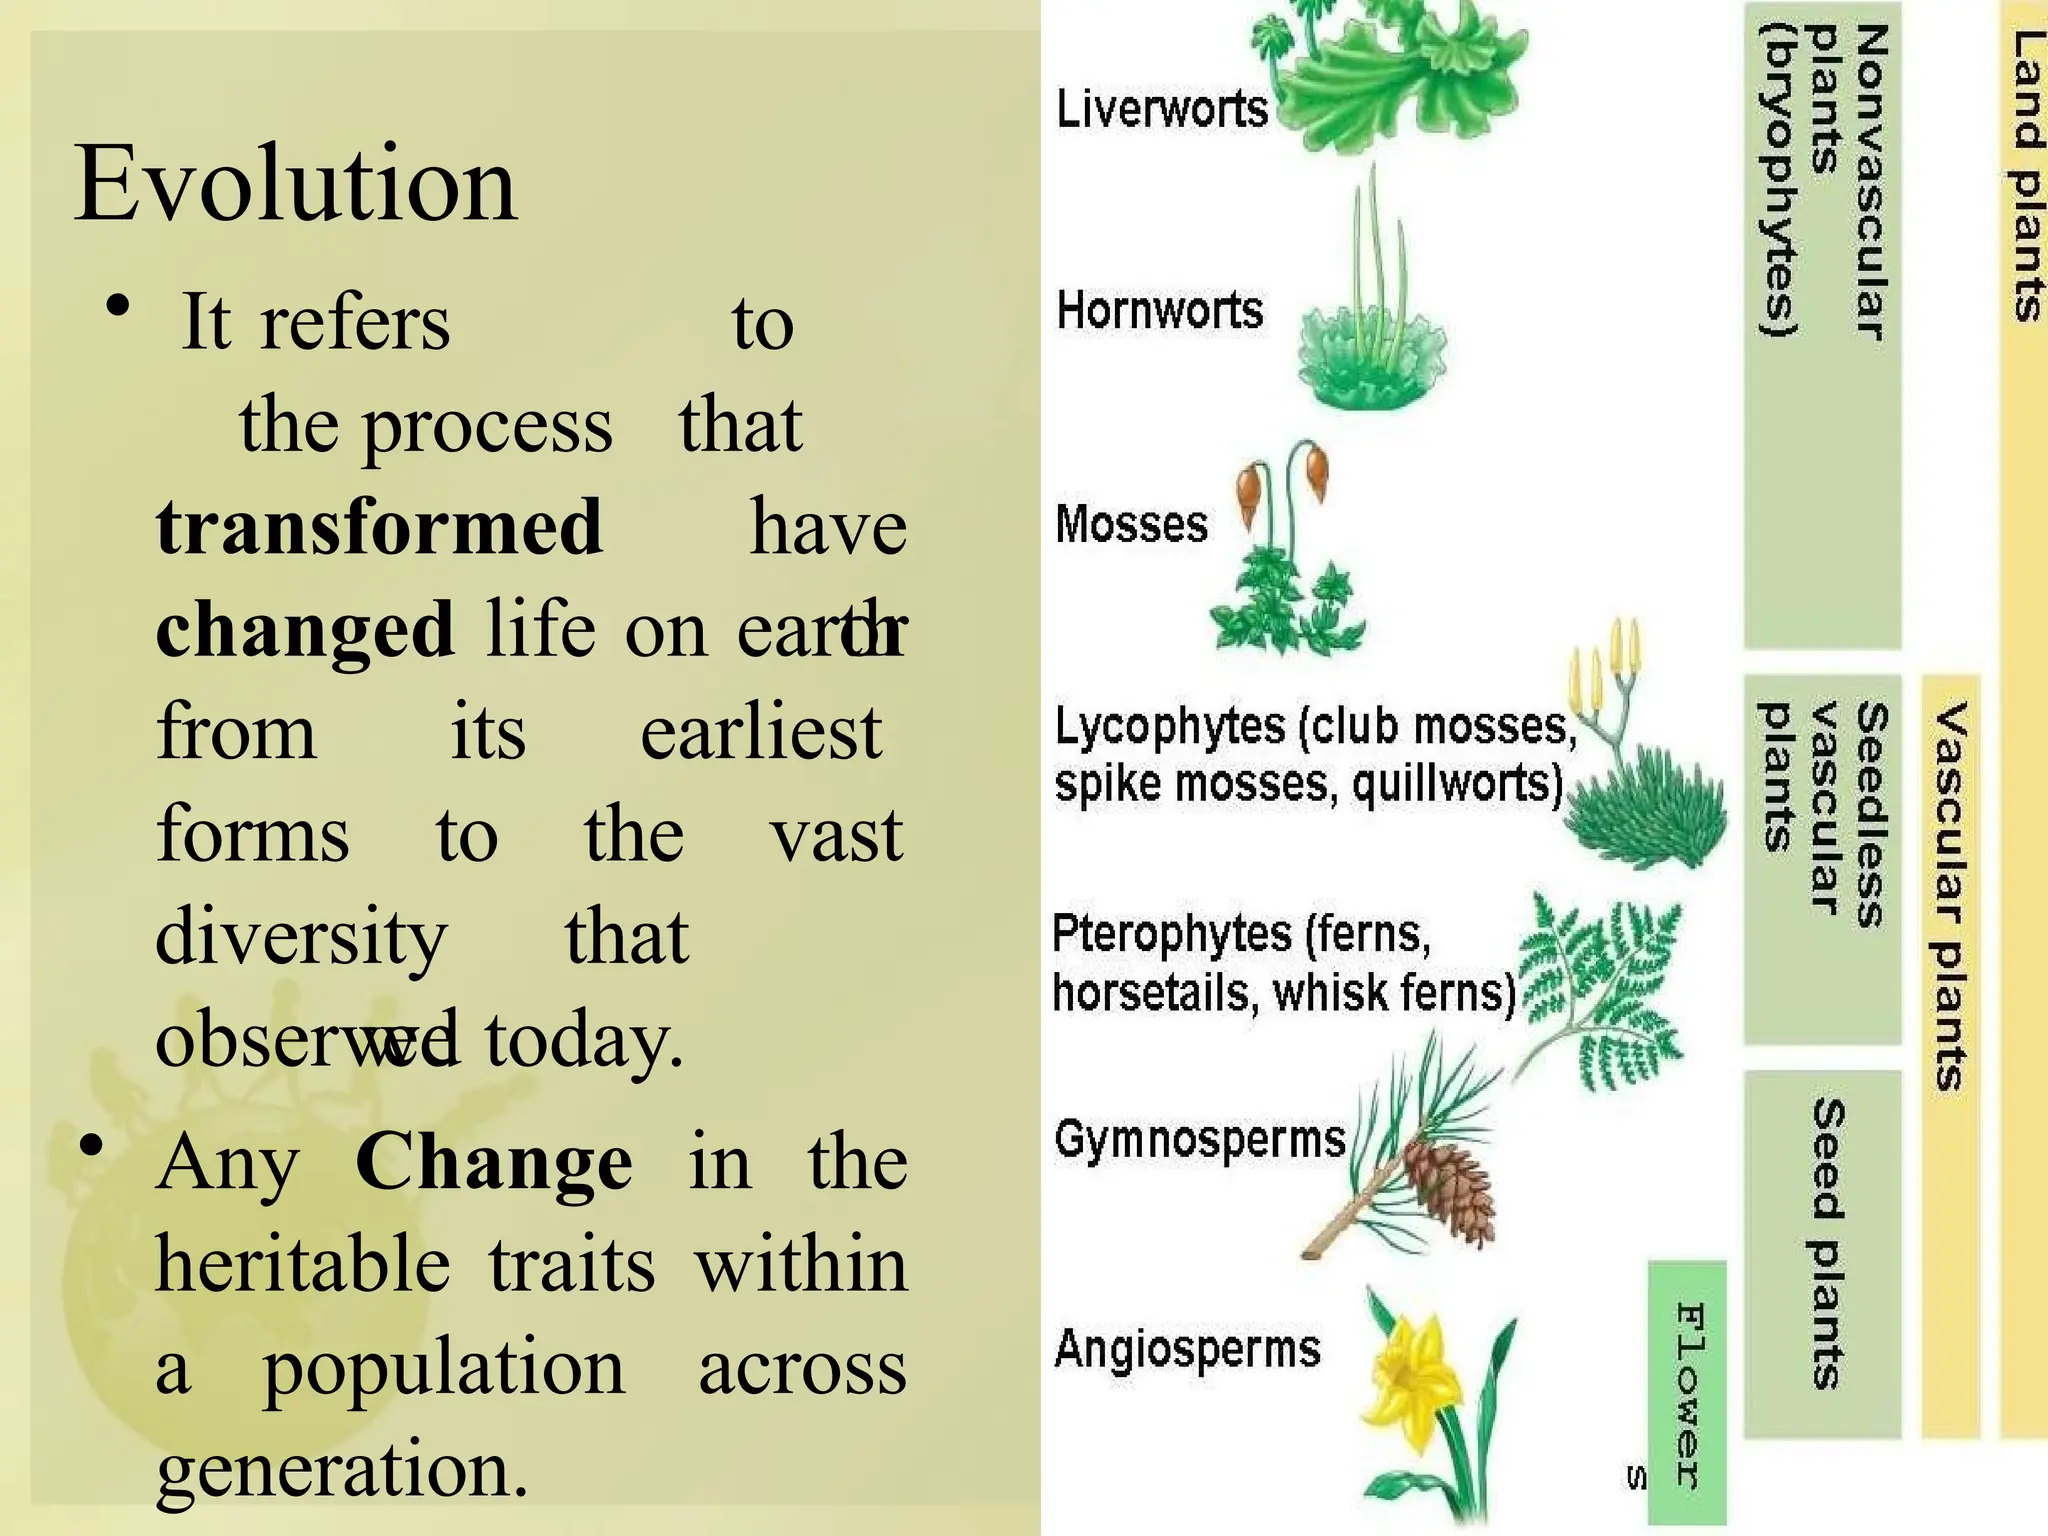
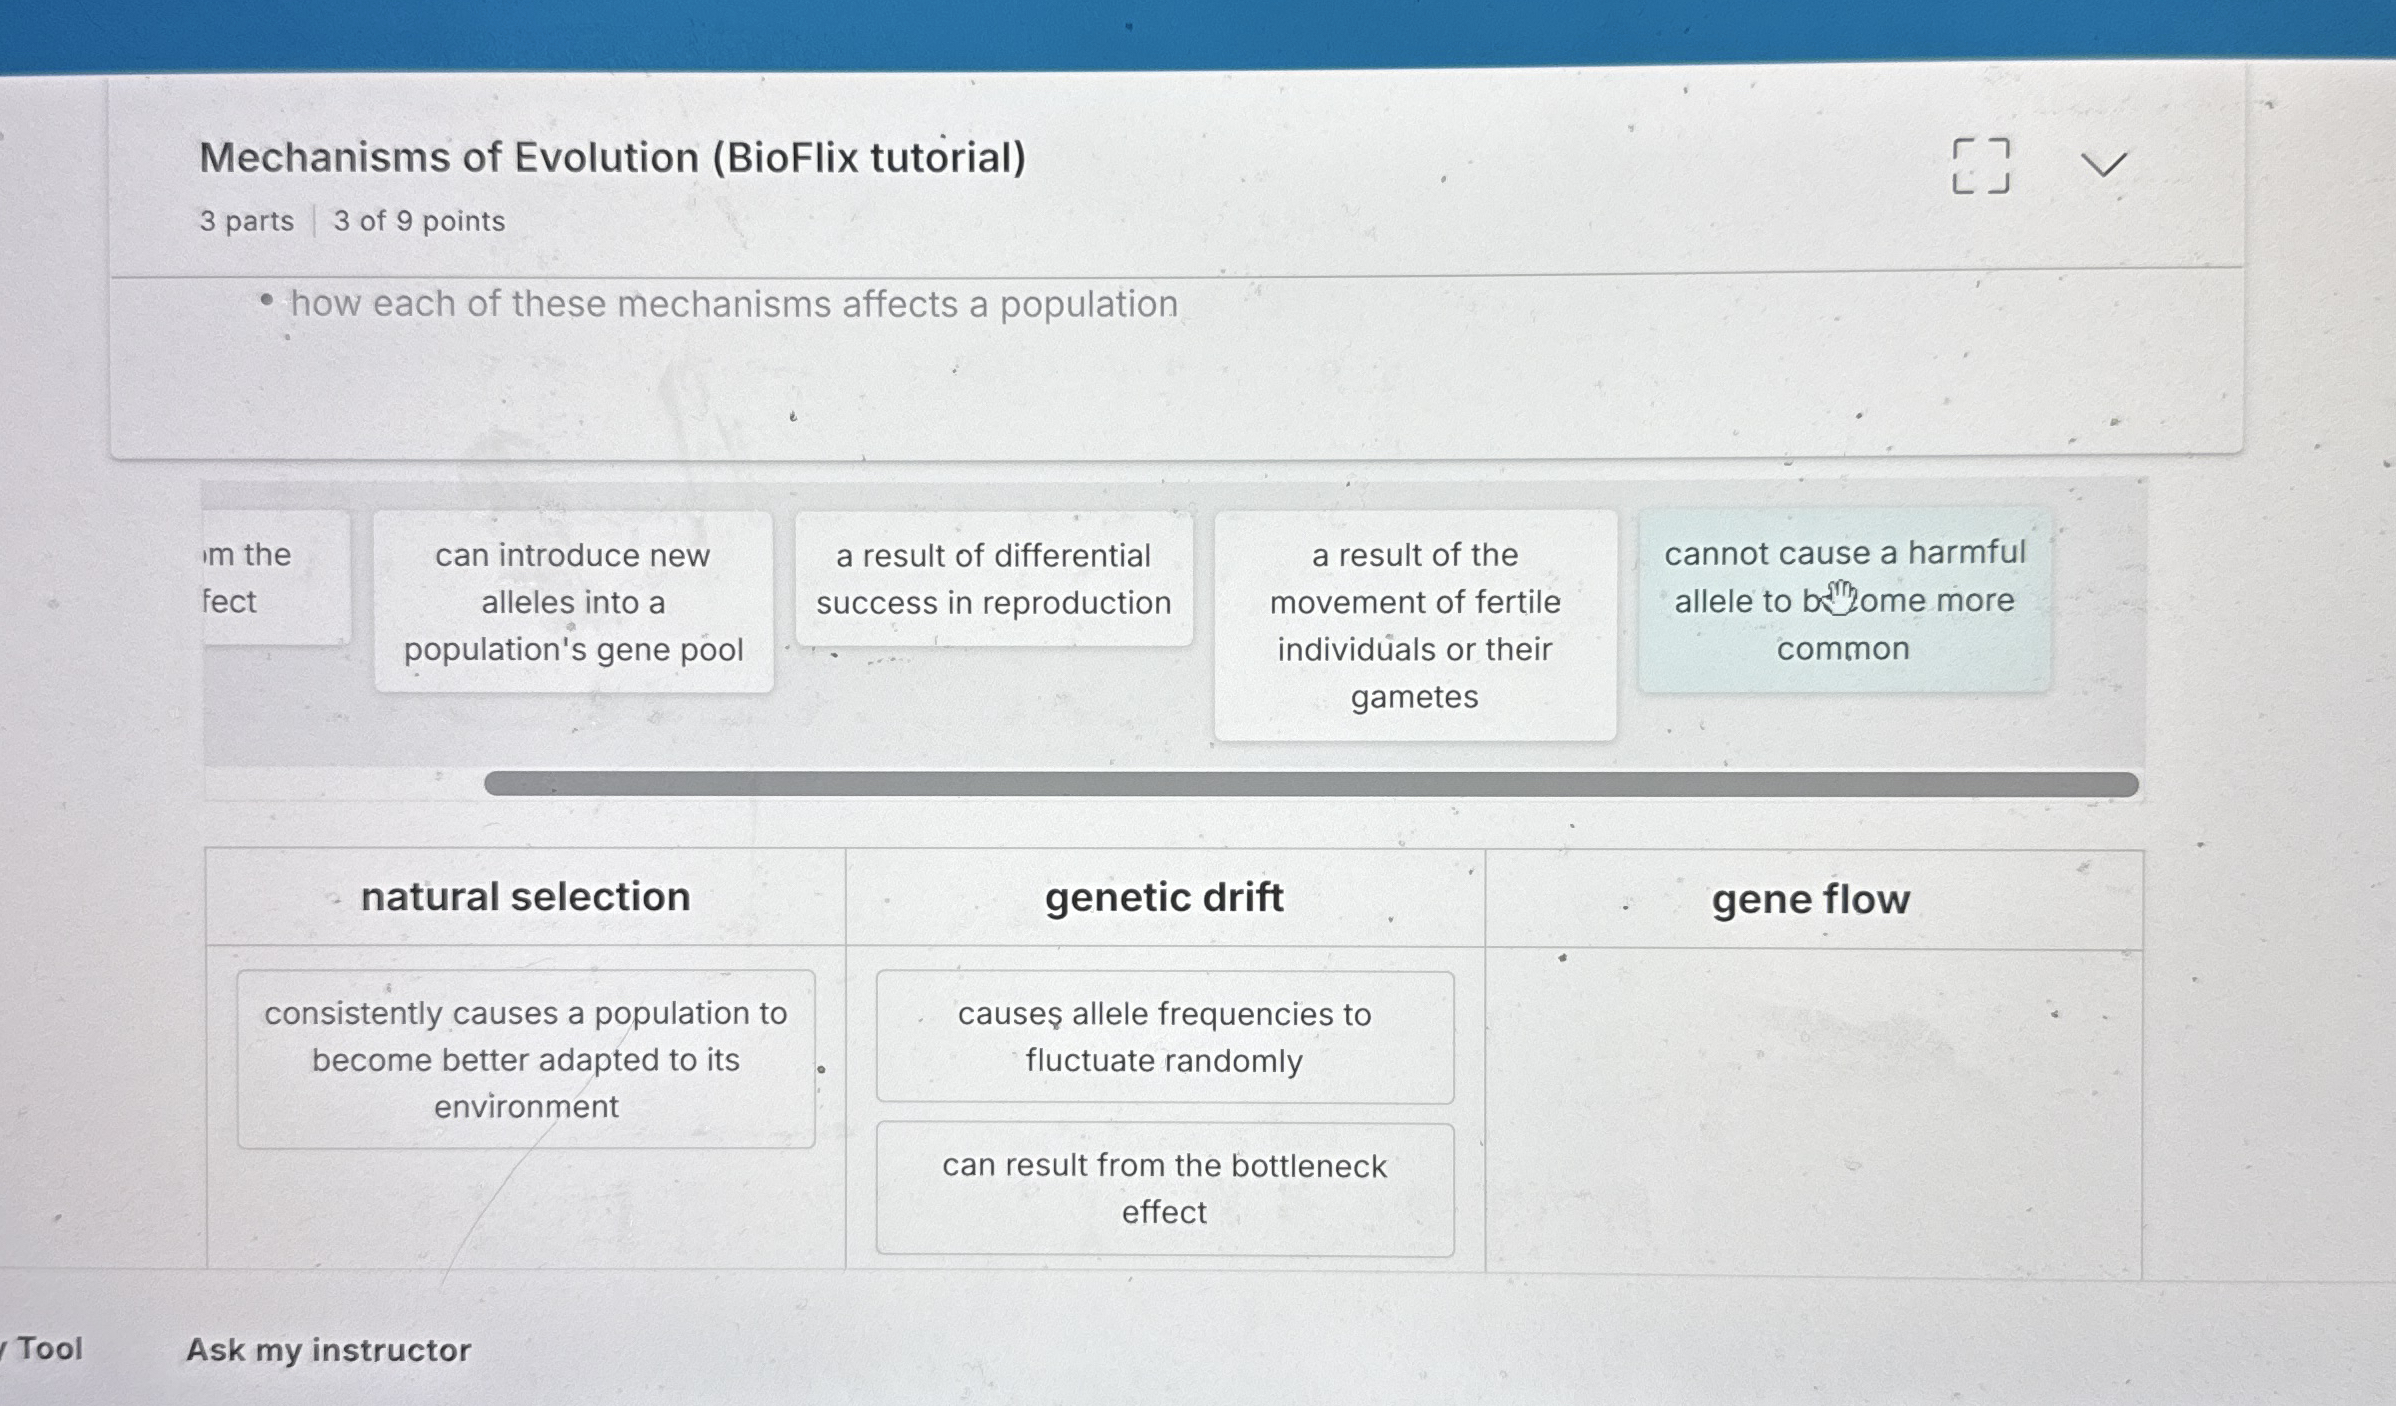
Bioflix Activity and How It Actually Works in Practice
Most people hear about Bioflix and immediately think synthetic biology is about redesigning organisms from scratch. That's only part of it. The real work involves understanding how gene expression cascades get rewired, how regulatory networks propagate through a cell, and what happens when you introduce a novel activity module into an existing evolutionary context. I spent about six months trying to get a specific Bioflix-based construct to express cleanly in a eukaryotic host, and the problem turned out to be something nobody warns you about upfront: off-target transactivation by the basal promoter elements in your construct. The construct was working fine in E. coli. But when I moved it into HEK293 cells, expression dropped to near background levels. Turns out the CMV promoter I used had cryptic binding sites for NF-B, and the cells were actively repressing them as part of a standard innate immune response. Switched to a minimal PGK promoter with a synthetic enhancer block, and expression jumped to roughly 40% of endogenous levels. That's the kind of detail that makes or breaks a Bioflix experiment.
Unlocking The Secrets Of Evolution The Bioflix Activity Mechanisms That Reshape The Tree Of Life
Bioflix is essentially a framework for studying and directing gene regulatory activity across biological systems. The "activity" part refers to measurable changes in transcriptional output, protein production, or signaling cascade behavior that you can observe and quantify. What makes it interesting from an evolutionary perspective is that these activity changes don't happen in isolation. When you modify a regulatory element, you're often shifting the entire fitness landscape around that locus, and the downstream consequences can ripple through multiple evolutionary timescales. I'll walk through the core mechanisms, then cover the practical side of running a Bioflix experiment, the tools you actually need, and where most people hit walls.
Core Mechanisms Behind Bioflix Activity
At the molecular level, Bioflix activity centers on three interacting components: the input signal, the regulatory circuit, and the output readout. The input can be a small molecule, a light pulse, a temperature shift, or even another gene product. The regulatory circuit is typically a designed promoter-operator pair, sometimes augmented with a ribozyme or an aptamer. The output is whatever phenotypic change you're tracking — fluorescence, growth rate, metabolite production, the usual suspects. The tricky part is that these components don't operate independently. Feedback loops are almost always present, even if you didn't design them. A repressor protein that's part of your circuit will accumulate over time, and at high concentrations it can exhibit non-specific DNA binding that silences nearby endogenous genes. I've seen this cause phenotype drift in continuous culture experiments that people initially attributed to mutation rather than circuit interference. Another mechanism worth understanding is resource competition. When you introduce a high-expression Bioflix circuit, the cell's transcriptional and translational machinery becomes a shared resource. This phenomenon, sometimes called "cargo effect" in the literature, means your circuit can inadvertently suppress expression of essential genes simply by outcompeting them for RNA polymerase and ribosomes. The effect scales with copy number and promoter strength, so a plasmid-based system with a strong T7 promoter will show this more dramatically than a chromosomally integrated construct.
Get the Full Details

How to Run a Bioflix Experiment
Start with a clear output metric. I can't stress this enough. People jump straight into construct design without deciding how they'll measure activity, and then they spend weeks chasing data that doesn't exist. Decide whether you're measuring fluorescence intensity, qPCR transcript levels, Western blot band density, or something more complex like single-cell RNA sequencing. Each choice has different trade-offs in terms of resolution, throughput, and cost. Next, pick your input modality. If you're studying evolutionary dynamics, chemical inducers like anhydrotetracycline or arabinose are standard because they give you dose-response curves. But chemical inducers have a half-life problem — they degrade, they get metabolized, and in long-term evolution experiments they can accumulate toxic byproducts. I switched to a light-inducible system (CRY2-CIB1-based) for a 200-generation evolution experiment, and it completely eliminated the chemical noise. The trade-off is that you need a custom incubator setup, and phototoxicity becomes a real concern at high intensities. Construct design should follow a modular approach. Build each component — promoter, RBS, coding sequence, terminator — as a standardized BioBrick or Golden Gate assembly part. Test each part individually before assembling the full circuit. I once spent three weeks troubleshooting a non-functional construct only to discover that the RBS I had chosen from a standard library had a predicted strength of 5,000 relative fluorescence units, but when I measured it in my actual host strain, it was closer to 800. Library values are strain-dependent. Always validate in your organism of choice.
Tools and Resources
For sequence design, Benchling is the default in most labs. It handles assembly planning, primer design, and plasmid mapping well enough. For more complex circuit simulations, COPASI or CellSim can model the dynamics, though the parameter estimation step is tedious. You'll need kinetic constants — promoter strength, RBS efficiency, protein degradation rates — and most of these aren't in public databases for non-model organisms. The Bioflix Activity Database (bioflix-db.org) maintains a curated collection of characterized regulatory parts. It's not exhaustive, but it covers the major bacterial and yeast systems. For evolutionary simulation work, I recommend EvoBeast or custom Python scripts using the SLiM framework. EvoBeast is more user-friendly if you're new to population genetics simulations. A practical tip: keep a lab notebook in a structured format. I use Obsidian with YAML frontmatter for every experiment. It sounds overkill, but when you're tracking three variables across twenty constructs over six months, you need searchability. Frontmatter fields for strain, construct ID, induction condition, and measured output let you query your own data faster than any spreadsheet.
Common Pitfalls
The biggest mistake I see is underestimating the time scale. Bioflix experiments that claim to show evolutionary adaptation in 50 generations are usually just showing adaptive drift within the first few doublings. Real evolutionary reconfiguration of regulatory networks takes hundreds to thousands of generations, depending on population size and selection pressure. If you're working with bacteria, plan on at least 200 generations with regular bottlenecking. With eukaryotes, it's more like 50–100 population doubling cycles. Another pitfall is ignoring genetic background. A Bioflix circuit that works in MG1655 might behave completely differently in a clinical isolate, even if you're doing a straight gene swap. Background mutations in global regulators like crp or fur can change everything. Always do your evolution experiments in a defined background, and sequence the final isolates to confirm what actually changed. Contamination is a silent killer. I lost an entire week of evolution data to a mycoplasma contamination that was slowly altering the growth rate of my culture. Nothing in the data looked obviously wrong — the population was adapting, just at a slightly slower rate than expected. A simple PCR-based mycoplasma test at the start and midpoint of any long experiment would have caught this in an hour.
Where Bioflix Falls Short
Bioflix activity mechanisms are powerful for studying gene regulation in controlled lab conditions, but they struggle in complex environments. Soil microbiomes, the human gut, marine systems — these are far too heterogeneous for current Bioflix approaches to model accurately. The regulatory circuits we design are based on simplified assumptions about nutrient availability, population density, and interaction networks. In natural environments, those assumptions break down quickly. There's also the issue of evolutionary stability. A Bioflix construct that functions perfectly for 100 generations will almost certainly accumulate mutations that degrade its performance over time. This isn't a design flaw — it's a fundamental property of any introduced genetic element in a replicating population. The workaround is to integrate the circuit into the chromosome at a neutral site and use redundant regulatory elements, but even that only buys you so many additional generations. For applications that require long-term stability, consider CRISPR-based gene drives or engineered symbionts instead of free-living Bioflix constructs. They offer different trade-offs — harder to control, but much more resilient over evolutionary time scales.
Getting Started
If you want to try Bioflix yourself, start small. Pick one promoter, one RBS, one reporter gene. Build it. Characterize it. Then add complexity one layer at a time. The temptation is to jump straight into a multi-gene circuit, but each additional component multiplies the number of failure modes you need to account for. A single-gene system has maybe five things that can go wrong. A three-gene circuit has closer to thirty. The community is reasonably active on GitHub and in the iGEM Slack channels. There's no single centralized hub for Bioflix resources, but the parts and protocols are spread across enough public repositories that you can piece together a working setup without too much trouble. Just don't expect anyone to hand you a turnkey solution. That's not how this field works. One final practical note: budget for sequencing. Even if you're only doing expression characterization, you'll want to confirm your construct sequence before and after each experiment. Sanger sequencing is cheap for individual clones, but if you're doing evolution experiments with multiple time points, you're looking at maybe 50–100 sequencing reactions total. At current rates, that's roughly $300–$600 depending on your provider. Worth every dollar when you need to distinguish a real mutation from a sequencing artifact in your construct backbone.