Mean And Standard Deviation Are The Only Two Numbers You Actually Need
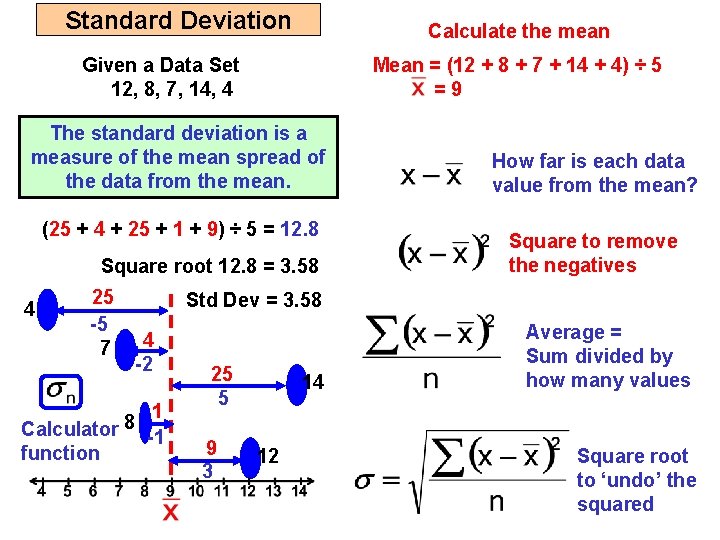
Every dataset I've ever touched collapses into two values at the end of the day. The mean tells you where the center sits, and standard deviation tells you how much the data is actually spread out. Anything more elaborate tends to be noise dressed up as insight, unless you're dealing with heavily skewed distributions where those two numbers become actively misleading. The mean is just a sum divided by a count. Add every observation together and split it by how many observations there are. That's it. Standard deviation is the average distance of each point from that mean, calculated by squaring each deviation, averaging those squares, and taking the square root. The square root part matters because it puts the result back in the original units of your data rather than leaving you with squared units that make no intuitive sense.
Unlocking The Secrets Of Data The Power Of Mean And Standard Deviation
Most people learn these concepts in a statistics class and then immediately forget them because nobody showed them how these numbers behave in production environments. I learned the hard way. A few years ago I was analyzing click-through rates across several marketing funnels. The means looked identical across three different campaigns, so management decided they were equivalent. The standard deviations told a completely different story. Campaign A had a tight cluster around 2.3% CTR with a standard deviation of 0.2. Campaign B was all over the place with a mean of 2.3% and a standard deviation of 1.8. Same mean. Completely different risk profiles. We stopped making decisions based on means alone after that. When you calculate these yourself, here is the practical workflow that works. Take your raw data and remove any obvious data entry errors first, because one typo can shift a mean by several percentage points. Compute the arithmetic mean by summing all values and dividing by n. For the standard deviation, subtract the mean from each individual value, square each result, sum those squares, divide by n minus one for a sample or by n for a population, and take the square root. Use sample standard deviation (dividing by n-1) unless you genuinely have the entire population you care about. In practice almost everyone has a sample, not a population. There is a common shortcut called the computational formula that avoids calculating every deviation individually before squaring. It goes like this: standard deviation equals the square root of [sum of squares minus n times the mean squared], all divided by n minus one. This is computationally cheaper and slightly more numerically stable when you are doing this by hand or in older spreadsheet software. Modern tools handle the straightforward method fine, but the shortcut still saves time when you're working with large datasets in constrained environments.
Here is something most beginners miss. Standard deviation assumes your data is roughly symmetric. If your data is heavily right-skewed, which is common in revenue figures, response times, or any dataset with outliers pulling one direction, the mean gets dragged toward the tail and the standard deviation inflates artificially. In those cases the median and the interquartile range give you a much truer picture of what is actually happening. I switched to reporting median and IQR for all customer lifetime value analysis after I noticed the mean was being pulled up by a handful of enterprise accounts making up forty percent of total revenue. Another thing that trips people up is treating standard deviation as if it means the same thing across different types of data. A standard deviation of five on a scale of zero to ten is catastrophic spread. A standard deviation of five on a dataset where values range from zero to ten thousand is basically nothing. Always compare standard deviation against the actual range of your data or calculate the coefficient of variation, which is the standard deviation divided by the mean, expressed as a percentage. That gives you a relative measure that is comparable across different scales. The empirical rule is worth knowing if your data is approximately normally distributed. Roughly sixty-eight percent of observations fall within one standard deviation of the mean, ninety-five percent within two, and ninety-nine point seven percent within three. This is a useful quick diagnostic. If you compute the mean and standard deviation and then check the data and find that thirty percent of your observations are beyond two standard deviations, your distribution is not normal and you should not rely on parametric tests or control charts built on that assumption. I once caught a fabricated dataset this way. Someone entered repeated values that made the data look artificially concentrated within two standard deviations. When I pulled the raw logs, the timestamps revealed the data had been duplicated and resubmitted by a broken pipeline job.
Get the Full Details
If you want to compute this in Python, use numpy or pandas. The functions are np.mean and np.std or df.mean() and df.std(). Pandas computes sample standard deviation by default with ddof set to one. Excel uses the STDEV.S function for sample and STDEV.P for population. R uses mean() and sd(). All of these handle missing values differently by default, so always check whether your tool is excluding NaNs or returning NaN itself. I lost about three hours once debugging a script where pandas was silently dropping half my rows because of invisible whitespace characters in the source file. The main limitation of relying solely on mean and standard deviation is that they describe only the first two moments of a distribution. They say nothing about skewness, kurtosis, multimodality, or the shape of the tails. A dataset can have the exact same mean and standard deviation as another dataset and look completely different when plotted. Datasets constructed specifically to demonstrate this are called Anscombe's quartet and they are worth plotting whenever someone tells you summary statistics are sufficient. They are not. Use mean and standard deviation as a first pass, not a final answer. They give you a fast operational summary that is easy to communicate to stakeholders who do not want to look at a histogram. Then follow up with a box plot or a density estimate to catch whatever the two numbers are hiding. That is the actual workflow I use now and it has saved me from making public recommendations based on incomplete information more times than I care to admit.