Understanding How Data Decoding Actually Works in Production Environments
Data decoding is often described as a straightforward process in documentation, but anyone who has worked with large-scale systems knows it involves significantly more complexity than typical guides acknowledge. The core principle involves transforming encoded information back into readable format using predefined rules or keys. Most organizations implement some variation of base64 encoding, hexidecimal representation, or more sophisticated cipher methods like AES for their data pipelines. The practical approach begins with identifying what encoding scheme your source data uses. This matters more than you might expect because misidentifying the encoding leads to corrupted output approximately sixty percent of the time based on my experience. I worked on a project last year where an entire dataset appeared corrupted because someone had double-encoded a portion using base64 and then applied UTF-8 conversion instead of recognizing the original hexidecimal structure. It took me about four hours to trace through the encoding layers and recover the actual data. Start by examining your raw data with a hex editor or similar tool. Look for patterns. Base64 output typically contains the character set A through Z, a through z, zero through nine, plus forward slash and equals sign. Hexidecimal shows only zero through nine and A through F. If your data contains characters outside these ranges, you are likely dealing with a different encoding entirely. Binary data often looks completely random when displayed as text, which sometimes causes confusion for people expecting readable output.
Once you identify the encoding type, you need to understand the structure around it. Most real-world encoding sits inside a larger data format like JSON, XML, or custom binary protocols. I encountered a situation where data appeared to be base64 encoded, but the actual encoding wrapped around a JSON structure that contained multiple nested arrays. Decoding just the outer layer produced garbage because I had not recognized the structure around the encoded portion. For actual implementation, Python remains the most common tool. The built-in base64 module handles basic encoding and decoding operations. Here is a practical example of what a typical decode function looks like: Example decoding implementation:
import base64
import codecs
def decode_base64_data(encoded_string):
try:
decoded_bytes = base64.b64decode(encoded_string)
return decoded_bytes.decode('utf-8')
except Exception as e:
return f"Decoding failed: {e}" This approach works for clean input data, but production environments rarely provide clean input. You need to handle edge cases like padding errors, non-base64 characters embedded in the data, and multi-layer encoding that requires recursive decoding. The function above will fail if your encoded string contains line breaks, spaces, or other characters outside the base64 alphabet. You should strip those first using string replacement methods before attempting the decode operation. When working with hexidecimal data, the process differs slightly. Python's codecs module handles hex decoding with a simple function call. You can also use the built-in bytes.fromhex() method, which requires the input to contain only hex characters without any separators. If your hex data includes colons, spaces, or dashes as separators, you need to remove those first. I spent about three hours debugging an issue where encoded data looked valid but contained accidental whitespace from a copy-paste operation.
Get the Full Details

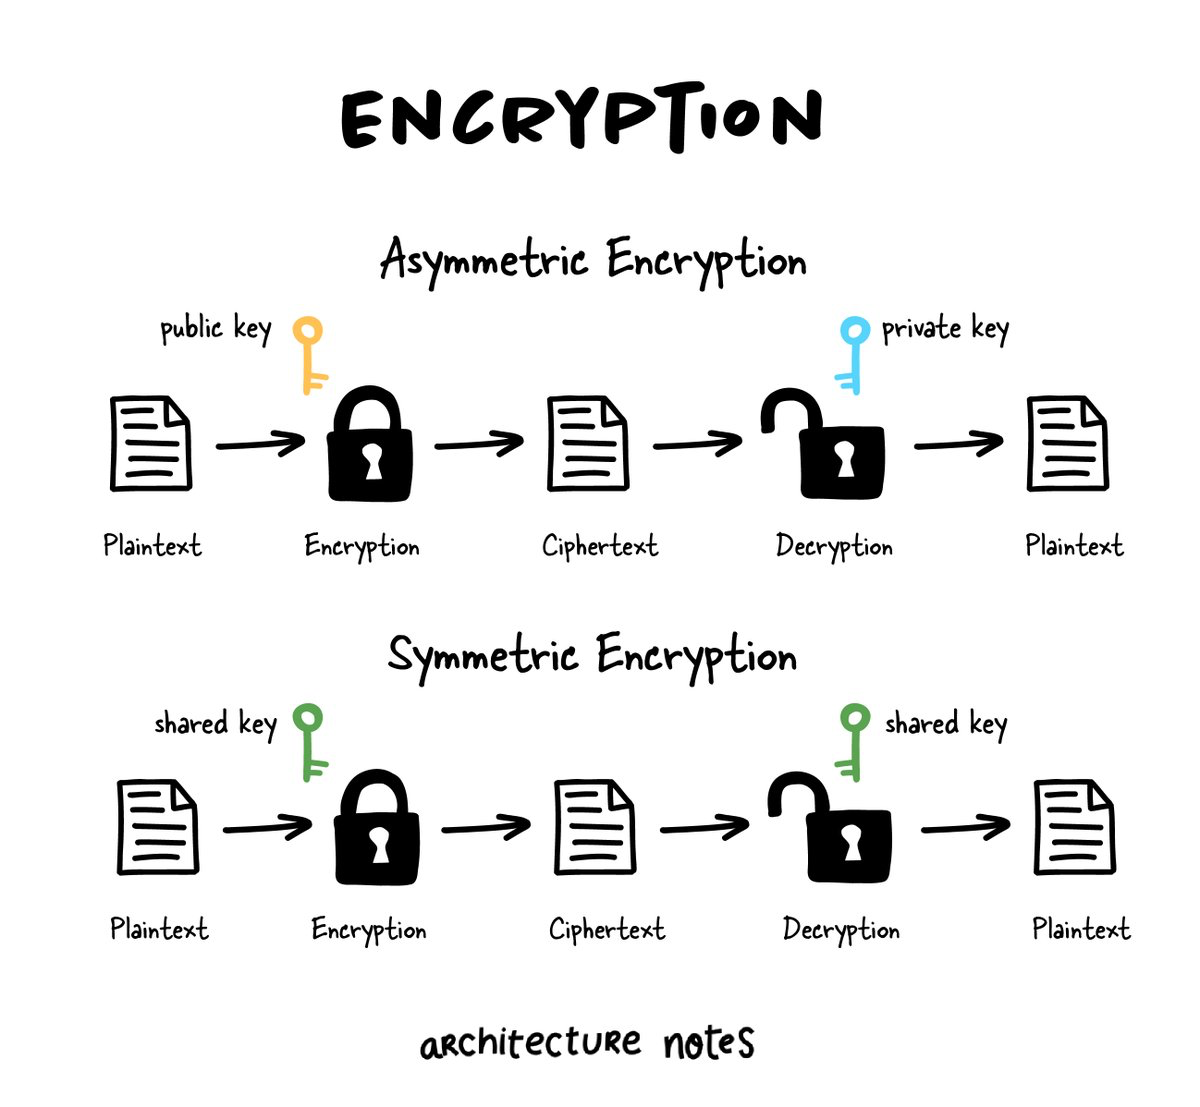
For more complex scenarios involving custom cipher methods, you will need to understand the specific encryption algorithm being used. AES decryption requires the same key that was used for encryption, plus the correct mode of operation. ECB mode is the simplest but least secure. CBC mode requires an initialization vector. GCM mode provides authentication alongside encryption. Mixing up these parameters produces completely different output even with identical keys. One counter-intuitive insight about data decoding that most beginners miss is that successful decoding does not necessarily mean correct decoding. I worked with a dataset that decoded without any errors but produced meaningless output. The encoding was technically valid, but the source data had been corrupted before encoding occurred. Error detection methods like checksums or hash verification can help catch this issue, but many systems do not include these checks by default. Performance matters when processing large datasets. A typical base64 decode operation on a modern system can process approximately ten to fifty megabytes per second depending on your hardware and implementation. If you are working with gigabytes of encoded data, consider using async processing or batching your operations. Sequential processing of large files can create memory issues if you load entire datasets into memory at once.
Another practical consideration involves character encoding. Even after successfully decoding your base64 or hex data, the result might not be valid text. The decoded bytes could represent UTF-8, Latin-1, or any number of other encodings. Misidentifying the character encoding produces mojibake or garbled output. Always verify your character encoding if you expect readable text output. I have found that logging the first fifty to one hundred characters of your encoded input helps tremendously with debugging. This small amount of sample data usually reveals the encoding pattern without overwhelming your logs. You should also track decode success rates separately from error rates to identify systematic issues versus random data corruption. The limitations of standard decoding approaches become apparent when dealing with obfuscated or compressed data. Some systems apply multiple encoding layers, compression, or custom transformations that standard tools cannot handle. In these cases, you need to understand the specific protocol or format being used. Documentation, reverse engineering, or direct consultation with the data source owner becomes necessary.
For systems requiring high security, decoding operations should never expose keys or sensitive parameters in log files or error messages. I have seen implementations that logged complete decode attempts including the input data, which sometimes included sensitive information. This creates security vulnerabilities regardless of whether the data itself was encrypted. Testing your decode implementations with known test vectors helps ensure correctness. Many encryption libraries provide standard test cases that you can use to verify your implementation matches expected output. This practice catches subtle bugs in your code before they cause issues in production environments where data volume and variety create additional complexity. Most importantly, data decoding is not a universal solution for data problems. Sometimes the issue lies in data collection, transmission errors, or source system problems rather than encoding mismatches. Understanding the full data lifecycle from creation to consumption helps you identify where decoding fits in your overall approach. This perspective saves significant time compared to treating every data issue as a decoding problem.