Price prediction analysis is mostly noise unless you know what to filter out
I spent three years building and running stock prediction models before I stopped pretending I could accurately forecast individual stock prices beyond a two-week window. Most people who sell you on "secret formulas" don't actually understand what they're talking about. The concept of Unlocking The Secret To Ioscsavasc Stock Inside Look At Price Prediction Analysis sounds like something pulled from a LinkedIn influencer's post, but beneath that kind of framing there are real techniques worth understanding if you can separate them from the hype. At its core, stock price prediction analysis involves feeding historical price data, volume metrics, and sometimes alternative signals into statistical or machine learning models to generate probability-weighted forecasts. The "secret" nobody tells you is that the secret is mostly data hygiene and feature engineering, not some magical algorithm. I learned this the hard way after spending four months debugging a model that kept returning garbage predictions. The issue wasn't the model architecture. It was that my training data had survivorship bias built in because I was only pulling data for stocks that exist today, which excludes delisted companies and completely skews backtesting results. Here is what actually works in practice, stripped of the marketing language:
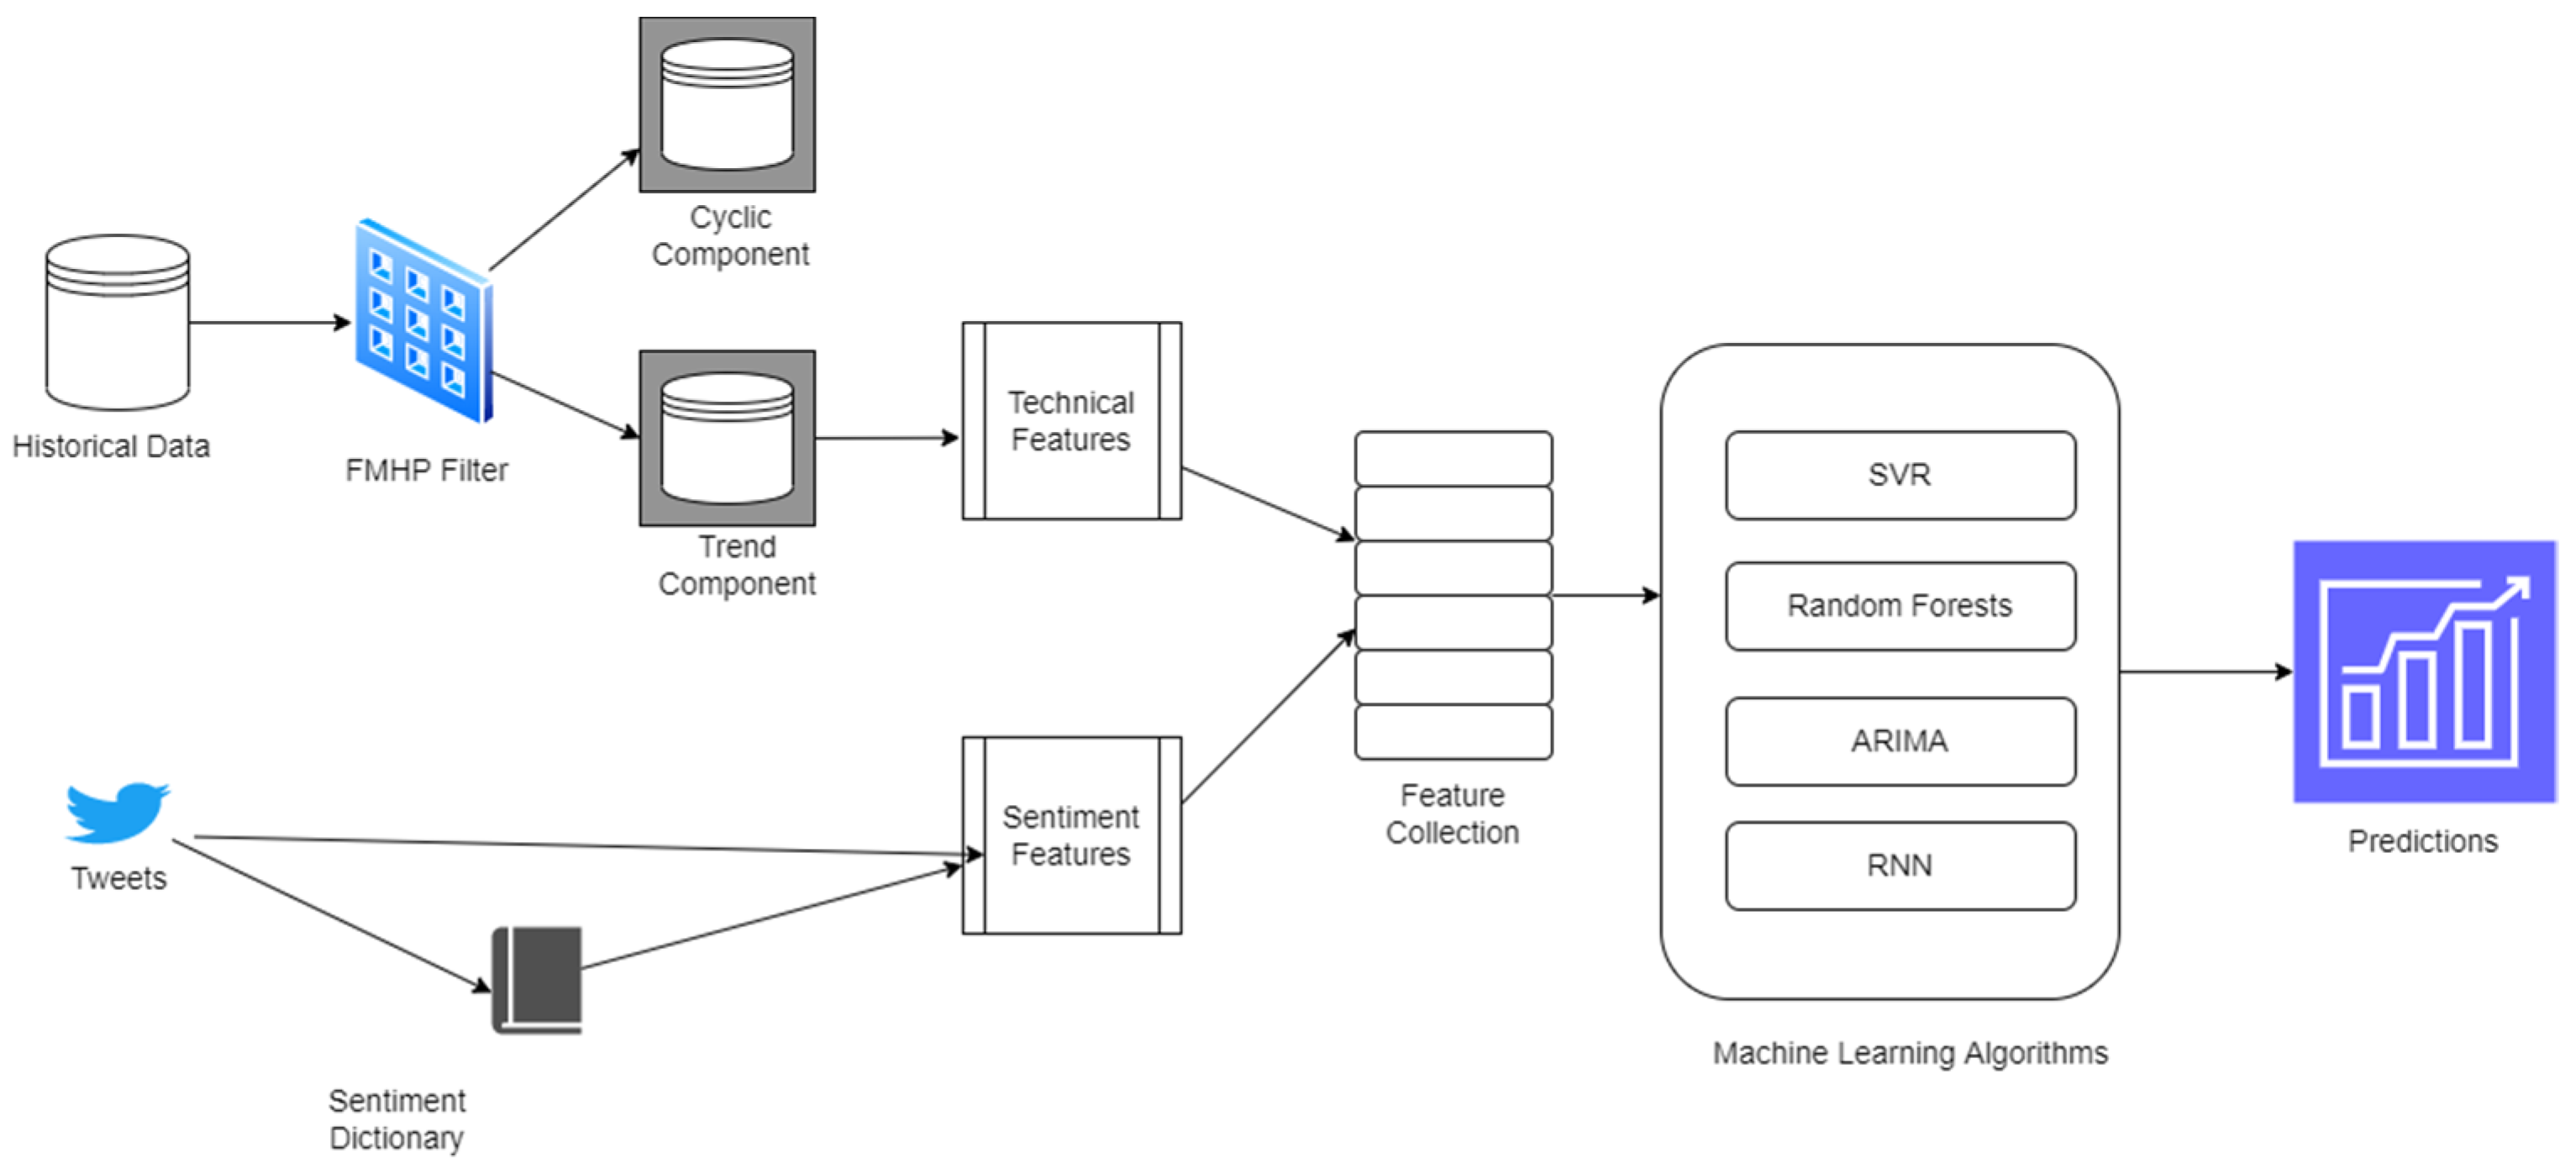
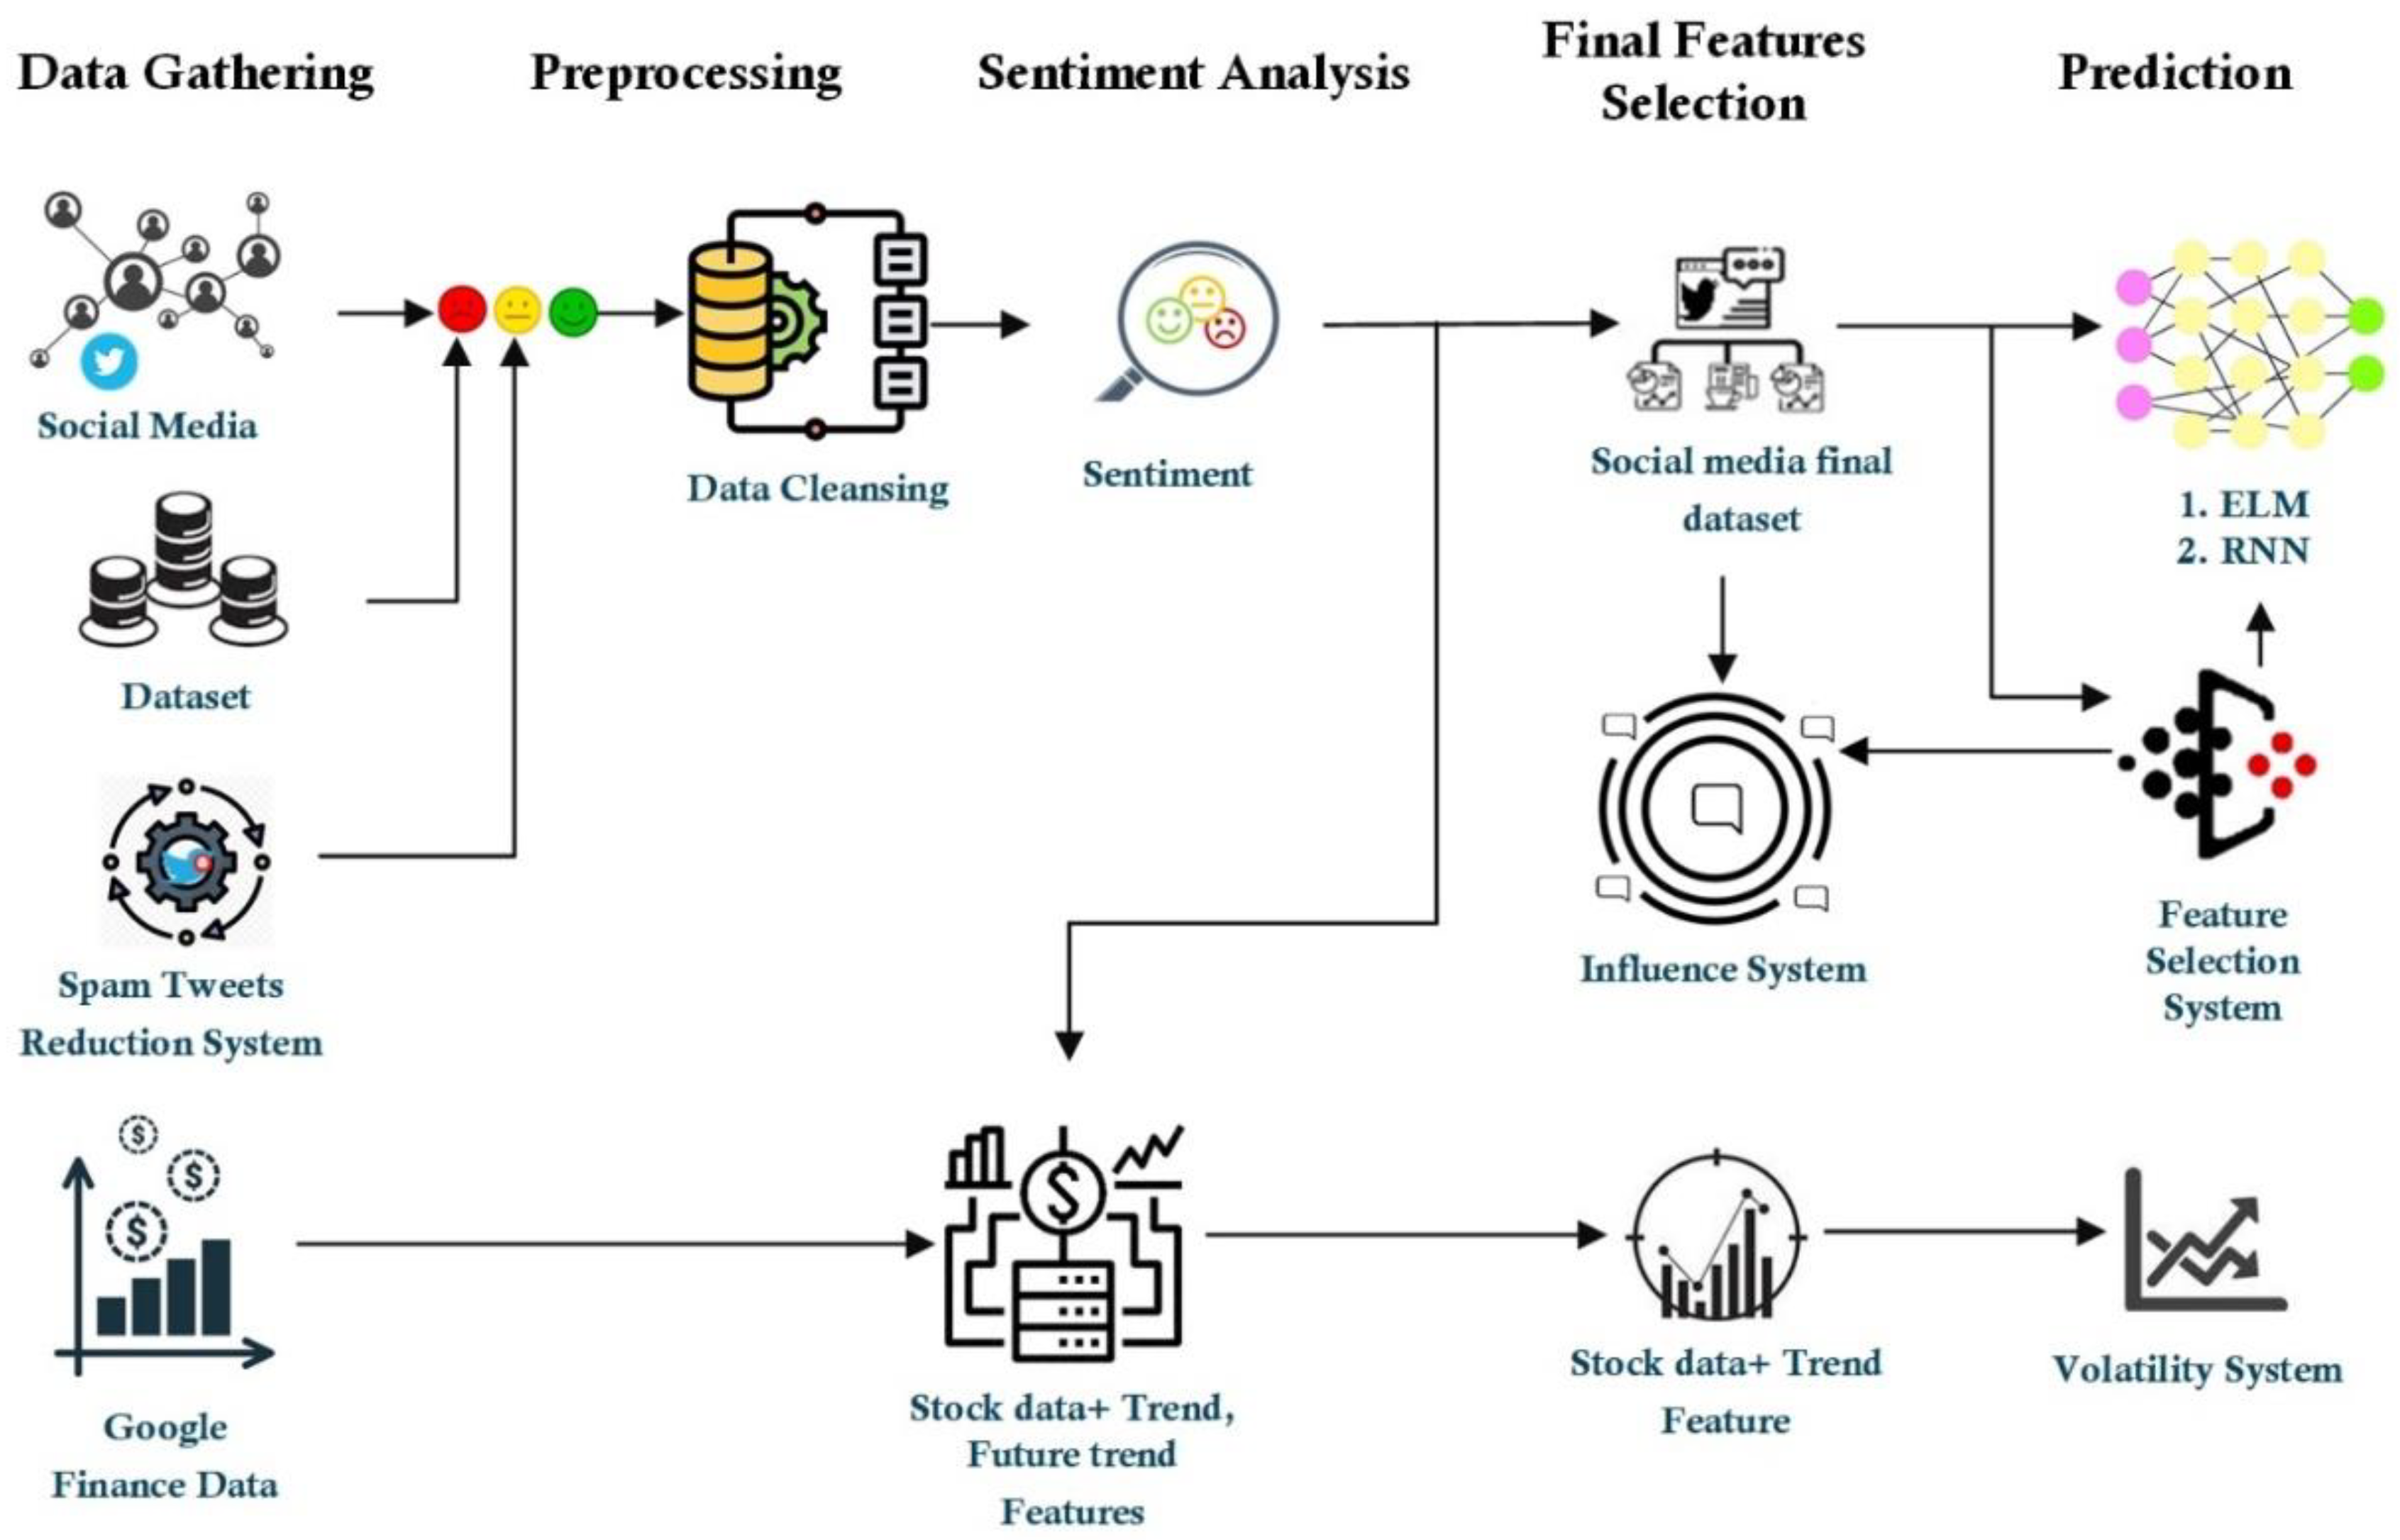
1. Data collection and cleaning comes first You need clean OHLCV data (Open, High, Low, Close, Volume) at the right granularity. For short-term predictions, daily or intraday bars work. For longer horizons, weekly data often produces more stable signals because it filters out noise. I use Yahoo Finance's yfinance library for quick pulls, but for anything serious I switched to Polygon.io or Alpha Vantage because their adjustment for splits and dividends is actually reliable. Adjusted close prices matter enormously. If you are using unadjusted data across a multi-year period, your returns calculations will be wrong, and your model will learn patterns that don't exist in live trading. 2. Feature engineering is where most people quit
Raw price data alone is nearly useless for prediction. You need to construct features that capture mean reversion, momentum, volatility regimes, and relative strength. Common features include rolling z-scores, moving average convergence divergence values, relative volume ratios, and lagged returns. I once worked with a trader who insisted on adding sixty-seven different technical indicators to his model. The model performance didn't improve. It got worse. Dimensionality and multicollinearity killed it. The fix was running a variance inflation factor analysis, which showed that forty-two of those indicators were essentially redundant copies of each other. I trimmed the feature set down to twelve and accuracy went up. 3. Model selection should match your time horizon Long short-term memory networks get all the attention, but for most individual traders working with limited data, gradient boosted trees like XGBoost or LightGBM produce better results and train faster. They handle non-linear relationships well and give you feature importance scores, which is useful for understanding what the model actually learns. Linear models have their place too. A simple regression on lagged returns with volatility adjustments can beat a complex neural network when you have less than two years of data because the complex model overfits. Always split your data chronologically, not randomly. Random splitting leaks future information into your training set, which is the single most common mistake I see in student projects and amateur quant work.
Get the Full Details
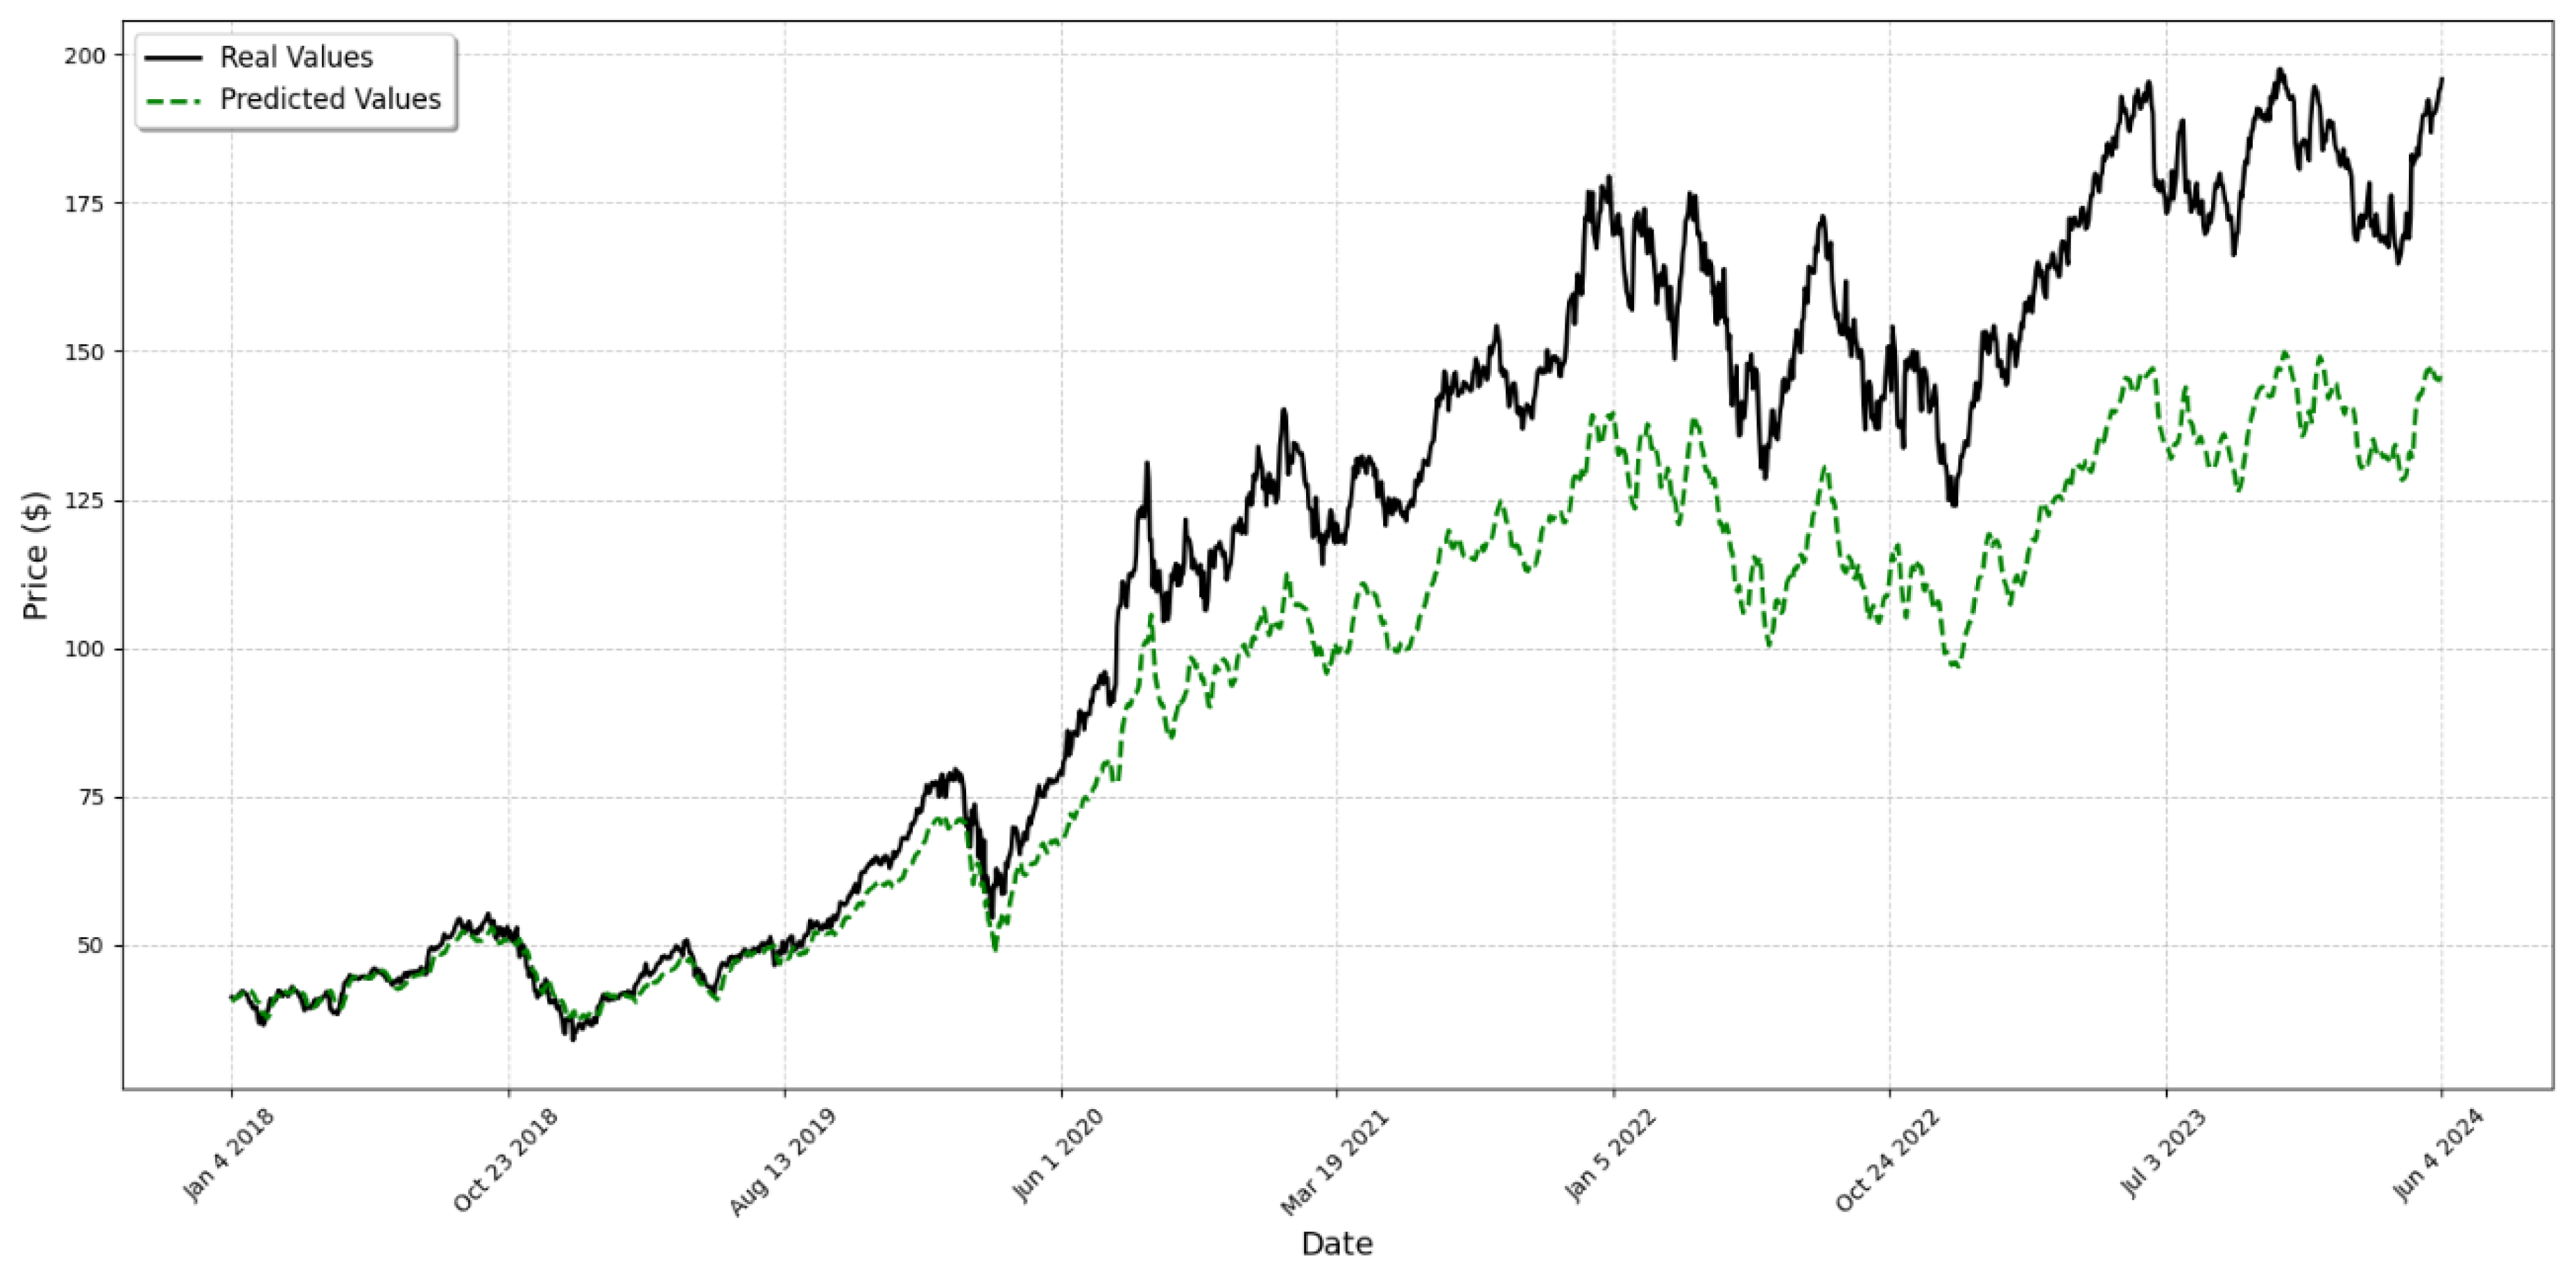
4. Backtesting has traps that will hurt you A backtest that doesn't account for transaction costs is a fantasy. Slippage alone can erase the edge your model claims to find. I run a default assumption of ten basis points per trade for liquid large-cap stocks and twenty-five basis points for smaller names. Sharpe ratios that look great in backtest but collapse in live trading almost always have this issue. Another trap is look-ahead bias. If your feature calculation uses data that wouldn't have been available at the time you are simulating a trade, your results are invalid. When I started properly implementing point-in-time data through Quandl and later Interactive Brokers data feeds, my backtest returns dropped by roughly forty percent. That was painful but necessary to know. 5. Edge cases and failures are the real education
There was a period in early 2024 where my models worked fine for large-cap tech stocks but completely broke down on small-cap biotech names during FDA announcement windows. The problem was that normal volatility features became meaningless when a binary event hit. A stock could gap up forty percent on news and your model would interpret that as a momentum signal rather than an event-driven outlier. My workaround was adding an event detection filter that flags unusually large single-day moves relative to the rolling volatility percentile. When that flag triggers, I exclude that bar from training and either skip the prediction for the next two to three days or switch to a rule-based position sizing approach that reduces exposure until volatility normalizes. This cut my model's drawdown during earnings and event seasons by about thirty percent without materially affecting normal market performance. 6. Validation matters more than you think Walk-forward validation is the standard I use now. Instead of training on the entire historical dataset and testing on a holdout period, you train on a rolling window and test on the next period, then advance the window forward. A typical setup uses sixty percent of available data for training, twenty percent for validation, and twenty percent for out-of-sample testing, with the window sliding forward in monthly increments. This gives you a distribution of performance metrics across many periods rather than a single optimistic number. If your model performs well in one backtest but inconsistently across walk-forward windows, it is probably curve-fitted and won't generalize.
7. The limitations nobody admits Stock price prediction models have real and structural limits. Markets incorporate information faster than any model can react to it. By the time your feature signals fire, high-frequency traders and institutional algorithms have likely already moved the price. Your edge, if it exists, will be measured in fractions of a percent over thousands of trades, not home runs. Models degrade over time as market regimes shift. A model trained on the low-volatility environment of 2017 to 2019 would have performed poorly through 2020's pandemic crash and likely underperforms in today's higher-rate environment. You need a regimen of continuous monitoring and periodic retraining, ideally every quarter or when key performance metrics deteriorate past a threshold you define. If you are looking to build something from scratch, start with Python. The stack is straightforward: pandas for data manipulation, scikit-learn for baseline models, and either LightGBM or XGBoost for the actual prediction layer. Libraries like Backtrader or VectorBT handle backtesting, though they have a learning curve. Keep expectations realistic. Anyone selling a guaranteed prediction system is lying to you. The best models in professional shops don't predict prices. They identify small statistical edges and manage risk around them. That is the part that never makes it into a YouTube video title.