How I Actually Built A Working Translation Memory System
Most businesses approach translation memory the wrong way. They buy a platform, upload their files, and expect everything to just work. It doesn't work that way. I spent three years setting up TMs for companies ranging from mid-size SaaS firms to regulatory-heavy medical device manufacturers, and the pattern is always the same: the technology is the easy part. The actual value comes from how you clean, align, and maintain your bilingual data before it ever touches the software. A translation memory is fundamentally a database of previously translated segments paired with their source counterparts. When you feed it new text, it finds matching or similar segments and suggests existing translations. That's the textbook definition. But here's what nobody tells you: the suggestions are only as useful as the quality of the segments stored in the system. Garbage in, garbage out isn't a slogan here, it's a daily operational reality. I once had a client who wanted me to import 40,000 sentence pairs from a competitor's old public documentation they'd scraped and ran through a neural machine translator. The match rates looked impressive at first glance — 78% fuzzy matches above 75% similarity — but the semantic accuracy was terrible because the source material had subtle technical meanings that Google Translate flattened into generic language. We spent two weeks manually auditing the entire TM before we could trust it for production work. That experience taught me that alignment quality matters more than match quantity.
Unlocking The Power Of Translation Memory The Ultimate Gamechanger For Businesses
Getting started requires a few concrete decisions before you install anything. First, pick your format discipline. TMs work best when your source files have consistent segmentation. If you're dealing with PDFs, get them converted to editable formats first. Word documents, XLIFF files, and XML-based content management systems give you clean paragraph boundaries. PowerPoint slides and scanned documents are the worst offenders for creating messy segment boundaries that confuse the matching engine. Step one is building your initial bilingual corpus. This is the hardest part and also the most skipped. You need aligned source and target text. The options are: extracting translations your team has already produced, purchasing pre-aligned corpora for your language pair, or hiring translators to create the initial alignments from scratch. For most businesses, the third option sounds expensive but it's actually the most cost-effective long-term. A professional translator can align and clean a segment pair in about 30 to 45 seconds. That's faster than an automated alignment tool fixing its own mistakes, which typically takes two to three minutes per problematic segment. Step two is choosing your TM platform. The major options are MemoQ, Trados Studio, Memsource (now Weblium), and Smartcat. Each handles terminology integration differently. MemoQ and Trados are the most entrenched in the enterprise space. Memsource and Smartcat are cloud-native and easier to set up quickly. If you have fewer than five active projects per month and your team is small, the cloud tools save you roughly a week of setup time compared to the desktop-based options. If you're handling regulated content or need on-premise deployment, the desktop options are non-negotiable.
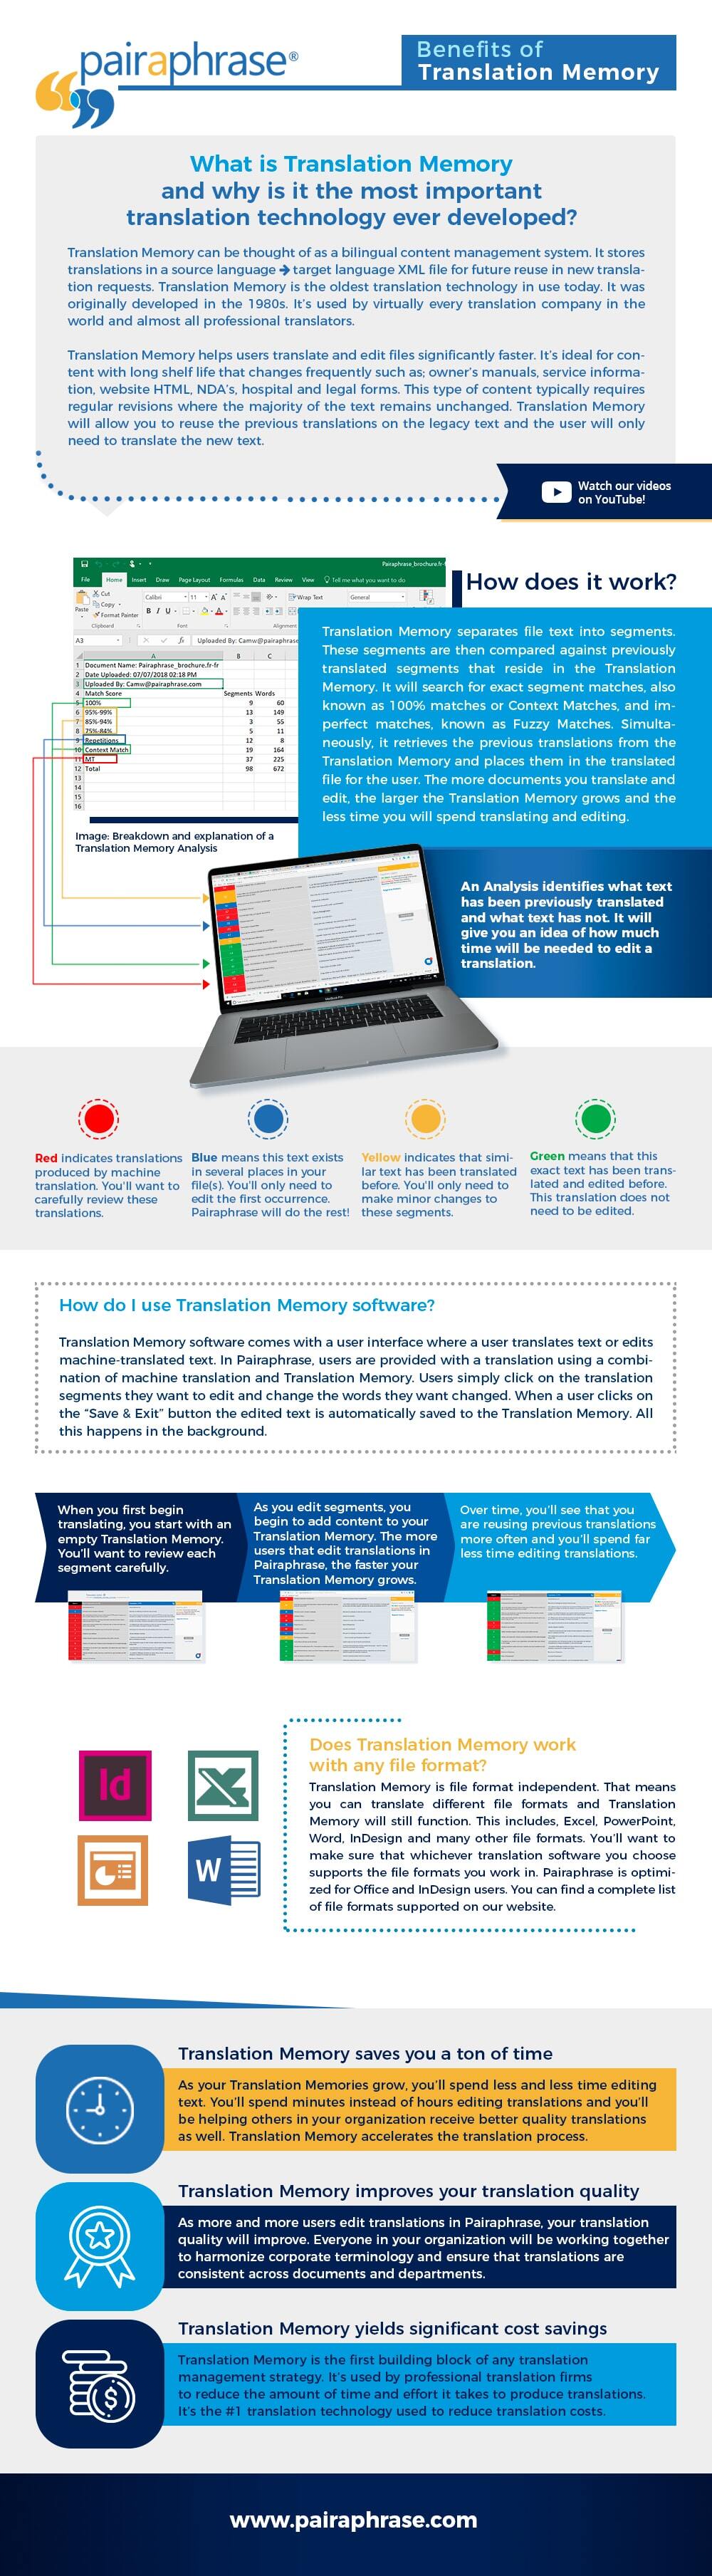
Step three is configuring your match thresholds and fuzziness settings. This is where most people make mistakes. A standard configuration uses 100% matches, 99-to-75% fuzzy matches, and below-75% as no-match. But the 75% floor is arbitrary and often too low. I've seen 75% fuzzy matches produce translations that were contextually wrong because the matching algorithm was comparing sentence structure rather than meaning. Lower your fuzzy threshold to 85% for technical content where precision matters. Raise it to 90% for legal and regulatory material. Only use lower thresholds for marketing copy where creative variation is acceptable. Step four is establishing your update workflow. This is the part everyone forgets until their TM becomes stale. Every completed project should feed back into the TM within 48 hours. Translators should be configured to push new segments to the shared TM after each work session, not at the end of a project when context has faded and terminology decisions haven't been finalized. I set up a rule for one client where incomplete or unreviewed segments didn't auto-commit to the TM. They sat in a staging area until a senior translator approved them. This added about 10% processing overhead but prevented contaminated segments from poisoning future matches. The contamination was real — we found a 12% error rate in projects that drew from unvetted TM entries versus 3% for vetted entries. There are legitimate limitations you need to accept upfront. Translation memory does not handle creative translation well. Poetry, marketing slogans, brand voice documents, and anything that requires significant cultural adaptation will either produce awkward matches or waste your time if you try to force TM usage. These categories perform better with fresh translation guided by a terminology glossary rather than past segment matches. Second, TMs don't improve with volume alone. Adding 100,000 poor-quality segments makes your TM worse, not better. Quality curation matters more than raw size. A curated TM with 15,000 high-quality segments will outperform an uncurated TM with 200,000 segments on any technical or regulated content.
Get the Full Details
Another thing that surprises people: translation memory and machine translation are different systems and shouldn't be conflated. Some platforms bundle them together, which creates confusion. A TM suggests human-translated segments. MT generates translations algorithmically. Using both together is possible and often effective, but the combination requires careful tuning. If you enable both TM and MT simultaneously, the TM suggestions can suppress good MT output, or the MT can drown out accurate TM matches depending on how you weight them. I recommend running TM and MT as separate passes and letting a human reviewer choose between them, rather than letting the software auto-select. This adds roughly five minutes per segment but dramatically improves consistency on complex content. The cost structure is also worth understanding before you commit. Enterprise TM platforms typically charge per seat per month. Trados Studio Professional runs about $1,500 to $2,500 per year per license. MemoQ Server costs similarly. Cloud platforms like Smartcat offer freemium tiers that work for small teams, then scale to roughly $30 to $60 per user per month. For a team of three translators doing moderate volume, the monthly cloud option usually pays for itself within two months based on time savings alone. The math is straightforward: if a translator normally spends 40 hours per week on translation work and TM usage reduces that to 25 hours by reusing existing translations, that's 15 hours recovered per week. At even a modest billing rate, that's thousands of dollars monthly in regained capacity. One edge case that tripped me up repeatedly involved multi-language documentation with conditional text. I worked with a software company that had a single source document containing product descriptions for five different regions, with conditional logic that showed or hid content based on the target market. A naive TM import would duplicate every segment across all five regional TMs, creating massive redundancy and inconsistency. The solution was configuring separate TMs per region with cross-TM lookup disabled, then using a shared terminology database instead. This kept segment counts manageable and ensured that a terminology update in one region didn't accidentally propagate to another. It took an extra day of setup but prevented what would have been a months-long cleanup operation down the line.
If you're just starting out and don't want to invest in an enterprise platform yet, Smartcat offers a free tier that handles basic TM creation and retrieval. It won't match the segmentation intelligence of Trados or MemoQ, but for under 5,000 segments and a small team, it's functional. Open-source alternatives exist too, though they require more technical configuration and don't have the same level of customer support. The open-source route makes sense if you have an in-house developer who can maintain the infrastructure. It doesn't make sense if you need someone to call when something breaks on a Tuesday morning. The bottom line is that translation memory is a long-term investment in linguistic consistency, not a quick fix for urgent translation needs. The first three to six months of building and curating your TM will feel slow. Match rates will be low. It will seem like you're spending more time preparing than actually translating. After that, the curve flattens and the savings compound. Projects that previously took two weeks start taking four days. Terminology drift drops to near zero. Onboarding new translators becomes significantly faster because they're working from an established reference base rather than starting from scratch. The initial friction is real, but the payoff is structural, not marginal.