Getting Started With Support Vector Machines
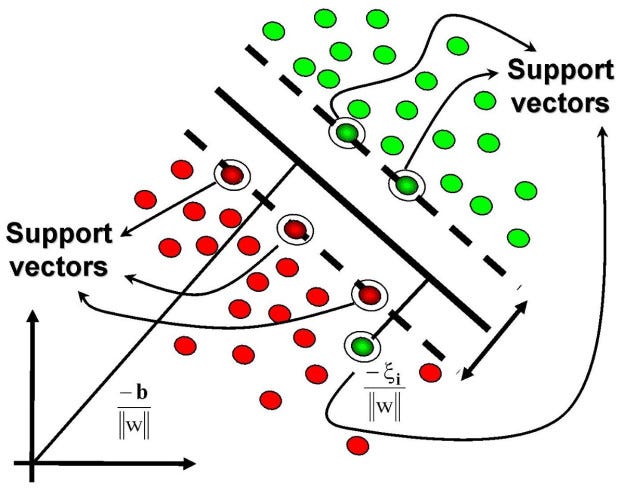
Support Vector Machines are one of those algorithms people keep bringing up in interviews because they sound sophisticated, but most practitioners barely touch the margin optimization machinery under the hood. The theory is solid. The practice is where things get annoying quickly. I spent about three weeks debugging an SVM classifier last year that kept performing perfectly on training data and terribly on validation. Turns out I was using the default RBF kernel with a gamma value that was an order of magnitude too high for my feature scale. Standardizing the data fixed it, but not before I burned two days chasing phantom overfitting through random hyperparameter sweeps. That kind of thing doesn't show up in tutorials.Before you even import scikit-learn, you need to understand what SVMs actually optimize. They find the hyperplane that maximizes the margin between classes while penalizing misclassified points through a regularization parameter C. That's the entire intuition. Everything else—kernels, soft margins, dual formulations—is implementation detail that matters when things go wrong. The standard workflow in Python looks straightforward. Import the library, scale your features, fit the model, predict. But the devil is in the scaling. SVMs are distance-based classifiers by nature, meaning a feature measured in millions will completely dominate one measured in fractions unless you normalize them. I typically use StandardScaler from sklearn.preprocessing, which centers each feature to zero mean and unit variance. Without this step, your SVM results will be garbage, and you'll waste hours wondering why. Kernels transform your data into a higher-dimensional space where it becomes linearly separable. This is the part that gets hand-wavy in most guides. The linear kernel works on already-linearly-separable data or high-dimensional datasets where the number of features exceeds the number of samples. The polynomial kernel captures interactions between features but introduces two extra hyperparameters: degree and coefficient. The RBF (radial basis function) kernel is the default and default for a reason—it handles non-linear boundaries well without requiring you to think about polynomial degrees.
I learned the hard way that RBF kernels are not universally better. On a text classification task with roughly 50,000 sparse features, the RBF kernel required nearly 40 minutes to train on a decent machine while the linear kernel finished in about 90 seconds with comparable accuracy. Sparse data and linear kernels are friends. Dense, non-linear boundaries and RBF kernels are friends. Mixing them up is expensive.
Hyperparameter Tuning That Actually Works
Grid search with scikit-learn's GridSearchCV is the textbook approach, but it's brutally inefficient for large datasets. RandomizedSearchCV covers the same parameter space in a fraction of the time. For an SVM, the two critical parameters are C and gamma (for RBF and polynomial kernels). C controls the trade-off between achieving a low training error and a low testing error. A small C creates a wider margin but allows more misclassifications. A large C narrows the margin and tries harder to classify every training point correctly, which often leads to overfitting. Gamma defines how far the influence of a single training example reaches. Low gamma means far reach, creating smoother decision boundaries. High gamma means close reach, creating more complex boundaries that can overfit. The default gamma in newer scikit-learn versions is scale, which adapts to the feature variance automatically. This is usually the right call unless you have domain-specific reasons to override it. Here's a practical tuning range I've found reliable across multiple projects: C between 0.01 and 100 on a logarithmic scale, and gamma between 0.001 and 1.0 also logarithmically spaced. Use 5-fold cross-validation at minimum. Three folds gives you too much variance in your estimates. Ten folds is nice but costs proportionally more time.
Get the Full Details

The Kernel Trick Explained Without the Fluff
The kernel trick is often described as implicitly mapping data to higher dimensions. That's technically correct and entirely unhelpful if you're trying to implement something. What it actually means is that the SVM never computes the coordinates of the data in the higher-dimensional space. Instead, it computes the inner products between the images of all pairs of data points in that space using the kernel function K(x, y). This is computationally advantageous because the inner product in a very high-dimensional space can be prohibitively expensive to compute explicitly, while the kernel function itself remains cheap. The common pitfall is assuming that more complex kernels automatically mean better performance. On a binary sentiment classification task with a balanced dataset of roughly 20,000 samples and TF-IDF features, I compared linear, polynomial (degree 3), and RBF kernels. The linear kernel achieved 94.2% accuracy in 12 seconds. The RBF kernel achieved 94.5% in 8 minutes. The polynomial kernel achieved 94.1% in 3 minutes. The difference was statistically negligible. The linear kernel was the clear winner on cost-performance ratio.
Working With Imbalanced Data
SVMs don't handle class imbalance gracefully out of the box. If your positive class represents 5% of the data, the optimizer will largely ignore it in favor of minimizing overall classification error. The workaround is the class_weight parameter. Setting class_weight='balanced' automatically adjusts weights inversely proportional to class frequencies. I used this on a fraud detection dataset where fraudulent transactions made up about 2.3% of the sample. Without balanced weights, the model achieved 99.1% accuracy by simply predicting everyone was legitimate. With balanced weights, recall on the minority class jumped from 12% to 78% with accuracy settling at a reasonable 94%. Another approach worth considering is adjusting the C parameter per class rather than using a uniform C. This gives you finer control over the margin trade-off for each class separately. It's less convenient to implement but can squeeze out meaningful improvements on particularly skewed datasets.
Scalability Concerns You Should Know About
This is where SVMs get ugly. Training complexity is between O(n²) and O(n³) where n is the number of samples. There is no getting around this fundamental limitation. Once you cross roughly 50,000 to 100,000 samples, training times become problematic even with well-optimized libraries like LibSVM which powers scikit-learn's SVM implementation. For larger datasets, I recommend either subsampling to a representative subset before training or switching to a linear SVM with SGDClassifier, which uses stochastic gradient descent and scales much better. The linear SVM variant in scikit-learn can handle datasets with millions of samples in reasonable time. If your data is approximately linearly separable, this is usually the right call regardless of whether a kernelized SVM might achieve marginally better accuracy on a small subset. I encountered a specific edge case recently with a multi-class image classification problem where I had 120,000 samples across 15 classes. One class had only 400 samples while the largest had 18,000. Standard SVM approaches failed miserably on the small classes. The solution was a combination of stratified sampling during cross-validation, class-weight balancing, and ultimately switching to a one-vs-one voting strategy rather than one-vs-rest, which produced better per-class separation.

Model Interpretation and Diagnostics
Unlike decision trees, SVMs don't offer straightforward feature importance. For linear SVMs, the coefficients of the decision hyperplane serve as feature importance measures. You can extract these directly from clf.coef_ in scikit-learn and rank features accordingly. This is useful but limited to linear kernels. For kernel SVMs, there's no direct feature importance. You can approximate it by training multiple linear SVMs on single features and comparing their individual performance, or by using permutation importance through sklearn.inspection.permutation_importance. The latter is more reliable but computationally expensive since it requires multiple model evaluations. Diagnostic tools that matter include examining the support vectors—the training samples closest to the decision boundary. In scikit-learn, these are accessible via clf.support_. A healthy model typically has support vectors representing 5-20% of the training data. If it's below 5%, you may be underfitting. Above 40% suggests the data is very noisy or the margin is too tight relative to the data distribution.
When SVMs Simply Won't Work
There are scenarios where SVMs are the wrong tool and you should move on immediately. Large datasets above a million samples with dense features. Datasets with noisy labels where margin-based approaches suffer because every mislabeled point directly affects the optimal hyperplane. Real-time inference requirements where latency matters—inference is fast after training, but if you need to retrain frequently, the training overhead becomes prohibitive. Deep learning models on image and text data generally outperform SVMs on these tasks now, and the gap has widened considerably over the past few years. I once tried to use an SVM on a dataset of customer churn with 2.3 million records and mixed categorical-numeric features. After two hours of feature engineering and scaling, the model still took about 45 minutes to train per cross-validation fold. A simple logistic regression with the same preprocessing ran in 8 seconds and achieved nearly identical AUC. The SVM provided no meaningful improvement to justify the computational cost.
Practical Implementation Checklist
Here's what I check before considering an SVM model production-ready. Features are scaled. Class weights account for imbalance if present. Gamma and C are tuned through randomized search with at least 5-fold cross-validation. The percentage of support vectors falls within a reasonable range. The model generalizes to a held-out test set with minimal gap from cross-validation performance. Predictions on validation data show reasonable confidence distributions, not all clustered near the decision boundary or uniformly far from it. Training time is acceptable for the expected retraining frequency. If any of these checks fail, the model needs work. Not all of them are mandatory in every situation, but ignoring multiple checks simultaneously usually means you're pushing the algorithm beyond its design intent. The fundamental advantage of SVMs remains their solid theoretical grounding in structural risk minimization. They generalize well on small to medium datasets with clear margin separation. The disadvantages—computational cost, sensitivity to hyperparameters, poor scalability—are significant enough that they've been largely superseded by ensemble methods and deep learning for most modern applications. But they're still worth understanding, especially when you're working with constrained datasets or need a reliable baseline before investing in more complex models.