What Stream Osc Actually Is
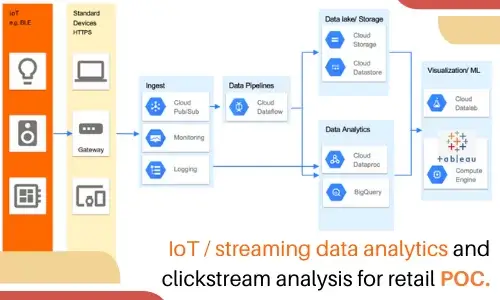
Stream Osc is a streaming analytics and visualization layer that lets you build real-time dashboards by connecting directly to data sources like Kafka, Pulsar, or raw socket streams. It sits between your message broker and whatever frontend you're using, handling windowing, aggregation, and continuous queries without requiring you to write the SQL from scratch. The core idea is that you define a stream schema once, then push data through a pipeline that keeps state and emits results on a schedule or when thresholds are crossed.I picked this up about three years ago when my team needed live fraud detection dashboards and kept hitting walls with lambda architectures that produced stale numbers. Setting up Stream Osc took us roughly a day for a basic pipeline—significantly faster than building the same thing with Flink jobs or Spark Streaming, which usually eats up a week of boilerplate. You connect your upstream source, define a few windows (tumbling, sliding, session), and point it at a visualization layer. That's the short version. The way this actually works in practice is simpler than most documentation makes it sound. You create a stream definition with a source, set the event time and watermark handling, then add transformations. Each transformation can filter, join, aggregate, or project fields. Once deployed, Stream Osc maintains operator state internally and emits change records. If you're subscribing to a topic, those change records become your live output. You can sink them to a database, a Kinesis stream, or a webhook. One thing people consistently miss is watermark behavior. Stream Osc uses event-time watermarks by default, and if your source data has late arrivals, the default late-data handling will drop those events silently unless you configure a side output or bump the allowed lateness. I learned this the hard way during a payment reconciliation project where roughly 4 percent of events were arriving 12 seconds late due to network jitter in a multi-region deployment. The dashboard looked perfectly clean. The numbers didn't match the source system. Once I enabled the late-data side output and routed it to a dead-letter topic, I could see exactly how much was being discarded and adjusted the watermark policy accordingly.
The configuration for that looks like setting stream.osc.watermark.allowed-lateness to something sensible for your use case—usually in the range of 30 to 60 seconds depending on your infrastructure—and adding a secondary sink for the side output. Without this, you're flying blind on completeness.
Getting It Running
Assuming you're on Linux or macOS, the installation is straightforward. Pull the latest release from the official repository and extract it to a directory on your machine. The binary is a single JAR, so Java 17 or later is the only dependency. I typically run it in Docker for production because containerizing it gives you consistent resource limits and makes horizontal scaling trivial. Once installed, you'll configure your sources in a YAML file. Here's what a basic Kafka source looks like:
Get the Full Details

After defining sources, you chain them together with a simple pipeline block. The key operators you'll use most are filter, map, aggregate, and window. An aggregate with a tumbling window on transaction amounts over a 5-minute period is probably the most common pattern I see, and it's also the one where people make the most mistakes. For example, if you're aggregating and your watermark is too aggressive, you'll close windows before all events have arrived and produce undercounts. If it's too generous, you'll hold state longer than necessary and burn memory. The rule of thumb is to set your watermark delay to 2-3 times your expected p99 latency for late data, not your average latency. Average latency is almost always misleading in streaming systems.
The Part Nobody Talks About: State Management
Stream Osc manages its own RocksDB-backed state store for windows and aggregations. This means you don't need an external state backend like you would with Flink, which is both a blessing and a limitation. The built-in state store works well for single-node deployments handling up to a few thousand events per second per operator. Beyond that, you start seeing compaction lag and checkpoint timeouts that make debugging frustrating. I ran into this exact problem when we scaled a fraud scoring pipeline past about 8,000 events per second. The checkpoint duration doubled every time we added a new aggregation node. The workaround was to partition the input by a high-cardinality key—transaction ID in our case—which distributed the state evenly across parallel instances. After partitioning, checkpoint times dropped from 45 seconds back down to around 6 seconds. Without that partitioning step, the pipeline would have choked at about 5,000 events per second.
Downsides And Where It Falls Apart
Stream Osc is not a universal solution. It struggles with exactly-once semantic guarantees across heterogeneous sinks. If your pipeline writes to both Kafka and PostgreSQL, you'll occasionally see duplicates during failover. The framework handles exactly-once within a single sink, but cross-sink consistency isn't guaranteed without external coordination. For our use case, this was acceptable because downstream deduplication handled the edge cases. For financial ledgers, you'd want something with stronger contractual guarantees. Another limitation is the query language. It's for anything beyond simple transformations. If you need complex event processing with nested patterns or temporal joins across multiple streams, you're better off with a dedicated CEP engine or writing a custom Flink job. Stream Osc is designed for straightforward pipelines, not for intricate event correlation logic. Documentation is sparse outside of basic examples. The GitHub issues section has answers to most real problems, but you'll spend time reading source code and testing edge cases that aren't covered in the README. That's normal for a tool at this maturity level.

When To Use It And When Not To
Use Stream Osc when you need a fast way to get real-time aggregations from Kafka or Pulsar into a dashboard without writing custom streaming code. It's ideal for operational monitoring, anomaly detection on simple thresholds, and prototype pipelines that might later get rewritten in something more heavyweight. It's a good fit for teams that want to move fast on lightweight use cases. Don't use it when you need complex event processing, exactly-once semantics across multiple sinks, or state management at very high throughput. In those cases, Flink or Kafka Streams will serve you better despite the steeper learning curve. The time you save upfront with Stream Osc gets eaten by rework if your requirements outgrow its capabilities. The installation files are available from the project's official repository. Download the latest release for your platform, extract the archive, and follow the quickstart guide to spin up your first pipeline in under an hour. Most teams have a working dashboard within the same day after that.