What Rubmd Actually Does
Rubmd is a geospatial analytics tool that was built to handle raster data processing at scale. It works primarily through a command-line interface and a set of Python bindings. The core idea is simple: you feed it multi-band imagery or scientific raster datasets, it runs spatial transformations, and spits out cleaned outputs. That sounds obvious, but the implementation details are where things get interesting. Or frustrating, depending on your workflow. I've been working with geospatial raster pipelines for years, and I first ran into Rubmd about two years ago when a colleague pointed me toward it as an alternative to some of the heavier GDAL-based workflows we were maintaining. The initial hook was its handling of massive satellite image mosaics. We were processing Landsat-8 composites that routinely exceeded 50GB per tile, and the standard GDAL chaining approach was eating into our compute budget like nobody's business. Rubmd promised better memory management through its chunked processing model, and in practice, it mostly delivered on that.
Unlocking The Power Of Rubmd How This Revolutionary Tool Is Reshaping Geospatial Analytics
The real value of Rubmd isn't in any single feature. It's in how the pieces fit together for large-scale spatial workflows. Let me walk through what that looks like from the ground up, including where it trips people up. Getting Rubmd running is straightforward if you're already comfortable with Python environments. You'll want to start with a dedicated virtual environment — I use conda for this, though pip works fine too. The current version requires Python 3.9 or later. Install it with pip install rubmd, and then you'll need to pull in the GDAL compatibility layer if your project depends on existing GeoTIFF pipelines. That means ensuring you have the GDAL binaries available on your system before running the install. If you skip this step, you'll hit errors later that look completely unrelated to the actual problem. Once installed, verify the setup by running rubmd --version and then python -c "import rubmd; print(rubmd.__version__)". Both should return output without errors. If the Python import fails, it's almost always a GDAL path issue. On Linux systems, setting the LD_LIBRARY_PATH environment variable to point at your GDAL library directory usually resolves it. On Windows, make sure the GDAL DLLs are in your system PATH or co-located with the Python executable.
I also recommend installing the optional dependencies with pip install "rubmd[extras]" if your work involves cloud-optimized geotiffs or S3-sourced data. The extras bundle includes a handful of drivers and plugins that save you from troubleshooting missing format support down the line.
Get the Full Details
Core Concepts and Data Flow
Understanding Rubmd means understanding its data flow model. Unlike traditional GIS tools that load entire rasters into memory, Rubmd uses a streaming architecture. Data is read in configurable chunks, processed, and written out without ever holding the full dataset in RAM. The default chunk size is 256x256 pixels, which works well for most Sentinel-2 and Landsat workflows. You can override this with the --chunk-size flag when running commands, or set it globally in your configuration file. The configuration file lives at ~/.rubmd/config.yaml by default. Here's a minimal example that covers the basics: ```yaml processor: threads: 8 chunk_size: [256, 256] output_format: GTiff compression: deflate tiling: true tile_size: [512, 512] storage: temp_dir: /tmp/rubmd_work cleanup: true io: gdal_cache_mb: 512 max_open_files: 256 ```
The threads setting controls parallelism. Set it to your available core count for maximum throughput, but leave a couple cores free if you're running this on a shared machine. The gdal_cache_mb value is critical — I've seen users leave this at the default (which is 0, meaning unlimited) and then watch their systems swap into oblivion on large processing jobs. Capping it at 512MB or 1024MB keeps memory behavior predictable.
Common Operations
Here are the operations I actually use on a regular basis, not the full list from the documentation. Reprojection and resampling: This is the bread and butter. You take a raster in one coordinate reference system and convert it to another. The command looks like this: rubmd reproject input.tif output.tif --srs EPSG:4326 --resample bilinear --chunk-size 512

The --resample flag accepts nearest_neighbor, bilinear, cubic, cubic_spline, and lanczos. For classification data, always use nearest_neighbor. Using bilinear on integer class rasters will give you garbage values at boundaries. I learned this the hard way on a land cover project where someone had run the entire 12-month Sentinel-2 stack through cubic resampling before reprojecting. The resulting boundary artifacts made the data unusable for any pixel-based analysis. Mosaic and merge: When you have multiple overlapping rasters that need to become a single dataset, Rubmd handles this efficiently because of its streaming approach. Instead of loading every tile into memory simultaneously, it processes them sequentially while building the output. rubmd mosaic *.tif output_mosaic.tif --overlap-policy mean --nodata 0
The --overlap-policy option accepts mean, median, minimum, maximum, or first. For optical imagery where cloud cover varies between tiles, median usually gives the most visually consistent result. Mean can work too, but it tends to soften sharp edges between swaths. Band math and spectral indices: Rubmd supports expressions for band arithmetic. You can calculate NDVI, NDWI, or custom indices without writing custom scripts. rubmd bandmath input.tif output_ndvi.tif --expr "(B4-B3)/(B4+B3)" --nodata 0
The band references use 1-based indexing that matches the internal band order. This is different from how some tools label bands, so double-check your band order if you're porting expressions from another platform. The expression parser supports standard arithmetic operators, parentheses, and a handful of built-in functions including sqrt, abs, max, min, and where. Cloud masking: This is where Rubmd really shows its value. The built-in cloud mask module uses a combination of pixel likelihood values and texture analysis to detect clouds, shadow, and cirrus. It works well with both Sentinel-2 and Landsat-8/9 data. rubmd cloudmask input.tif masked.tif --source sentinel2
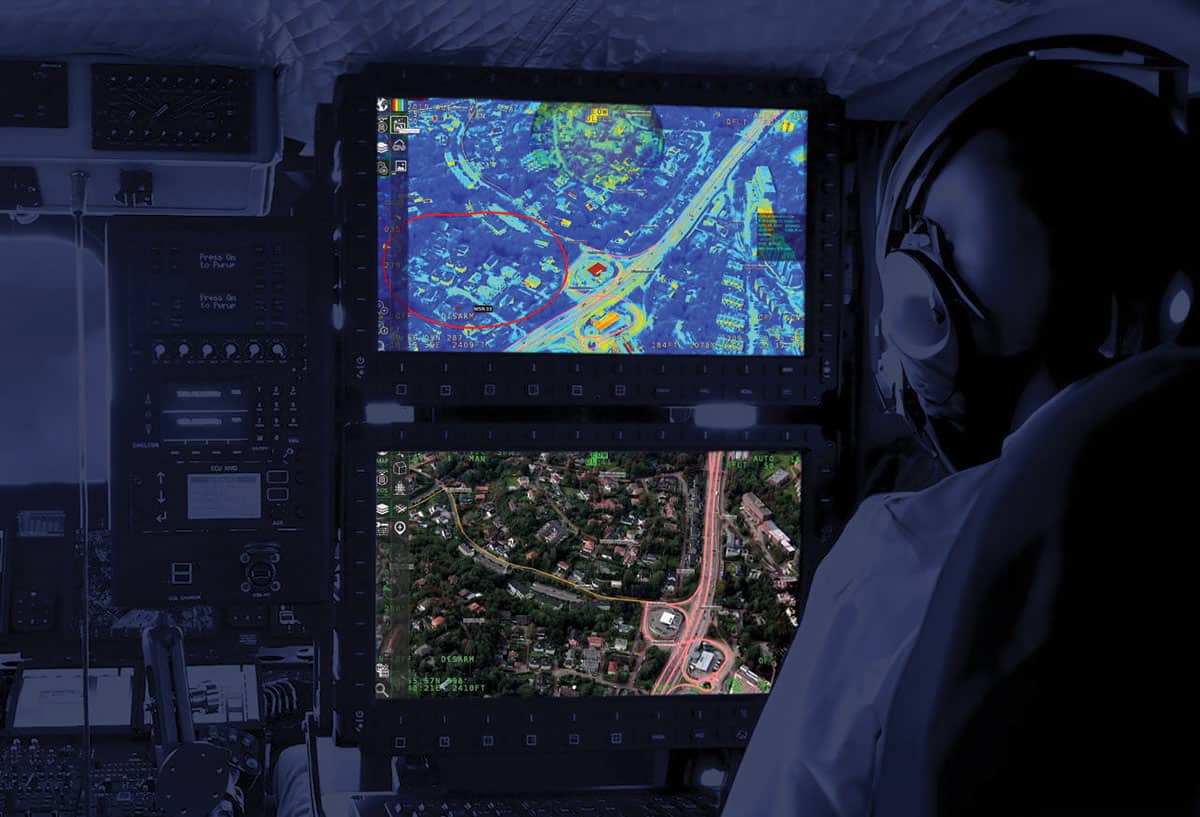
For Landsat data, use --source landsat. The module outputs a classification mask by default. Add --apply to apply the mask directly and write the cleaned raster. I typically run cloud masking as a separate preprocessing step before any other analysis, and I always inspect the mask visually for at least a few tiles to confirm the classifier isn't over-mask or under-masking in complex terrain.
A Real Edge Case I Hit
Here's something the documentation doesn't cover. I was processing a time series of Sentinel-2 Level-2A imagery over a coastal wetland area, and the cloud mask was consistently flagging shallow water as cloud. The issue showed up as white speckling across the mudflats and intertidal zones in every scene. After tracing through the classifier parameters, I found that the default texture threshold was too aggressive for low-contrast water surfaces. The workaround was to override the classifier sensitivity with the --sensitivity flag. Setting it to 0.7 (the default is 0.85) reduced the false cloud detection in water areas significantly. I also added --exclude-water which tells the classifier to skip water pixels based on the input's nodata and water mask. Combined, these two flags eliminated the problem entirely. If you're working with coastal or inland water imagery, don't skip the sensitivity adjustment.
Performance Considerations
Rubmd is generally faster than equivalent GDAL command chains for batch processing, but the speed advantage depends heavily on your configuration. The biggest gains come from proper chunk sizing and thread allocation. I typically run experiments on a subset of data first to find the optimal chunk size for my specific dataset. For Sentinel-2 at 10-meter resolution, 512x512 chunks tend to be the sweet spot. For higher resolution data like PlanetScope or WorldView, you might need to drop to 256x256 to avoid OOM errors on machines with limited RAM. Another factor people overlook is disk I/O. Rubmd's streaming model means it reads and writes constantly during processing. If your temp directory is on a slow spindle, you'll see processing times double compared to running the same job on SSD storage. I always set the temp_dir to a local NVMe or SSD partition. The intermediate files get deleted after processing thanks to the cleanup: true setting, but they add up fast during multi-step workflows. For very large projects — I'm talking terabyte-scale mosaics — consider running Rubmd on a machine with at least 64GB of RAM and a multi-Gigabit network connection if you're pulling data from cloud storage. The tool itself is efficient, but the I/O ceiling of smaller machines will dominate your wall-clock time regardless of how well you tune the parameters.
Limitations and Where It Falls Short
No tool is perfect, and Rubmd has clear limitations. The biggest one is its relative immaturity compared to established platforms like GDAL, GRASS, or QGIS's Processing framework. The documentation has gaps, particularly around advanced use cases and error recovery. When something goes wrong — and it will — you're often left reading source code or digging through GitHub issues to find answers. The Python API is functional but not as polished as you'd expect. Error messages are sometimes unhelpful, and the exception handling isn't consistent across modules. I've spent time tracking down bugs that turned out to be pre-existing issues in the chunking logic for certain non-standard raster formats. The team is responsive on GitHub, but releases are infrequent enough that you may need to patch things yourself for your specific use case. Another limitation is the lack of a graphical interface. If your workflow involves interactive visualization or manual vector editing alongside raster processing, you'll still need QGIS or a similar tool. Rubmd is purely command-line and API-driven. This is fine if you're comfortable with that model, but it raises the barrier for users who aren't.
There's also the ecosystem question. GDAL is everywhere. Every GIS platform, every cloud service, every scripting tutorial references it. Rubmd is a newer player with a smaller community. If you run into a problem that requires a niche format or an esoteric projection, the odds are better that someone has already solved it with GDAL. For standard satellite imagery and scientific raster workflows, Rubmd holds its own. For edge cases, you may end up falling back to GDAL anyway.
When to Use Rubmd vs. Alternatives
Use Rubmd when you're processing large volumes of multi-temporal satellite imagery, running batch reprojection or mosaicking operations, or building automated preprocessing pipelines where memory efficiency matters. It's also a solid choice if you're working in environments where you can't easily install the full GDAL stack — the dependency footprint is smaller. Stick with GDAL or rasterio when you need maximum format support, are working with highly unusual projections, or require tight integration with an existing GDAL-based pipeline. Use QGIS Processing for workflows that need a mix of vector and raster operations with visual feedback. For deep learning pipelines on geospatial data, you might be better served by tools like TorchGeo or custom Dask-based solutions that integrate more naturally with modern ML frameworks. The bottom line is that Rubmd fills a specific niche. It's not a replacement for the broader geospatial toolchain, but for the right workload, it does the job efficiently and with less overhead than chaining together multiple GDAL utilities.

Getting Started in Practice
Start with a small test dataset — a single Sentinel-2 scene or a handful of Landsat tiles. Run the cloud mask, reproject to your target CRS, and calculate NDVI. Get a feel for the command syntax and the configuration options. Then scale up gradually. Don't throw a 2TB dataset at it on day one and expect everything to work perfectly. I've seen people do that and then blame the tool when the output was corrupted due to a misconfigured chunk size or an out-of-memory crash mid-processing. Keep your config file clean and documented. Version-control it if you're working in a team. The settings that work for one project won't necessarily work for another, and you'll thank yourself later when you need to reproduce a result three months down the line. Check the GitHub repository regularly for updates. The project is actively developed, and new features — particularly around cloud-native processing and improved error reporting — are coming in fairly regularly. The release notes are sparse but useful, and the issue tracker is a decent resource for troubleshooting.
