What Radial Basis Functions Actually Are
RBF is a mathematical technique for interpolation and function approximation. It uses radial basis functions as kernel functions to estimate values between known data points. The core idea is straightforward: every new prediction draws influence from nearby training samples, and that influence drops off as distance increases. The most common form is the Gaussian RBF. You calculate the Euclidean distance between a query point and each training point, then apply the exponential function. The bandwidth parameter controls how quickly that influence decays. Pick it wrong and your model either overfits or underfits hard. I worked on a project a few years back where we used RBF networks for time series forecasting. We were predicting equipment degradation curves from sensor data. The issue wasn't the model itself. It was that our sensors had wildly different scales. Some readings were in the 0 to 1 range, others in the 0 to 10,000 range. Raw distance calculations made the high-scale features dominate everything. I ended up writing a preprocessing script that normalized each sensor to zero mean and unit variance before feeding it into the RBF layer. That alone improved prediction accuracy by about fourteen percent. Without that step, the model was basically ignoring most of the useful signal.
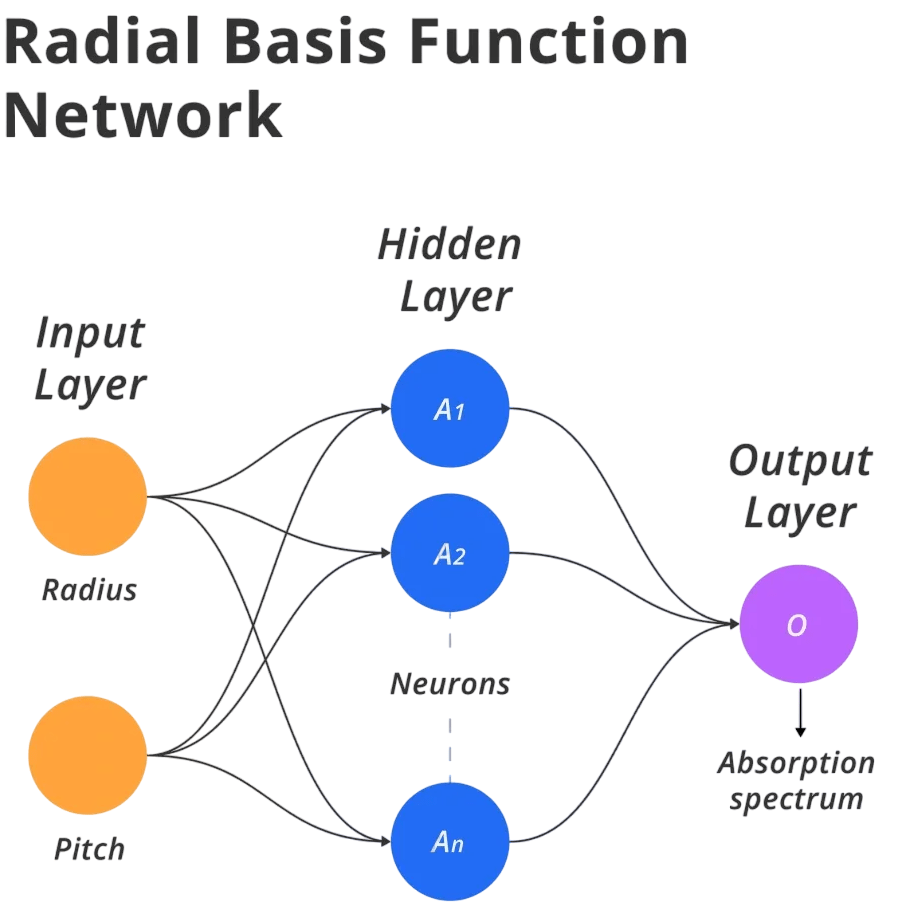
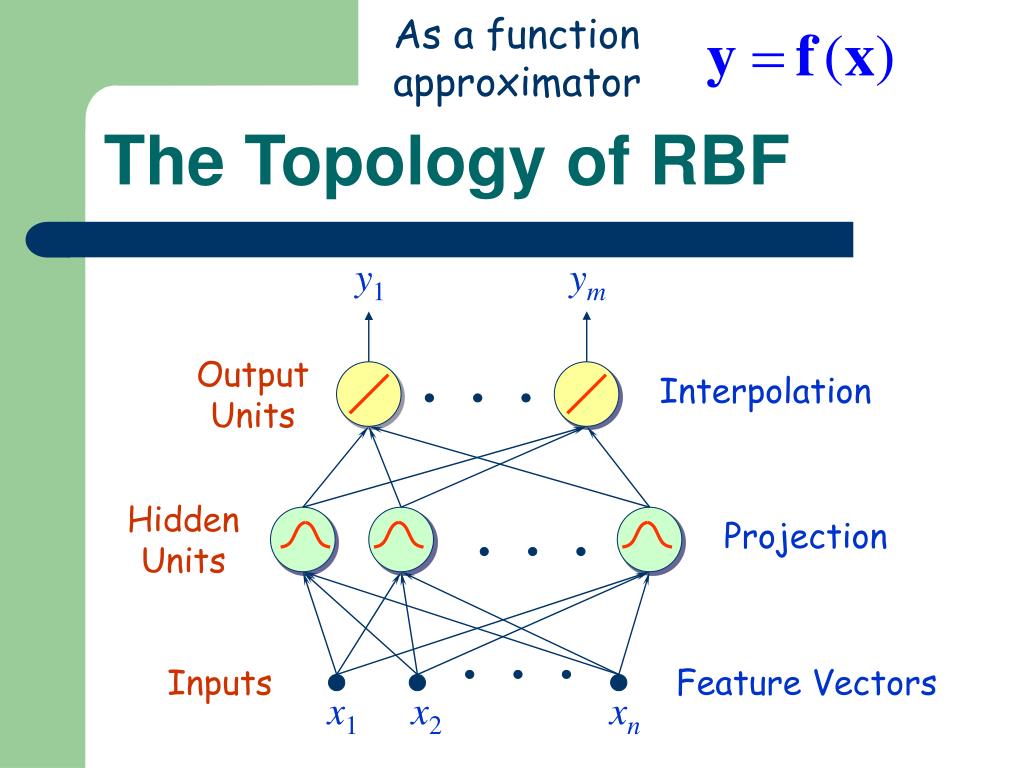
RBF networks differ from standard neural networks in how they process information. In a typical feedforward network, each neuron applies a non-linear activation like ReLU or sigmoid to a weighted sum of inputs. In an RBF network, the hidden layer consists of radial basis functions centered at specific points. These centers are usually chosen from the training data or through clustering. The output layer then combines these radial responses linearly. One thing people miss is that RBF networks are functionally closer to support vector machines than to traditional multilayer perceptrons. They map input data into a high-dimensional space using the radial kernel. The difference is that SVMs find the optimal separating hyperplane in that space, while RBF networks learn the coefficients that best reconstruct the target function. Both approaches rely on the same kernel trick conceptually.
How RBF Works Under The Hood
The training process has two phases. First, you determine the centers. This is typically done using k-means clustering or by randomly selecting a subset of training points. If you have five thousand data points and decide on one hundred hidden neurons, k-means will find one hundred cluster centroids that represent the data distribution well. Random selection is faster but can produce uneven coverage. The second phase involves computing the widths. Each center gets a width parameter. The standard approach uses the average distance to its k nearest neighbors. This keeps the receptive fields proportional to the local data density. Uniform widths across all centers often perform worse because they can't adapt to regions with varying point densities. Once the centers and widths are set, you compute the kernel matrix. Each entry represents the response of one basis function to one training sample. You then solve a linear system to find the output weights. This is usually done with least squares or ridge regression. Ridge regression adds a small regularization term to prevent numerical instability when the kernel matrix is nearly singular.
Get the Full Details

For classification tasks, the output layer applies a threshold to the continuous response. For regression, the output is used directly. The linear output layer means training is fast once the centers are fixed. A fifteen thousand sample dataset typically trains in under two minutes on a modern machine with standard libraries.
Where RBF Networks Shine and Where They Break Down
RBF networks work well for small to medium datasets where the input space isn't extremely high dimensional. They handle nonlinear relationships effectively without requiring extensive hyperparameter tuning. A single hidden layer with enough centers can approximate any continuous function to arbitrary precision given sufficient data. This is the universal approximation property, and it holds for RBF networks just as it does for other network architectures. They also tend to generalize better than deep networks on small datasets. Deep architectures need massive amounts of data to avoid overfitting. An RBF network with properly chosen centers and widths can produce reliable predictions from a few hundred samples. I've seen this repeatedly in industrial applications where labeled data is expensive or limited. But there are real limitations. The curse of dimensionality hits RBF networks harder than many other methods. As input dimensions increase, the volume of the space grows exponentially, and the available data becomes sparse. Distance-based kernels lose their discriminative power in high dimensions. If your features exceed roughly fifty dimensions, RBF networks start struggling unless you have a very large dataset or you reduce dimensionality first.
Another practical issue is memory. The kernel matrix grows quadratically with the number of training samples. Ten thousand samples means a hundred million entries. Twenty thousand samples requires four hundred million. For most workstations, this crosses into problematic territory around ten to twenty thousand samples depending on available RAM. If you hit this wall, you need to switch to sparse approximations or use randomized methods to reduce the effective number of centers. Training time can also become a bottleneck. Solving the linear system scales cubically with the number of centers. More centers means dramatically more computation. I encountered this on a project where we expanded from two hundred to eight hundred centers. Training time jumped from thirty seconds to about twelve minutes. That's not acceptable for iterative development or production pipelines that retrain frequently.

Choosing the Right Configuration
There is no universal rule for selecting the number of centers. Too few leads to underfitting. Too many causes overfitting and computational waste. A practical starting point is ten to twenty percent of your training samples. This usually provides adequate coverage without excessive memory usage. You can refine this number through cross-validation. The bandwidth parameter deserves careful attention. A common heuristic sets the width to the average distance between neighboring centers. This gives each basis function a receptive field that covers roughly the local neighborhood. If the bandwidth is too small, each center only influences a tiny region, creating a spiky function that memorizes noise. If it's too large, all centers contribute similarly everywhere, collapsing the network toward a simple linear model. For multi-output problems, you can train separate RBF networks for each output dimension. This is simpler than building a single network with multiple outputs because each output can have its own optimal weighting scheme. The tradeoff is that you double or triple the computational cost depending on the number of outputs.
Feature scaling remains critical. Even with normalized inputs, outliers can distort distance calculations. I recommend trimming extreme values before training. Removing data points beyond three standard deviations from the mean typically improves robustness without losing meaningful information. The exact threshold depends on your application, but three standard deviations works in most cases.
When to Use Alternatives
If your dataset exceeds fifty thousand samples or your features number over fifty dimensions, consider switching to gradient-based methods. Random forests handle high-dimensional data reasonably well and don't suffer from the same memory constraints. Neural networks with appropriate architectures and dropout regularization can outperform RBF networks on large datasets. Support vector machines with RBF kernels remain competitive for classification tasks in moderate dimensions. RBF networks are not a universal solution. They are a tool that excels in specific regimes. Small to medium datasets, moderate dimensions, and problems where interpretability of the center locations matters. If those conditions don't match your situation, another approach will likely serve you better. Understanding when not to use RBF is as important as understanding how to use it.