
Probability and statistics are tools most people misuse without realizing it.
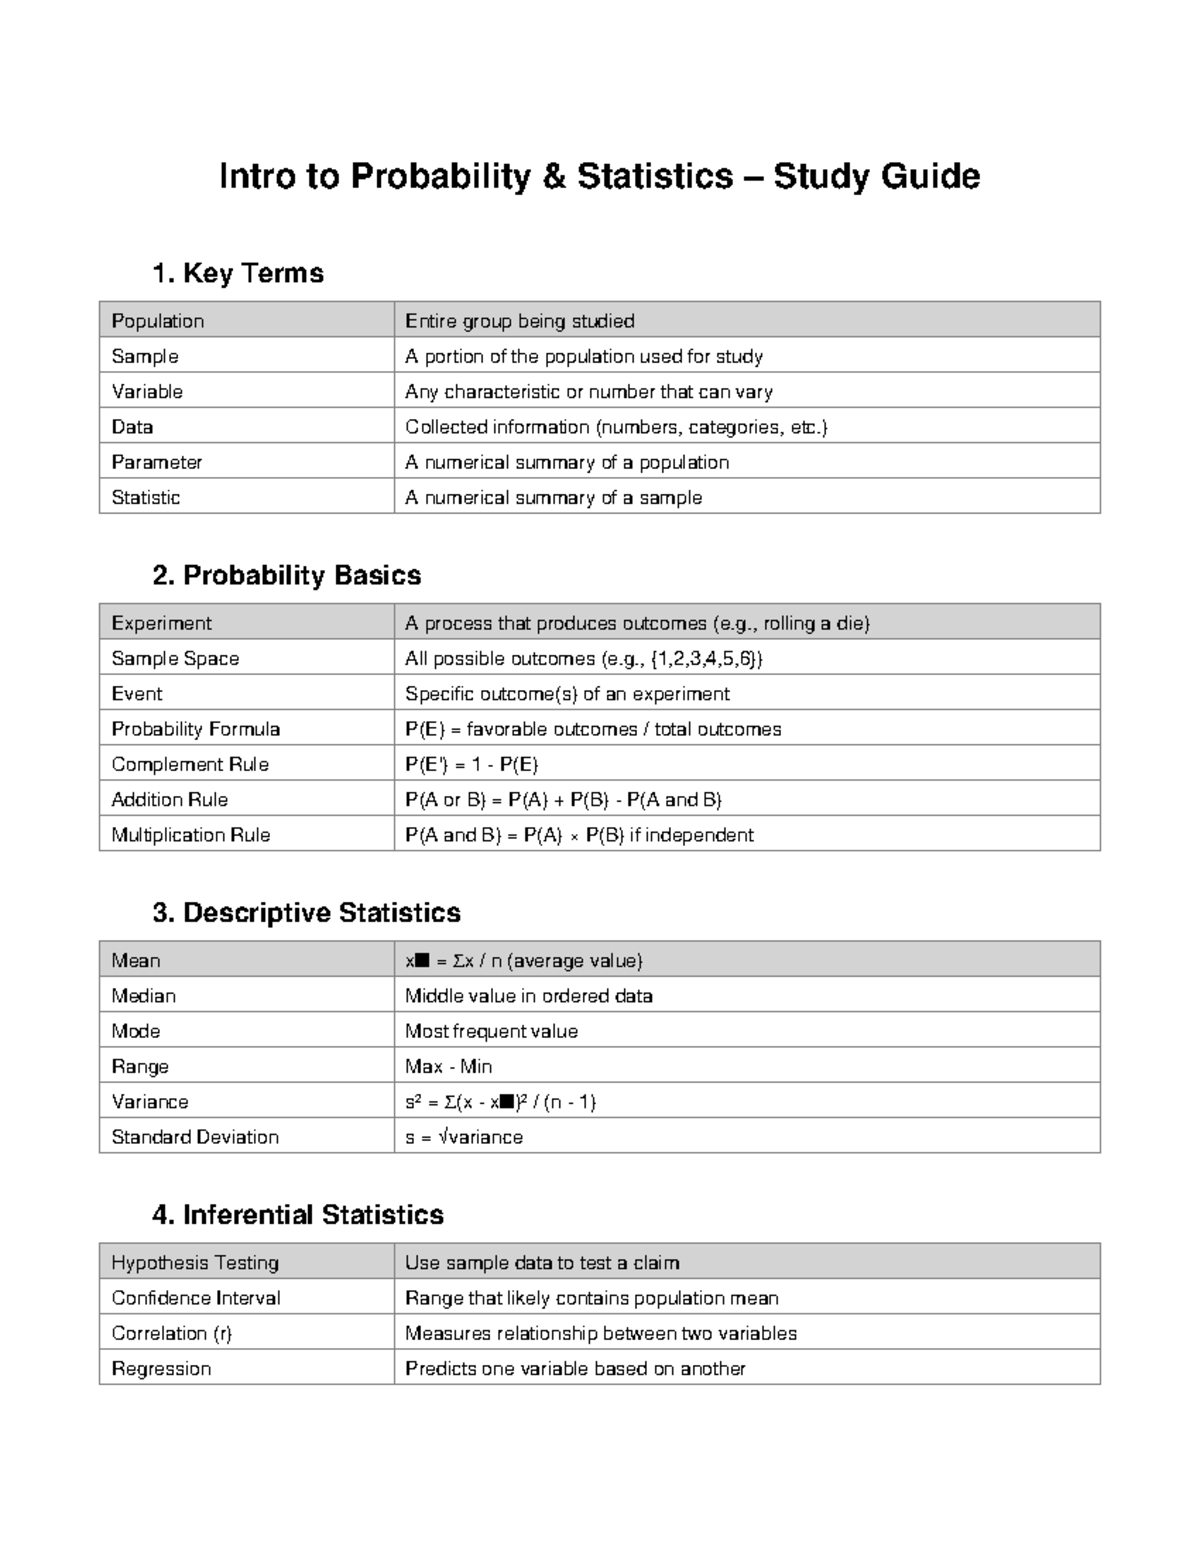
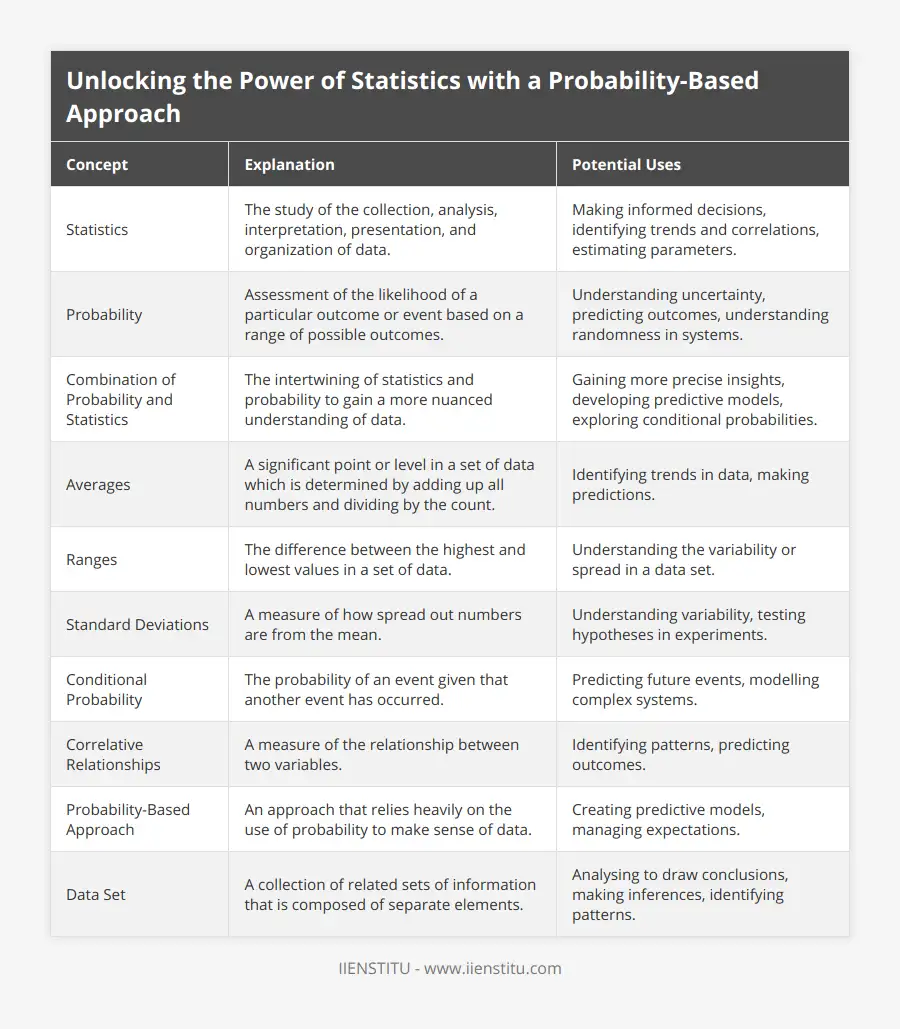
I spent years working with actual datasets instead of textbook examples. You'd be surprised how often the clean assumptions don't hold. A lot of people learn the formulas, pass the course, and then proceed to misinterpret their results in completely confident ways. Understanding probability and statistics isn't really about memorizing the normal distribution or knowing when to use a t-test. It's about developing an intuition for what the numbers are actually telling you and, more importantly, what they're lying to you about. Most introductory courses start with definitions. They tell you what a random variable is before showing you why it matters. That's backwards. I learned to think about probability as conditional statements first. Every probability you calculate is really P(A | B) — the probability of A given B. The vertical bar is the most important character in all of statistics. People forget it. They report P(A) as if it exists independently of whatever conditions created the data. Let me give you a specific example from my own work. A few years back I was analyzing failure rates for a component in a manufacturing process. The initial dataset came from a production run that ran smoothly for three weeks. The calculated defect rate was 0.3 percent, which looked great. Then we had a supplier change mid-month, and the defect rate jumped to 4.1 percent. The problem wasn't that I had calculated the wrong probability. The problem was that I had treated the first observation as representative when it was actually conditional on a specific set of operating parameters that no longer held. The real insight was recognizing that P(failure | machine settings version A) and P(failure | machine settings version B) are completely different probabilities, and collapsing them into a single number was meaningless.
This happens everywhere. Medical studies pool patients with different characteristics and report one outcome rate. Financial models assume volatility is constant when it clearly isn't. You don't need fancy methods to fix this. You just need to ask what conditions the probability is conditioned on and whether those conditions still apply.
The frequentist and Bayesian divide is more pragmatic than philosophical
Textbooks present these as competing worldviews. In practice, everyone uses a bit of both. Frequentist methods give you p-values and confidence intervals. Bayesian methods give you posterior distributions and credible intervals. The choice between them usually comes down to sample size and what you need the analysis to do. With large samples, frequentist and Bayesian results converge. The difference becomes academic. With small samples, the choice is critical. Frequentist methods with n less than 30 per group are often unreliable unless the data are perfectly behaved. Bayesian methods with weakly informative priors can still produce reasonable estimates in those situations, but they require you to specify the prior explicitly. That's not a weakness. It's a feature that forces you to state assumptions you would otherwise hide. Here's a practical rule I use. If I'm doing an exploratory analysis with decent sample sizes, I run frequentist tests because they're faster and the output format is standardized. If I'm dealing with sparse data, sequential monitoring, or updating beliefs as new information arrives, I switch to a Bayesian framework. Hierarchical Bayesian models are particularly useful when you have multiple groups with different sample sizes. They handle the variation between groups automatically through partial pooling. A standard ANOVA would either overfit the group-level differences or pool them entirely. The hierarchical approach sits between those two extremes.
Get the Full Details
Distributions are tools, not destinations
Students spend weeks learning the properties of the normal, binomial, Poisson, and exponential distributions. That's useful. But the real skill is recognizing when the standard distributions fail and what to use instead. The normal distribution assumes symmetry and finite variance. Real data rarely satisfies both. Income data is right-skewed. Reaction times are right-skewed. Count data with many zeros violates Poisson assumptions. Financial returns exhibit fat tails that the normal distribution severely understates. When the normal approximation breaks, you have options. Generalized linear models handle non-normal distributions through link functions. The Poisson or negative binomial regression handles count data. The beta regression handles proportions bounded between zero and one. The Gamma distribution handles right-skewed continuous data. You don't need to derive the likelihood functions from scratch. Statistical software handles the mechanics. You need to understand which distribution matches the data generating process. I remember working on a project involving time-to-event data where the hazard rate wasn't constant. The standard exponential model was completely wrong for this situation. The survival curve showed a decreasing hazard over time, which meant early failures were more likely. A Weibull model with a shape parameter less than one fit the data much better. The difference in predicted median survival time between the two models was roughly 18 percent. That's not a trivial discrepancy when you're making decisions based on those estimates.
What p-values actually mean and how easily they mislead
A p-value of 0.05 does not mean there is a 5 percent chance the null hypothesis is true. It does not mean there is a 95 percent chance the alternative is correct. It means that if the null hypothesis were true, you would observe data this extreme or more extreme in 5 percent of repeated experiments. That's it. The misinterpretation is so common that statistical organizations have published position statements about it. The bigger problem is p-hacking. When you test enough hypotheses or try enough model specifications, you will find statistically significant results by chance alone. A study that tests 20 independent hypotheses at alpha = 0.05 has roughly a 64 percent chance of producing at least one false positive. That calculation assumes independence, which is rarely true in practice. Real datasets have correlated variables, which makes the effective number of tests hard to determine. The Bonferroni correction is conservative but simple. Divide your alpha level by the number of comparisons. If you make 10 comparisons, use alpha = 0.005 instead of 0.05. The false discovery rate approach proposed by Benjamini and Hochberg is less conservative and more commonly used in modern research. It controls the proportion of false positives among rejected hypotheses rather than the family-wise error rate. Both methods reduce power. That's the tradeoff. You either accept more false positives or you lose the ability to detect real effects.
Causal inference is where most people get stuck
Probability describes relationships. Statistics quantifies uncertainty. Causal inference asks whether changing X actually changes Y. Observational data can suggest causation, but correlation alone never proves it. Confounding is the standard problem. A third variable influences both the exposure and the outcome, creating a spurious association. Randomized controlled trials are the gold standard because randomization balances confounders on average. But you can't always randomize. Sometimes the data are observational. In those cases, you need methods like instrumental variables, regression discontinuity, or propensity score matching. Each method has specific assumptions that must hold for the causal estimate to be valid. Violating those assumptions produces biased estimates that look precise. I encountered this directly when analyzing the effect of a training program on employee performance. The raw comparison showed a 12 percent improvement for participants. But employees who volunteered for the program were already higher performers. The selection bias was substantial. After matching on pre-program performance metrics and tenure, the estimated effect dropped to 4 percent. The direction was correct but the magnitude was five times smaller than the naive analysis suggested. That's the kind of gap that decision-makers miss when they only look at unadjusted numbers.
Common pitfalls that waste time and credibility
Multiple testing without correction. Treating missing data as random when the mechanism is clearly not random. Assuming linearity when the relationship is monotone but curved. Using point estimates without acknowledging uncertainty. Publishing only significant results while filing away non-significant findings. These are not edge cases. They are routine practices that corrupt entire fields of research. Another frequent mistake is confusing statistical significance with practical significance. A treatment effect of 0.01 percent might be statistically significant with a large enough sample, but it has no meaningful impact in practice. Conversely, a large effect with a small sample might not reach statistical significance, and the study gets dismissed. Both errors are common. The solution is to report effect sizes with confidence intervals and interpret them in the context of the domain, not just against an arbitrary alpha threshold.
Software choices matter less than understanding
R, Python with scipy and statsmodels, Julia, SAS, SPSS. Pick the one your team knows. The statistical results will be numerically equivalent across well-implemented packages. What matters is whether you understand what the code is doing. Writing a script that runs a linear regression is trivial. Understanding what the coefficients represent, what assumptions underlie the inference, and what diagnostics to check is the actual work. For Bayesian analysis, I use Stan through rstan or cmdstanr. The sampling-based approach is computationally intensive but produces accurate posterior distributions even for complex hierarchical models. For frequentist work, the broom package in R turns model outputs into tidy data frames, which makes it easier to automate comparisons across many models. I also keep a personal library of diagnostic plots for residuals, leverage, and influence. Standard textbooks cover these. People rarely check them.
Where probability and statistics break down
No method handles deliberate data fabrication. No statistical test compensates for a fundamentally flawed research question. No amount of sophisticated modeling fixes biased sampling frames. If your data collection process systematically excludes certain populations, your analysis will produce precise but wrong answers. Black swan events are another limitation. Fat-tailed distributions mean extreme outcomes occur far more frequently than normal-theory models predict. Risk assessments based on historical variance often underestimate tail risk. The 2008 financial crisis and subsequent market events demonstrated this repeatedly. Models that assumed normal returns and constant correlations produced confidence intervals that proved wildly inadequate. This doesn't mean statistics is useless. It means you need to stress-test your assumptions against scenarios that your historical data never contained.
Building actual intuition takes deliberate practice
Work with messy data. Run simulations to see how estimators behave under different conditions. Plot everything before you summarize it. Read the original papers, not just the secondary summaries. Replicate published results when possible. These habits won't make you immune to errors, but they will make you more aware of where errors are likely to hide. Probability and statistics are not about finding truth through computation. They are about quantifying uncertainty in a disciplined way. The discipline is the valuable part.


