
Payment Gateway Architecture Breakdown
The way payment gateways actually process transactions under the hood is something most teams I talk to still don't understand well enough. They plug in a third-party SDK, throw it at a staging environment, and hope for the best. That approach works until it doesn't, and then you're sitting at 2 AM with a failed settlement batch and no idea which hop in the chain broke. I spent about three years building custom gateway integrations for a mid-market e-commerce platform before moving into architecture consulting. The patterns are fairly consistent across providers, but the failure modes are not.
Unlocking The Power Of Payment Gateway Architecture The Key To Seamless Transaction Processing
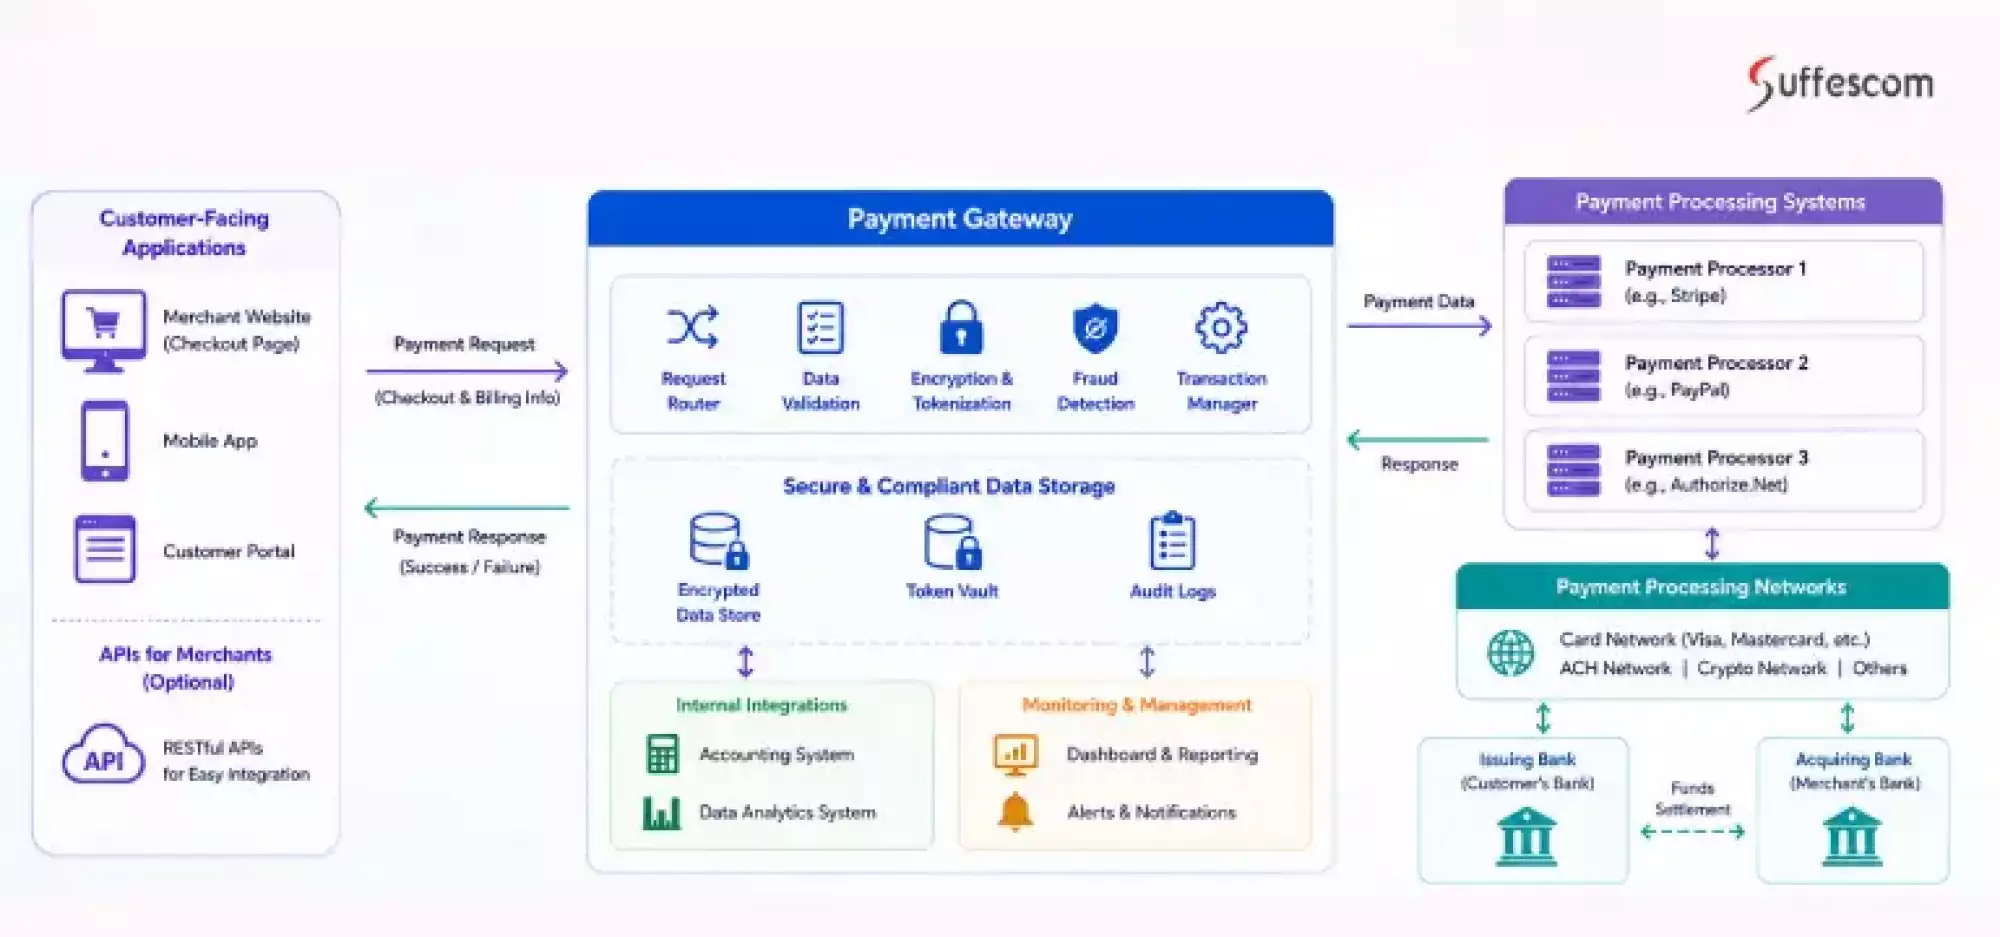
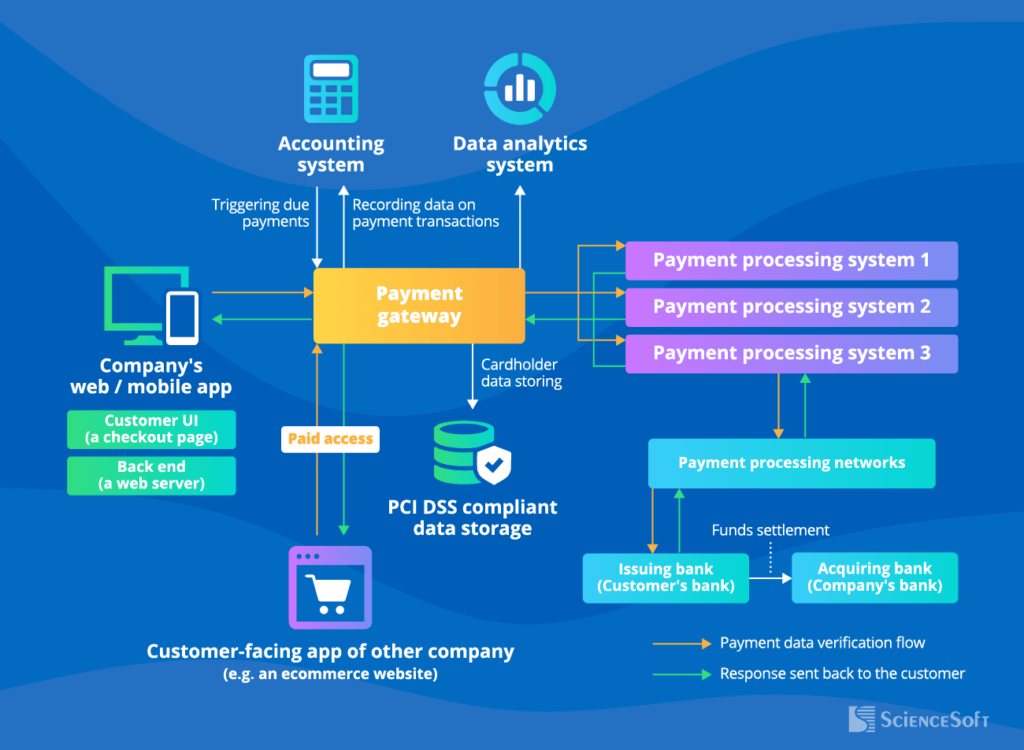
Let's get into how the pieces actually connect. A payment gateway sits between your application and the acquirer bank. When a customer clicks "pay," your app sends the transaction data to the gateway over HTTPS. The gateway tokenizes or passes that data through to the card network (Visa, Mastercard, etc.) via the acquirer. The issuing bank responds with an authorization response code. The gateway relays that back to you. Simple in theory. The architecture around it determines whether it works reliably under load or falls apart. The core components are the request router, the tokenization layer, the fraud screening engine, the reconciliation service, and the settlement processor. Each one is a potential bottleneck if you don't size it correctly. Here's a common setup I see documented incorrectly all the time. The merchant server initiates a payment_intent creation, the gateway returns a client token, the frontend uses that token to submit card details directly to the gateway API, and the gateway posts back a webhook when the transaction completes. That flow sounds right on paper but the error handling is where everything usually breaks.
I once had a client whose webhook endpoint was only logging 401 responses, not the actual payload. Their gateway had switched to HMAC-signed webhooks without updating the merchant docs. They were silently failing about 3% of their orders for six months because the auth check was rejecting valid webhooks from a subset of the gateway's regional nodes. I found it by comparing their internal order count against the gateway's reported transaction volume and noticing the gap matched the exact rejection pattern in the error logs. The fix was adding secondary signature validation on the webhook handler and a daily reconciliation job that flagged any mismatch above 0.5%. The reconciliation piece is where most architectures are weakest. You need a system that runs every hour comparing your database records against the gateway's settlement reports. Most teams skip this because it's boring infrastructure work. That's exactly why it's critical.
Get the Full Details
Architecture Patterns and Trade-offs
There are two main architectural approaches here. The first is a synchronous pass-through model where your gateway simply forwards requests to the processor and relays the response. This is faster to implement and cheaper to run but gives you almost no visibility into what's happening mid-flight. If the processor times out, your gateway times out with it, and you have no fallback. The second approach is a semi-synchronous queued model where transactions enter a message queue before hitting the processor. This gives you retry logic, dead letter queues, and better observability. The trade-off is added latency, usually 200 to 800 milliseconds depending on your queue depth and consumer scaling. For most high-volume merchants, the queued model is worth the latency hit because you can actually debug failures when they occur. A third option exists for enterprise setups: a polyglot architecture where different payment flows use different gateways routed by payment method, region, or risk score. I built one of these for a cross-border marketplace. We routed domestic cards through a cheaper processor, international cards through a provider with better approval rates in those corridors, and alternative payment methods through a specialized aggregator. The routing engine itself took about six weeks to build and test. But it improved our overall authorization rate by 4.2 percentage points within the first quarter after going live.
The routing logic needs to account for processor uptime stats, not just approval rates. A processor might show a great approval rate in documentation but have a history of intermittent timeouts during peak hours in certain regions. I always recommend pulling your own real-world processor performance data over at least 90 days before building routing rules on top of it.
Tokenization and Security Considerations
Tokenization is non-negotiable for PCI compliance if you're handling card data. The gateway should never expose raw PAN numbers to your servers. When you implement this, make sure your token storage maps cleanly to customer records without creating orphaned tokens that accumulate over time. I've seen systems where abandoned carts left thousands of unused tokens in the gateway's vault, and the cleanup process became a monthly manual operation. The 3D Secure flow adds another layer of complexity. The redirect-based authentication means your architecture needs to handle state management across at least three hops: your server, the gateway, and the issuing bank's authentication server. If your session state isn't designed to survive the redirect, customers will get bounced back to your checkout page mid-authentication, and you'll lose the transaction. I implemented a server-side nonce system tied to a short TTL session cookie to handle this reliably. It added about 15 lines of middleware but eliminated a whole class of auth failures. Idempotency keys are another thing that gets overlooked until it causes problems. Your gateway implementation should generate and track an idempotency key per payment attempt. Without this, any network retry from the client side can create duplicate charges. I've seen support tickets where a single customer was charged four times for one purchase because their mobile app retried the request on a timeout and the backend had no deduplication logic.
Failure Modes and Recovery
The biggest architectural risk in payment processing isn't the initial transaction. It's what happens after authorization when settlement fails. A transaction can be authorized successfully by the issuing bank, relayed through the gateway, captured by your system, and then rejected during settlement due to a processor error or a bank reconciliation mismatch. If your architecture doesn't track the full lifecycle state of each transaction, these failures are invisible until your settlement report comes in wrong. I recommend a state machine with these explicit states: initiated, authorized, captured, settled, reconciled, and failed. Each transition should be logged with a timestamp and the responsible component. When a state transition fails, the system should auto-retry with exponential backoff before moving the transaction to a failed state for manual review. Another practical issue is timezone handling across your architecture. Your application server, your gateway provider, and your acquiring bank may all store timestamps in different timezones. I once traced a settlement discrepancy back to a 3-hour offset between the gateway's UTC timestamps and the acquirer's local business day boundaries. The fix was standardizing all internal timestamps to UTC and converting only at the reporting layer.
Rate limiting is a feature you should implement on your own side even if your gateway provider offers it. Gateway rate limits exist to protect the provider's infrastructure, not yours. If you hit a rate limit during a flash sale, you need your own queue management to stagger requests rather than failing hard. I've seen merchant platforms crash their checkout pages entirely because they didn't implement client-side rate limiting before the request reached the gateway.
Monitoring and Observability
Your monitoring stack should track three categories of metrics: latency percentiles per gateway hop, error rates broken down by error code and processor, and reconciliation deltas between your records and the gateway's records. Dashboards are useful but alerting on the right thresholds is where most teams struggle. I've found that alerting on reconciliation delta above 1% over a rolling 60-minute window catches most issues before they become revenue problems. Latency alerts should be set per-p99, not per-average, because the average hides the tail-end failures that actually hurt customers. The one thing I wish more teams implemented is a sandbox smoke test that runs every hour against the live gateway sandbox environment. Gateway API contracts change without notice. Breaking changes in their schema or auth methods will show up in your smoke test results before they show up in your production errors. This caught a silent authentication method deprecation from one of our gateway providers about four hours before it would have affected any real customers.

Scaling Considerations
If you're processing more than a few hundred transactions per minute, your gateway architecture needs horizontal scaling at the request routing layer. A single application server handling payment requests becomes a bottleneck not because of computation but because of outbound connection limits to the gateway API. Connection pooling and keep-alive settings matter more than CPU or memory at this scale. For very high-volume operations, consider whether a direct acquirer connection makes sense versus routing through a gateway aggregator. Direct connections eliminate a hop and reduce latency by roughly 100 to 300 milliseconds per transaction. They also remove the aggregator's markup from your per-transaction fees. The downside is that you take on the integration and maintenance burden yourself, and you lose the fallback routing flexibility that aggregators provide. I'd recommend this path only if your monthly transaction volume exceeds 500,000 and you have engineering capacity to maintain the connection layer. The architecture choices you make now affect how quickly you can respond when payment providers change their terms, raise their fees, or experience outages. Building with observability and replayability in mind from the start saves weeks of debug time when those inevitable disruptions happen.


