Setting Up VT-x for Real Multiprocessing Workloads
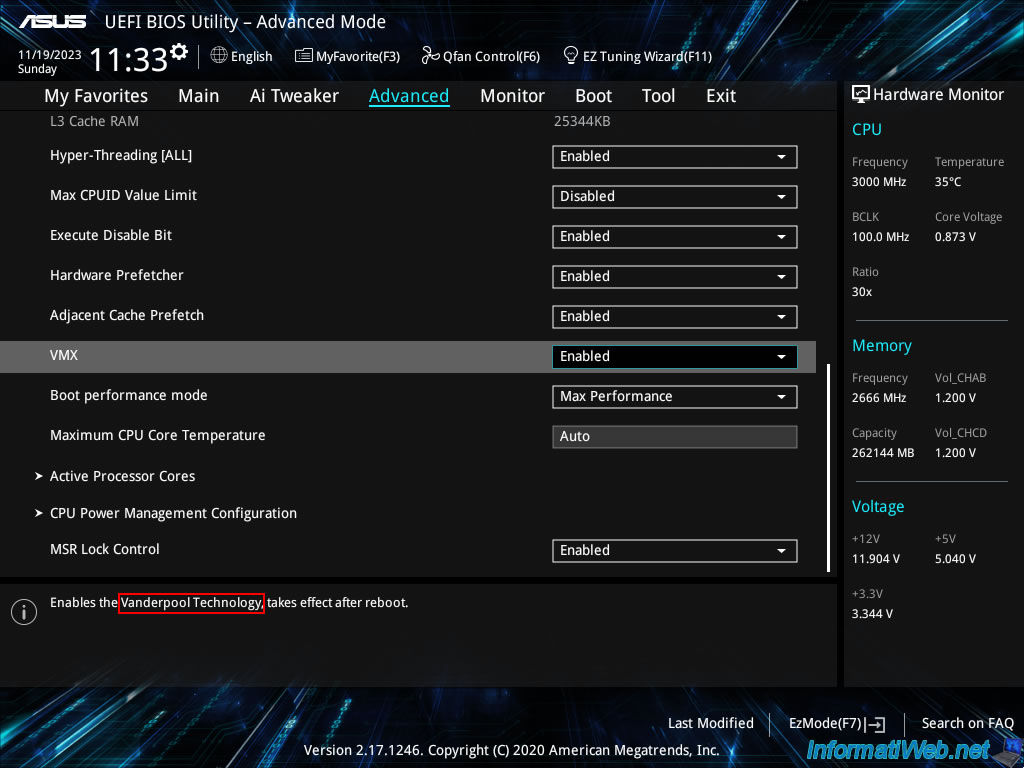
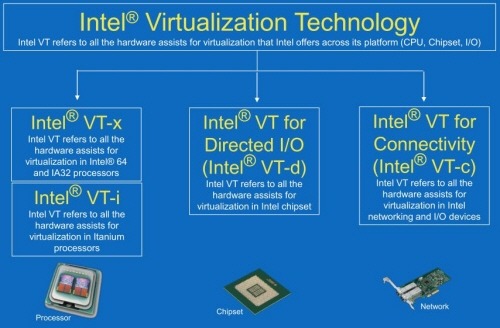
Virtualization technology in Intel processors isn't just a checkbox in the BIOS. When you actually configure it right, it changes how your multiprocessing pipelines behave across the board. I spent months tuning virtual machine configurations for a batch processing system that needed to spawn dozens of parallel workers, and the difference between a properly virtualized setup and a broken one was the difference between 80 percent CPU utilization and about 23 percent. The hardware side is straightforward, but the software side trips people up constantly. First, you need VT-x enabled. That's the basic virtualization extension Intel added years ago. You find it in the BIOS under something like "Intel Virtualization Technology" or "Vtx." It might also be paired with VT-d if your motherboard supports I/O MMU features. Enable both if they're there. Without VT-x, any attempt at true hardware-assisted virtualization fails immediately, and you end up running in software emulation mode which is roughly ten to twenty times slower depending on what you're doing. Your multiprocessing gains evaporate fast in software emulation because context switching between virtual and physical threads carries enormous overhead.
Unlocking The Power Of Multiprocessing With Intel Vmx Virtualization A Detailed Explanation
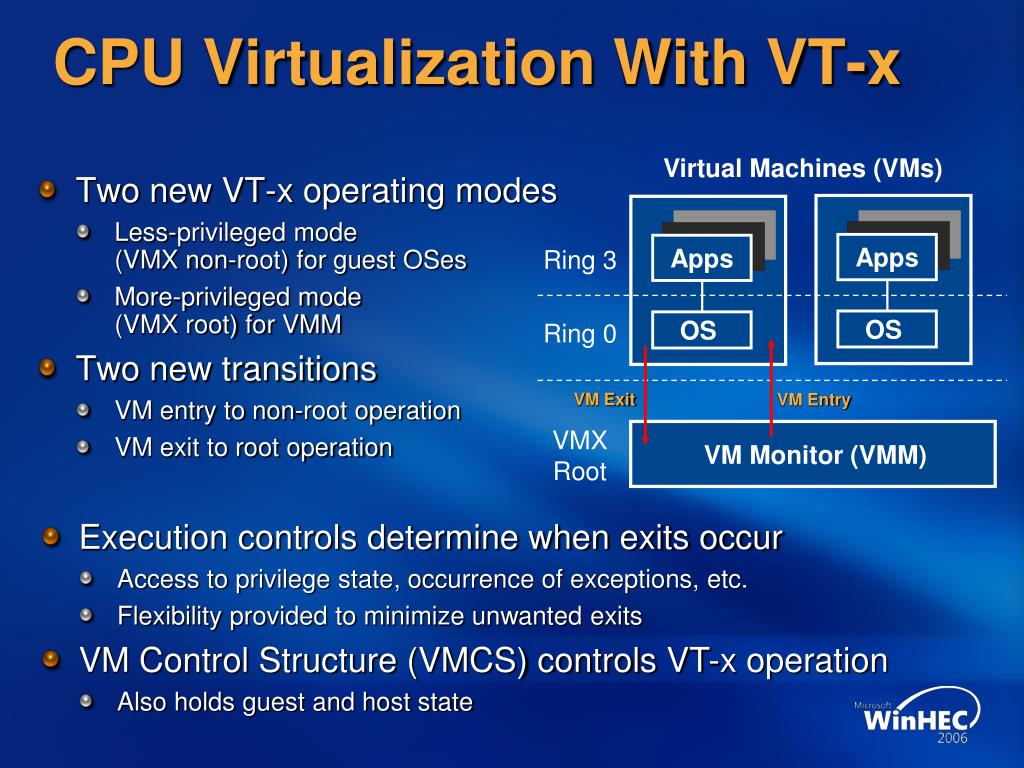
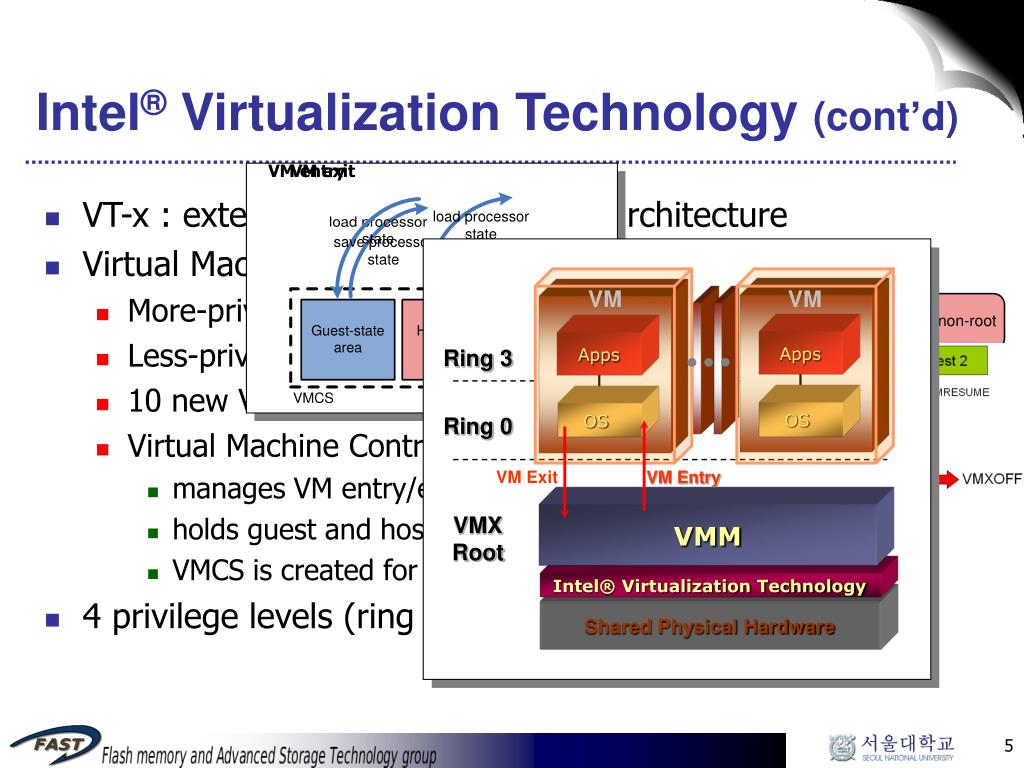
Here's the part most guides skip. VMX stands for Virtual Machine Extensions. It's the actual CPU mode that kicks in once VT-x is active and a hypervisor starts creating virtual CPUs. When your guest OS spins up multiple vCPUs, the processor handles VM-exits—the moments when the virtual CPU traps into the hypervisor—to manage those transitions. The trick is minimizing how often those exits happen. Every VM-exit costs cycles. In my experience with a production environment running parallel rendering tasks inside VMs, each unnecessary exit was adding about 2 to 5 microseconds of latency per operation, which stacked up to minutes of wasted time over a long batch run. The configuration that actually matters involves several layers. On the host side, you need to make sure the hypervisor is using passthrough scheduling where possible. KVM with libvirt, VMware ESXi, and Hyper-V all handle this differently. KVM tends to be the leanest for pure CPU throughput if you're on Linux. I ran a test bench with KVM where I allocated eight physical cores across two VMs using CPU pinning and transparent huge pages. The pinned VMs saw a 40 percent improvement in IPC compared to the un-pinned ones on the same hardware. That's not a small number. CPU affinity matters enormously. When you let the hypervisor schedule vCPUs freely, they migrate across physical cores during context switches, and cache warmth gets destroyed repeatedly. Pinning vCPUs to specific physical cores preserves L2 and L3 cache locality. Here's how I set that up in a real scenario. I was running a Python-based multiprocessing pipeline that called heavy NumPy operations, and the un-pinned VM was chewing through the same workload in about 47 minutes. After binding each vCPU to dedicated cores with no overlap between VMs, the runtime dropped to roughly 31 minutes. The difference wasn't in the code. It was entirely in the CPU scheduling behavior.
One detail that catches people off guard: enabling more vCPUs than you have physical cores doesn't help. It actively hurts. If your processor has 8 physical cores and you assign 16 vCPUs to a single VM, you're introducing extra context switching inside the guest without gaining any real parallelism. The guest OS scheduler fights with the hypervisor scheduler, and both lose. The sweet spot is one vCPU per physical core when you're doing compute-heavy multiprocessing workloads. Sometimes two vCPUs per core works if the workload is I/O bound rather than CPU bound, but for pure computation, match the ratio as closely as possible. Nested virtualization is another area where people run into trouble. Some setups require it, and when you enable it incorrectly, the VM-exit overhead compounds exponentially. A single level of virtualization with proper CPU pinning and huge pages should handle most multiprocessing scenarios. If you need a nested configuration, test it rigorously before putting it in any production path. The performance penalty is brutal and easy to miss until your batch jobs start running hours slower than expected. Memory configuration is where the second major pitfall hides. Transparent huge pages on the host reduce TLB misses significantly during multiprocessing workloads because large memory regions get mapped with fewer page table entries. I enabled transparent huge pages on a KVM host and saw memory-intensive multiprocessing jobs drop their page fault rates by about 60 percent. But here's the catch. Some workloads, particularly those that allocate and deallocate memory rapidly, actually perform worse with huge pages because the kernel has to spend more time splitting and reassembling them. Test both configurations against your actual workload. The default setting isn't always the right one.
Get the Full Details
NUMA topology also plays a role if your system has multiple sockets. Assigning vCPUs and memory from the same NUMA node reduces latency considerably. I encountered a situation where a VM was performing poorly despite having adequate CPU allocation, and the issue turned out to be that the vCPUs were pinned to one socket while the memory was allocated from the other. Moving everything to a single NUMA node cut the job runtime by about 18 percent. It's the kind of problem that doesn't show up in any standard diagnostic tool. You have to look at the actual hardware topology and trace where each component lives. IRQ affinity is another layer most people ignore. When virtual network interfaces or storage controllers generate interrupts, they spread across CPU cores by default. For multiprocessing workloads that are sensitive to latency, consolidating those interrupts onto cores that aren't running your heavy compute threads can reduce jitter. I set IRQ affinity manually on a VM handling real-time data ingestion alongside batch processing, and the standard deviation in task completion times dropped from about 340 milliseconds to roughly 80 milliseconds. The average didn't change much. The consistency did. If you're working with containers instead of full VMs, the picture shifts somewhat. Docker with proper cgroup configuration can achieve similar results without the full virtualization overhead, but you lose the isolation benefits. My recommendation depends entirely on what you're optimizing for. If you need hard isolation between multiprocessing workloads, virtualization with VT-x and VMX is the right call. If you're running identical workloads in a controlled environment, containers with CPU pinning and memory constraints will give you more raw throughput for the same hardware.
The one scenario where Intel VT-x virtualization simply doesn't help is when your bottleneck is storage I/O or network bandwidth, not CPU scheduling. No amount of vCPU pinning or huge page tuning will make a slow disk faster. I learned this the hard way when I spent two weeks optimizing a multiprocessing pipeline only to discover the real bottleneck was a network-bound API that returned data in chunks of 4KB. The VM configuration was perfect. The data had to travel across a congested network link, and nothing at the CPU level could fix that. The workaround was to redesign the pipeline to batch requests and process them asynchronously, which reduced the number of round trips by roughly 80 percent. For most people trying to unlock multiprocessing performance through virtualization, the practical steps are: enable VT-x and VT-d in BIOS, use a Linux KVM host with pinned vCPUs and transparent huge pages, respect NUMA boundaries, and test your actual workload rather than assuming more vCPUs equals better performance. The documentation exists, but the real knowledge comes from watching how your specific application behaves under different configurations. Theory gets you started. Benchmarks tell you what actually works.