Why Automated Backups Are Lying To You
I stopped trusting automated backup jobs after a ransomware incident took down our primary production cluster last November. The automated snapshots had been running on schedule for three years. The backup software reported success every time. But when we tried to restore from the most recent clean snapshot, the recovery process pulled corrupted pages from a storage tier that had been silently bit-rotting for eleven months. We lost two days of transactional data that we couldn't rebuild from application logs. That was the moment I started doing manual database backups again. Not because automation is bad. It isn't. Automation is essential for scale. But automation creates a false sense of security when you don't verify what it's actually capturing. Manual backups force you to look at your data directly. They require physical involvement with the process, which means you catch issues that a cron job logging "Backup completed successfully" will never show you.
Unlocking The Power Of Manual Database Backup A Gamechanger For Data Security
Here is how the process actually works in practice, not the textbook version. You need a consistent, transaction-safe point-in-time snapshot of your database, written to a storage target that exists outside your primary infrastructure. The word manual here doesn't mean you write complex scripts from scratch every time. It means you are the person who initiates, verifies, and validates the backup, not a scheduled job that runs unattended. The basic flow for a PostgreSQL database looks something like this. You stop accepting writes for a brief window using a maintenance mode flag on your application layer, then you run a consistent dump through pg_dump with the --clean and --if-exists flags so the restore is idempotent. You compress the output with zstd at level 3, which gives you good ratio without burning CPU for hours. You write it to an offsite location, verify the checksum, and then you start accepting writes again. That is the entire process. It takes about twelve to eighteen minutes for a 40 gigabyte database on a standard SSD-backed storage system. If your database is larger, expect the restore time to dominate your planning, not the backup time. For MySQL or MariaDB installations, mysqldump with the --single-transaction flag is your baseline. It uses InnoDB's MVCC to produce a consistent snapshot without locking the entire table. The catch is that it only works reliably on InnoDB. If you have MyISAM tables hiding somewhere in your schema, --single-transaction will give you a corrupted logical dump because MyISAM does not support transactional consistency. I spent six hours debugging a restore failure once before I discovered a legacy MyISAM table buried in a partitioned schema that nobody documented. Flagging all tables explicitly with --ignore-table for the MyISAM ones and dumping them separately with --flush-logs before the transactional dump solved the problem.
MongoDB operates differently because it is document-based and doesn't have traditional transaction semantics in the same way relational databases do. mongodump with the --oplog flag is critical here. It captures the oplog during the backup window so you can replay operations after the initial snapshot. Without the oplog, your backup will be internally consistent at the moment the dump starts, but any writes that happen during the backup process will be lost on restore. That gap can be significant on a busy collection. Snowflake presents an interesting edge case that almost nobody warns you about. You can use the SNOWFLAKE backup integration feature in combination with CREATE RESTORE POINT, but I learned the hard way that restore points do not survive account-level deletion. If someone with the right privileges drops your account or if a security incident triggers an automated account teardown, your restore points vanish. The workaround I implemented was to continuously export key schemas to Parquet files in cloud storage every four hours using a scheduled task. Parquet files are just data. They don't care about account state. This became my true recovery baseline.
Get the Full Details
The Verification Step That Separates Backups From Hope
Most people skip verification. This is why manual backups matter more than you might expect, because the manual process makes verification a visible part of the workflow instead of an afterthought. After you complete a backup, you need to restore it to an isolated environment and confirm that the data is queryable and logically consistent. Not test this on your production server. Spin up a temporary instance in the same region, apply the dump, and run a validation query that checks row counts against known values from your source system. A row count mismatch between source and restored database usually means you missed a schema element during the dump, or a compression step corrupted part of the output. I encountered this with a PostgreSQL dump where the pg_dump command was failing silently on extensions because the --schema-only flag was being mixed with --data-only in a script I inherited from a previous administrator. The restore produced a structurally valid database with no custom types, which meant stored procedures referencing those types failed at runtime with obscure error messages. The fix was to dump extensions separately and apply them before the main schema restore. You should also verify that your retention policy is working correctly. If you are keeping seven days of manual backups, confirm that the oldest backup in your rotation is still readable and that the newest one is complete. I discovered once that a disk space cleanup script was removing the oldest backup file every night, but it was deleting the wrong file because the naming convention had changed six months earlier and nobody updated the cleanup rule. The retention window appeared intact in the directory listing but the actual recoverable data was three days behind the schedule.
Storage Targets And The Anti-Single-Point-Of-Failure Rule
Your backup has to live somewhere other than the system it protects. This sounds obvious. It is not always followed. I have seen organizations storing disaster recovery copies on the same NAS array as the primary database. When that array failed, both the production data and the backups failed together. The failure domain of your backup storage must be independent of your primary storage failure domain. For on-premise setups, this usually means an external network attached storage unit on a separate VLAN, or a physical tape library that requires manual retrieval. For cloud environments, it means a bucket in a different region or a different cloud provider entirely. Cross-region replication is cheap for most object storage providers. I would rather pay a small monthly fee for cross-region storage than lose everything during a regional outage. Encryption at rest is non-negotiable. Most database dump tools support encryption through wrapper scripts or built-in flags. With PostgreSQL, you can pipe the compressed output through GPG symmetric encryption before writing it to storage. This ensures that even if someone gains physical access to your backup media, they cannot read the data without the key. Store the encryption key in a separate location from the backup itself. A USB drive in a locked drawer, or a hardware security module in a different building. The encryption key and the encrypted backup should never coexist in the same physical or virtual environment.
When Manual Backups Are The Wrong Choice
I am not arguing that manual backups should replace automated ones. They should complement each other. Manual backups have real limitations. They are labor-intensive. You cannot run a manual verification process on a thousand databases every week without a team. The process introduces human error at multiple points: wrong flags, incorrect targets, missed verification steps, stale encryption keys. If you are managing a fleet of more than fifty databases, or if your databases exceed two hundred gigabytes each, manual backups will not scale. Your time will be consumed by execution and you will not have capacity left for verification. In that scenario, you should invest in an automated backup solution with built-in verification capabilities, such as Barman for PostgreSQL or MySQL Enterprise Backup for MySQL, and then run manual backup checks once a month as a sanity validation layer. The automated system handles the daily workload. The manual check catches automation failures. Another scenario where manual backups fail is real-time analytics environments where zero-downtime is required and you cannot afford even a brief write suspension window. pg_dump with lock acquisition will block writes. --single-transaction on MySQL reduces lock duration but does not eliminate it under heavy write loads. If your application cannot tolerate any lock contention, you need a streaming replication-based backup solution that captures changes in real time, not a logical dump performed manually.
Practical Workflow You Can Start Today
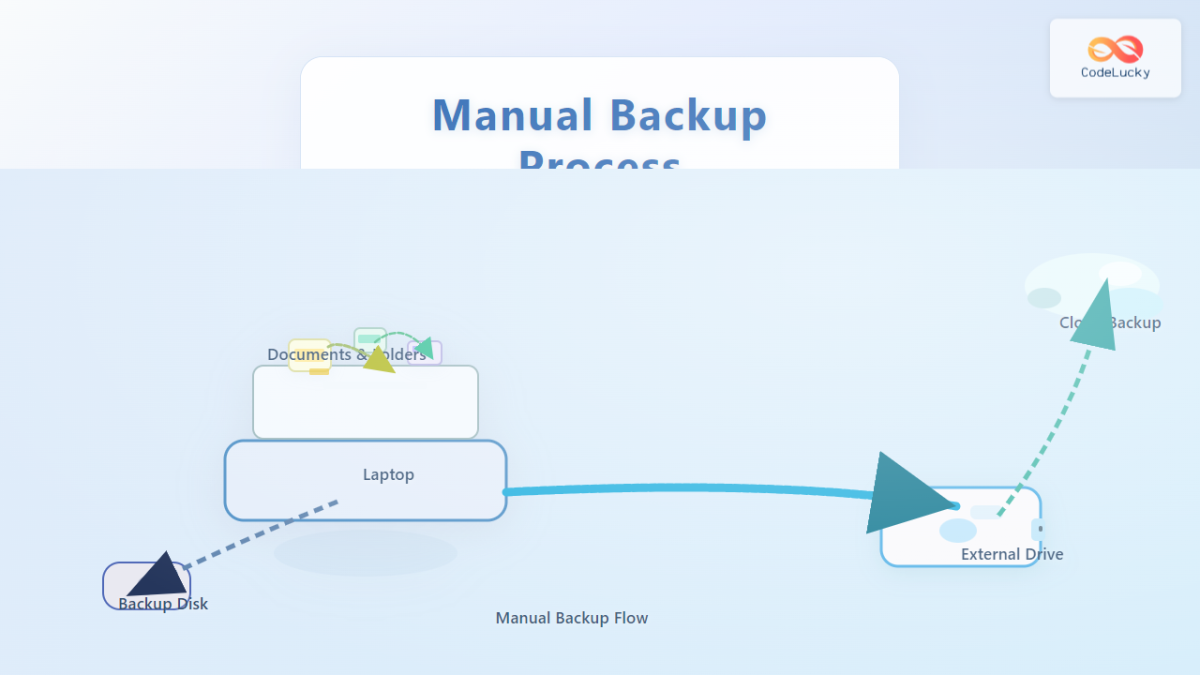
Write a script that does the following in order. First, log the operation start time and your database connection parameters. Second, put the application into maintenance mode or pause write traffic at the application layer. Third, execute the backup command with appropriate flags for your database engine. Fourth, compress and encrypt the output. Fifth, transfer the backup to your offsite storage target and confirm the transfer completed successfully. Sixth, calculate and store a SHA-256 checksum of the final backup file. Seventh, resume write traffic. Eighth, log the completion time and duration. Run this script manually at least once per week. Do not schedule it. The act of running it manually is the point. You will notice things you did not know. You will discover that a migration happened six months ago and the backup script references the wrong configuration path. You will find that your offsite storage credential expired last quarter. You will see how long the process actually takes and whether it fits within your maintenance window. Each manual run is a small audit of your entire backup posture. The recovery testing should happen on a schedule that matches your risk tolerance. Financial systems might justify weekly restore drills. A low-traffic internal dashboard might be fine with quarterly verification. The key insight is that a backup you have never restored is not a backup. It is a guess. Manual backup processes force you to confront that gap between assumption and evidence, which is exactly why they protect your data better than any automated system that logs success without proving it.