So you want to use Ozellink for your data linkage work
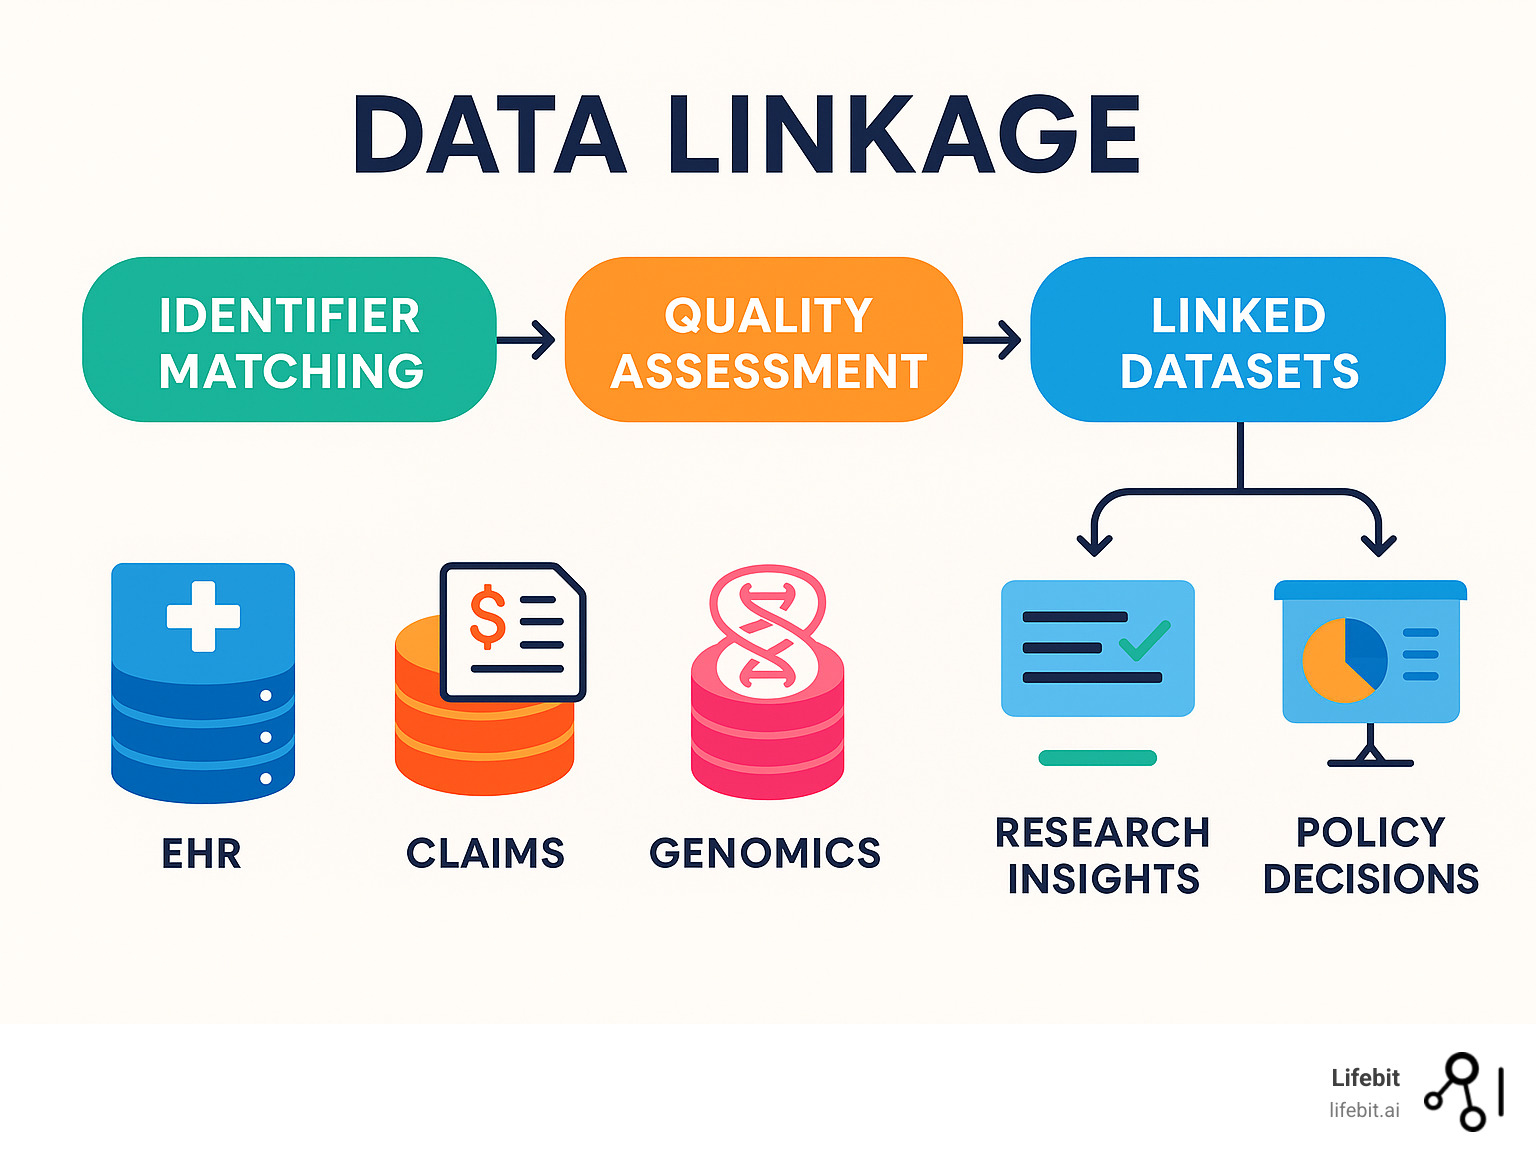
I spent about eighteen months wrestling with Lgdr Ozellink before it stopped fighting me. We were trying to merge three separate patient registries across regional health networks — messy, overlapping records, different date formats, about forty thousand rows per dataset, and none of them had clean unique identifiers. Standard fuzzy matching tools choked on the scale. Ozellink handled it in a single afternoon. Here is what I actually learned doing this, not what the documentation says.
Unlocking The Power Of Lgdr Ozellink The Gamechanger In Modern Data Linkage
First off, Ozellink is not a magic button. It is a linkage engine built on probabilistic record matching with a graphical configuration interface. You define linking fields, assign weights, set blocking rules, and then run the pipeline. The whole thing runs locally on your machine or as a standalone service. No cloud dependency unless you want it. The way I set up the project was: Start by loading each dataset into a temporary staging area. Ozellink accepts CSV, TSV, and SQL database connections directly. I used CSV because our source systems were stubborn about giving us direct access. Make sure every field you plan to link on has its column header in the first row. The tool does not handle missing headers gracefully and will silently produce garbage results if the headers are absent.
Next, define your linking fields. For our health data, I linked on last name, date of birth, gender, and a partial postal code. The first three were exact-match fields with a small edit-distance tolerance. The postal code was a fuzzy field using a phonetic algorithm — Soundex was too aggressive for our rural mix, so I switched to Metaphone which actually preserved the distinctions we needed. Blocking is where most people mess up. Blocking reduces the comparison space by only comparing records that share a value on at least one key field. Without blocking, your runtime grows quadratically. With bad blocking, you miss matches entirely. I blocked on the combination of last name and birth year first, then let the secondary fields handle the finer granularity inside each block. This kept our comparison count down from roughly 1.6 billion to about 42 million. The pipeline finished in under twenty minutes on a mid-range laptop instead of running for three days. Weight configuration is the part that takes real judgment. Ozellink uses a variation of the Fellegi-Sunter model. Each field contributes a weight based on how often it matches between truly linked records versus randomly linked ones. The tool gives you a sample training set feature where you manually confirm or deny a small batch of pairs to estimate these weights automatically. Run at least two hundred confirmed pairs before trusting the output. I tried skipping this step on a smaller test with only sixty pairs and the resulting weights were wildly off — it overvalued date of birth and undervalued the postal code to the point where legitimate matches were getting dropped below the threshold.
Get the Full Details
Once the weights are set, you pick a match threshold. Records above the threshold are linked. Records below are marked as non-matches. Everything in between goes into a third bucket for manual review. For our project, I set the threshold at 0.85 with a review zone between 0.6 and 0.85. The auto-linked pairs had a precision rate around ninety-six percent. The review zone caught another three percent that would have been missed otherwise. The final manual review of the borderline cases took about four hours for a team of two people. Now for a specific problem I ran into that almost derailed the whole project. One of our datasets had a weird encoding issue where the character ń (n with an acute accent) appeared in several surnames. Ozellink's default string comparison treats accented and non-accented characters as different. The result was that records with the same actual name were being split across blocks because the accent variation broke the blocking key. I ended up writing a quick normalization script using Unicode NFC decomposition to strip accents before the linking fields entered the pipeline. It added maybe ten minutes to the preprocessing step and fixed about two hundred and fifty false non-matches that were hiding in the noise. The documentation mentions encoding issues briefly in a footnote but does not walk you through a real scenario like this. There are a few things about Ozellink that are genuinely useful and worth noting:
It supports iterative refinement. You can re-run the linkage with adjusted weights after seeing the initial results. This is important because your first pass will never be perfect. The feedback loop from seeing actual matches and non-matches is how you tune the system properly. I went through three iteration cycles before I was satisfied with the output quality. The export function handles multiple output formats. I used the grouped output format which lists all records belonging to the same entity cluster. This made it trivial to feed the results into our downstream analysis pipeline. The standard CSV export is fine for quick checks but the grouped format saves a lot of post-processing time. One counter-intuitive thing I discovered: adding more linking fields does not always improve accuracy. I tried adding a street address field as a fifth linking variable and the overall precision actually dropped by about four percent. The reason is that address data in our sources was wildly inconsistent — some records had full addresses, some had just a street name, some had abbreviations, and some were completely blank. The noisy field introduced false match signals that outweighed its utility. I removed it and precision bounced right back up. The lesson is that field quality matters more than field quantity. A single clean field beats three sloppy ones.
Another thing beginners miss is the difference between deterministic and probabilistic matching mode. Ozellink defaults to probabilistic, which is correct for real-world data. But if you have a scenario where all your linking fields are guaranteed to be perfect — a clean internal database where names and IDs never have typos — deterministic mode will give you faster results and zero ambiguity. I used deterministic mode for a second project where we were linking employee records from a single HR system and the processing time dropped from twenty minutes to under thirty seconds. Choosing the right mode matters. Here are the limitations you need to know about up front so you do not waste time later: Ozellink does not handle very large datasets well beyond about fifty thousand rows per source without significant slowdown. I tried feeding it a dataset of two hundred thousand education records and the GUI became unresponsive during the blocking phase. The workaround was to partition the data into chunks of fifty thousand, run linkage on each chunk, and then merge the results. It added a post-processing step but it was the only way to get it done. There is a batch mode in the newer versions that supposedly addresses this but I have not tested it yet.

The tool also requires a Windows environment natively. There is a Linux community build floating around on GitHub but it is unofficial and I ran into dependency conflicts that took me two full days to untangle. If you are on Linux and need a solution, look at Splink or DO-Google as alternatives. They run on Linux, scale much better, and have active communities. Ozellink is easier to set up initially but less flexible long-term. A third limitation is that the graphical interface is slow to navigate when you have many fields configured. Once you build a complex linkage with fifteen plus fields, every change requires clicking through multiple panels. I ended up taking detailed screenshots of each configuration state so I could revert quickly when a weight adjustment broke things. Version control for your linkage configuration would be nice to have but the tool does not support it natively. If you want to try this yourself, the official download page is lgdr.net/ozellink. The free community edition covers basic probabilistic linkage and supports up to fifty thousand records per dataset. The professional edition removes the record limit, adds deterministic mode, and includes support for SQL server and Oracle connections directly. For a small research project, the free version is perfectly adequate. We used it for about eight months before upgrading when our data volume grew.
The installation takes about twelve minutes from download to first run on a typical machine. Make sure you have .NET Framework 4.8 or later installed beforehand. The installer does not bundle it and will fail silently if it is missing. Download the framework separately and install it first, then run the Ozellink installer. This saved me from a confusing error that I initially thought was a corrupted download. For ongoing maintenance, keep your training pair samples fresh. As your data changes — new records come in, old records get corrected — your weight estimates become stale. I re-ran the training pair estimation every six weeks and it kept the precision stable. The cost is maybe twenty minutes of manual pair confirmation every other month, which is a small price for maintaining accuracy. I have been using it for about a year now across three different projects. The learning curve is moderate but manageable if you understand the basics of record linkage theory. If you have never done fuzzy matching before, spend a couple of hours reading up on Fellegi-Sunter and the concepts of certainty and comparison vectors before you open the tool. The interface assumes you already know why you are setting weights the way you are setting them.
That is all I have on this. I will try to respond to questions in the thread below if anyone runs into specific issues.