
Setting Up 360-Degree Feedback So It Actually Works
I spent a few years managing feedback cycles across multiple orgs before settling into a setup that didn't make people hate their coworkers. Most of that time was spent wrestling with tool selection, rater bias, and the fact that most companies collect 360 data and then absolutely nothing with it. If you're looking at 360-degree feedback platforms, the feature list on the sales page will look identical across vendors. The real differences show up during deployment, around eight weeks in, when your first round of results start coming back and everything falls apart in ways the demo never showed you.
Unlocking The Power Of 360degree Feedback With Mason Outlook
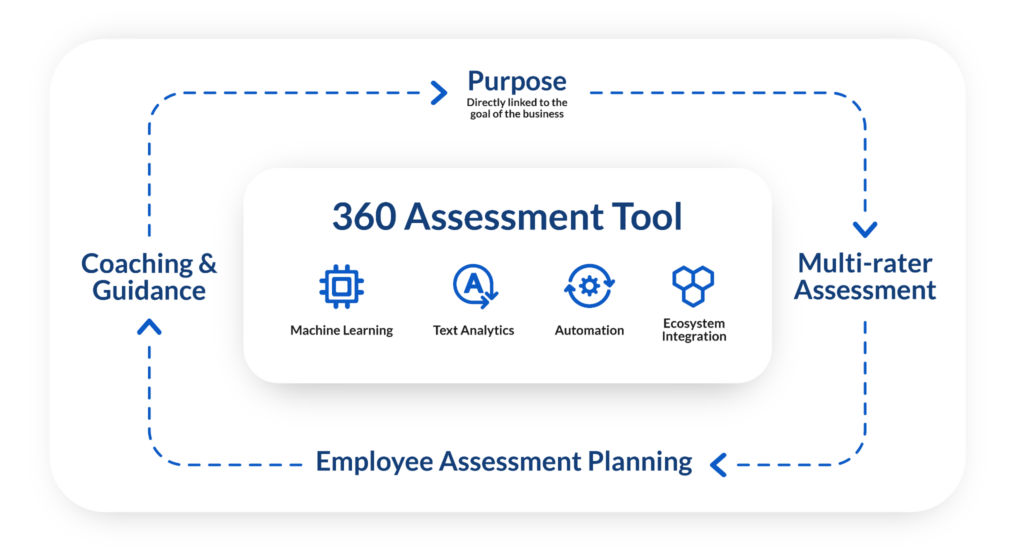
Mason Outlook appears to be positioned as a 360-degree feedback and performance management platform. The general approach with tools in this space follows a fairly standard pattern: you configure the assessment framework, select or import raters, send out the survey rounds, aggregate responses, and generate individual and team reports. What separates a working system from a wasted license comes down to how each of those steps is actually handled in practice. The core mechanism works by collecting anonymous or attributed feedback from multiple perspectives around an employee — peers, managers, direct reports, sometimes self-assessment and external stakeholders. The aggregation produces a profile showing where ratings converge and where they diverge. That divergence is usually the most valuable part of the data. When a manager rates themselves a 4.5 and every direct report rates them a 2.8, that gap tells you something specific about the working relationship that no performance review conversation will ever surface organically. Here is the part that nobody puts in the brochure: you need roughly six to eight raters per person for the data to be statistically meaningful, and most companies try to run this with three. Three raters gives you noise dressed up as signal. Eight gives you something you can actually act on. I learned this the hard way with an early deployment where I ran the cycle with five raters per person and spent two weeks analyzing what turned out to be random variance. The follow-up cycle with eight raters per person produced results that were dramatically more consistent and far more useful.
What To Configure Before You Launch
The question set matters more than anything else. Generic competency frameworks produce generic results. If your survey asks people to rate "communication skills" on a five-point scale, you will get a cluster of 3s and 4s that are technically data but practically useless. Behavioral anchored rating scales work better because they describe specific actions instead of abstract traits. Instead of "demonstrates good communication," you get "actively listens to team concerns and responds with actionable feedback within 24 hours." The rater selection process is the second place where deployments die. If managers nominate their own raters, you will get a roster full of people who like them. I had a case where a director's 360 came back with an average of 4.7 across 12 raters, and every single rater had been personally selected by that director. The direct reports had not been included because the director deemed them "not ready for feedback responsibility." That is not a measurement. That is a popularity contest with a scoring matrix. Use a mix of forced selection and manager approval. Direct reports must be included. At least one peer from a different team. At least one cross-functional collaborator. Let the manager add up to two additional raters of their choice, but require that those raters have concrete working relationships with the person being assessed. This removes the option of nominating someone who sat in the same meeting once.
Get the Full Details
The Reporting Phase Is Where Most People Fail
Getting the reports generated is straightforward. Making sure anyone actually reads them is not. The typical output from any 360 platform includes an individual report with competency scores, comparison benchmarks, and open-text comments. Most people open the PDF, look at the radar chart for approximately four seconds, and close it. The radar chart is visually appealing and informationally sparse. The open-text comments are where the actual data lives. Structure a debrief session within ten business days of report availability. Do not let the data sit in an inbox for three weeks and hope people will revisit it. The debrief should be between the employee and a trained facilitator, not their manager, because the manager is often one of the people being rated. A neutral third party helps the employee process the feedback without immediately becoming defensive or starting to mentally argue with each comment. One thing that surprised me after running dozens of cycles: the highest-impact conversations are almost never about the lowest-scoring competency. They are about the gap between how the person sees themselves and how others see them. That gap is called the blind spot in the literature, and it is the single most predictive factor for whether the feedback cycle actually changes behavior going forward.
Common Pitfalls I Have Actually Encountered
Rater fatigue is real and it compounds every time you run a cycle. If you have a mid-size company of 200 people and you send out 360 surveys to everyone, a significant portion of your workforce is also a rater for someone else. People get surveyed for six different colleagues and they start giving the same generic feedback to everyone. I solved this by staggering the cycles. One group in Q1, another in Q2, and a third in Q3. This kept the rater load manageable and the quality of comments noticeably higher. Another issue that comes up repeatedly: the central tendency problem. People rate everyone a 3 or a 4 because they do not want to be the one who gives a low score. This is especially common in cultures where direct negative feedback is stigmatized. The workaround is to include a minimum threshold for low ratings. If fewer than 10% of raters give a score below 3 on any competency, flag the assessment as potentially compromised and either extend the survey window with a reminder about honest rating or rerun the cycle with a different rater composition. There is also the question of whether to make results public within the team. Some platforms offer a team-level aggregate view. I have found that sharing team aggregates without individual data creates enough transparency to build trust without exposing anyone to embarrassment. Sharing individual data publicly almost never goes well. The one exception I have seen work is when the entire leadership team participates first and models the behavior by discussing their own feedback openly in a forum setting.
What This Tool Does Not Solve
A 360-degree feedback platform will not fix a management problem. If your organization has a culture where people are afraid to give honest feedback, putting that feedback through a slick interface does not change the underlying dynamic. You will still get inflated scores and padded comments regardless of which vendor you use. It also will not replace regular one-on-one conversations. The annual or semi-annual cycle is a snapshot. It is useful for identifying patterns over time, but it is a poor substitute for ongoing dialogue. The companies that get the most out of these systems treat the 360 as a diagnostic tool, not a replacement for management. If you are working with a small team under 30 people, a structured 360 cycle may be overkill. Simple peer feedback rounds conducted quarterly often provide similar signal at a fraction of the administrative overhead. The framework is the same, just less formal and less resource-intensive.
Practical Next Steps
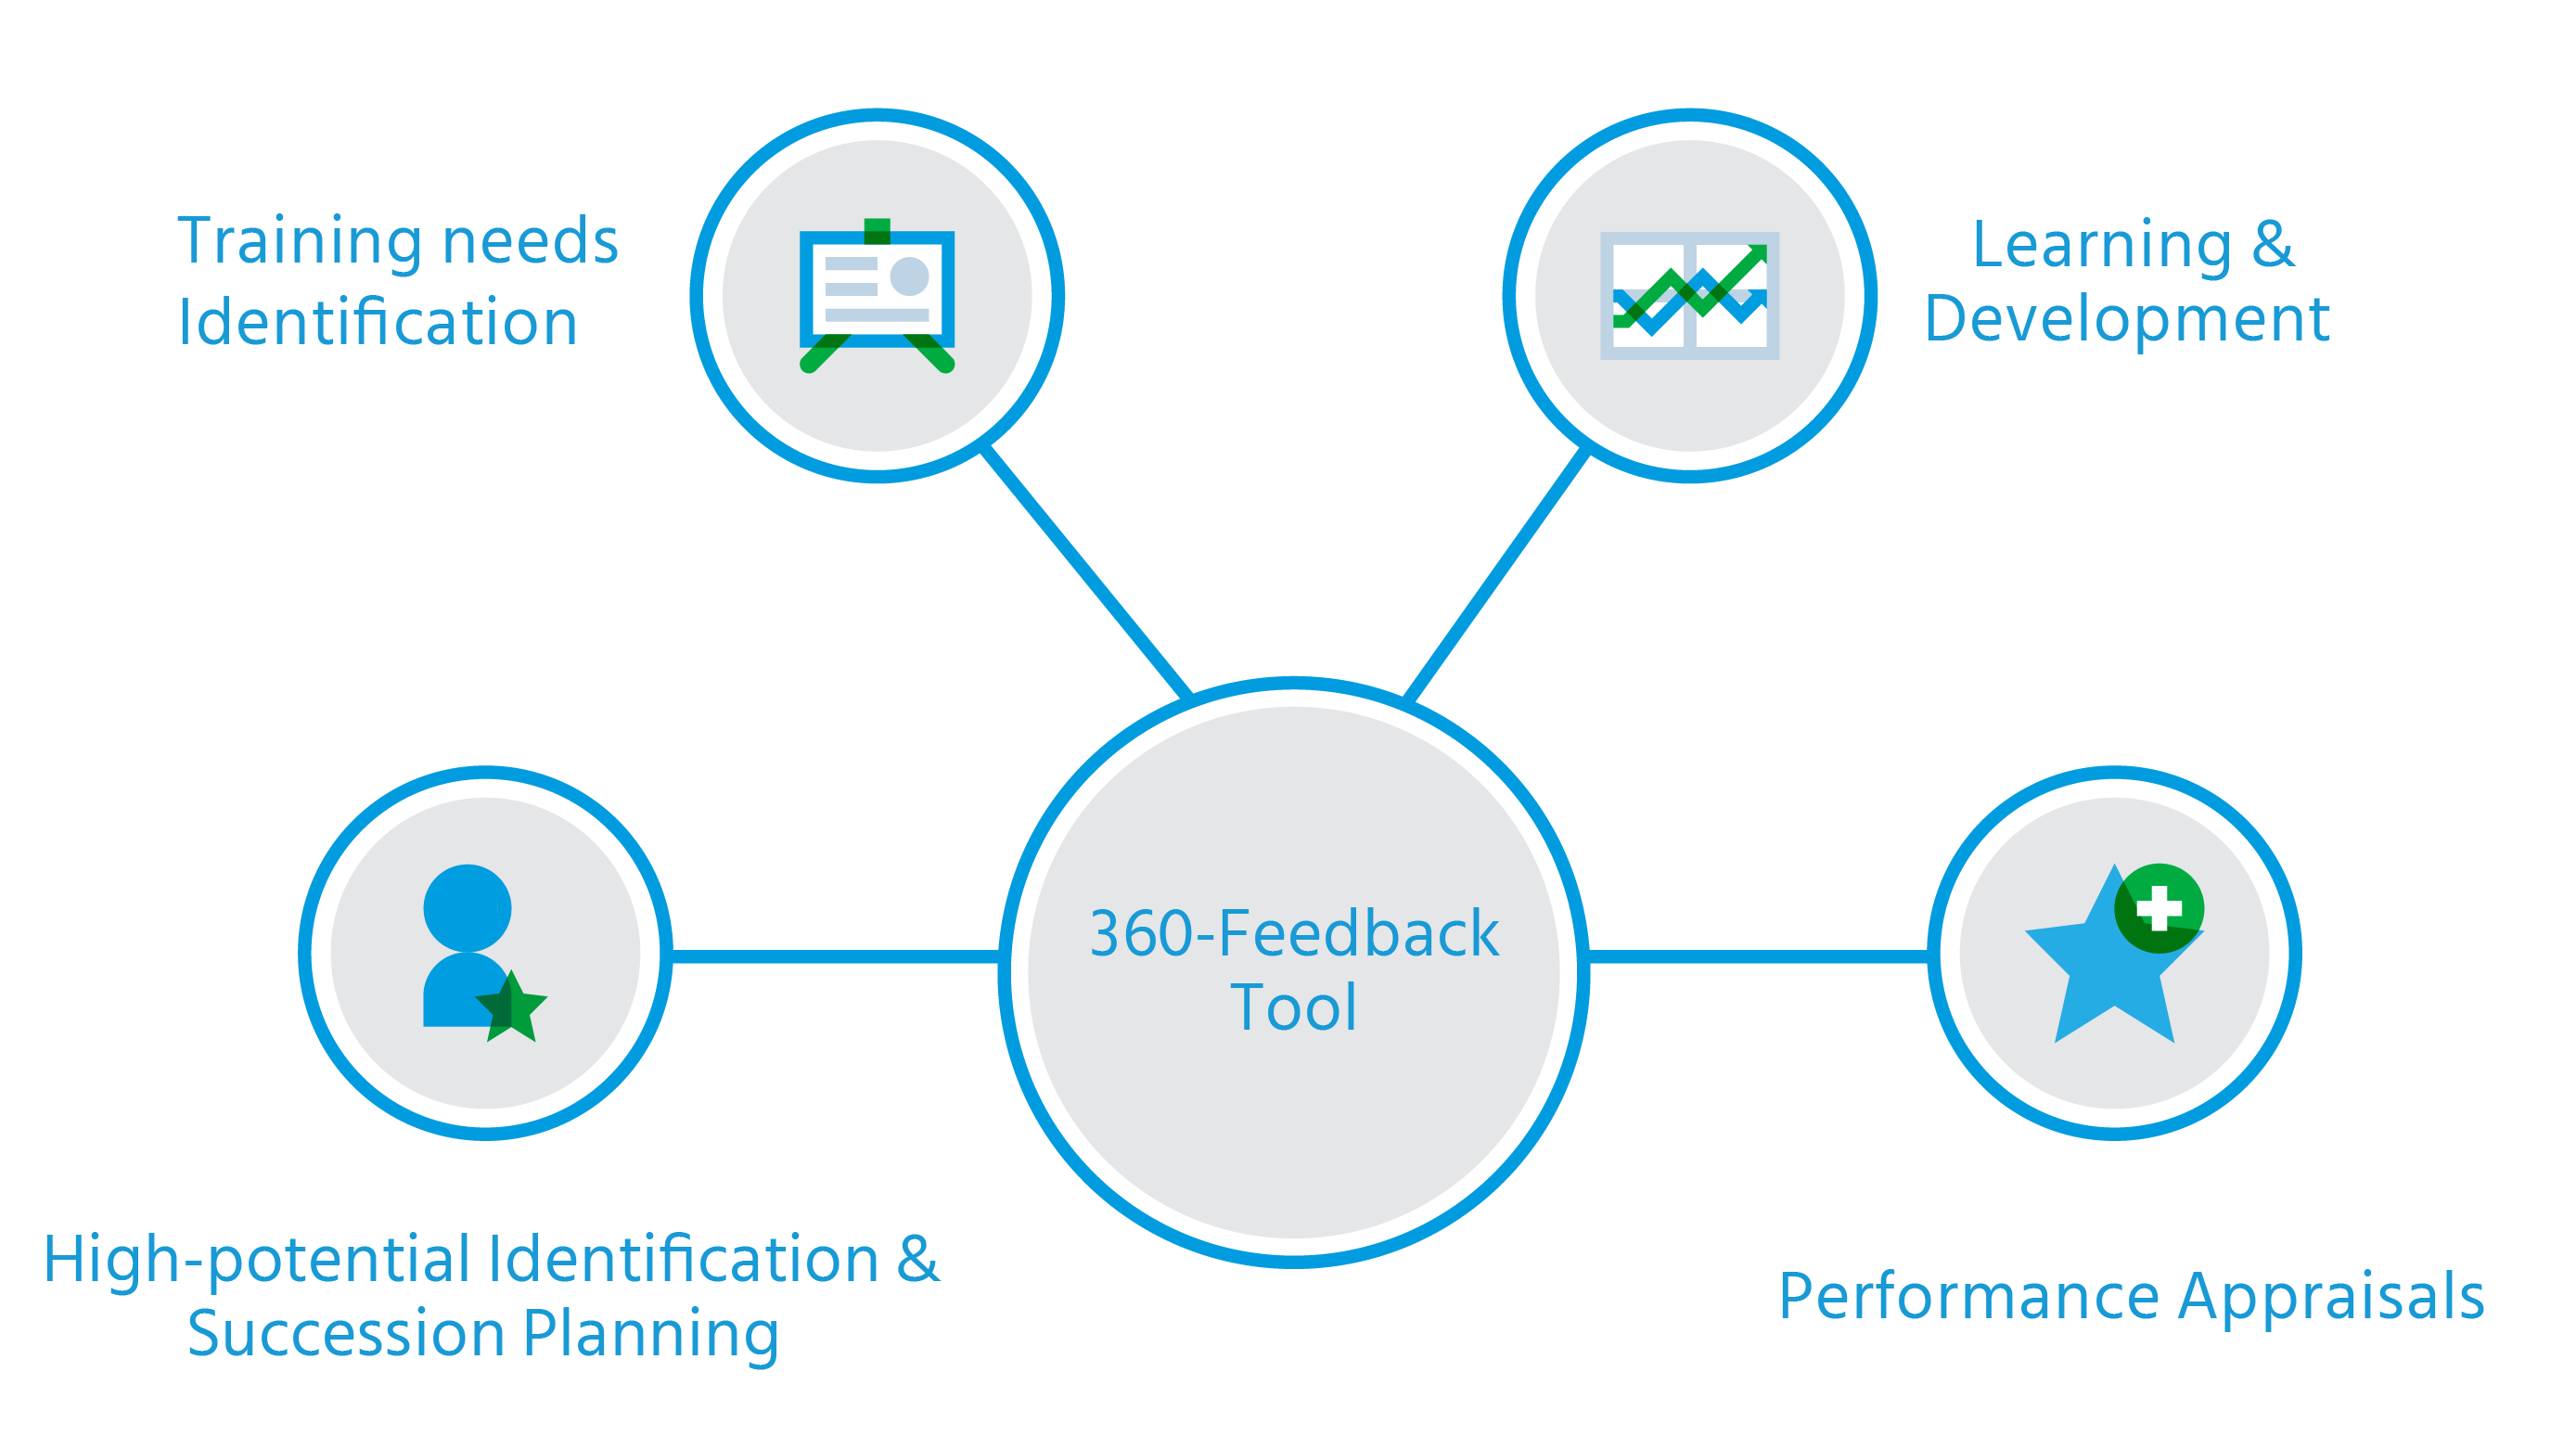
Start with a pilot group of 15 to 20 people across different levels. Run a single cycle with careful rater selection and a proper debrief process. Measure the outcomes: how many people completed their debrief, how many created an action plan, how many followed up three months later. Use those numbers to decide whether to scale. Most organizations that skip the pilot and roll out to the entire company at once end up with low completion rates and a lot of frustrated employees who feel like the exercise was performative. The technology side of things is mostly commoditized at this point. The differentiator is always the process design and the organizational willingness to sit with uncomfortable data. Pick a platform that fits your existing workflow, configure it carefully, and invest more time in the human side of the deployment than you would expect to need.


