Understanding the 403 Forbidden Status Code
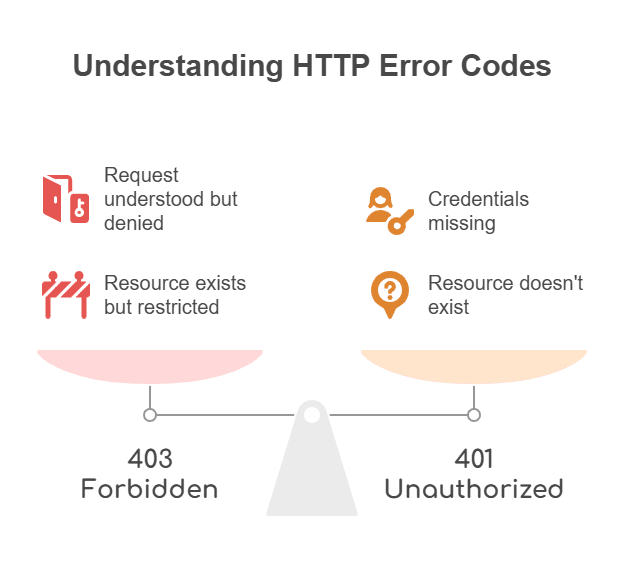
The 403 Forbidden status code is one of those server responses that shows up constantly in web operations, and it means exactly what it says: the server understands your request but refuses to authorize it. It's different from a 404, which means the resource doesn't exist, or a 500, which means the server broke. A 403 means the resource is there, the server is running, and it's just not letting you in. Most people hit it, stare at it, and move on. It's not particularly mysterious unless you've been burned by it repeatedly.
Unlocking The Mysterious World Of 403 Forbidden What You Need To Know
I spent three days last year debugging a 403 on a production API endpoint that no one could reproduce in staging. The endpoint worked fine for our internal team, worked fine for test accounts, and then started returning 403 for about 15% of real users. We were pulling our hair out because the error logs showed nothing useful — just a clean refusal from the WAF (Web Application Firewall) with no explanation attached to the response body. Turns out one of our security rules was flagging a specific combination of custom headers that a particular mobile SDK was sending. The header wasn't malicious in any way. It was just a vendor identifier that happened to contain a substring matching a SQL injection pattern in our rule set. We tightened the regex scope and added an exception for that header. Took six hours total once we knew what to look for.Here's the thing most guides don't tell you: a 403 response can come from a dozen different layers in a modern stack. The web server itself (Nginx, Apache) can return it based on file permissions or configuration. A reverse proxy or CDN like Cloudflare can block it at the edge. The application framework might reject it after routing. An API gateway or WAF can inject its own 403 independently. And an authentication middleware layer can return it before the request ever touches your business logic. When you see a 403, the first question isn't "what's wrong" — it's "which layer threw this?" That distinction matters because the fix is completely different depending on where it originates.
Common Causes and How to Diagnose Them
The most frequent cause is straightforward: insufficient permissions. You're accessing a resource you don't have authorization for. This happens in two main flavors. In the first, you're not authenticated at all and the server doesn't even bother telling you what you'd need — it just says no. In the second, you're authenticated but your account lacks the specific role or permission for that endpoint or resource. Checking your authentication tokens and session state usually resolves the first case. The second one requires looking at your RBAC (Role-Based Access Control) configuration or checking whether the resource has per-user ownership restrictions.Then there's IP-based blocking, which is increasingly common. Your request might be perfectly valid but your IP address is on a deny list. This could be intentional — the admin blocked your subnet. It could also be collateral damage from a previous abuse incident on the same IP range. Shared hosting environments and residential ISPs often have their IPs flagged because other tenants or users ran scrapers or launched attacks from the same address pool. If you're behind a corporate proxy or VPN, the exit node IP might be the problem, not your actual location. URL or path-based restrictions are another category that trips people up. The .htaccess file on Apache servers can deny access to specific directories or file patterns. Nginx uses location blocks with deny directives. Some frameworks implement route-level access control that returns 403 before the controller even executes. If you recently migrated sites or changed directory structures, old .htaccess rules or misconfigured rewrite rules can silently block requests that should work. I've seen this happen when a developer moved a Laravel app to a subdirectory without updating the security config — every request to the public assets path got blocked by a leftover rule meant for the old location. Cors misconfigurations can also surface as 403 errors, though this is less obvious. When the preflight OPTIONS request fails due to missing or incorrect CORS headers, some browsers and clients interpret the failure as a 403 rather than a network error. Check your Access-Control-Allow-Origin, Access-Control-Allow-Methods, and Access-Control-Allow-Headers settings. If the requesting origin isn't explicitly listed or the method isn't permitted, the server may return 403 instead of the more descriptive 400 or 404 that the spec suggests.
Get the Full Details

Practical Troubleshooting Steps
Start by checking the response headers. A well-configured server will include information about why the request was blocked. Some return a Retry-After header. Others include a server-specific header like X-Blocked-By or X-WAF-Reason that points directly to the blocking mechanism. Cloudflare adds a cf-ray header you can use to look up the request in their logs. AWS WAF returns a reason code in the response if you've configured custom logging. Without these headers, you're flying blind, which is why configuring your security layers to include rejection reasons is worth the effort. Next, test with curl or Postman using minimal headers. Strip everything down to the bare request with no custom headers, no user-agent variations, and a clean accept type. If that works, the issue is in your request construction — one of your headers is triggering a filter. Add them back one at a time until the 403 returns. This narrows the problem from "something in my request" to "this specific header." I recently narrowed down a persistent 403 to the X-Forwarded-For header by using this exact method. The receiving server's geo-blocking was rejecting requests that contained a forwarded IP from a region the API didn't support, even though the actual client IP was in an allowed region.Check file and directory permissions if you're dealing with a self-hosted setup. On Linux servers, the web server process runs as a specific user — usually www-data, nginx, or apache. If a directory is owned by a different user with restrictive permissions, the web server can't read it and returns 403. The typical fix is chmod 755 for directories and 644 for files, but the exact permissions depend on your server configuration and whether you're using suPHP or similar tools that enforce per-user permission checks. Review your .htaccess or nginx.conf files for deny rules. A single deny from line in Apache or an allow/deny block in Nginx can silently kill requests. These files are easy to overlook because they're often buried in deployment configs or inherited from previous projects. If you recently cloned a repository or restored a backup, check for config files that came along with it. One of my team members pushed a staging .htaccess with a deny-all rule to production and spent two hours wondering why the entire site was down before checking the file.
Authentication and Authorization Pitfalls
Bearer tokens and API keys have expiration, and hitting a 403 is often the first signal that yours has expired or been revoked. Refresh tokens can also expire, which means you might have a valid access token that can't be refreshed, leaving you in a limbo state where the server knows you were authenticated at some point but won't honor the current credentials. Check token expiry timestamps before assuming the server is being arbitrary. JWT tokens in particular can cause confusion because they're opaque strings — you can't tell by looking at them whether they're expired or malformed without decoding the payload. Rate limiting sometimes masquerades as authorization failures. Some systems return 403 instead of 429 (Too Many Requests) when you exceed thresholds, especially older or poorly configured APIs. If you're hitting an endpoint repeatedly and getting 403s consistently, check whether your request rate has changed. I encountered this on a project where a batch processing job suddenly started failing with 403s. The job had been running fine for months, but we'd accidentally increased the concurrency from 5 parallel requests to 50, which triggered a rate limit that was implemented as a silent block rather than a proper 429 response. Cookie-based authentication has its own quirks. Domain mismatches between your app and the auth cookie domain will cause the browser to stop sending cookies, resulting in an unauthenticated 403. Same-site attribute misconfiguration can prevent cookies from being sent on cross-site requests. Secure flag issues arise when a cookie marked as secure is sent over HTTP instead of HTTPS. These are subtle because the browser handles them silently — there's no error message, the cookie just isn't sent, and the server sees an anonymous request.
CDN and WAF Considerations
Content delivery networks and web application firewalls sit between your users and your origin server, and they generate their own 403 responses independently of your application. This means you might debug your code for hours only to find the block is coming from Cloudflare, Akamai, AWS Shield, or a similar service. Most of these platforms have dashboards where you can view blocked requests and the specific rule that triggered the block. Cloudflare's security events log, for instance, shows exactly which rule fired, the rule ID, and the action taken. Without checking these logs, you're diagnosing the symptom without seeing the cause. DDoS protection modes are a common source of unexpected 403s. When a CDN detects what it interprets as an attack, it may block all traffic from the affected IPs or regions as a precaution. This is especially common during campaigns where multiple targets are under attack simultaneously — the WAF broadens its filtering and legitimate requests get caught in the net. If you notice a sudden spike in 403s across many different users, check your CDN status page and security event logs. The fix is usually adjusting sensitivity thresholds or whitelisting specific traffic patterns that are being flagged.Geo-blocking is another CDN feature that produces 403s. Some services restrict access by country or region for licensing or compliance reasons. If your application serves content that has regional distribution rights, the CDN will block requests from unauthorized locations. This can be confusing for users who are traveling or using VPNs, because their actual location might be fine but their perceived location isn't. Document these restrictions clearly in your API documentation so users aren't left guessing.
Edge Cases and Known Issues
One edge case that caused me significant headaches involved mixed-content restrictions on HTTPS pages. A page served over HTTPS that includes resources fetched over HTTP will sometimes trigger a 403-like behavior in modern browsers. The browser blocks the mixed content as a security measure, and some server configurations respond to these blocked requests with 403 instead of handling them gracefully. Check your page resources and ensure all asset URLs use the same protocol as the parent page.Another issue involves request size limits. Some servers return 403 when a request body exceeds configured limits, rather than the more appropriate 413 Payload Too Large. This happens when the server's request filtering layer treats oversized payloads as potential attack vectors and blocks them at the perimeter. If you're sending large uploads or complex GraphQL mutations and getting 403s, check the request size against your server's configured limits. There's also the matter of case sensitivity in URL paths. Some servers treat /API/Users and /api/users as different resources, and if your access control rules are applied to the lowercase version but your request uses uppercase, you'll get a 403. This is more common on Unix-based servers where the filesystem is case-sensitive. I've seen this bite teams working across different environments where the development server (often Windows-based) is case-insensitive but the production server (Linux) enforces case sensitivity. The 403 response code has a notable limitation: it doesn't distinguish between "you're not allowed because you're not logged in" and "you're not allowed because you're logged in but lack permission." This ambiguity makes debugging harder because the client can't tell whether it should prompt for authentication or escalate a permission request. Some APIs return different status codes for these cases — 401 for unauthenticated and 403 for unauthorized — but many don't follow this convention consistently. When working with APIs that conflate the two, you may need to make a separate authenticated request to determine whether the 403 is an auth issue or a permissions issue.
What Doesn't Work
Refreshing the page rarely fixes a genuine 403. If the server is refusing your request, reloading the same URL with the same credentials will produce the same result. Clearing your browser cache might help if the issue involves stale authentication tokens stored locally, but it won't resolve server-side permission blocks. Incognito mode is useful for testing whether a browser extension or cached credential is causing the problem, but it's not a general solution. The same applies to switching browsers — if the server is blocking based on your account permissions or IP address, changing the browser won't help. Some people recommend trying a different network or VPN to rule out IP blocking, and this can be legitimate in certain cases. But it's worth noting that many services actively block known VPN and datacenter IP ranges, so switching to a VPN might just replace one block with another. If you suspect IP blocking, the most reliable approach is to contact the site administrator rather than guessing your way through different networks.Preventing Future 403 Errors
If you're the one deploying the service, proper error messaging makes a huge difference. A 403 response that includes a human-readable explanation of why access was denied saves minutes or hours of debugging. Log the specific reason on the server side and expose it through error headers or response bodies when appropriate. Don't leak sensitive information about your security rules, but do tell the user whether they need to log in, request access, or contact support. Implement proper logging on all layers. The WAF log, the CDN log, the reverse proxy log, and the application log should all record the reason for each 403. When incidents happen, having these logs correlated by request ID lets you trace the request through every layer and identify exactly where the block occurred. I've seen teams spend days chasing 403s across multiple services because each service logged the rejection independently without a shared correlation ID.Regular security audits of your access control rules prevent the kind of misconfiguration that causes silent blocks. Permission rules accumulate over time — new endpoints get added, old ones get deprecated, and the access control configuration drifts from the actual intent. A quarterly review of who has access to what, especially on sensitive endpoints, catches these issues before they cause user-facing problems. Automated testing that includes unauthorized access attempts can also catch misconfigurations early in the deployment pipeline.