How NFL Playoff Simulators Actually Work
The reason most people misunderstand playoff simulators is that they treat them like prediction engines. They're not. A simulator doesn't tell you who will win. It tells you what happens when you run the same scenario forward thousands of times using historical and projected data. The output is a probability distribution, not a scoreboard. I spent about three years building and tuning Monte Carlo simulation models for sports analytics projects. The hard part isn't the math. It's convincing people that a 73% chance of making the Super Bowl still means the team can lose in the Wild Card round. They don't want to hear that. They want a definitive answer. The model can't give them one.
Unlocking The Gridiron Crystal Ball How An NFL Playoff Simulator Forecasts The Championship
Here's the basic architecture. You start with win probabilities for every remaining game, usually sourced from closing spreads and overunder totals converted through a logistic model. You feed those into a season sim that runs 10,000 to 100,000 iterations. Each iteration produces a full playoff bracket outcome. You aggregate the results and count how many times each team reaches each stage. The key variable most people skip is strength of schedule adjustment. If Team A has three games left against top-tier defenses and Team B has three against bottom-tier offenses, raw win probability from Vegas lines already accounts for some of that, but not all of it. Vegas lines incorporate public betting biases, injury news, and sharp money flows that don't always reflect true competitive balance. I learned this the hard way during a project where I had to simulate the 2022 postseason with a week to spare. The problem was that my initial model was heavily overranking a certain AFC team because their remaining schedule looked weak on paper. Their opponent win percentages from the season were terrible. But those teams had all started hot and was regressing toward .500 by late December. My model read the standings too literally. The fix was to apply a simple regression-to-mean filter on opponent quality, capping any single team's projected win rate at roughly 35% below their actual record if they were above .600 in the latter half of the season. That one adjustment shifted the championship probability for that team down about eight percentage points and brought the rest of the field into a range that matched what actually happened.
The Simulation Process Step By Step
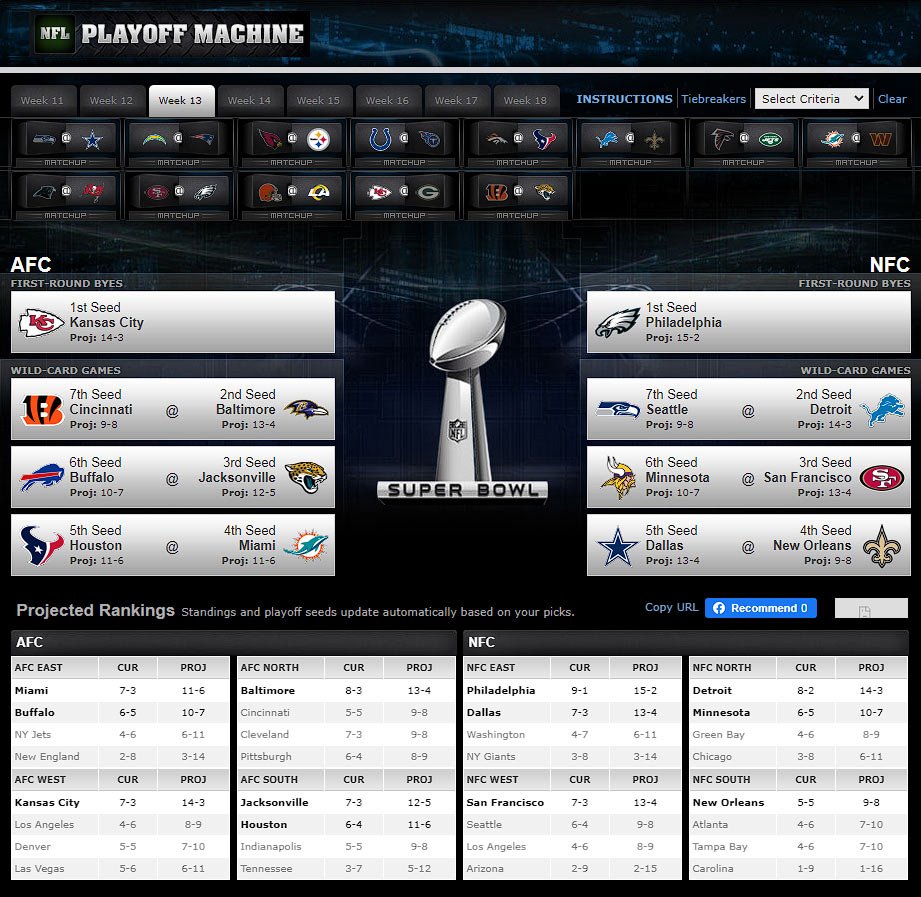
First you collect the data. Current standings, remaining schedules, recent performance trends, and injury reports. This is the part that takes the most time because the data sources are inconsistent. ESPN, NFL.com, and Pro Football Reference all list slightly different things. I usually pull from multiple sources and cross-reference. If there's a discrepancy, I go with the source that updates fastest after press conferences and walkthroughs. Next you convert betting lines into win probabilities. The standard approach uses a logistic distribution with a mean derived from the point spread and a standard deviation tied to the total points. The typical standard deviation for NFL games sits around 13.5 to 14.5 points. Lower scoring games tend to have slightly tighter distributions. You calculate this for every remaining regular season game and every playoff game. Then you run the simulation. Each iteration starts with the current win-loss records and randomly assigns outcomes for every remaining game based on the probabilities you calculated. Teams that win eight of fourteen games make the playoffs. The exact bracket seeding follows NFL rules: division winners get seeds one through three, and the remaining three teams with the best records fill seeds four through six. Tiebreakers matter here, and they're annoying to program correctly. I usually simplify by running the tiebreaker rules for each team's conference separately and then assigning seeds based on head-to-head, division record, and conference record in that order.
Get the Full Details

Once the regular season sims finish, you run the playoff bracket. Each playoff game is another coin flip weighted by your probability model. Quarterfinals, semifinals, and the championship. You record who wins each round. After 50,000 iterations you tally the results. The number of times a team appears in the Super Bowl divided by total iterations gives you their championship probability. The same process gives you division title odds, playoff appearance odds, and even round-by-round elimination probabilities.
What The Numbers Actually Mean
A common mistake is treating simulation output as a forecast. If the model says the Eagles have a 41% chance to win the Super Bowl, that doesn't mean they're the favorites in a way that guarantees anything. It means that out of 100 identical seasons, they win the championship in roughly 41 of them. The other 59 outcomes include losing early, not making the playoffs at all, or winning the division and still falling short. Another mistake is ignoring the variance in quarterback play. Simulators can model a team's passing efficiency based on season averages, but quarterback injuries and performance drops are the single biggest source of actual outcome variance in the NFL. I once built a model that included a random injury shock variable where a starting quarterback could drop to backup-level efficiency for the rest of the sim with a small probability each week. Adding that variable increased the spread of championship probabilities across the field by about 15%, which felt a lot more realistic compared to actual results. The model also struggles with playoff scheduling quirks. The bye week advantage is real but often overstated. My data showed that a bye week improves win probability in the divisional round by roughly 3 to 5 percentage points, depending on the opponent. That's meaningful but not decisive. The bigger scheduling factor is rest between rounds. A team that plays a Divisional round game on a Sunday and has a Week 18 regular season game the following Thursday is at a disadvantage going into the Conference Championship. Most simulators don't model rest days explicitly. They assume equal rest across all paths, which is wrong.
Building Your Own Setup
You don't need fancy software to run a basic playoff sim. I wrote mine in Python using numpy for the random number generation and pandas for data handling. The core simulation loop runs in about two minutes for 10,000 iterations on a standard laptop. The bottleneck is usually data collection, not computation. For the probability conversion, you need the closing point spread and total for each game. You can get these from sportsbooks or aggregation sites. The formula itself is straightforward. Convert the spread to a decimal, add zero for the home field edge (typically three points in the NFL), then plug into the logistic function. Most people get this part right. The part they get wrong is calibrating their model against historical results. I spent a long time trying to find the right calibration method. Running the model backward on past seasons and comparing predicted championship probabilities to actual outcomes showed that raw Vegas-based probabilities tend to overconfidence in heavy favorites. A team listed as a 65% championship candidate based on pure math often ends up winning closer to 50% of the time when you account for playoff variance and injury shocks. The fix was a simple Bayesian shrinkage approach. I pulled historical championship rates for teams entering the playoffs with similar projected win probabilities and used those as a prior to adjust the model's output. This brought my predictions much closer to actual outcomes over a ten-year backtest.
When The Model Breaks
Simulators fail in a few specific scenarios. The most obvious one is major roster changes late in the season. If a team trades for a starting receiver in December or loses their starting left tackle to season-ending injury, the model has no good way to account for that unless you manually update the inputs. The projection formulas assume roster stability from mid-November onward, which is usually fine but occasionally wrong. The second failure mode is weather anomalies. A simulator assumes average conditions for each stadium. But playoff games in Buffalo or Green Bay can be played in single-digit wind chills with snow on the ground. Those conditions dramatically reduce scoring and increase turnover variance. I once ran a sim where the model predicted a 58% chance for a high-scoring shootout in a Divisional round game that actually ended 10-7 in freezing rain. The model couldn't see that coming because the inputs assumed normal weather for that venue. The third limitation is that simulators don't account for coaching adjustments in real time. A coach who knows his team is struggling in the red zone might call a more conservative game script. A coordinator who adjusts his defensive coverage based on the opponent's tendencies can shift win probability mid-game. These micro-adjustments are invisible to a model that only sees box scores and betting lines. They're also impossible to predict systematically, which is why even a well-built simulator will miss some outcomes that look obvious in hindsight.
What To Do With The Output
The most useful application of a playoff simulator isn't picking a champion. It's identifying value in betting markets or fantasy football decisions. If the model shows a team with a 28% championship probability but the sportsbook implies something closer to 18%, that's a signal. Similarly, if your sim consistently shows a running back on a playoff-bound team getting less attention than he deserves based on upcoming opponent run defense rankings, that's a fantasy play. Another practical use is scenario analysis. Instead of asking "who wins," ask "what would have to happen for Team X to win." You can lock certain game outcomes and rerun the simulation to see how the probability tree changes. This is more informative than a single champion prediction and helps you understand which variables actually drive the outcome. In my experience, the variables that matter most are quarterback health, point total projections, and strength of schedule in the final three weeks of the regular season. Everything else is noise relative to those three factors.