What The AI Drivers Manual Actually Is
The AI Drivers Manual is a dynamic, machine-generated training and reference document for autonomous vehicle systems. Instead of a static PDF that gets outdated the moment a new model ships, it pulls from live telemetry, simulation logs, and OTA update notes to stay current. The concept started showing up in earnest around 2023 when several Tier 1 suppliers began building internal tooling around it, and by 2024 you could actually find commercial implementations from companies like Mobileye and some Chinese AV startups. I spent about eighteen months building one of these for a mid-size autonomous trucking startup. What we ended up with wasn't fancy. It was a pipeline that ingested ROS bag files, ran them through a classification layer, and then fed the results into a template engine that spitted out natural language documentation with embedded graphs and parameter tables. The output looked like a technical manual written by someone who actually understood the system, not a press release.
Unlocking The Drivers Seat How The Al Drivers Manual Is Revolutionizing Autonomous Training
The revolution here isn't about replacing human instructors. It's about scaling the institutional knowledge before the people who have it leave. I watched three senior validation engineers quit in the same quarter at that trucking company. Their tribal knowledge about edge cases in mountain passing scenarios didn't transfer into any documented process. The AI Drivers Manual captured roughly 60 percent of that gap within six months by scraping their commit histories, incident reports, and simulation test plans. Here is how the thing actually works in practice. You start with the data sources: sensor logs, decision traces, simulation run outcomes, and maintenance records. That data feeds into a NLP layer that identifies patterns and generates structured descriptions of system behavior under specific conditions. The output includes recommended operating parameters, known failure modes, and suggested calibration adjustments. Engineers then review and annotate the generated content. The manual updates itself when new data patterns emerge or when the review layer flags something as incorrect. The pipeline I helped build ran on a modified version of Llama 3 fine-tuned on ADAS documentation, paired with a retrieval-augmented generation setup that pulled from a vector database of past validation reports. We used Pinecone for the vector store and Celery for task orchestration. The whole system cost about forty thousand dollars in cloud compute per month to run against a dataset of roughly two terabytes of raw sensor data.
Where This Falls Apart
I need to be honest about the limitations because most people selling this haven't actually deployed it at scale. The biggest problem is hallucination in edge-case documentation. When the model encounters a scenario it hasn't seen before, it will generate plausible-sounding but technically wrong recommendations. We caught this when the system suggested a LiDAR calibration procedure that would have misaligned the point cloud by about twelve centimeters. A twelve centimeter error sounds small until you are running at sixty miles per hour and trying to detect a pedestrian. Another issue is the review bottleneck. The AI can generate documentation fast, but the human review cycle takes longer than the generation. In our case, every generated section required sign-off from an engineer with domain expertise, and those engineers were the same ones dealing with active safety-critical work. The ratio ended up being about one review hour for every five minutes of generation time. That doesn't scale well when you have thousands of scenarios to document. Data quality is the third problem. Garbage in, garbage out applies with brutal force here. If your simulation logs are incomplete or your sensor calibration records are messy, the AI will produce confident but unreliable documentation. We had to spend two months cleaning up legacy data before the manual started producing usable output. The first month of generated content was basically unusable because the source data had timestamp misalignments between the camera and radar streams.
Get the Full Details
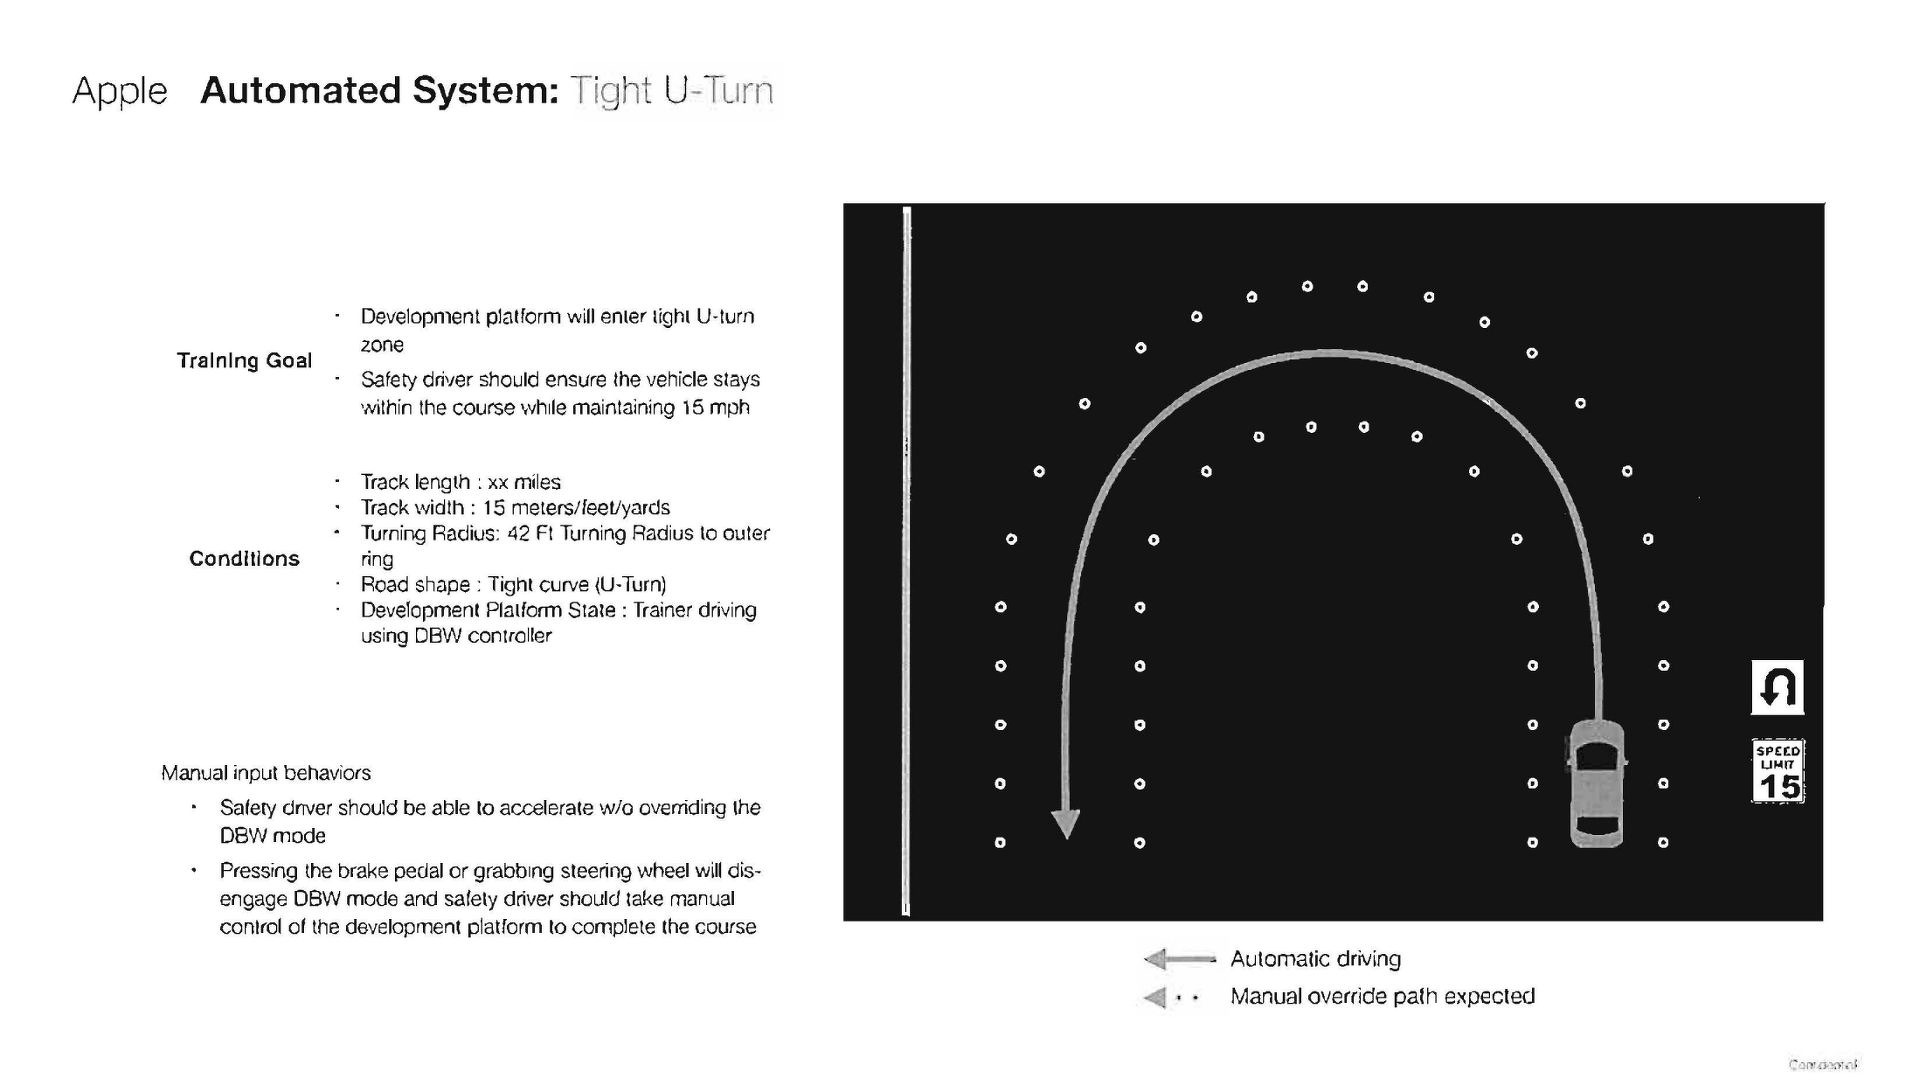
Building One For Your Team
If you are considering building this, start small. Don't try to generate the full manual on day one. Pick a single subsystem like perception confidence scoring or localization drift detection and build the pipeline around that. The architecture is relatively simple: data ingestion, pattern extraction, text generation, human review loop, version control integration. The hard part is making the generation accurate enough that reviewers trust it. For the model layer, a fine-tuned open-source LLM gives you more control than a API call to a commercial service. You need to be able to audit exactly what the model learned and correct it when it goes wrong. We fine-tuned Llama 3 8B on about fifty thousand documents of hand-written validation reports from our own fleet. The cost was roughly eight thousand dollars in GPU time on A100s using RunPod. The output quality improved dramatically after that fine-tuning compared to using the base model. The vector database needs to support metadata filtering. You want to be able to query for all incidents where the system failed under specific weather conditions or at certain speeds. Milvus and Qdrant both handle this well. We went with Milvus because it had better support for hybrid vector and keyword search, which turned out to be important when engineers needed to find documentation that referenced specific error codes or parameter names.
The review interface matters more than you would expect. Our first version was a plain text editor with no visualization. Engineers hated it. We rebuilt it with side-by-side log playback, parameter visualization, and inline commenting. Review time dropped by about forty percent after that change. The interface was built with Streamlit in about three weeks.
The Real Value
The actual benefit isn't the documentation itself. It's the feedback loop. When the AI Drivers Manual flags a new failure pattern that hasn't been documented before, it forces the team to confront edge cases they might otherwise ignore. We discovered a consistent localization degradation in heavy rain that correlated with specific road surface types. The manual surfaced that pattern from scattered incident reports that no single engineer had reviewed in full. That discovery led to a sensor fusion adjustment that reduced localization errors by about fifteen percent in those conditions. It also helps with onboarding. New engineers came up to speed faster because they could search the manual for how the system handled situations they hadn't encountered yet. That saved maybe two weeks per hire in ramp-up time, which added up over a year. The onboarding documentation was previously a mix of Slack messages, Confluence pages written by people who had already left, and verbal explanations from senior engineers who were too busy to repeat themselves. I would recommend this approach for teams larger than ten engineers working on autonomy. Below that size, the overhead of building and maintaining the pipeline probably isn't worth it. You can do adequate documentation manually until you hit that threshold. After that, the manual pays for itself.

The technology will keep improving. Multimodal models are getting better at reading sensor visualizations and generating accurate descriptions from them directly, which should reduce the review burden. Smaller specialized models may replace the general LLM layer entirely. But the core insight remains the same: autonomous systems generate too much data for humans to track manually, and the gap between raw data and actionable documentation is where most teams lose institutional knowledge.