What Actually Holds Your System Back
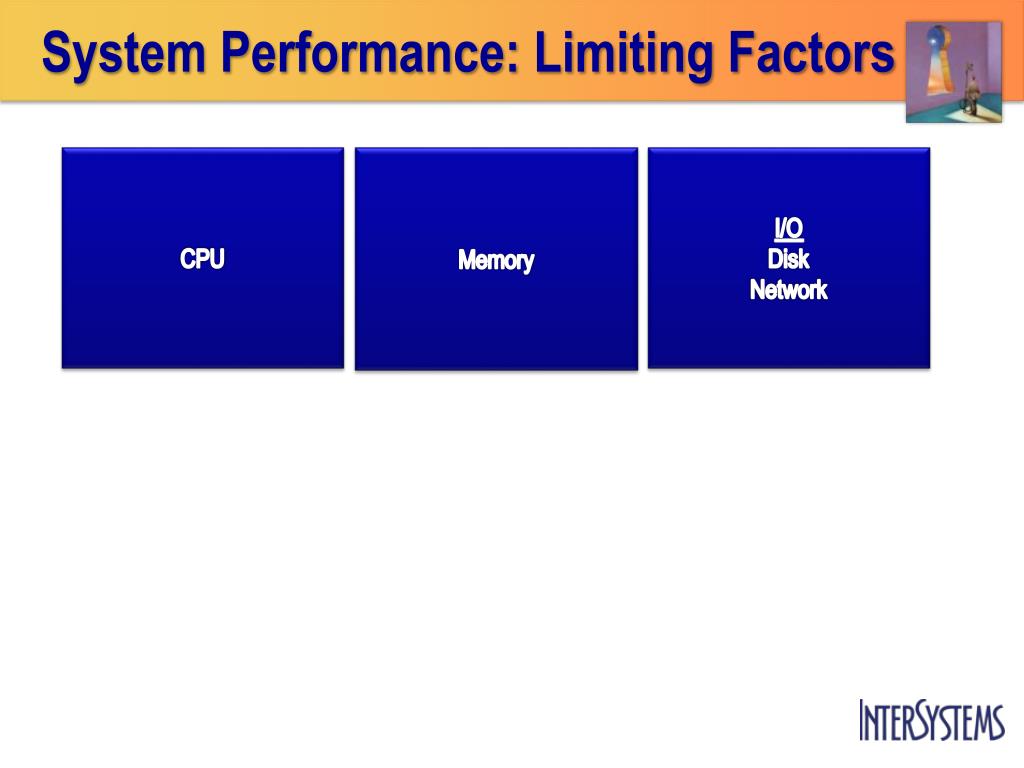
The limiting factor is whichever resource hits its ceiling first. That is the entire definition. People overcomplicate this because they want a single tool or command that solves everything. It does not work that way. I spent three years trying to force teams to look at CPU when the real problem was disk I/O. We ended up swapping out SSDs for cheaper ones because the bottleneck was elsewhere and the whole exercise was wasted. Before you start chasing numbers, you need a framework that tells you where to look. Here is the practical approach.
Unlocking System Performance The Definitive Limiting Factor Definition Guide
Start by mapping your workload. Write down what the system does under normal conditions. What goes in, what comes out, where data sits, how many threads are active. Most people skip this because it feels like paperwork. It is not paperwork. It is the difference between guessing and knowing. Next, measure each resource at the same time. CPU usage, memory pressure, disk throughput, network latency, and IOPS. Run your typical workload while you capture all of these simultaneously. If you measure one in isolation and another on a different day, you are not getting data, you are getting noise. I once worked on a database cluster where every metric looked fine in individual tests. CPU sat at 40 percent, memory was half full, network was idle. The application felt sluggish. What we missed was that the storage controller had a write buffer that filled up after about eight minutes of sustained writes. Once it saturated, every write request stalled waiting for flash to catch up. The CPU sat there looking bored. The fix was not more CPU or more RAM. It was a controller cache battery replacement and a rewrite of the transaction commit pattern to batch smaller writes. Took about an hour of investigation once we knew where to look. Would have taken weeks if we kept running benchmarks in circles.
The limiting factor shifts depending on load. This is the part that catches people off guard. A system might be CPU-bound at low concurrency, switch to memory-bound at moderate load, and become I/O-bound under heavy traffic. You need to map this across your actual operating range, not just the peak scenario. Run tests at 25 percent, 50 percent, 75 percent, and 100 percent of expected load. Plot the results. The curve that saturates first is your limiting factor at that level. When you identify the factor, you optimize it. But you do not optimize beyond the point where the next resource becomes the new bottleneck. This is called the law of the drum in Theory of Constraints and it applies identically here. I had a team that optimized a query to reduce a lock contention window from 200 milliseconds to 12 milliseconds. The system got faster, but then the network switch became the new ceiling. They had to upgrade the switch tier just to see the benefit of the code change. Budget blowout for a marginal gain that would have been visible without the premature optimization. There are tools for this. top and htop for quick CPU and memory snapshots. iostat for disk metrics. vmstat for a combined view. bpftrace or dtrace when you need deeper kernel-level insight. Perf is good for CPU pipeline analysis. For application-level tracing, systemtap or eBPF-based tools like bpftrace scripts will show you exactly where time is being spent inside calls. Do not collect all of this at once across a production system without a plan. These tools add overhead. Sample at intervals that make sense for your workload, not every millisecond.
Get the Full Details

A counter-intuitive thing to keep in mind: sometimes the limiting factor is not a resource at all. It is the scheduler. On Linux, the CFS (Completely Fair Scheduler) can create artificial contention when many CPU-intensive tasks compete, even when total utilization is well below 100 percent. I ran into this with a real-time audio processing app that stuttered only when three background services were also running. CPU was at 60 percent total. The fix was setting SCHED_FIFO for the audio thread and cgroup restrictions for the background services. Not a hardware issue. A scheduling issue. People buy servers for this. Another thing beginners miss is the difference between utilization and saturation. A CPU at 90 percent utilization is not necessarily the bottleneck. A CPU at 90 percent utilization with zero run queue is doing heavy computation and finishing fast. A CPU at 40 percent utilization with a run queue of 20 is severely thrashing. Check the run queue length and average load, not just the percentage. w and uptime give you this. On multi-core systems, divide the load by core count. If the result is above 1.0, you are saturating. Memory is another area where people read the wrong number. Free memory on Linux is mostly cache. If your system has 2 GB free but 60 GB of page cache, it looks like you have plenty of headroom. You do not, not in the way that matters for active working sets. Check free -h and then look at /proc/meminfo for Dirty, Writeback, and Cached separately. The key numbers are Active(anon), Inactive(anon), and SwapUsed. When swap is actively used during your workload, memory is your limiting factor regardless of what free reports.
I need to be honest about where this approach breaks down. It does not help you when the bottleneck is external. If your application depends on a third-party API that adds 800 milliseconds per call, no amount of local optimization will fix the response time. The limiting factor is outside your system boundary. Same thing with shared infrastructure in cloud environments where you do not control the hypervisor or the physical host. You can measure, but you cannot always resolve. In those cases, the workaround is architecture change, not tuning. Break the dependency, add caching, or move to a different provider tier. Measuring the unmeasurable is a waste of time. There is also the problem of transient bottlenecks. A task that runs for ten seconds every four hours can dominate your user experience even though it barely moves the aggregate numbers. A nightly report generation job that locks a table for three minutes will make the system feel broken during that window while your hourly averages look healthy. You need distributional data, not just averages. Look at p95 and p99 latencies, not mean. datadog, prometheus with histogram buckets, or even simple logging with percentile calculations will show you what the average hides. The process is iterative. Identify the current limiting factor. Optimize it. Re-measure. Find the new limiting factor. Repeat. Each cycle should give you diminishing returns, and you stop when the cost of further optimization exceeds the value of the improvement. I have seen teams spend months shaving milliseconds off a pipeline that only ran once a day. The math never works out.
If you want a download link or a script to automate the measurement phase, there are open-source options. netdata provides real-time dashboards with minimal setup. pmm (Percona Monitoring and Management) is heavier but gives you historical data and query-level breakdowns for databases. For a lightweight custom approach, a combination of cron-triggered iostat -x 1 300, vmstat 1 300, and mpstat -P ALL 1 300 piped to a CSV file will give you five minutes of clean data to analyze without installing anything extra. The bottom line is that identifying the limiting factor is straightforward in theory and tedious in practice. It requires looking at the right metrics at the right time and resisting the urge to optimize what looks broken rather than what actually is. Your system is only as fast as its slowest part, and that part changes. Keep measuring.