Dealing With Missing Symbols In Tabular Data
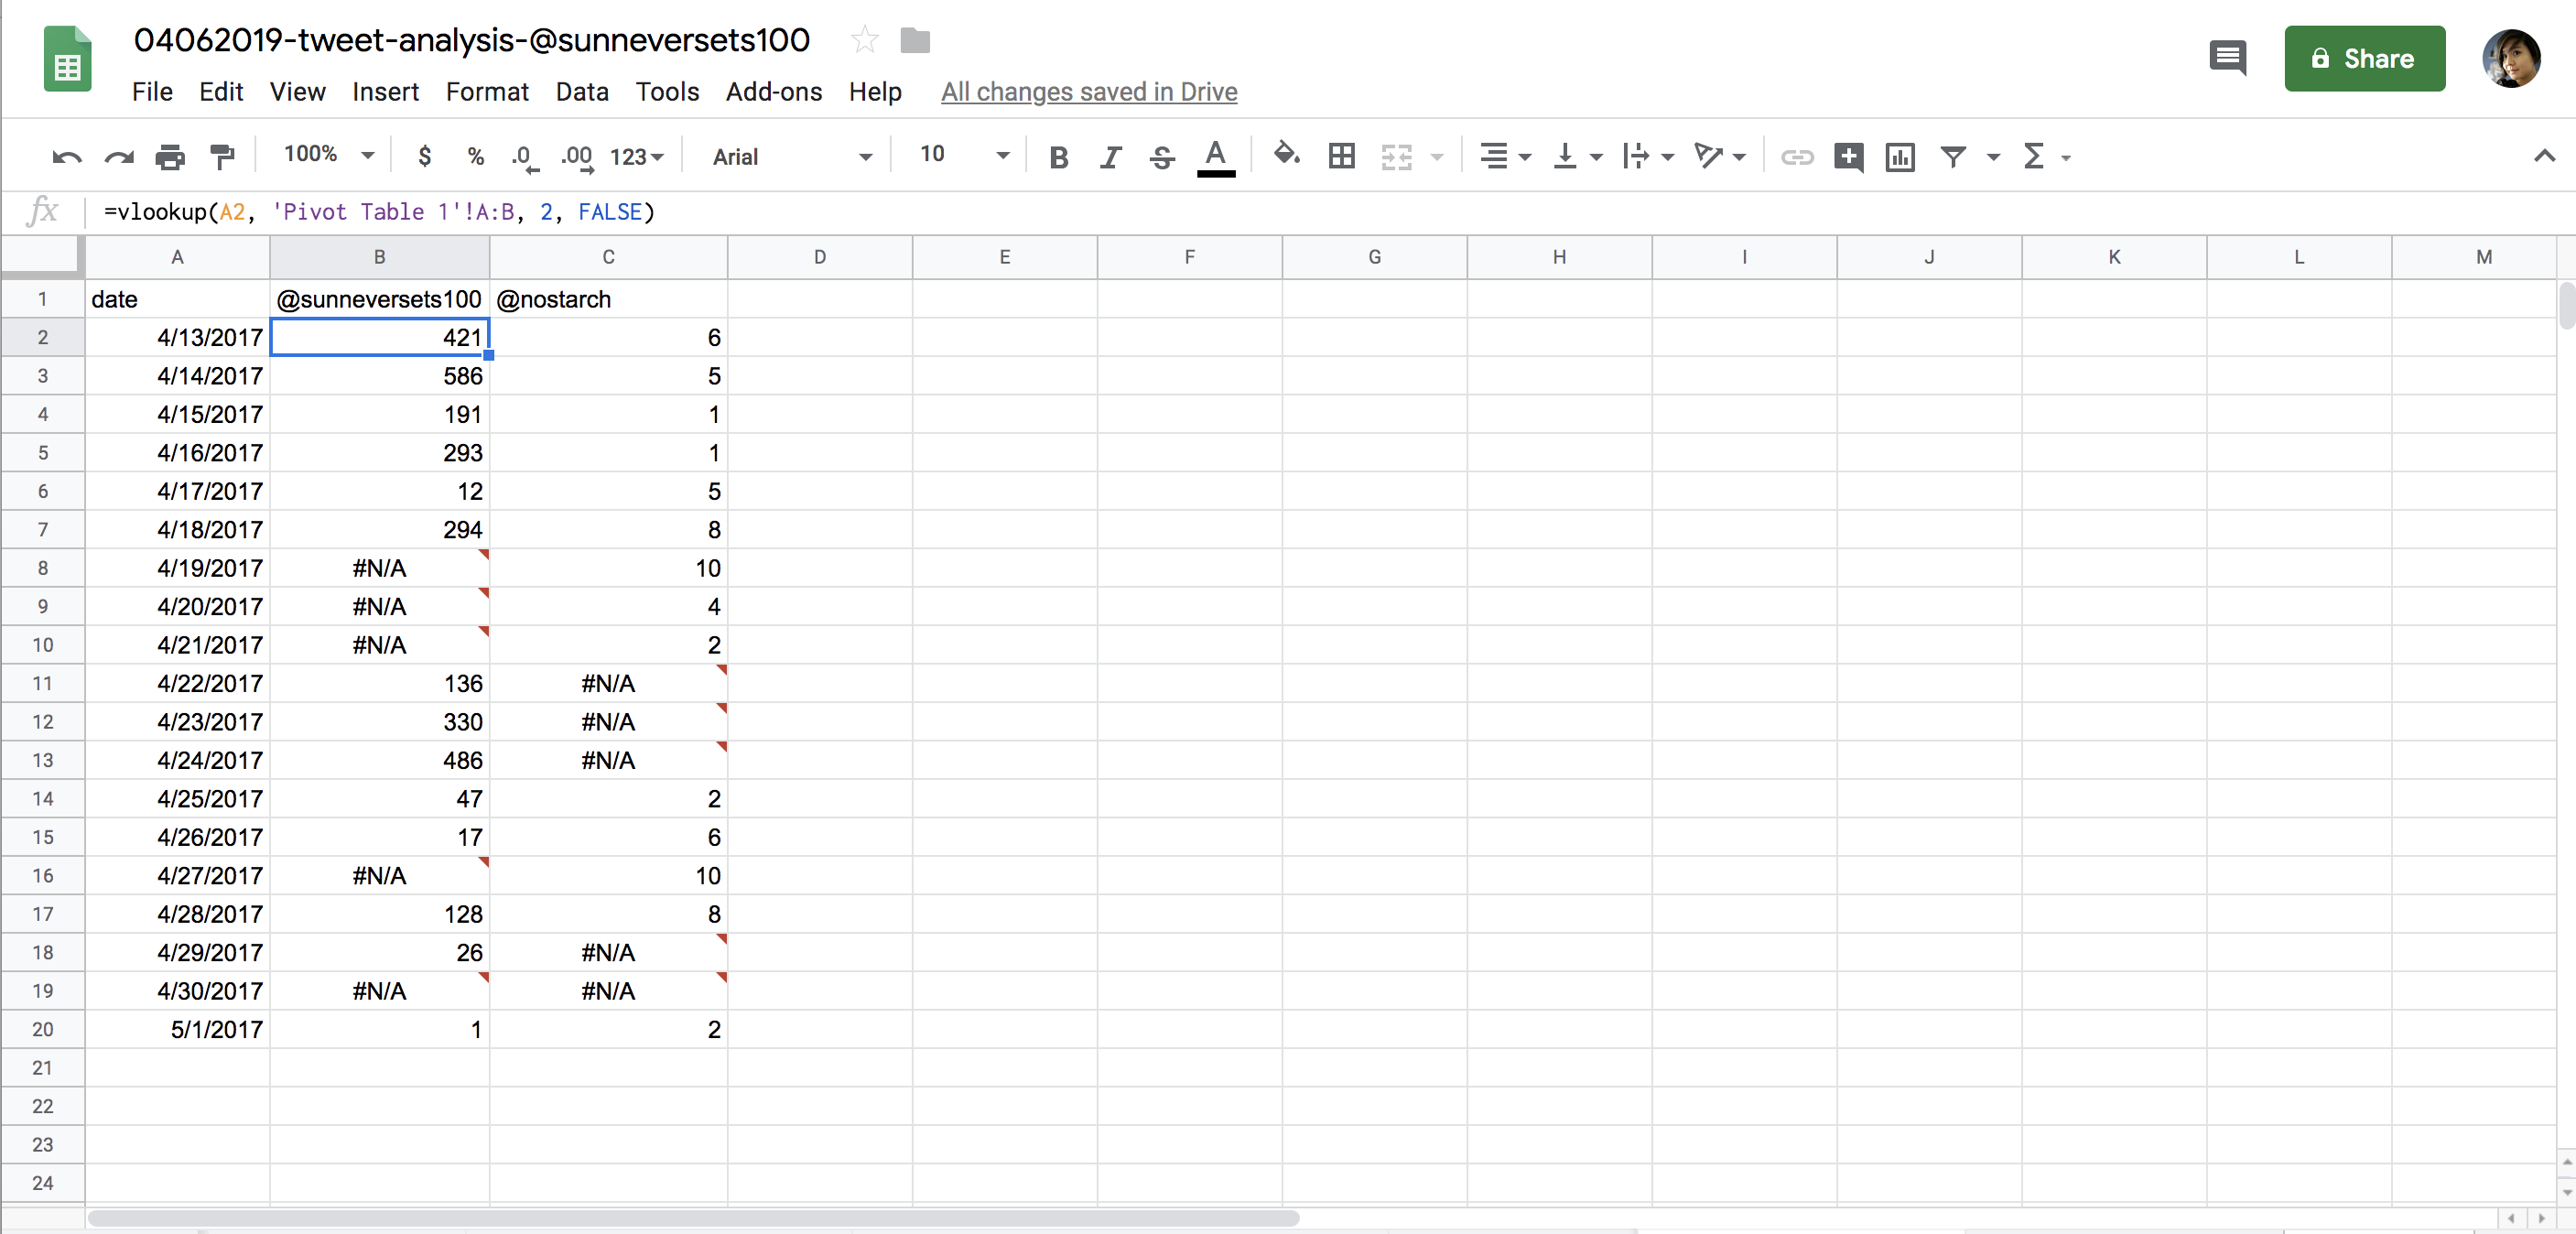
You pull a dataset from a legacy system, open it in whatever tool you have running, and immediately notice the symbol column is full of gaps. Sometimes a plus sign is missing. Sometimes a negative operator just vanishes. Sometimes entire rows have empty cells where a symbol should be. This is one of those routine but annoying data quality problems that shows up constantly, and it is not worth the panic you might feel the first time you see it. The core issue is that blank symbol columns usually mean one of three things. The first is actual missing data, where the source simply did not capture the value. The second is a data entry error, like a user leaving the field blank because they assumed a default applied. The third is a parsing artifact, where a downstream export process dropped certain characters during a transformation step. Your approach changes depending on which one you are dealing with, so I need you to stop treating every blank the same way. I spent about two years working with transaction tables where the operator symbol field was inconsistently populated across different regional feeds. The worst case I ran into involved a batch export from a financial platform where the plus symbol was stripped entirely whenever the preceding value was positive, because the system stored everything as unsigned integers and only carried a sign flag elsewhere. The blank symbol did not mean zero or missing, it meant the row was structurally positive by design. If I had just filled every blank with a default operator, the subsequent reconciliation would have been wrong by a significant margin.
The first step is always to check the raw source before you touch anything in your analysis environment. Look at the import file, the API response, the database dump, whatever generated the table. See if the blanks correspond to a pattern. Are they clustered in certain date ranges? Do they correlate with a specific region, user segment, or data pipeline job? When I noticed the positive-only bias in my financial example, the workaround was straightforward: I joined the transaction table back to the source system on the primary key and pulled the separate sign flag field, then reconstructed the operator column from that. That took about twenty minutes once I mapped the join keys correctly.
When To Impute Versus When To Leave Blank
A common mistake beginners make is automatically filling blank symbols with a default value, usually a plus or an equals sign. This works in narrow cases and fails loudly in others. If you have reason to believe the missing symbol is actually information, then imputation is the right call. If the blank genuinely means no operator was recorded and you have no way to recover it, you leave it blank and document the gap. Here is the nuance most guides skip over. In many analytical workflows, a missing symbol in a comparison table actually breaks downstream joins or aggregations silently. You end up with grouped totals that look fine until someone notices the discrepancy and traces it back three layers of transformation. The real fix is often to treat the blank symbol as its own category during aggregation, rather than silently converting it to a standard operator. You can handle this by converting the symbol column to a string type that preserves blanks, running your group-by operations, and then checking the output for a null category that might be swallowing rows you thought were accounted for. I have seen people waste half a day debugging a sum that was off by a few thousand dollars only to discover the blank symbol rows were being excluded from the aggregation because the column was typed as an integer, and null integers simply do not participate in the sum the way people expect them to. Switching the column to a nullable string type and explicitly filtering for null symbols resolved it in about five minutes.
Get the Full Details
Practical Steps For Routine Cases
If your blanks are straightforward missing values and you have enough context to infer the correct symbol, here is what I usually do. First, check neighboring rows. In sequential tables, especially ones sorted by a primary key or timestamp, adjacent rows often share the same operator. A simple forward-fill or nearest-neighbor imputation can recover values without introducing bias, provided the sequence is logical and you are not dealing with a flagged or manually edited column. Second, cross-reference with other columns in the same row. If you have numeric values before and after a comparison operator, you can often deduce the symbol by reverse calculation. A row with values forty and fifty and a blank symbol between them is almost certainly a less-than relationship, unless you are working in a domain where the convention is reversed. I keep a small lookup script for this because manual eyeballing gets tedious past a few hundred rows. Third, check your data dictionary or schema documentation. Some systems use blank symbols intentionally to represent a state, like pending comparison or undetermined classification. I once worked with an inventory table where a blank symbol meant the item had not yet been assigned to a warehouse zone, which was meaningful information on its own. Filling those blanks with an operator would have destroyed that signal.
When The Method Fails Completely
There are scenarios where filling in blank symbols is not worth the effort. If more than ten percent of the column is blank and there is no recoverable source or logical inference path, you are better off excluding the column from that analysis and noting the limitation. Chasing ghost values introduces more error than you save in completeness. I have flagged these cases to stakeholders and moved on, usually cutting the reconciliation time from a full day down to an hour of documentation and a clean exclusion note in the methodology section. The same applies when the table comes from multiple pipelines with inconsistent symbol conventions. Merging a dataset where one source uses + and another uses P for positive is not a filling problem, it is a normalization problem, and you need to standardize the encoding before you even think about imputation. Otherwise you are just creating a mess that looks clean on the surface. My final recommendation is to write down exactly what you did with every blank cell you encountered, whether you left it blank, inferred it, or pulled it from a source field. Future you will appreciate the trail when someone asks why a particular aggregation differs from the previous quarter's numbers. That is usually the only thing that matters at the end of the day.