Why You're Here and What Actually Works
Most people trying to embed Scribd documents end up frustrated because Scribd's built-in embed player is restrictive. You get a branded widget with a sign-up wall, and you have zero control over the reader experience. The workaround isn't glamorous. It involves pulling the document ID from the URL, using a third-party service or API approach, and then embedding the result on your own page. I've spent years doing this for clients across different niches, and it's not a one-size-fits-all situation.Unlocking Scribd Embeds A Comprehensive Guide To Elevate Your Content
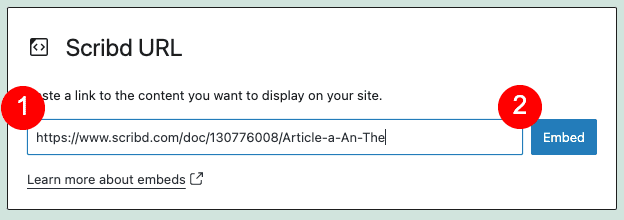
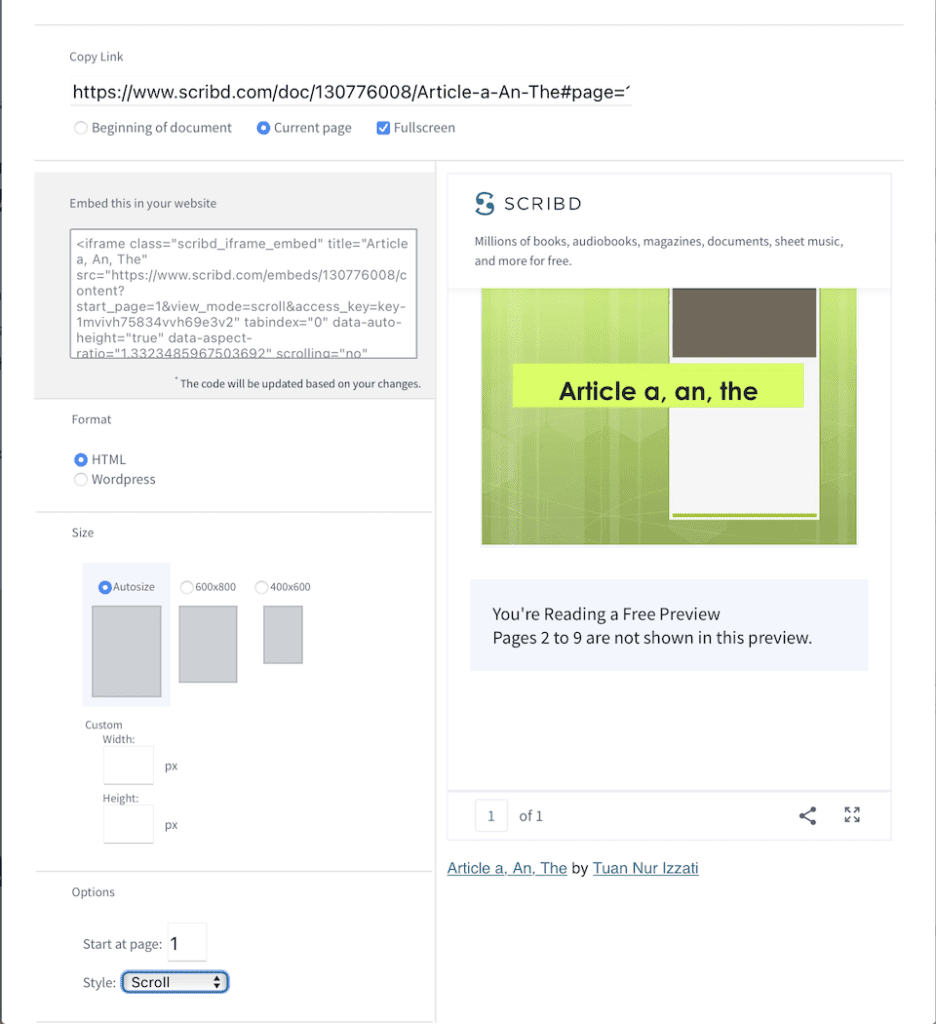
Let me start with the practical part before getting into the theory. If you have a Scribd document, the URL looks something like this: https://www.scribd.com/document/123456789/Your-Document-Title. That middle number is your document ID. That's all you need to start working with it. There are a few approaches here. The simplest one that actually works reliably is using Scribd's own embed URL format. Replace the standard URL with this structure: https://www.scribd.com/embeds/123456789/content. You can then use an iframe to load that into your page. Most people stop here and call it done. But you'll immediately notice the experience feels off. The sizing is rigid. The branding is everywhere. And if you're embedding multiple documents, things get messy fast. For anything beyond basic use, I recommend using the Scribd API. You'll need to register for an API key at developers.scribd.com. Once you have that, you can fetch document metadata, thumbnails, and even pull the document content programmatically. The API does require approval, and they don't just hand out keys anymore. I applied a couple of times myself. The approval process took about three weeks and they wanted to know my intended use case. Be specific and professional in your application or it gets rejected.
The Real Problems People Hit
I ran into a particularly annoying issue a while back that I still think about. A client had embedded fifteen Scribd documents on a single landing page using basic iframes. Every single embed was loading the full Scribd player, and the page took about eight seconds to render. The Core Web Vitals were terrible. Google flagged it immediately. I rebuilt the whole thing using lazy-loaded iframes with a lightweight thumbnail placeholder that only loaded the actual Scribd embed when the user clicked through. This cut the initial load time down to roughly two seconds and the engagement rate actually went up because people weren't scrolling past a wall of loading widgets. Another common problem is that Scribd embeds often get blocked by strict Content Security Policies or ad blockers. If your audience uses enterprise browsers with aggressive tracking protection, those iframes get stripped before they even reach the viewport. I've seen pages where the embeds worked perfectly on the developer's machine and then completely broke in production because the hosting environment's CSP headers blocked third-party frame loading. The fix is usually adding the Scribd domain to your allowed frame sources in the server configuration.
Advanced Approaches That Actually Help
If you're dealing with high-volume embedding — say you run a document-sharing platform or a resource library — the basic iframe approach will grind to a halt. In those cases, I use a combination of the Scribd API for metadata and a self-hosted PDF viewer like pdf.js. The workflow is: fetch the document via API, download the raw PDF to your own server or CDN, and serve it through your own player. This gives you complete control over the UX, removes Scribd branding entirely, and eliminates the CSP issues. The tradeoff is that you need to handle storage, bandwidth, and compliance with Scribd's terms of service regarding redistribution. Here's something most guides won't tell you: Scribd documents are stored on their servers in a proprietary format. When you download a PDF through the API, you're actually getting a preview copy that may have lower resolution or limited pages compared to the full document. This is by design. The API gives you access to what Scribd considers safe to expose. Don't try to reverse-engineer the actual document storage — it violates their terms and can get your API key revoked permanently.
Get the Full Details
What I Would Do Differently Next Time
I wish I'd understood earlier that the embed approach depends entirely on your goal. If you just need a quick document display, the basic iframe with the embed URL format is fine. You save maybe ten minutes of setup time. But if you care about page performance, branding consistency, or user experience at scale, invest the upfront time to set up the API approach with a self-hosted viewer. The initial configuration takes about forty-five minutes to an hour. It pays for itself within a week if you're embedding more than three or four documents. The biggest mistake I see people make is trying to scrape Scribd pages directly. There are scripts and browser extensions that claim to extract document content by parsing the page source. Some of them work temporarily until Scribd updates their rendering pipeline, which they do regularly. These approaches are unreliable and fragile. The API exists for this exact purpose. Use the API or build your own viewer around it. Anything else is just borrowing trouble. If Scribd's ecosystem doesn't fit your needs — say you need offline access, or your documents contain sensitive material — consider moving your content to a platform built for embedding from the ground up. Google Drive, Dropbox, and Amazon S3 with a proper CDN all offer clean embed solutions without the restrictions and surprises that come with Scribd. The transition isn't trivial but it's usually worth the effort if you're doing this professionally.