Starting from a Production Issue That Cost Us a Week
We had a client application running on an ASP.NET MVC stack where the home page response time jumped from 200 milliseconds to over 12 seconds during a traffic spike. The database connections weren't the bottleneck, the CPU was barely taxed at 40 percent. What actually broke was the way we were structuring our controllers and views together. Everything lived in the same project, views were referencing model classes directly in ways that forced database queries inside view rendering code, and we had no caching layer at all. It took us three days just to trace where the queries were coming from because the architecture didn't make the data flow obvious. This is the kind of situation that forces you to think about Unlocking Scalable Web Development Mastering Nj Mvc Website Architecture in a practical way, not an academic one. The theoretical MVC pattern is simple enough. The reality of making it scale is where the work actually happens. After we restructured that project, response times dropped back under 300 milliseconds even at three times the previous traffic. Here is how we did it and what I wish we had known before starting.
Unlocking Scalable Web Development Mastering Nj Mvc Website Architecture
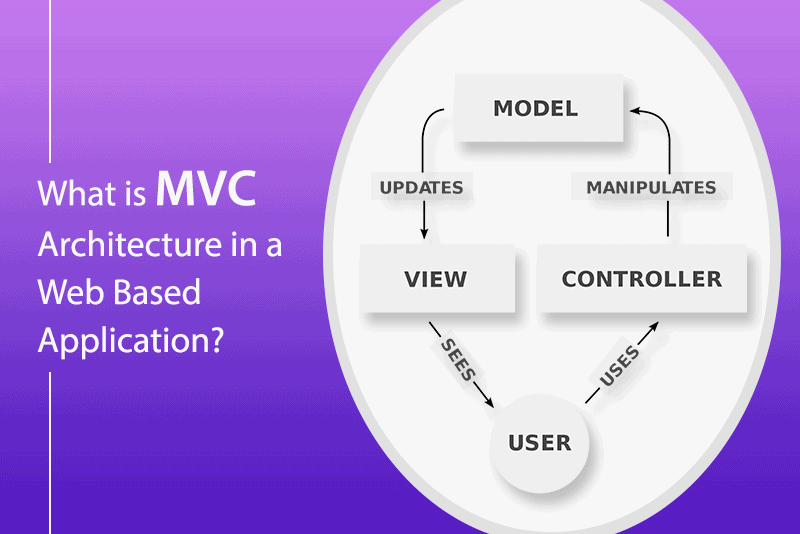
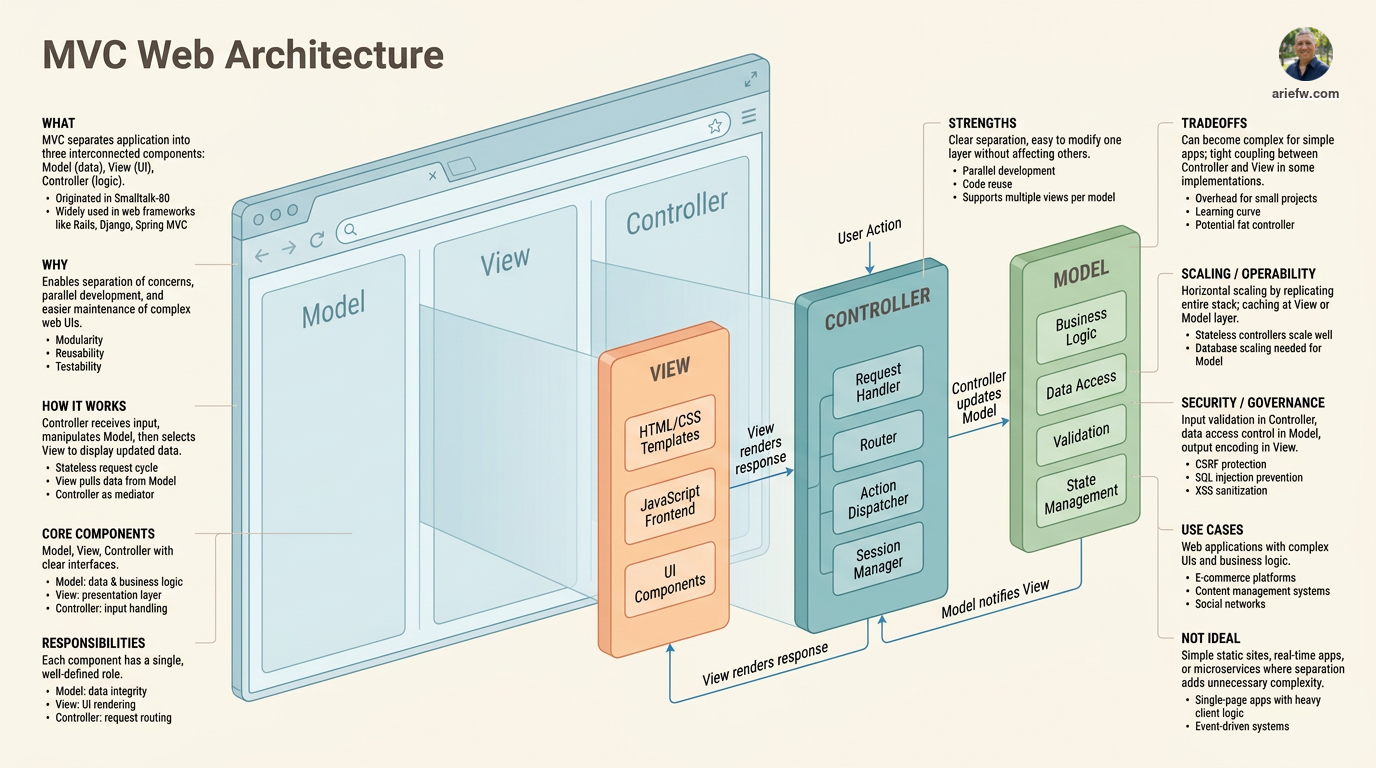
The MVC pattern itself breaks an application into three parts. The model handles data and business logic. The view renders the user interface. The controller sits between them and manages the flow of requests. In a small project, this separation feels like overhead. In a large project, it is the only thing that keeps the codebase from becoming an unmaintainable mess. The question is not whether you should use MVC. It is whether your implementation of MVC can handle growth without breaking apart. One thing most tutorials do not emphasize enough is that the controller is often where scalability problems start. Controllers in ASP.NET MVC are designed to be lightweight request handlers, but in practice they tend to accumulate business logic over time. You add a feature, someone puts the logic directly in the controller action. Another feature comes along, the same pattern repeats. Six months later, your controllers are several thousand lines long and calling repositories in ways that are hard to test or optimize. The solution is to enforce a strict boundary. Controllers should only accept input, call a service or handler layer, and return a result. Nothing else belongs there.
Structuring the Project for Scale
When I talk about project structure, I am not referring to folder organization for aesthetics. I mean the actual dependency relationships between layers. A scalable MVC application should be organized so that changes in one layer do not force recompilation or redeployment of unrelated layers. In practice, this means splitting your code into at least three assemblies: a domain layer, a service layer, and a presentation layer. The domain layer contains your entities, value objects, and domain events. It has zero dependencies on any external framework or library. The service layer contains your application logic, orchestration, and interaction with databases through repositories. The presentation layer is your MVC project, which depends only on the service layer. This structure might feel like extra work upfront, but it prevents the kind of tangled dependencies that make scaling painful. When you need to add a new API endpoint or swap out a data provider, you can do it without touching the controllers or views. I learned this the hard way on a project where we started with a single project containing everything. By the time we realized we needed to add a REST API alongside the existing MVC frontend, we had spent two weeks untangling references between our view models and database entities. The fix was to extract the domain layer first, which meant rewriting half the existing code. If we had structured it properly from the start, that work would have taken maybe a day.
Get the Full Details
The Repository Pattern and Database Access
Database access is where most MVC applications hit their first real scaling wall. The typical approach is to let each controller or view call a database context directly. This works fine until you have five different places querying the same data with slightly different filters, and none of them are caching or batching requests efficiently. The repository pattern addresses this by abstracting database operations behind an interface. Your controllers depend on the interface, not on Entity Framework or whatever ORM you are using. This gives you a single point where you can add caching, query optimization, or logging. In our production case, the fix for the slow home page was to implement a simple memory cache layer inside the repository. We cached the most frequently accessed data for sixty seconds with cache key invalidation tied to entity updates. This alone reduced database queries by about eighty percent during peak traffic. There is a trap here that beginners often fall into. The repository pattern can easily become an anemic layer that just passes calls through to the ORM without adding any value. That is not a useful abstraction. A proper repository should encapsulate query logic, handle caching strategies, and manage transaction boundaries. If your repository is nothing more than a wrapped DbContext, you have added complexity without any benefit. The repository should make it harder for consumers to write inefficient queries, not easier.
Caching Strategies That Actually Matter
Most MVC applications leave caching entirely to the browser or to output caching directives. Output caching in ASP.NET MVC is straightforward to set up, but it has significant limitations. It caches the entire rendered view, which means you cannot easily personalize content or handle dynamic data without complicating your cache keys. A more effective approach combines multiple caching layers. At the data layer, use in-memory caching for frequently accessed but infrequently changed data. Distributed caching with something like Redis becomes necessary when you are running multiple server instances. At the view layer, fragment caching allows you to cache individual parts of a page rather than the whole thing. A typical dashboard page might have a static header, a personalized greeting, and a data widget. The header and widget can be cached independently with different expiration times, while the greeting is rendered fresh for each user. In one of my projects, we implemented fragment caching for a product listing page that had a category filter, a sort order, and pagination. The cache key included all three parameters. Without fragment caching, every unique combination of those parameters would generate a full database query and render the entire page. With fragment caching, the same combination was served from cache after the first request, and response times dropped from around 800 milliseconds to roughly 50 milliseconds for cached responses. The setup took about four hours of work across two developers.
Handling Concurrency and State
MVC applications are stateless by design, which is generally a good thing for scalability. But statelessness creates real problems when you need to maintain user sessions or handle concurrent operations. The traditional session state approach, where data is stored in-process on the web server, does not scale beyond a single server. When you add multiple servers behind a load balancer, in-process session data becomes inconsistent. The solution is to move session state to an external provider. SQL Server session state is better than in-process but introduces database overhead. Redis or a similar in-memory store is significantly faster and handles high concurrency much more gracefully. Our migration from in-process session to Redis reduced session-related database queries by about ninety percent and eliminated the server affinity problems we were having with load balancing. Concurrency management is another area that gets overlooked. When multiple users update the same entity simultaneously, optimistic concurrency control using row versioning or timestamp columns prevents data corruption. ASP.NET MVC supports this through model binding and validation attributes, but you have to implement it deliberately. The default behavior in many projects is to simply overwrite concurrent changes, which leads to lost data that is very difficult to detect and recover from.

Monitoring and Performance Testing
No matter how well you architect your MVC application, you will not know where the bottlenecks are without proper monitoring. Application Insights or similar APM tools provide detailed traces of request timing, database query performance, and exception patterns. Setting this up early, before you have a production problem, saves enormous amounts of time during troubleshooting. Performance testing should also happen before you go live. Load testing your application with tools like k6 or JMeter reveals how it behaves under conditions that differ from your development environment. I have seen applications that performed well at fifty concurrent users completely collapse at two hundred, and the failure mode was always the same. The code path that looked harmless in testing involved a synchronous database call inside a loop, and under load, those synchronous calls created thread pool starvation that brought the entire application to a halt. The fix in that case was straightforward in principle but required careful identification. We replaced the synchronous calls with async versions and added a semaphore to limit concurrent database connections. Response times under load improved by roughly seven times. Without the load testing, we never would have discovered the issue before it affected real users.
Common Architectural Mistakes
There are a few recurring mistakes I see in MVC projects that directly impact scalability. The first is putting too much logic in the view. Razor views that contain Ccode blocks calling services or performing calculations make the application harder to test and slower to render. Views should only contain presentation logic, not business logic. The second mistake is ignoring the N plus one query problem. This is extremely common in MVC applications where a controller fetches a list of entities and the view iterates over them, triggering a database query for each related item. EF Core has change tracking and lazy loading features that can trigger these queries automatically. The fix is to use eager loading with Include statements or projection with Select to fetch all needed data in a single query. The third mistake is building monolithic controllers that try to handle every possible operation. This creates tight coupling between unrelated features and makes it impossible to scale individual parts of the application independently. The remedy is to decompose controllers into smaller, focused units, potentially using routing to organize them by feature area rather than by entity type.
When MVC Is Not the Right Choice
I should mention that MVC architecture is not always the best fit. For applications that are primarily data-heavy APIs with minimal presentation logic, a microservices approach or a dedicated API framework might be more appropriate. MVC adds complexity around routing, view rendering, and model binding that is unnecessary if you are building a backend service. Similarly, for real-time applications with heavy WebSocket communication, the request-response cycle of MVC is not ideal. The key is to match the architecture to the actual requirements of your application. A well-architected MVC application can handle substantial traffic, but it requires deliberate effort in layering, caching, and database access patterns. Skipping those steps because the application seems small at the start is the most common reason MVC projects become unscalable later. The restructuring cost grows exponentially the longer you delay it.
Practical Steps to Get Started
If you are starting a new MVC project with scalability in mind, begin with the layered structure I described. Create separate projects for your domain, services, and presentation layers before you write any business logic. Implement repository interfaces early, even if your initial implementation is simple. Add caching at the repository level from the beginning rather than retrofitting it later. Set up monitoring and logging on day one so you have baseline performance data. Write integration tests that verify your database queries are efficient. Check the actual SQL that Entity Framework generates, because the query you expect and the query EF produces are often different. An Include statement that looks correct in your code might generate multiple queries instead of one join if the relationship configuration is not set up properly. This kind of issue does not show up in unit tests and is very difficult to debug in production without detailed logging. The bottom line is that scalable MVC architecture is not about using the latest framework features or following a specific folder structure. It is about understanding where performance problems will occur in your application and designing your layers to contain them. The principles are well established. The challenge is applying them consistently throughout the development process rather than treating them as something to address after the application is already built and struggling under load.