Azure Service Health vs Azure Status: What Actually Matters for Your Subscriptions
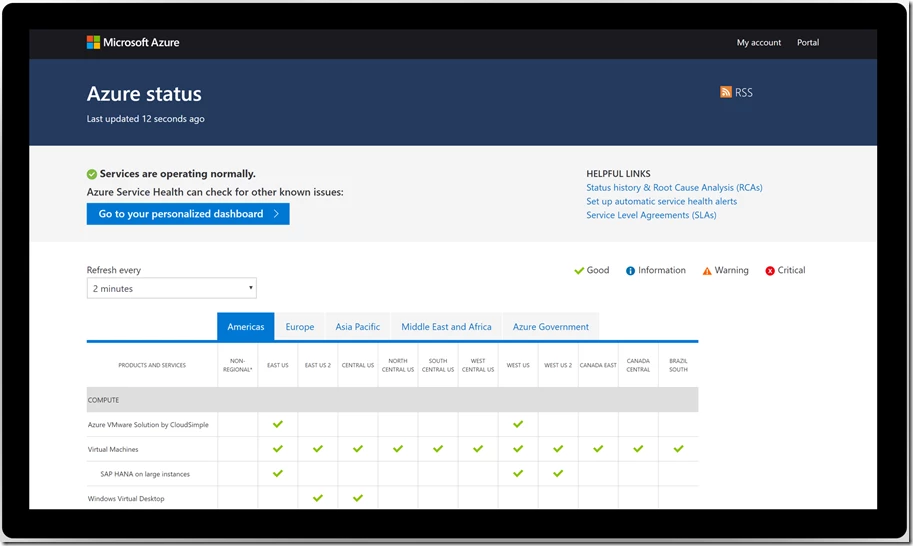
Azure Status is the public dashboard. It shows what is happening across every Azure service in every region. You open it and see a grid of green, yellow, or red indicators depending on how many users are reporting issues. That information is free and requires no setup. But it does not know which resources belong to you. For that, you need Azure Service Health. Service Health is the personalized version of Azure Status. It takes the same incident data and filters it down to what actually impacts your subscriptions, resource groups, and individual resources. That filtering is what makes it useful instead of just noisy. Without it, you would be manually checking the status page every twenty minutes during an outage to see if your specific storage account in West Europe was affected. Getting it working is not complicated, but the configuration has enough knobs that people skip parts of it. Here is the order I recommend setting things up.
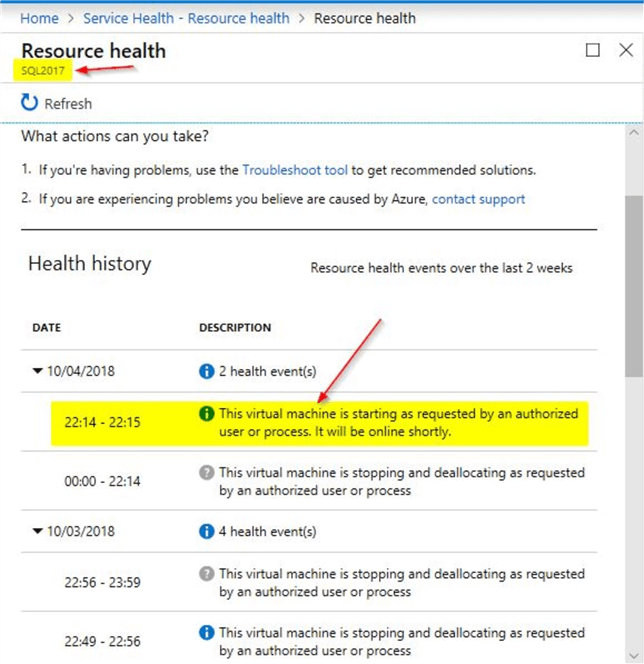
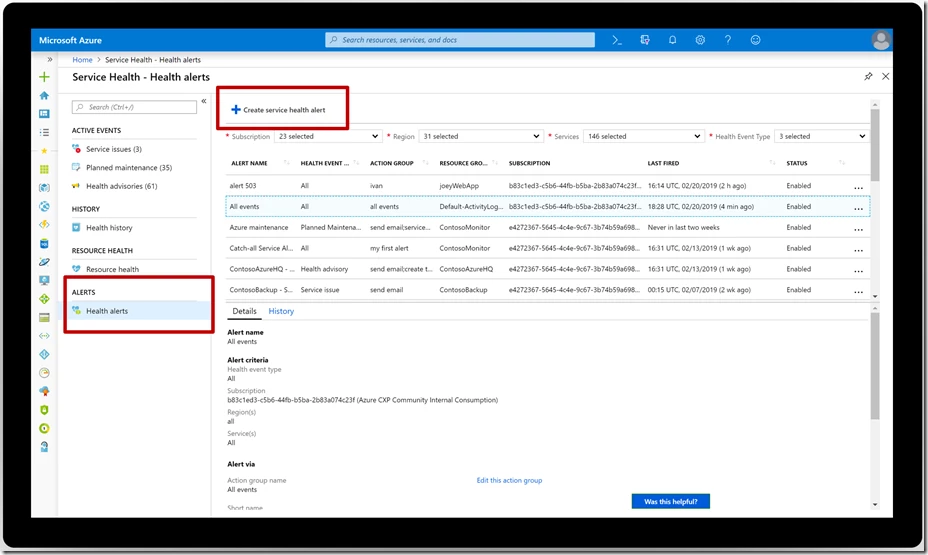
First, go to Service Health in the Azure portal and review the three tabs: Azure Status, Incidents, and Health Messages. The Azure Status tab on the left side of Service Health is different from the public status page because it is already scoped to your subscriptions. You will see the same incidents, but only the ones affecting your resources appear with the relevant severity level for you personally. Second, enable incident alerts. Navigate to Incidents, click on any active event, and select Alert. You can configure alerts for incident updates, new incidents, or resolved incidents. These alerts route to Action Groups, which then fan out to email, SMS, webhook, or paging integrations like PagerDuty or Microsoft Teams. The alert is triggered within approximately 15 minutes of an incident being classified as affecting your resources. That window matters. If you need sub-minute detection during a critical deployment, Service Health alone will not cut it. Third, set up resource health notifications. This is separate from incident alerts. Resource Health monitors the health of individual resources, not whole services. A single VM going unavailable triggers a different alert path than a regional outage. Go to the resource, click Health, and enable the alert rule. This gives you visibility into the specific resource level rather than the service level.
I ran into a case last year where a storage account in East US 2 started returning 503 errors during a regional degradation event. Service Health showed the incident within minutes, but our alert fired 22 minutes after the incident began, not 15. The delay was not a bug. It was the platform doing its correlation work across multiple telemetry sources. The workaround was to set up a lightweight synthetic check from an Azure Function that polls the storage account endpoint every 60 seconds and fires an immediate alert if it starts failing, regardless of what Service Health says. That got us from a 22-minute blast radius down to under 2 minutes. There is a counter-intuitive thing most teams miss about Service Health alerts. They are not based on the total number of users affected globally. They are based on whether your specific resources are tagged as impacted. This means two things. First, a massive outage in a region where you have no resources will not generate an alert. Second, a minor outage in a region where you have critical infrastructure can generate a high-severity alert. The severity rating inside Service Health is not a reflection of global impact. It is a reflection of your exposure. Treat the severity badge as a signal for your own risk, not for how bad the incident is overall. Another thing people overlook is the Health Messages tab. It contains planned maintenance, feature changes, and deprecation notices that do not count as incidents but can break things if you ignore them. A good example is when Microsoft retires an old API version or moves a backend component during a scheduled window. These messages show up here first, often weeks before they take effect. I have seen teams miss a deprecation notice for a legacy authentication endpoint and then spend a weekend migrating after the cutoff date instead of during the grace period. Bookmark the Health Messages tab and subscribe to those updates through the same alert mechanism.
Get the Full Details
The limitations are real. Service Health does not provide historical incident data through an API that you can query for arbitrary date ranges. You can see incidents that are currently active or recently closed, but if you need to build a compliance report covering the last 18 months of outages, you are stuck exporting manually or writing a custom solution around the limited logging that is available. There is also no way to alert on the public status page itself. If a service is degraded globally but not affecting your resources, Service Health stays silent. That is by design, but it frustrates teams that want visibility into upstream failures even when their own resources are unaffected. Another practical limitation is the alert routing. Every notification goes through Action Groups, and Action Groups live at the subscription level. If you are managing resources across 40 subscriptions spread among five management groups, you either duplicate your alert configuration 40 times or you use a script to create and maintain them in bulk. I use Terraform for this. It is not perfect, but it keeps the configuration consistent across subscriptions. For teams that need deeper real-time monitoring beyond what Service Health provides, the alternative is building your own observability pipeline using Application Insights, Log Analytics, and Event Grid. That gives you lower latency detection and custom alerting logic, but it also means you are responsible for maintaining the pipeline, tuning the false positive rate, and keeping the dashboards current when Microsoft changes their internal architecture. Service Health handles all of that for you. The trade-off is mostly about control versus convenience.
One more thing worth noting about the alert configuration. The include all future incidents checkbox in the alert rule settings determines whether the alert fires for every incident going forward or just the current one. Leave it checked unless you have a reason to stop. I have seen configurations where someone unchecked it during a test, forgot to recheck it, and then missed a production incident alert entirely because the rule was scoped to a single event. The Azure portal URL for Service Health is always the same regardless of region: portal.azure.com, then search for Service Health. There is no separate endpoint per region because the service is global. The underlying data is region-aware, but the interface is centralized. If you are using the Azure CLI, the command az monitor service-health gives you programmatic access to view incidents and health messages, though the output is less structured than the portal UI. If you want to start today with nothing preconfigured, the fastest path is to go to Service Health, click on any active incident that shows up for your subscriptions, and set up an alert from there. That gives you something working in about five minutes. From there you can refine it into the full setup: action groups, resource health notifications, health message subscriptions, and the synthetic check if your tolerance for alert delay is lower than the platform default.