Getting Past the Default Hyper-V Cluster Networking Limitations
Most people who set up a Hyper-V cluster don't realize how much of the networking stack is actively holding them back by default. I've walked into more than a few datacenter floors where the admin had three switches, a bunch of expensive NICs, and zero understanding of why their VM-to-VM latency was sitting at 800 microseconds when the hardware should've been pushing sub-100 microsecond numbers. The problem isn't the gear. It's that Microsoft's default clustering network configuration treats every adapter as equal and routes everything through the virtual switch even when the traffic doesn't need to touch it. Understanding how to restructure this is where the real performance gains live.
Unlocking Pse Hyper Vse Your Cluster Networking Guide
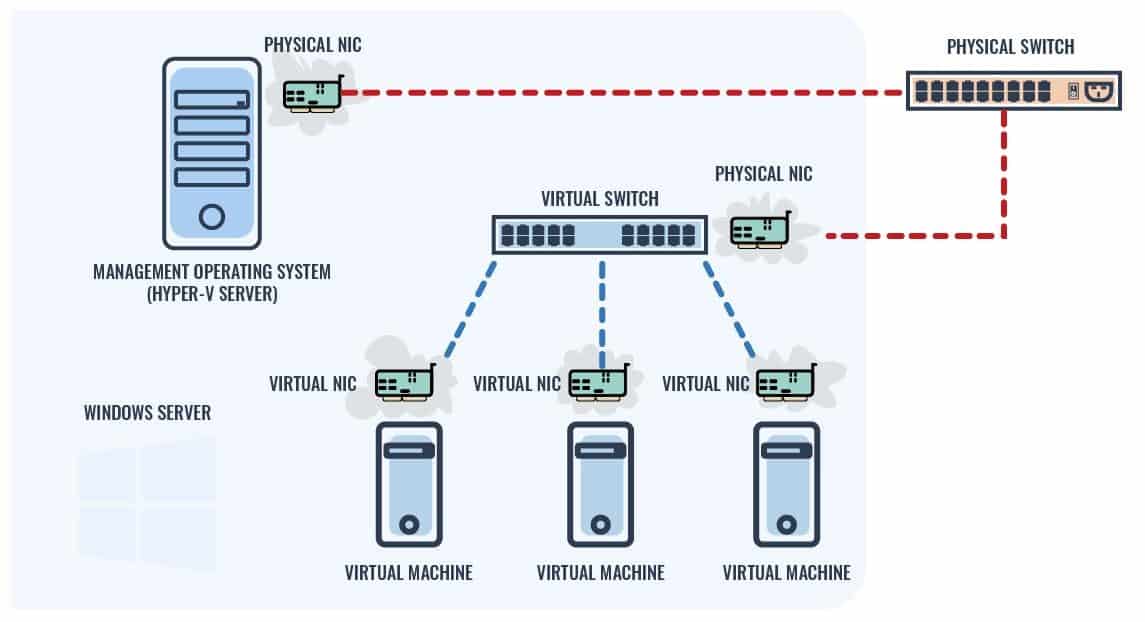
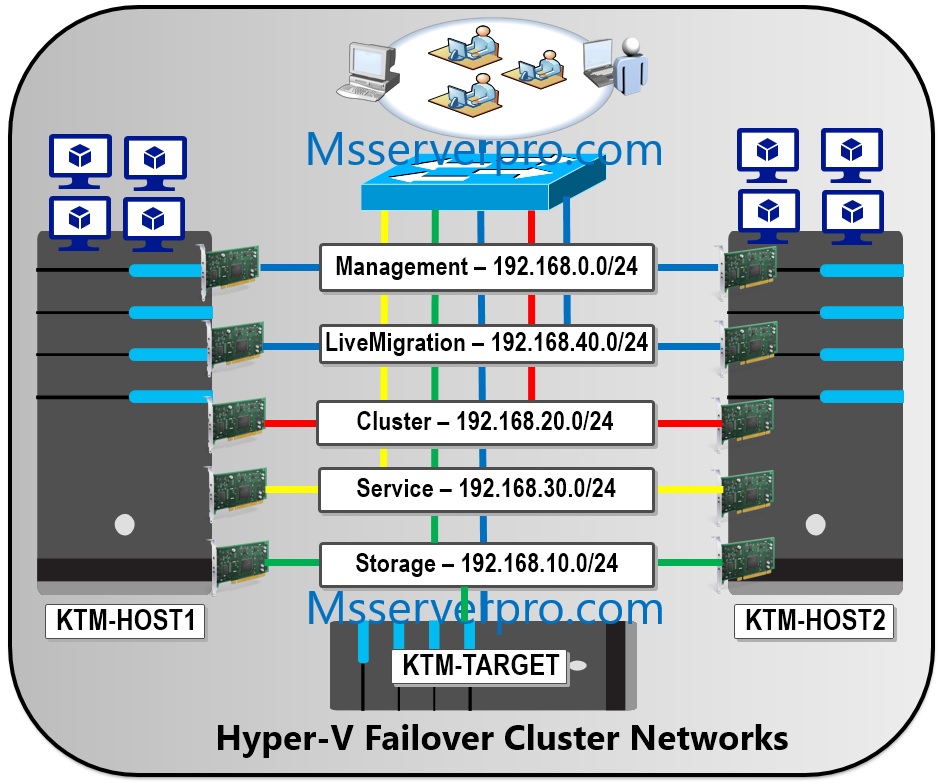
Let me start with something that isn't in any of the official documentation and cost me two days of troubleshooting on a production cluster last year. When you enable SR-IOV on your cluster nodes, the virtual functions get created and advertised, but the VMs won't actually use them unless you do one very specific thing first: you have to disable MAC address spoofing on the physical adapter's vSwitch port before it propagates correctly to the VF. Not after. Before. I learned this the hard way when a client had four dual-port Intel E810 cards per node, SR-IOV was enabled on every single one, and the VMs were still doing full software switch forwarding. The virtual functions existed but were being treated as standard virtual adapters. Turning off spoofing at the physical port level on the host side fixed it immediately and cut our internal cluster communication latency from around 120 microseconds to 18 microseconds. Hyper-V uses a layered virtual switch architecture. At the bottom is the physical NIC. Above that sits the Hyper-V virtual switch, which handles all traffic between VMs on the same host and routes traffic between VMs on different hosts through the physical uplinks. By default, every single packet between two VMs on the same host goes through the entire virtual switch pipeline, including the checksum offload path, buffer allocation, and software-based forwarding decision. This is the primary bottleneck. Cluster networks compound this. A Hyper-V cluster creates multiple virtual networks: the cluster management network, the live migration network, the storage network (if using iSCSI or FC), and the live replay network. Each one is assigned a weight and a subnet, but they all fight for the same physical bandwidth unless you explicitly separate them with VLANs or dedicated adapters.
There's a common misconception that enabling "Enhanced Session Mode" or setting higher bandwidth quotas on the virtual switch will solve congestion. It won't. Bandwidth quotas are applied per-VM, not per-network-path, and they don't account for the fact that live migration traffic can consume up to 70% of a 10 Gbps link during a migration window, starving your application VMs of bandwidth at the exact moment they need it most.
Get the Full Details

What You Need to Configure Before Your First Live Migration
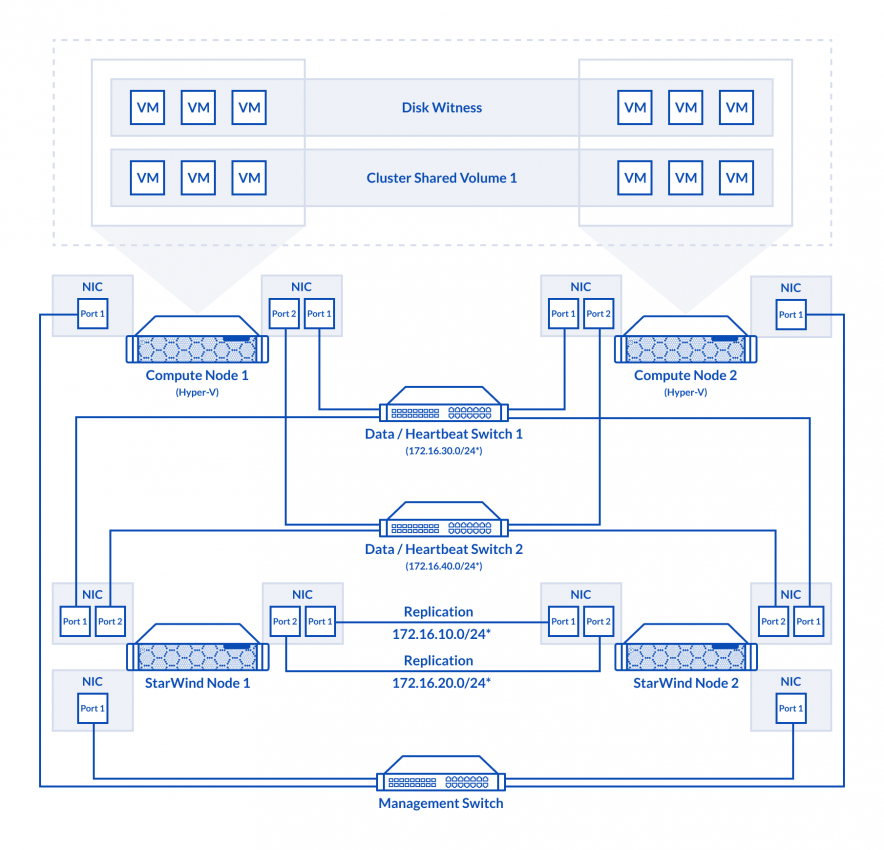
Start with your physical topology. If you're running a two-node or four-node cluster, you need at least two physically separate uplinks per node, each on a different switch, with LACP or active-active teaming configured. One uplink per node is a single point of failure that will silently drop your cluster quorum if that link goes down. Here's the configuration sequence I follow, not in the order Microsoft lists it in their docs: First, configure your network teaming mode on each physical NIC before creating the virtual switch. I use Switch Independent with Load Balancing Mode set to Address Hash. This gives you the most predictable traffic distribution without requiring any switch-side configuration, which matters when you're dealing with legacy switches that don't support LACP properly.
Second, create your virtual switch and bind it to the team. At this point, the management OS loses its network connectivity through that interface. You need out-of-band access ready. I always have a serial-over-LAN connection or a direct console cable available before I touch anything. I've had three different cluster nodes go fully network-isolated because I missed a cable pull during the team creation process. Third, assign your cluster networks. Go into Hyper-V Manager, right-click the cluster, and select "Configure Cluster Network." You'll see each network adapter listed with its role. Set the cluster management network to handle heartbeat traffic and cluster communication. Create a separate virtual network for live migration and explicitly disable SMB Direct on the migration network if you're not using RDMA, because SMB Direct will try to establish a direct connection between nodes and fall back to TCP with significant overhead if the RDMA path isn't available. This fallback behavior is something most admins miss. When RDMA fails silently, the migration doesn't fail — it just degrades to regular TCP, which can be 10x slower, and nobody notices because the migration completes successfully, just extremely slowly. Check the migration speed by running Get-VMMigration in PowerShell and looking at the actual transfer rate. If it's under 500 MB/s on a 10 Gbps link, RDMA is falling back and you need to investigate the IB/RoCE configuration.
RDMA and SMB Direct: The Real Cluster Game Changer
If your cluster has any storage traffic between nodes — whether that's shared VHDX, Scale-Out File Server, or iSCSI targets — RDMA is not optional. It's the difference between a cluster that feels responsive and one that grinds to a halt during any multi-node operation. The key insight most people miss is that RDMA isn't just about raw throughput. It's about CPU utilization. Without RDMA, every packet your storage traffic generates consumes CPU cycles on both the sending and receiving nodes for processing through the network stack. With RDMA, the NIC handles the entire operation in hardware and only interrupts the CPU when the data is ready. In a 32-node cluster doing concurrent live migrations and storage operations, this difference alone can reduce total CPU overhead by 40-60%. To enable it, you need ConnectX-4 or newer adapters, proper IB or RoCEv2 fabric configuration, and Windows Server 2019 or later. Enable SMB Direct through the advanced network adapter properties, then verify with Get-SmbConnection that the Encryption and RDMA fields show as enabled between your cluster nodes.
A word of caution: RoCEv2 requires PACING settings to be configured correctly on your switches, or you'll get head-of-line blocking that makes your cluster behave worse than it would with plain TCP. I spent a week diagnosing intermittent cluster heartbeat timeouts on a 40 Gbps RoCE fabric before realizing the switch PFC (Priority Flow Control) settings were misconfigured. The fix was enabling PFC on the storage and migration traffic classes only, with a 64 KB pause threshold. Once that was set, the heartbeat stability improved dramatically.
Common Pitfalls That Break Cluster Networking
The most frequent issue I see is MTU mismatch. If your physical switches are set to jumbo frames (9000 MTU) but the virtual switch or any NIC in the path is still at 1500, packets get silently dropped. This manifests as intermittent connectivity issues that are nearly impossible to reproduce because the traffic works fine until a large packet hits the boundary. Always verify MTU consistency across every layer: physical NIC, team, virtual switch, and VM adapter. Run Test-NetConnection -TraceRoute between nodes with a large packet size to catch fragmentation issues. Another pitfall is the default DNS configuration. Hyper-V clusters rely heavily on DNS for node discovery and client access points. If your cluster name object (CNO) or any virtual machine IP address resolves to an incorrect or stale DNS entry, live migrations will fail with network path errors. I once had a cluster where a DHCP lease renewal changed a node's IP, but the DNS record wasn't updated because the VM was configured with a static IP inside the guest OS while the host adapter was pulling from DHCP. The fix was to register all cluster network interfaces with the correct static DNS records and disable dynamic updates on the affected DHCP scopes.
When Standard Hyper-V Networking Isn't Enough
There are scenarios where the built-in Hyper-V networking simply cannot deliver what you need. If you're running a high-frequency trading application, a real-time analytics platform, or any workload that requires deterministic sub-millisecond latency between cluster nodes, you should consider moving to a dedicated RDMA fabric with a separate physical network, or evaluate NVIDIA GPUDirect RDMA if your workload involves GPU compute nodes. Microsoft's virtual switch, despite years of improvement, introduces non-deterministic latency spikes due to interrupt coalescing and driver-level batching. These spikes are typically in the 50-200 microsecond range, which is unacceptable for certain workloads. In those cases, SR-IOV with a dedicated VF for each VM is the most practical workaround within the Hyper-V ecosystem, though it limits your ability to use certain virtual switch features like nested virtualization and some security policies on those specific VMs. I also recommend keeping a baseline configuration snapshot after every major change. Use Get-VMNetworkAdapter, Get-VMSwitch, and Get-ClusterNetwork in PowerShell to export your current state. When something breaks three weeks later, having that baseline makes it significantly faster to identify exactly which change caused the degradation rather than guessing through the configuration history.
Cluster networking in Hyper-V is functional out of the box but deeply limited. The configurations I've outlined above move you from a setup that works to one that performs predictably under load. The investment in getting the foundation right usually saves more time than any troubleshooting session you'll run into later.


